Merge branch 'main' into GymnasiumUpdate/Unit6
 Thomas Simonini
21
.github/ISSUE_TEMPLATE/i-have-a-bug-with-a-hands-on.md
vendored
Normal file
@@ -0,0 +1,21 @@
|
||||
---
|
||||
name: I have a bug with a hands-on
|
||||
about: You have encountered a bug during one of the hands-on
|
||||
title: "[HANDS-ON BUG]"
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
# Describe the bug
|
||||
|
||||
A clear and concise description of what the bug is.
|
||||
**Please share your notebook link so that we can reproduce the error**
|
||||
|
||||
# Material
|
||||
|
||||
- Did you use Google Colab?
|
||||
|
||||
If not:
|
||||
- Your Operating system (OS)
|
||||
- Version of your OS
|
||||
12
.github/ISSUE_TEMPLATE/i-have-a-question.md
vendored
Normal file
@@ -0,0 +1,12 @@
|
||||
---
|
||||
name: I have a question
|
||||
about: You have a question about a part of the course
|
||||
title: "[QUESTION]"
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
1. First, the **best way to get a response fast is to ask the community** it on #rl-study-group in our Discord server: https://www.hf.co/join/discord
|
||||
|
||||
2. If you prefer you can ask here, please **be specific**.
|
||||
14
.github/ISSUE_TEMPLATE/i-want-to-improve-the-course.md
vendored
Normal file
@@ -0,0 +1,14 @@
|
||||
---
|
||||
name: I want to improve the course
|
||||
about: You found a typo, an error or you want to improve a part of the course
|
||||
title: "[UPDATE]"
|
||||
labels: ''
|
||||
assignees: ''
|
||||
|
||||
---
|
||||
|
||||
# What do you want to improve?
|
||||
|
||||
- Explain the typo/error or the part of the course you want to improve
|
||||
|
||||
- **Also, don't hesitate to open a Pull Request with the update**.
|
||||
1
.github/workflows/build_documentation.yml
vendored
@@ -17,3 +17,4 @@ jobs:
|
||||
languages: en
|
||||
secrets:
|
||||
token: ${{ secrets.HUGGINGFACE_PUSH }}
|
||||
hf_token: ${{ secrets.HF_DOC_BUILD_PUSH }}
|
||||
|
||||
1
.github/workflows/build_pr_documentation.yml
vendored
@@ -18,4 +18,3 @@ jobs:
|
||||
path_to_docs: deep-rl-class/units/
|
||||
additional_args: --not_python_module
|
||||
languages: en
|
||||
hub_base_path: https://moon-ci-docs.huggingface.co
|
||||
|
||||
14
.github/workflows/delete_doc_comment.yml
vendored
@@ -1,13 +1,13 @@
|
||||
name: Delete dev documentation
|
||||
name: Delete doc comment
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
types: [ closed ]
|
||||
|
||||
workflow_run:
|
||||
workflows: ["Delete doc comment trigger"]
|
||||
types:
|
||||
- completed
|
||||
|
||||
jobs:
|
||||
delete:
|
||||
uses: huggingface/doc-builder/.github/workflows/delete_doc_comment.yml@main
|
||||
with:
|
||||
pr_number: ${{ github.event.number }}
|
||||
package: deep-rl-class
|
||||
secrets:
|
||||
comment_bot_token: ${{ secrets.COMMENT_BOT_TOKEN }}
|
||||
12
.github/workflows/delete_doc_comment_trigger.yml
vendored
Normal file
@@ -0,0 +1,12 @@
|
||||
name: Delete doc comment trigger
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
types: [ closed ]
|
||||
|
||||
|
||||
jobs:
|
||||
delete:
|
||||
uses: huggingface/doc-builder/.github/workflows/delete_doc_comment_trigger.yml@main
|
||||
with:
|
||||
pr_number: ${{ github.event.number }}
|
||||
17
.github/workflows/upload_pr_documentation.yml
vendored
Normal file
@@ -0,0 +1,17 @@
|
||||
name: Upload PR Documentation
|
||||
|
||||
on:
|
||||
workflow_run:
|
||||
workflows: ["Build PR Documentation"]
|
||||
types:
|
||||
- completed
|
||||
|
||||
jobs:
|
||||
build:
|
||||
uses: huggingface/doc-builder/.github/workflows/upload_pr_documentation.yml@main
|
||||
with:
|
||||
package_name: deep-rl-course
|
||||
hub_base_path: https://moon-ci-docs.huggingface.co
|
||||
secrets:
|
||||
hf_token: ${{ secrets.HF_DOC_BUILD_PUSH }}
|
||||
comment_bot_token: ${{ secrets.COMMENT_BOT_TOKEN }}
|
||||
33
DISCORD.Md
@@ -1,33 +0,0 @@
|
||||
## Discord 101
|
||||
|
||||
Hey there! My name is Huggy, the dog 🐶, and I'm looking forward to train with you during this RL Class! Although I don't know much about bringing sticks (yet), I know one or two things about Discord. So I wrote this guide to help you learn about it!
|
||||
|
||||

|
||||
|
||||
Discord is a free chat platform. If you've used Slack, it's quite similar. There is a Hugging Face Community Discord server with 8000 members you can join with a single click [here](http://hf.co/join/discord). 🐕 So many humans to play with!
|
||||
|
||||
Starting in Discord can be a bit intimidating, so let me take you through it.
|
||||
|
||||
* Unlike Slack, you have access to most channels. That means that there might be a bit more noise that what you would like. And I hate loud noise **woof**! 🔔 Since channels are gathered by topic, you can mute individual channels or entire categories. For example, the **Audio Lounge** category is about ML for Audio which I don't care about, so I right click the category and then click **Mute**. Ah much better!
|
||||
* I still see so many channels **woof**. You can also collapse a category so you don't see channels that are not of interest.
|
||||
* So which channels are interesting to me?
|
||||
* They are in the reinforcement learning lounge.
|
||||
* #rl-announcements have announcements about the course.
|
||||
* #discussions is a place where you can talk with fellow humans.
|
||||
* #unity-ml-agents is a place to talk about ML Agents, a library we'll learn during th ecourse.
|
||||
* #study-groups do you want to form a group with fellow humans? This is the place
|
||||
|
||||
The HF Community Server has a thriving community of humans interested in many areas, so you can also learn from those. There are paper discussions, events, and many other things. Here are other channels in the community
|
||||
* in #reads people share interesting resources or papers they've found
|
||||
* in #today-im-learning people share what they are learning...today!
|
||||
* in #i-made-this you can show off your amazing projects **woof**.
|
||||
|
||||
|
||||
🦴🐕Was this useful? There are a couple of tips I can share with you:
|
||||
* There are voice channels you can use as well, although most people prefer text chat.
|
||||
* You can use markdown style. So if you're writing code, you can use that style. Sadly this does not work as well for links.
|
||||
* You can open threads as well!
|
||||
|
||||
I hope this is useful! And if you have questions, just ask! See you later! 🌳
|
||||
|
||||
**Huggy**
|
||||
207
README.md
@@ -1,5 +1,7 @@
|
||||
# [The Hugging Face Deep Reinforcement Learning Course 🤗 (v2.0)](https://huggingface.co/deep-rl-course/unit0/introduction)
|
||||
|
||||
<img src="https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit0/thumbnail.jpg" alt="Thumbnail"/>
|
||||
|
||||
If you like the course, don't hesitate to **⭐ star this repository. This helps us 🤗**.
|
||||
|
||||
This repository contains the Deep Reinforcement Learning Course mdx files and notebooks. **The website is here**: https://huggingface.co/deep-rl-course/unit0/introduction?fw=pt
|
||||
@@ -26,208 +28,3 @@ To cite this repository in publications:
|
||||
howpublished = {\url{https://github.com/huggingface/deep-rl-class}},
|
||||
}
|
||||
```
|
||||
|
||||
<br>
|
||||
<br>
|
||||
<br>
|
||||
<br>
|
||||
|
||||
|
||||
|
||||
|
||||
# The documentation below is for v1.0 (deprecated)
|
||||
|
||||
We're launching a **new version (v2.0) of the course starting December the 5th,**
|
||||
|
||||
The syllabus 📚: https://simoninithomas.github.io/deep-rl-course
|
||||
|
||||
## **Sign up here** ➡️➡️➡️ http://eepurl.com/ic5ZUD
|
||||
|
||||
<br>
|
||||
<br>
|
||||
<br>
|
||||
<br>
|
||||
|
||||
# The documentation below is for v1.0 (deprecated)
|
||||
|
||||
In this free course, you will:
|
||||
|
||||
- 📖 Study Deep Reinforcement Learning in **theory and practice**.
|
||||
- 🧑💻 Learn to **use famous Deep RL libraries** such as Stable Baselines3, RL Baselines3 Zoo, and RLlib.
|
||||
- 🤖 Train agents in **unique environments** such as SnowballFight, Huggy the Doggo 🐶, and classical ones such as Space Invaders and PyBullet.
|
||||
- 💾 **Publish your trained agents in one line of code to the Hugging Face Hub**. But also **download powerful agents from the community**.
|
||||
- 🏆 **Participate in challenges** where you will evaluate your agents against other teams.
|
||||
- 🖌️🎨 **Learn to share your own environments made with Unity and Godot**.
|
||||
|
||||
|
||||
The best way to keep in touch is to **join our discord server to exchange with the community and with us** 👉🏻 https://discord.gg/aYka4Yhff9
|
||||
|
||||
Are you new to Discord? Check our **discord 101 to get the best practices** 👉 https://github.com/huggingface/deep-rl-class/blob/main/DISCORD.Md
|
||||
|
||||
And don't forget to share with your friends who want to learn 🤗!
|
||||
|
||||
## The Syllabus 🏗️
|
||||
This course is **self-paced** you can start when you want 🥳.
|
||||
|
||||
| 📆 Publishing date | 📘 Unit | 👩💻 Hands-on |
|
||||
|---------------|----------------------------------------------------------|----------------------------------------------------------------------------------------------------------|
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit1#unit-1-introduction-to-deep-reinforcement-learning) | [An Introduction to Deep Reinforcement Learning](https://github.com/huggingface/deep-rl-class/tree/main/unit1) | [Train a Deep Reinforcement Learning lander agent to land correctly on the Moon 🌕 using Stable-Baselines3](https://github.com/huggingface/deep-rl-class/blob/main/unit1/unit1.ipynb) |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit1/unit1-bonus) | [Bonus](https://github.com/huggingface/deep-rl-class/tree/main/unit1/unit1-bonus) | |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/blob/main/unit2/README.md)| [Q-Learning](https://github.com/huggingface/deep-rl-class/blob/main/unit2/README.md) | [Train an agent to cross a Frozen lake ⛄ and train an autonomous taxi 🚖](https://github.com/huggingface/deep-rl-class/blob/main/unit2/unit2.ipynb). |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit3#unit-3-deep-q-learning-with-atari-games-) | [Deep Q-Learning](https://github.com/huggingface/deep-rl-class/tree/main/unit3#unit-3-deep-q-learning-with-atari-games-) | Train a Deep Q-Learning agent to play Space Invaders using [RL-Baselines3-Zoo](https://github.com/DLR-RM/rl-baselines3-zoo) |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/blob/main/unit3/bonus.md)| [Bonus: Automatic Hyperparameter Tuning using Optuna](https://github.com/huggingface/deep-rl-class/blob/main/unit3/bonus.md)| | | |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit4#unit-4-an-introduction-to-unity-mlagents-with-hugging-face-) | [🎁 Learn to train your first Unity MLAgent](https://github.com/huggingface/deep-rl-class/tree/main/unit4#unit-4-an-introduction-to-unity-mlagents-with-hugging-face-) | [Train a curious agent to destroy Pyramids 💥](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit4/unit4.ipynb) |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit5#unit-5-policy-gradient-with-pytorch) | [Policy Gradient with PyTorch](https://huggingface.co/blog/deep-rl-pg) | [Code a Reinforce agent from scratch using PyTorch and train it to play Pong 🎾, CartPole and Pixelcopter 🚁](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit5/unit5.ipynb) |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit6#towards-better-explorations-methods-with-curiosity) | [Towards better explorations methods with Curiosity](https://github.com/huggingface/deep-rl-class/tree/main/unit6#towards-better-explorations-methods-with-curiosity)| |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit7#unit-7-advantage-actor-critic-a2c-using-robotics-simulations-with-pybullet-) | [Advantage Actor Critic (A2C)](https://github.com/huggingface/deep-rl-class/tree/main/unit7#unit-7-advantage-actor-critic-a2c-using-robotics-simulations-with-pybullet-) | [Train a bipedal walker and a spider to learn to walk using A2C](https://github.com/huggingface/deep-rl-class/tree/main/unit7#unit-7-advantage-actor-critic-a2c-using-robotics-simulations-with-pybullet-) |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit8#unit-8-proximal-policy-optimization-ppo-with-pytorch) | [Proximal Policy Optimization (PPO)](https://github.com/huggingface/deep-rl-class/tree/main/unit8#unit-8-proximal-policy-optimization-ppo-with-pytorch) | [Code a PPO agent from scratch using PyTorch and bulletproof it with Classical Control Environments](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit8/unit8.ipynb) |
|
||||
| [Published 🥳](https://github.com/huggingface/deep-rl-class/tree/main/unit9#unit-9-decision-transformers-and-offline-reinforcement-learning-) | [Decision Transformers and offline Reinforcement Learning](https://github.com/huggingface/deep-rl-class/tree/main/unit9#unit-9-decision-transformers-and-offline-reinforcement-learning-) | [Train your first Offline Decision Transformer model from scratch to make a half-cheetah run ](https://github.com/huggingface/blog/blob/main/notebooks/101_train-decision-transformers.ipynb) |
|
||||
|
||||
|
||||
|
||||
## The library you'll learn during this course
|
||||
Version 1.0 (current):
|
||||
- [Stable-Baselines3](https://github.com/DLR-RM/stable-baselines3)
|
||||
- [RL Baselines3 Zoo](https://github.com/DLR-RM/rl-baselines3-zoo)
|
||||
- [CleanRL](https://github.com/vwxyzjn/cleanrl)
|
||||
|
||||
Version 2.0 (in addition to SB3, RL-Baselines3-Zoo and CleanRL):
|
||||
- [RLlib](https://docs.ray.io/en/latest/rllib/index.html)
|
||||
- [Sample Factory](https://github.com/alex-petrenko/sample-factory)
|
||||
- [Hugging Face Decision Transformers](https://huggingface.co/blog/decision-transformers)
|
||||
- More to come 🏗️
|
||||
|
||||
## The Environments you'll use
|
||||
### Custom environments made by the Hugging Face Team using Unity and Godot
|
||||
|
||||
| Environment | Screenshot |
|
||||
|-----------------|--------------------------------------------------|
|
||||
| Huggy the Doggo 🐶 (Based on [Unity's Puppo the Corgi work](https://blog.unity.com/technology/puppo-the-corgi-cuteness-overload-with-the-unity-ml-agents-toolkit)) |  |
|
||||
| SnowballFight ☃️ 👉 Play it here: https://huggingface.co/spaces/ThomasSimonini/SnowballFight |  |
|
||||
|
||||
|
||||
### Gym classic and controls environments 🕹️
|
||||
|
||||
| Environment | Screenshot |
|
||||
|-----------------|--------------------------------------------------|
|
||||
| Lunar Lander 🚀🌙 |  |
|
||||
| Frozen Lake ⛄ |  |
|
||||
| Taxi 🚖 |  |
|
||||
| Cartpole |  |
|
||||
| Pong 🎾 |  |
|
||||
| Pixelcopter 🚁 |  |
|
||||
|
||||
|
||||
|
||||
### Gym Atari environments 👾
|
||||
|
||||
| Environment | Screenshot |
|
||||
|-----------------|--------------------------------------------------|
|
||||
| Space Invaders 👾 |  |
|
||||
| Breakout |  |
|
||||
| Qbert |  |
|
||||
| Seaquest |  |
|
||||
|
||||
|
||||
### PyBullet 🤖
|
||||
|
||||
| Environment | Screenshot |
|
||||
|-----------------|--------------------------------------------------|
|
||||
| Ant Bullet |  |
|
||||
| Walker 2D Bullet |  |
|
||||
|
||||
|
||||
|
||||
### MLAgents environments 🖌️
|
||||
- More to come 🚧
|
||||
|
||||
|
||||
- More to come 🚧
|
||||
|
||||
|
||||
## Prerequisites
|
||||
- Good skills in Python 🐍
|
||||
- Basics in Deep Learning and Pytorch
|
||||
|
||||
If it's not the case yet, you can check these free resources:
|
||||
- Python: https://www.udacity.com/course/introduction-to-python--ud1110
|
||||
- Intro to Deep Learning with PyTorch: https://www.udacity.com/course/deep-learning-pytorch--ud188
|
||||
- PyTorch in 60min: https://pytorch.org/tutorials/beginner/deep_learning_60min_blitz.html
|
||||
|
||||
## FAQ
|
||||
**Is this class free?**
|
||||
|
||||
Yes, totally free 🥳.
|
||||
|
||||
|
||||
**Do I need to have a Hugging Face account to follow the course?**
|
||||
|
||||
Yes, to push your trained agents during the hands-on, you need an account (it's free) 🤗.
|
||||
|
||||
You can create one here 👉 [https://huggingface.co/join](https://huggingface.co/join)
|
||||
|
||||
|
||||
**What’s the format of the class?**
|
||||
|
||||
The course consists of **8 Units.** In each of the Units, we'll have:
|
||||
|
||||
- **A theory explained part**: an article and a video (based on Deep Reinforcement Learning Course)
|
||||
- **A hands-on Google Colab** where you'll learn to use famous Deep RL libraries such as Stable Baselines3, RL Baselines3 Zoo, and RLlib to train your agents in unique environments such as SnowballFight, Huggy the Doggo 🐶, and classical ones such as Space Invaders and PyBullet.
|
||||
- **Some optional challenges**: train an agent in another environment, and try to beat the results.
|
||||
|
||||
It's not a live course video, so you can watch and read each unit when you want 🤗
|
||||
You can check the syllabus here 👉 https://github.com/huggingface/deep-rl-class
|
||||
|
||||
|
||||
**What I will do during this course?**
|
||||
|
||||
In this free course, you will:
|
||||
|
||||
- 📖 Study Deep Reinforcement Learning in theory and practice.
|
||||
- 🧑💻 Learn to use famous Deep RL libraries such as Stable Baselines3, RL Baselines3 Zoo, and RLlib.
|
||||
- 🤖 Train agents in unique environments such as SnowballFight, Huggy the Doggo 🐶, and classical ones such as Space Invaders and PyBullet.
|
||||
- 💾 Publish your trained agents in one line of code to the Hub. But also download powerful agents from the community.
|
||||
- 🏆 Participate in challenges where you will evaluate your agents against other teams.
|
||||
- 🖌️🎨 Learn to share your own environments made with Unity and Godot.
|
||||
|
||||
|
||||
**Where do I sign up?**
|
||||
|
||||
Here 👉 http://eepurl.com/h1pElX
|
||||
|
||||
|
||||
**Where can I find the course?**
|
||||
|
||||
**On this repository**, we'll publish every week the links (chapters, hands-ons, videos).
|
||||
|
||||
|
||||
**Where can I exchange with my classmates and with you?**
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us** 👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9)
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
|
||||
**I have some feedback**
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. If you have some, please fill this form 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
|
||||
**How much background knowledge is needed?**
|
||||
|
||||
Some prerequisites:
|
||||
|
||||
Good skills in **Python** 🐍
|
||||
Basics in **Deep Learning and Pytorch**
|
||||
|
||||
If it's not the case yet, you can check these free resources:
|
||||
|
||||
- Python: [https://www.udacity.com/course/introduction-to-python--ud1110](https://www.udacity.com/course/introduction-to-python--ud1110)
|
||||
- Intro to Deep Learning with PyTorch: [https://www.udacity.com/course/deep-learning-pytorch--ud188](https://www.udacity.com/course/deep-learning-pytorch--ud188)
|
||||
- PyTorch in 60min: [https://pytorch.org/tutorials/beginner/deep_learning_60min_blitz.html](https://pytorch.org/tutorials/beginner/deep_learning_60min_blitz.html)
|
||||
|
||||
|
||||
**Is there a certificate?**
|
||||
|
||||
Yes 🎉. You'll **need to upload the eight models with the eight hands-on.**
|
||||
|
||||
|
||||

|
Before Width: | Height: | Size: 900 KiB |

|
Before Width: | Height: | Size: 571 KiB |

|
Before Width: | Height: | Size: 181 KiB |

|
Before Width: | Height: | Size: 68 KiB |

|
Before Width: | Height: | Size: 387 KiB |

|
Before Width: | Height: | Size: 230 KiB |

|
Before Width: | Height: | Size: 369 KiB |

|
Before Width: | Height: | Size: 215 KiB |

|
Before Width: | Height: | Size: 690 KiB |

|
Before Width: | Height: | Size: 454 KiB |

|
Before Width: | Height: | Size: 2.2 MiB |

|
Before Width: | Height: | Size: 210 KiB |

|
Before Width: | Height: | Size: 218 KiB |

|
Before Width: | Height: | Size: 340 KiB |
@@ -53,7 +53,7 @@
|
||||
"\n",
|
||||
"### The library used 📚\n",
|
||||
"\n",
|
||||
"- [MLAgents (Hugging Face version)](https://github.com/huggingface/ml-agents)"
|
||||
"- [MLAgents](https://github.com/Unity-Technologies/ml-agents)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "x7oR6R-ZIbeS"
|
||||
@@ -102,7 +102,7 @@
|
||||
"\n",
|
||||
"- 📖 Study Deep Reinforcement Learning in **theory and practice**.\n",
|
||||
"- 🧑💻 Learn to **use famous Deep RL libraries** such as Stable Baselines3, RL Baselines3 Zoo, CleanRL and Sample Factory 2.0.\n",
|
||||
"- 🤖 Train **agents in unique environments** \n",
|
||||
"- 🤖 Train **agents in unique environments**\n",
|
||||
"\n",
|
||||
"And more check 📚 the syllabus 👉 https://simoninithomas.github.io/deep-rl-course\n",
|
||||
"\n",
|
||||
@@ -161,7 +161,7 @@
|
||||
"source": [
|
||||
"## Clone the repository and install the dependencies 🔽\n",
|
||||
"\n",
|
||||
"- We need to clone the repository, that **contains the experimental version of the library that allows you to push your trained agent to the Hub.**"
|
||||
"- We need to clone the repository, that contains **ML-Agents.**"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -173,8 +173,8 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"# Clone this specific repository (can take 3min)\n",
|
||||
"!git clone --depth 1 --branch hf-integration-save https://github.com/huggingface/ml-agents"
|
||||
"# Clone the repository (can take 3min)\n",
|
||||
"!git clone --depth 1 https://github.com/Unity-Technologies/ml-agents"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -192,19 +192,6 @@
|
||||
"!pip3 install -e ./ml-agents"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"# Due to some conflicts between mlagents and tensorflow we need to uninstall it\n",
|
||||
"!pip3 uninstall tensorflow -y"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "yBRsYPvtTjrm"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -267,7 +254,7 @@
|
||||
"id": "nyumV5XfPKzu"
|
||||
},
|
||||
"source": [
|
||||
"Make sure your file is accessible "
|
||||
"Make sure your file is accessible"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -328,16 +315,74 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Check the Huggy config file\n",
|
||||
"## Create the Huggy config file\n",
|
||||
"\n",
|
||||
"- In ML-Agents, you define the **training hyperparameters into config.yaml files.**\n",
|
||||
"\n",
|
||||
"- For the scope of this notebook, we're not going to modify the hyperparameters, but if you want to try as an experiment, you should also try to modify some other hyperparameters, Unity provides very [good documentation explaining each of them here](https://github.com/Unity-Technologies/ml-agents/blob/main/docs/Training-Configuration-File.md)."
|
||||
"- For the scope of this notebook, we're not going to modify the hyperparameters, but if you want to try as an experiment, you should also try to modify some other hyperparameters, Unity provides very [good documentation explaining each of them here](https://github.com/Unity-Technologies/ml-agents/blob/main/docs/Training-Configuration-File.md).\n",
|
||||
"\n",
|
||||
"- But we need to create a config file for Huggy.\n",
|
||||
"\n",
|
||||
" - To do that click on Folder logo on the left of your screen.\n",
|
||||
"\n",
|
||||
" <img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit1/create_file.png\" alt=\"Create file\" width=\"10%\">\n",
|
||||
"\n",
|
||||
" - Go to `/content/ml-agents/config/ppo`\n",
|
||||
" - Right mouse click and create a new file called `Huggy.yaml`\n",
|
||||
"\n",
|
||||
" <img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit1/create-huggy.png\" alt=\"Create huggy.yaml\" width=\"20%\">\n",
|
||||
"\n",
|
||||
"- Copy and paste the content below 🔽"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "NAuEq32Mwvtz"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"behaviors:\n",
|
||||
" Huggy:\n",
|
||||
" trainer_type: ppo\n",
|
||||
" hyperparameters:\n",
|
||||
" batch_size: 2048\n",
|
||||
" buffer_size: 20480\n",
|
||||
" learning_rate: 0.0003\n",
|
||||
" beta: 0.005\n",
|
||||
" epsilon: 0.2\n",
|
||||
" lambd: 0.95\n",
|
||||
" num_epoch: 3\n",
|
||||
" learning_rate_schedule: linear\n",
|
||||
" network_settings:\n",
|
||||
" normalize: true\n",
|
||||
" hidden_units: 512\n",
|
||||
" num_layers: 3\n",
|
||||
" vis_encode_type: simple\n",
|
||||
" reward_signals:\n",
|
||||
" extrinsic:\n",
|
||||
" gamma: 0.995\n",
|
||||
" strength: 1.0\n",
|
||||
" checkpoint_interval: 200000\n",
|
||||
" keep_checkpoints: 15\n",
|
||||
" max_steps: 2e6\n",
|
||||
" time_horizon: 1000\n",
|
||||
" summary_freq: 50000"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "loQ0N5jhXW71"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"- Don't forget to save the file!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "oakN7UHwXdCX"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
@@ -345,9 +390,9 @@
|
||||
"\n",
|
||||
"- For instance **if you want to save more models during the training** (for now, we save every 200,000 training timesteps). You need to modify:\n",
|
||||
" - `checkpoint_interval`: The number of training timesteps collected between each checkpoint.\n",
|
||||
" - `keep_checkpoints`: The maximum number of model checkpoints to keep. \n",
|
||||
" - `keep_checkpoints`: The maximum number of model checkpoints to keep.\n",
|
||||
"\n",
|
||||
"=> Just keep in mind that **decreasing the `checkpoint_interval` means more models to upload to the Hub and so a longer uploading time** \n",
|
||||
"=> Just keep in mind that **decreasing the `checkpoint_interval` means more models to upload to the Hub and so a longer uploading time**\n",
|
||||
"We’re now ready to train our agent 🔥."
|
||||
],
|
||||
"metadata": {
|
||||
@@ -373,9 +418,9 @@
|
||||
"3. `--run_id`: the name you want to give to your training run id.\n",
|
||||
"4. `--no-graphics`: to not launch the visualization during the training.\n",
|
||||
"\n",
|
||||
"Train the model and use the `--resume` flag to continue training in case of interruption. \n",
|
||||
"Train the model and use the `--resume` flag to continue training in case of interruption.\n",
|
||||
"\n",
|
||||
"> It will fail first time when you use `--resume`, try running the block again to bypass the error. \n",
|
||||
"> It will fail first time when you use `--resume`, try running the block again to bypass the error.\n",
|
||||
"\n"
|
||||
]
|
||||
},
|
||||
@@ -422,7 +467,7 @@
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/notebooks/create-token.jpg\" alt=\"Create HF Token\">\n",
|
||||
"\n",
|
||||
"- Copy the token \n",
|
||||
"- Copy the token\n",
|
||||
"- Run the cell below and paste the token"
|
||||
],
|
||||
"metadata": {
|
||||
@@ -538,7 +583,7 @@
|
||||
"1. In step 1, choose your model repository which is the model id (in my case ThomasSimonini/ppo-Huggy).\n",
|
||||
"\n",
|
||||
"2. In step 2, **choose what model you want to replay**:\n",
|
||||
" - I have multiple ones, since we saved a model every 500000 timesteps. \n",
|
||||
" - I have multiple ones, since we saved a model every 500000 timesteps.\n",
|
||||
" - But since I want the more recent, I choose `Huggy.onnx`\n",
|
||||
"\n",
|
||||
"👉 What’s nice **is to try with different models steps to see the improvement of the agent.**"
|
||||
@@ -582,4 +627,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
}
|
||||
@@ -1,4 +1,4 @@
|
||||
stable-baselines3[extra]
|
||||
box2d-py
|
||||
stable-baselines3==2.0.0a5
|
||||
swig
|
||||
gymnasium[box2d]
|
||||
huggingface_sb3
|
||||
pyglet==1.5.1
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
gym==0.24
|
||||
gymnasium
|
||||
pygame
|
||||
numpy
|
||||
|
||||
@@ -8,4 +8,4 @@ pyyaml==6.0
|
||||
imageio
|
||||
imageio_ffmpeg
|
||||
pyglet==1.5.1
|
||||
tqdm
|
||||
tqdm
|
||||
@@ -3,10 +3,11 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "view-in-github"
|
||||
"id": "view-in-github",
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"<a href=\"https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/notebooks/unit2/unit2.ipynb\" target=\"_parent\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Open In Colab\"/></a>"
|
||||
"<a href=\"https://colab.research.google.com/github/huggingface/deep-rl-class/blob/GymnasiumUpdate%2FUnit2/notebooks/unit2/unit2.ipynb\" target=\"_parent\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Open In Colab\"/></a>"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -19,8 +20,7 @@
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit3/thumbnail.jpg\" alt=\"Unit 2 Thumbnail\">\n",
|
||||
"\n",
|
||||
"In this notebook, **you'll code from scratch your first Reinforcement Learning agent** playing FrozenLake ❄️ using Q-Learning, share it to the community, and experiment with different configurations.\n",
|
||||
"\n",
|
||||
"In this notebook, **you'll code your first Reinforcement Learning agent from scratch** to play FrozenLake ❄️ using Q-Learning, share it with the community, and experiment with different configurations.\n",
|
||||
"\n",
|
||||
"⬇️ Here is an example of what **you will achieve in just a couple of minutes.** ⬇️\n"
|
||||
]
|
||||
@@ -39,25 +39,18 @@
|
||||
"source": [
|
||||
"###🎮 Environments: \n",
|
||||
"\n",
|
||||
"- [FrozenLake-v1](https://www.gymlibrary.dev/environments/toy_text/frozen_lake/)\n",
|
||||
"- [Taxi-v3](https://www.gymlibrary.dev/environments/toy_text/taxi/)\n",
|
||||
"- [FrozenLake-v1](https://gymnasium.farama.org/environments/toy_text/frozen_lake/)\n",
|
||||
"- [Taxi-v3](https://gymnasium.farama.org/environments/toy_text/taxi/)\n",
|
||||
"\n",
|
||||
"###📚 RL-Library: \n",
|
||||
"\n",
|
||||
"- Python and NumPy\n",
|
||||
"- [Gym](https://www.gymlibrary.dev/)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "DPTBOv9HYLZ2"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"- [Gymnasium](https://gymnasium.farama.org/)\n",
|
||||
"\n",
|
||||
"We're constantly trying to improve our tutorials, so **if you find some issues in this notebook**, please [open an issue on the GitHub Repo](https://github.com/huggingface/deep-rl-class/issues)."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "3iaIxM_TwklQ"
|
||||
"id": "DPTBOv9HYLZ2"
|
||||
}
|
||||
},
|
||||
{
|
||||
@@ -70,8 +63,8 @@
|
||||
"\n",
|
||||
"At the end of the notebook, you will:\n",
|
||||
"\n",
|
||||
"- Be able to use **Gym**, the environment library.\n",
|
||||
"- Be able to code from scratch a Q-Learning agent.\n",
|
||||
"- Be able to use **Gymnasium**, the environment library.\n",
|
||||
"- Be able to code a Q-Learning agent from scratch.\n",
|
||||
"- Be able to **push your trained agent and the code to the Hub** with a nice video replay and an evaluation score 🔥.\n",
|
||||
"\n",
|
||||
"\n"
|
||||
@@ -81,6 +74,7 @@
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## This notebook is from the Deep Reinforcement Learning Course\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/notebooks/deep-rl-course-illustration.jpg\" alt=\"Deep RL Course illustration\"/>"
|
||||
],
|
||||
"metadata": {
|
||||
@@ -114,6 +108,7 @@
|
||||
},
|
||||
"source": [
|
||||
"## Prerequisites 🏗️\n",
|
||||
"\n",
|
||||
"Before diving into the notebook, you need to:\n",
|
||||
"\n",
|
||||
"🔲 📚 **Study [Q-Learning by reading Unit 2](https://huggingface.co/deep-rl-course/unit2/introduction)** 🤗 "
|
||||
@@ -134,18 +129,18 @@
|
||||
"id": "V68VveLacfxJ"
|
||||
},
|
||||
"source": [
|
||||
"- The *Q-Learning* **is the RL algorithm that** \n",
|
||||
"*Q-Learning* **is the RL algorithm that**:\n",
|
||||
"\n",
|
||||
" - Trains *Q-Function*, an **action-value function** that contains, as internal memory, a *Q-table* **that contains all the state-action pair values.**\n",
|
||||
" \n",
|
||||
" - Given a state and action, our Q-Function **will search into its Q-table the corresponding value.**\n",
|
||||
"- Trains *Q-Function*, an **action-value function** that encoded, in internal memory, by a *Q-table* **that contains all the state-action pair values.**\n",
|
||||
"\n",
|
||||
"- Given a state and action, our Q-Function **will search the Q-table for the corresponding value.**\n",
|
||||
" \n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit3/Q-function-2.jpg\" alt=\"Q function\" width=\"100%\"/>\n",
|
||||
"\n",
|
||||
"- When the training is done,**we have an optimal Q-Function, so an optimal Q-Table.**\n",
|
||||
" \n",
|
||||
"- And if we **have an optimal Q-function**, we\n",
|
||||
"have an optimal policy,since we **know for each state, what is the best action to take.**\n",
|
||||
"have an optimal policy, since we **know for, each state, the best action to take.**\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit3/link-value-policy.jpg\" alt=\"Link value policy\" width=\"100%\"/>\n",
|
||||
"\n",
|
||||
@@ -171,7 +166,6 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"\n",
|
||||
"To validate this hands-on for the [certification process](https://huggingface.co/deep-rl-course/en/unit0/introduction#certification-process), you need to push your trained Taxi model to the Hub and **get a result of >= 4.5**.\n",
|
||||
"\n",
|
||||
"To find your result, go to the [leaderboard](https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard) and find your model, **the result = mean_reward - std of reward**\n",
|
||||
@@ -193,13 +187,13 @@
|
||||
"\n",
|
||||
"We’ll install multiple ones:\n",
|
||||
"\n",
|
||||
"- `gym`: Contains the FrozenLake-v1 ⛄ and Taxi-v3 🚕 environments. We use `gym==0.24` since it contains a nice Taxi-v3 UI version.\n",
|
||||
"- `gymnasium`: Contains the FrozenLake-v1 ⛄ and Taxi-v3 🚕 environments. \n",
|
||||
"- `pygame`: Used for the FrozenLake-v1 and Taxi-v3 UI.\n",
|
||||
"- `numpy`: Used for handling our Q-table.\n",
|
||||
"\n",
|
||||
"The Hugging Face Hub 🤗 works as a central place where anyone can share and explore models and datasets. It has versioning, metrics, visualizations and other features that will allow you to easily collaborate with others.\n",
|
||||
"\n",
|
||||
"You can see here all the Deep RL models available (if they use Q Learning) 👉 https://huggingface.co/models?other=q-learning"
|
||||
"You can see here all the Deep RL models available (if they use Q Learning) here 👉 https://huggingface.co/models?other=q-learning"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "4gpxC1_kqUYe"
|
||||
@@ -233,7 +227,7 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"To make sure the new installed libraries are used, **sometimes it's required to restart the notebook runtime**. The next cell will force the **runtime to crash, so you'll need to connect again and run the code starting from here**. Thanks for this trick, **we will be able to run our virtual screen.**"
|
||||
"To make sure the new installed libraries are used, **sometimes it's required to restart the notebook runtime**. The next cell will force the **runtime to crash, so you'll need to connect again and run the code starting from here**. Thanks to this trick, **we will be able to run our virtual screen.**"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "K6XC13pTfFiD"
|
||||
@@ -289,7 +283,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import numpy as np\n",
|
||||
"import gym\n",
|
||||
"import gymnasium as gym\n",
|
||||
"import random\n",
|
||||
"import imageio\n",
|
||||
"import os\n",
|
||||
@@ -323,12 +317,12 @@
|
||||
"id": "NAvihuHdy9tw"
|
||||
},
|
||||
"source": [
|
||||
"## Create and understand [FrozenLake environment ⛄]((https://www.gymlibrary.dev/environments/toy_text/frozen_lake/)\n",
|
||||
"## Create and understand [FrozenLake environment ⛄]((https://gymnasium.farama.org/environments/toy_text/frozen_lake/)\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
"💡 A good habit when you start to use an environment is to check its documentation \n",
|
||||
"\n",
|
||||
"👉 https://www.gymlibrary.dev/environments/toy_text/frozen_lake/\n",
|
||||
"👉 https://gymnasium.farama.org/environments/toy_text/frozen_lake/\n",
|
||||
"\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
@@ -352,7 +346,10 @@
|
||||
"id": "UaW_LHfS0PY2"
|
||||
},
|
||||
"source": [
|
||||
"For now let's keep it simple with the 4x4 map and non-slippery"
|
||||
"For now let's keep it simple with the 4x4 map and non-slippery.\n",
|
||||
"We add a parameter called `render_mode` that specifies how the environment should be visualised. In our case because we **want to record a video of the environment at the end, we need to set render_mode to rgb_array**.\n",
|
||||
"\n",
|
||||
"As [explained in the documentation](https://gymnasium.farama.org/api/env/#gymnasium.Env.render) “rgb_array”: Return a single frame representing the current state of the environment. A frame is a np.ndarray with shape (x, y, 3) representing RGB values for an x-by-y pixel image."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -363,7 +360,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Create the FrozenLake-v1 environment using 4x4 map and non-slippery version\n",
|
||||
"# Create the FrozenLake-v1 environment using 4x4 map and non-slippery version and render_mode=\"rgb_array\"\n",
|
||||
"env = gym.make() # TODO use the correct parameters"
|
||||
]
|
||||
},
|
||||
@@ -384,7 +381,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"env = gym.make(\"FrozenLake-v1\", map_name=\"4x4\", is_slippery=False)"
|
||||
"env = gym.make(\"FrozenLake-v1\", map_name=\"4x4\", is_slippery=False, render_mode=\"rgb_array\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -480,6 +477,7 @@
|
||||
},
|
||||
"source": [
|
||||
"## Create and Initialize the Q-table 🗄️\n",
|
||||
"\n",
|
||||
"(👀 Step 1 of the pseudocode)\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit3/Q-learning-2.jpg\" alt=\"Q-Learning\" width=\"100%\"/>\n",
|
||||
@@ -584,12 +582,13 @@
|
||||
},
|
||||
"source": [
|
||||
"## Define the greedy policy 🤖\n",
|
||||
"\n",
|
||||
"Remember we have two policies since Q-Learning is an **off-policy** algorithm. This means we're using a **different policy for acting and updating the value function**.\n",
|
||||
"\n",
|
||||
"- Epsilon-greedy policy (acting policy)\n",
|
||||
"- Greedy-policy (updating policy)\n",
|
||||
"\n",
|
||||
"Greedy policy will also be the final policy we'll have when the Q-learning agent will be trained. The greedy policy is used to select an action from the Q-table.\n",
|
||||
"The greedy policy will also be the final policy we'll have when the Q-learning agent completes training. The greedy policy is used to select an action using the Q-table.\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit3/off-on-4.jpg\" alt=\"Q-Learning\" width=\"100%\"/>\n"
|
||||
]
|
||||
@@ -647,9 +646,9 @@
|
||||
"\n",
|
||||
"- With *probability 1 - ɛ* : **we do exploitation** (i.e. our agent selects the action with the highest state-action pair value).\n",
|
||||
"\n",
|
||||
"- With *probability ɛ*: we do **exploration** (trying random action).\n",
|
||||
"- With *probability ɛ*: we do **exploration** (trying a random action).\n",
|
||||
"\n",
|
||||
"And as the training goes, we progressively **reduce the epsilon value since we will need less and less exploration and more exploitation.**\n",
|
||||
"As the training continues, we progressively **reduce the epsilon value since we will need less and less exploration and more exploitation.**\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit3/Q-learning-4.jpg\" alt=\"Q-Learning\" width=\"100%\"/>\n"
|
||||
]
|
||||
@@ -696,9 +695,9 @@
|
||||
"source": [
|
||||
"def epsilon_greedy_policy(Qtable, state, epsilon):\n",
|
||||
" # Randomly generate a number between 0 and 1\n",
|
||||
" random_int = random.uniform(0,1)\n",
|
||||
" # if random_int > greater than epsilon --> exploitation\n",
|
||||
" if random_int > epsilon:\n",
|
||||
" random_num = random.uniform(0,1)\n",
|
||||
" # if random_num > greater than epsilon --> exploitation\n",
|
||||
" if random_num > epsilon:\n",
|
||||
" # Take the action with the highest value given a state\n",
|
||||
" # np.argmax can be useful here\n",
|
||||
" action = greedy_policy(Qtable, state)\n",
|
||||
@@ -716,6 +715,7 @@
|
||||
},
|
||||
"source": [
|
||||
"## Define the hyperparameters ⚙️\n",
|
||||
"\n",
|
||||
"The exploration related hyperparamters are some of the most important ones. \n",
|
||||
"\n",
|
||||
"- We need to make sure that our agent **explores enough of the state space** to learn a good value approximation. To do that, we need to have progressive decay of the epsilon.\n",
|
||||
@@ -789,9 +789,10 @@
|
||||
" # Reduce epsilon (because we need less and less exploration)\n",
|
||||
" epsilon = min_epsilon + (max_epsilon - min_epsilon)*np.exp(-decay_rate*episode)\n",
|
||||
" # Reset the environment\n",
|
||||
" state = env.reset()\n",
|
||||
" state, info = env.reset()\n",
|
||||
" step = 0\n",
|
||||
" done = False\n",
|
||||
" terminated = False\n",
|
||||
" truncated = False\n",
|
||||
"\n",
|
||||
" # repeat\n",
|
||||
" for step in range(max_steps):\n",
|
||||
@@ -800,13 +801,13 @@
|
||||
"\n",
|
||||
" # Take action At and observe Rt+1 and St+1\n",
|
||||
" # Take the action (a) and observe the outcome state(s') and reward (r)\n",
|
||||
" new_state, reward, done, info = \n",
|
||||
" new_state, reward, terminated, truncated, info =\n",
|
||||
"\n",
|
||||
" # Update Q(s,a):= Q(s,a) + lr [R(s,a) + gamma * max Q(s',a') - Q(s,a)]\n",
|
||||
" Qtable[state][action] = \n",
|
||||
"\n",
|
||||
" # If done, finish the episode\n",
|
||||
" if done:\n",
|
||||
" # If terminated or truncated finish the episode\n",
|
||||
" if terminated or truncated:\n",
|
||||
" break\n",
|
||||
" \n",
|
||||
" # Our next state is the new state\n",
|
||||
@@ -836,9 +837,10 @@
|
||||
" # Reduce epsilon (because we need less and less exploration)\n",
|
||||
" epsilon = min_epsilon + (max_epsilon - min_epsilon)*np.exp(-decay_rate*episode)\n",
|
||||
" # Reset the environment\n",
|
||||
" state = env.reset()\n",
|
||||
" state, info = env.reset()\n",
|
||||
" step = 0\n",
|
||||
" done = False\n",
|
||||
" terminated = False\n",
|
||||
" truncated = False\n",
|
||||
"\n",
|
||||
" # repeat\n",
|
||||
" for step in range(max_steps):\n",
|
||||
@@ -847,13 +849,13 @@
|
||||
"\n",
|
||||
" # Take action At and observe Rt+1 and St+1\n",
|
||||
" # Take the action (a) and observe the outcome state(s') and reward (r)\n",
|
||||
" new_state, reward, done, info = env.step(action)\n",
|
||||
" new_state, reward, terminated, truncated, info = env.step(action)\n",
|
||||
"\n",
|
||||
" # Update Q(s,a):= Q(s,a) + lr [R(s,a) + gamma * max Q(s',a') - Q(s,a)]\n",
|
||||
" Qtable[state][action] = Qtable[state][action] + learning_rate * (reward + gamma * np.max(Qtable[new_state]) - Qtable[state][action]) \n",
|
||||
"\n",
|
||||
" # If done, finish the episode\n",
|
||||
" if done:\n",
|
||||
" # If terminated or truncated finish the episode\n",
|
||||
" if terminated or truncated:\n",
|
||||
" break\n",
|
||||
" \n",
|
||||
" # Our next state is the new state\n",
|
||||
@@ -931,20 +933,21 @@
|
||||
" episode_rewards = []\n",
|
||||
" for episode in tqdm(range(n_eval_episodes)):\n",
|
||||
" if seed:\n",
|
||||
" state = env.reset(seed=seed[episode])\n",
|
||||
" state, info = env.reset(seed=seed[episode])\n",
|
||||
" else:\n",
|
||||
" state = env.reset()\n",
|
||||
" state, info = env.reset()\n",
|
||||
" step = 0\n",
|
||||
" done = False\n",
|
||||
" truncated = False\n",
|
||||
" terminated = False\n",
|
||||
" total_rewards_ep = 0\n",
|
||||
" \n",
|
||||
" for step in range(max_steps):\n",
|
||||
" # Take the action (index) that have the maximum expected future reward given that state\n",
|
||||
" action = greedy_policy(Q, state)\n",
|
||||
" new_state, reward, done, info = env.step(action)\n",
|
||||
" new_state, reward, terminated, truncated, info = env.step(action)\n",
|
||||
" total_rewards_ep += reward\n",
|
||||
" \n",
|
||||
" if done:\n",
|
||||
" if terminated or truncated:\n",
|
||||
" break\n",
|
||||
" state = new_state\n",
|
||||
" episode_rewards.append(total_rewards_ep)\n",
|
||||
@@ -1045,15 +1048,16 @@
|
||||
" :param fps: how many frame per seconds (with taxi-v3 and frozenlake-v1 we use 1)\n",
|
||||
" \"\"\"\n",
|
||||
" images = [] \n",
|
||||
" done = False\n",
|
||||
" state = env.reset(seed=random.randint(0,500))\n",
|
||||
" img = env.render(mode='rgb_array')\n",
|
||||
" terminated = False\n",
|
||||
" truncated = False\n",
|
||||
" state, info = env.reset(seed=random.randint(0,500))\n",
|
||||
" img = env.render()\n",
|
||||
" images.append(img)\n",
|
||||
" while not done:\n",
|
||||
" while not terminated or truncated:\n",
|
||||
" # Take the action (index) that have the maximum expected future reward given that state\n",
|
||||
" action = np.argmax(Qtable[state][:])\n",
|
||||
" state, reward, done, info = env.step(action) # We directly put next_state = state for recording logic\n",
|
||||
" img = env.render(mode='rgb_array')\n",
|
||||
" state, reward, terminated, truncated, info = env.step(action) # We directly put next_state = state for recording logic\n",
|
||||
" img = env.render()\n",
|
||||
" images.append(img)\n",
|
||||
" imageio.mimsave(out_directory, [np.array(img) for i, img in enumerate(images)], fps=fps)"
|
||||
]
|
||||
@@ -1209,7 +1213,7 @@
|
||||
"This way:\n",
|
||||
"- You can **showcase our work** 🔥\n",
|
||||
"- You can **visualize your agent playing** 👀\n",
|
||||
"- You can **share with the community an agent that others can use** 💾\n",
|
||||
"- You can **share an agent with the community that others can use** 💾\n",
|
||||
"- You can **access a leaderboard 🏆 to see how well your agent is performing compared to your classmates** 👉 https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard\n"
|
||||
]
|
||||
},
|
||||
@@ -1337,8 +1341,8 @@
|
||||
"id": "E2875IGsprzq"
|
||||
},
|
||||
"source": [
|
||||
"Congrats 🥳 you've just implemented from scratch, trained and uploaded your first Reinforcement Learning agent. \n",
|
||||
"FrozenLake-v1 no_slippery is very simple environment, let's try an harder one 🔥."
|
||||
"Congrats 🥳 you've just implemented from scratch, trained, and uploaded your first Reinforcement Learning agent.\n",
|
||||
"FrozenLake-v1 no_slippery is very simple environment, let's try a harder one 🔥."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -1349,12 +1353,12 @@
|
||||
"source": [
|
||||
"# Part 2: Taxi-v3 🚖\n",
|
||||
"\n",
|
||||
"## Create and understand [Taxi-v3 🚕](https://www.gymlibrary.dev/environments/toy_text/taxi/)\n",
|
||||
"## Create and understand [Taxi-v3 🚕](https://gymnasium.farama.org/environments/toy_text/taxi/)\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
"💡 A good habit when you start to use an environment is to check its documentation \n",
|
||||
"\n",
|
||||
"👉 https://www.gymlibrary.dev/environments/toy_text/taxi/\n",
|
||||
"👉 https://gymnasium.farama.org/environments/toy_text/taxi/\n",
|
||||
"\n",
|
||||
"---\n",
|
||||
"\n",
|
||||
@@ -1374,7 +1378,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"env = gym.make(\"Taxi-v3\")"
|
||||
"env = gym.make(\"Taxi-v3\", render_mode=\"rgb_array\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -1453,6 +1457,7 @@
|
||||
},
|
||||
"source": [
|
||||
"## Define the hyperparameters ⚙️\n",
|
||||
"\n",
|
||||
"⚠ DO NOT MODIFY EVAL_SEED: the eval_seed array **allows us to evaluate your agent with the same taxi starting positions for every classmate**"
|
||||
]
|
||||
},
|
||||
@@ -1516,6 +1521,7 @@
|
||||
},
|
||||
"source": [
|
||||
"## Create a model dictionary 💾 and publish our trained model to the Hub 🔥\n",
|
||||
"\n",
|
||||
"- We create a model dictionary that will contain all the training hyperparameters for reproducibility and the Q-Table.\n"
|
||||
]
|
||||
},
|
||||
@@ -1554,7 +1560,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"username = \"\" # FILL THIS\n",
|
||||
"repo_name = \"\"\n",
|
||||
"repo_name = \"\" # FILL THIS\n",
|
||||
"push_to_hub(\n",
|
||||
" repo_id=f\"{username}/{repo_name}\",\n",
|
||||
" model=model,\n",
|
||||
@@ -1567,9 +1573,8 @@
|
||||
"id": "ZgSdjgbIpRti"
|
||||
},
|
||||
"source": [
|
||||
"Now that's on the Hub, you can compare the results of your Taxi-v3 with your classmates using the leaderboard 🏆 👉 https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard\n",
|
||||
"Now that it's on the Hub, you can compare the results of your Taxi-v3 with your classmates using the leaderboard 🏆 👉 https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard\n",
|
||||
"\n",
|
||||
"⚠ To see your entry, you need to go to the bottom of the leaderboard page and **click on refresh** ⚠\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/notebooks/unit2/taxi-leaderboard.png\" alt=\"Taxi Leaderboard\">"
|
||||
]
|
||||
@@ -1690,17 +1695,18 @@
|
||||
},
|
||||
"source": [
|
||||
"## Some additional challenges 🏆\n",
|
||||
"The best way to learn **is to try things by your own**! As you saw, the current agent is not doing great. As a first suggestion, you can train for more steps. With 1,000,000 steps, we saw some great results! \n",
|
||||
"\n",
|
||||
"The best way to learn **is to try things on your own**! As you saw, the current agent is not doing great. As a first suggestion, you can train for more steps. With 1,000,000 steps, we saw some great results!\n",
|
||||
"\n",
|
||||
"In the [Leaderboard](https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard) you will find your agents. Can you get to the top?\n",
|
||||
"\n",
|
||||
"Here are some ideas to achieve so:\n",
|
||||
"Here are some ideas to climb up the leaderboard:\n",
|
||||
"\n",
|
||||
"* Train more steps\n",
|
||||
"* Try different hyperparameters by looking at what your classmates have done.\n",
|
||||
"* **Push your new trained model** on the Hub 🔥\n",
|
||||
"\n",
|
||||
"Are walking on ice and driving taxis too boring to you? Try to **change the environment**, why not using FrozenLake-v1 slippery version? Check how they work [using the gym documentation](https://www.gymlibrary.dev/) and have fun 🎉."
|
||||
"Are walking on ice and driving taxis too boring to you? Try to **change the environment**, why not use FrozenLake-v1 slippery version? Check how they work [using the gymnasium documentation](https://gymnasium.farama.org/) and have fun 🎉."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -1714,7 +1720,7 @@
|
||||
"\n",
|
||||
"Understanding Q-Learning is an **important step to understanding value-based methods.**\n",
|
||||
"\n",
|
||||
"In the next Unit with Deep Q-Learning, we'll see that creating and updating a Q-table was a good strategy — **however, this is not scalable.**\n",
|
||||
"In the next Unit with Deep Q-Learning, we'll see that while creating and updating a Q-table was a good strategy — **however, it is not scalable.**\n",
|
||||
"\n",
|
||||
"For instance, imagine you create an agent that learns to play Doom. \n",
|
||||
"\n",
|
||||
@@ -1722,7 +1728,7 @@
|
||||
"\n",
|
||||
"Doom is a large environment with a huge state space (millions of different states). Creating and updating a Q-table for that environment would not be efficient. \n",
|
||||
"\n",
|
||||
"That's why we'll study, in the next unit, Deep Q-Learning, an algorithm **where we use a neural network that approximates, given a state, the different Q-values for each action.**\n",
|
||||
"That's why we'll study Deep Q-Learning in the next unit, an algorithm **where we use a neural network that approximates, given a state, the different Q-values for each action.**\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit4/atari-envs.gif\" alt=\"Environments\"/>\n"
|
||||
]
|
||||
@@ -1733,7 +1739,7 @@
|
||||
"id": "BjLhT70TEZIn"
|
||||
},
|
||||
"source": [
|
||||
"See you on Unit 3! 🔥\n",
|
||||
"See you in Unit 3! 🔥\n",
|
||||
"\n",
|
||||
"## Keep learning, stay awesome 🤗"
|
||||
]
|
||||
@@ -1744,10 +1750,12 @@
|
||||
"private_outputs": true,
|
||||
"provenance": [],
|
||||
"collapsed_sections": [
|
||||
"Ji_UrI5l2zzn",
|
||||
"67OdoKL63eDD",
|
||||
"B2_-8b8z5k54"
|
||||
]
|
||||
"B2_-8b8z5k54",
|
||||
"8R5ej1fS4P2V",
|
||||
"Pnpk2ePoem3r"
|
||||
],
|
||||
"include_colab_link": true
|
||||
},
|
||||
"gpuClass": "standard",
|
||||
"kernelspec": {
|
||||
@@ -1760,4 +1768,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
}
|
||||
@@ -7,7 +7,7 @@
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"<a href=\"https://colab.research.google.com/github/huggingface/deep-rl-class/blob/ThomasSimonini%2FUnit3/notebooks/unit3/unit3.ipynb\" target=\"_parent\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Open In Colab\"/></a>"
|
||||
"<a href=\"https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/notebooks/unit3.ipynb\" target=\"_parent\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Open In Colab\"/></a>"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -44,7 +44,9 @@
|
||||
"source": [
|
||||
"### 🎮 Environments: \n",
|
||||
"\n",
|
||||
"- SpacesInvadersNoFrameskip-v4 \n",
|
||||
"- [SpacesInvadersNoFrameskip-v4](https://gymnasium.farama.org/environments/atari/space_invaders/)\n",
|
||||
"\n",
|
||||
"You can see the difference between Space Invaders versions here 👉 https://gymnasium.farama.org/environments/atari/space_invaders/#variants\n",
|
||||
"\n",
|
||||
"### 📚 RL-Library: \n",
|
||||
"\n",
|
||||
@@ -127,6 +129,10 @@
|
||||
"source": [
|
||||
"# Let's train a Deep Q-Learning agent playing Atari' Space Invaders 👾 and upload it to the Hub.\n",
|
||||
"\n",
|
||||
"We strongly recommend students **to use Google Colab for the hands-on exercises instead of running them on their personal computers**.\n",
|
||||
"\n",
|
||||
"By using Google Colab, **you can focus on learning and experimenting without worrying about the technical aspects of setting up your environments**.\n",
|
||||
"\n",
|
||||
"To validate this hands-on for the certification process, you need to push your trained model to the Hub and **get a result of >= 200**.\n",
|
||||
"\n",
|
||||
"To find your result, go to the leaderboard and find your model, **the result = mean_reward - std of reward**\n",
|
||||
@@ -173,6 +179,81 @@
|
||||
"id": "KV0NyFdQM9ZG"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"# Install RL-Baselines3 Zoo and its dependencies 📚\n",
|
||||
"\n",
|
||||
"If you see `ERROR: pip's dependency resolver does not currently take into account all the packages that are installed.` **this is normal and it's not a critical error** there's a conflict of version. But the packages we need are installed."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "wS_cVefO-aYg"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"# For now we install this update of RL-Baselines3 Zoo\n",
|
||||
"!pip install git+https://github.com/DLR-RM/rl-baselines3-zoo@update/hf"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "hLTwHqIWdnPb"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"IF AND ONLY IF THE VERSION ABOVE DOES NOT EXIST ANYMORE. UNCOMMENT AND INSTALL THE ONE BELOW"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "p0xe2sJHdtHy"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"#!pip install rl_zoo3==2.0.0a9"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "N0d6wy-F-f39"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!apt-get install swig cmake ffmpeg"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "8_MllY6Om1eI"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "4S9mJiKg6SqC"
|
||||
},
|
||||
"source": [
|
||||
"To be able to use Atari games in Gymnasium we need to install atari package. And accept-rom-license to download the rom files (games files)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!pip install gymnasium[atari]\n",
|
||||
"!pip install gymnasium[accept-rom-license]"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "NsRP-lX1_2fC"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
@@ -201,29 +282,6 @@
|
||||
"!pip3 install pyvirtualdisplay"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"# Additional dependencies for RL Baselines3 Zoo\n",
|
||||
"!apt-get install swig cmake freeglut3-dev "
|
||||
],
|
||||
"metadata": {
|
||||
"id": "fWyKJCy_NJBX"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!pip install pyglet==1.5.1"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "C5LwHrISW7Q5"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
@@ -234,68 +292,11 @@
|
||||
"virtual_display.start()"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "ww5PQH1gNLI4"
|
||||
"id": "BE5JWP5rQIKf"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "mYIMvl5X9NAu"
|
||||
},
|
||||
"source": [
|
||||
"## Clone RL-Baselines3 Zoo Repo 📚\n",
|
||||
"You can now directly install from python package `pip install rl_zoo3` but since we want **the full installation with extra environments and dependencies** we're going to clone `RL-Baselines3-Zoo` repository and install from source."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "eu5ZDPZ09VNQ"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!git clone https://github.com/DLR-RM/rl-baselines3-zoo"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "HCIoSbvbfAQh"
|
||||
},
|
||||
"source": [
|
||||
"## Install dependencies 🔽\n",
|
||||
"We can now install the dependencies RL-Baselines3 Zoo needs (this can take 5min ⏲)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "s2QsFAk29h-D"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%cd /content/rl-baselines3-zoo/ \n",
|
||||
"!git checkout v1.8.0"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "3QaOS7Xj9j1s"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install setuptools==65.5.0\n",
|
||||
"!pip install -r requirements.txt\n",
|
||||
"# Since colab uses Python 3.9 we need to add this installation\n",
|
||||
"!pip install gym[atari,accept-rom-license]==0.21.0"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -305,9 +306,31 @@
|
||||
"## Train our Deep Q-Learning Agent to Play Space Invaders 👾\n",
|
||||
"\n",
|
||||
"To train an agent with RL-Baselines3-Zoo, we just need to do two things:\n",
|
||||
"1. We define the hyperparameters in `/content/rl-baselines3-zoo/hyperparams/dqn.yml`\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/notebooks/unit3/hyperparameters.png\" alt=\"DQN Hyperparameters\">\n"
|
||||
"1. Create a hyperparameter config file that will contain our training hyperparameters called `dqn.yml`.\n",
|
||||
"\n",
|
||||
"This is a template example:\n",
|
||||
"\n",
|
||||
"```\n",
|
||||
"SpaceInvadersNoFrameskip-v4:\n",
|
||||
" env_wrapper:\n",
|
||||
" - stable_baselines3.common.atari_wrappers.AtariWrapper\n",
|
||||
" frame_stack: 4\n",
|
||||
" policy: 'CnnPolicy'\n",
|
||||
" n_timesteps: !!float 1e7\n",
|
||||
" buffer_size: 100000\n",
|
||||
" learning_rate: !!float 1e-4\n",
|
||||
" batch_size: 32\n",
|
||||
" learning_starts: 100000\n",
|
||||
" target_update_interval: 1000\n",
|
||||
" train_freq: 4\n",
|
||||
" gradient_steps: 1\n",
|
||||
" exploration_fraction: 0.1\n",
|
||||
" exploration_final_eps: 0.01\n",
|
||||
" # If True, you need to deactivate handle_timeout_termination\n",
|
||||
" # in the replay_buffer_kwargs\n",
|
||||
" optimize_memory_usage: False\n",
|
||||
"```"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -346,7 +369,9 @@
|
||||
"id": "Hn8bRTHvERRL"
|
||||
},
|
||||
"source": [
|
||||
"2. We run `train.py` and save the models on `logs` folder 📁"
|
||||
"2. We start the training and save the models on `logs` folder 📁\n",
|
||||
"\n",
|
||||
"- Define the algorithm after `--algo`, where we save the model after `-f` and where the hyperparameter config is after `-c`."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -357,7 +382,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!python train.py --algo ________ --env SpaceInvadersNoFrameskip-v4 -f _________"
|
||||
"!python -m rl_zoo3.train --algo ________ --env SpaceInvadersNoFrameskip-v4 -f _________ -c _________"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -377,7 +402,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!python train.py --algo dqn --env SpaceInvadersNoFrameskip-v4 -f logs/"
|
||||
"!python -m rl_zoo3.train --algo dqn --env SpaceInvadersNoFrameskip-v4 -f logs/ -c dqn.yml"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -399,7 +424,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!python enjoy.py --algo dqn --env SpaceInvadersNoFrameskip-v4 --no-render --n-timesteps _________ --folder logs/"
|
||||
"!python -m rl_zoo3.enjoy --algo dqn --env SpaceInvadersNoFrameskip-v4 --no-render --n-timesteps _________ --folder logs/ "
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -419,7 +444,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!python enjoy.py --algo dqn --env SpaceInvadersNoFrameskip-v4 --no-render --n-timesteps 5000 --folder logs/"
|
||||
"!python -m rl_zoo3.enjoy --algo dqn --env SpaceInvadersNoFrameskip-v4 --no-render --n-timesteps 5000 --folder logs/"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -440,7 +465,7 @@
|
||||
"id": "ezbHS1q3HYVV"
|
||||
},
|
||||
"source": [
|
||||
"By using `rl_zoo3.push_to_hub.py` **you evaluate, record a replay, generate a model card of your agent and push it to the hub**.\n",
|
||||
"By using `rl_zoo3.push_to_hub` **you evaluate, record a replay, generate a model card of your agent and push it to the hub**.\n",
|
||||
"\n",
|
||||
"This way:\n",
|
||||
"- You can **showcase our work** 🔥\n",
|
||||
@@ -518,6 +543,8 @@
|
||||
"\n",
|
||||
"`-orga`: Your Hugging Face username\n",
|
||||
"\n",
|
||||
"`-f`: Where the trained model folder is (in our case `logs`)\n",
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/notebooks/unit3/select-id.png\" alt=\"Select Id\">"
|
||||
]
|
||||
},
|
||||
@@ -649,7 +676,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!python enjoy.py --algo dqn --env BeamRiderNoFrameskip-v4 -n 5000 -f rl_trained/"
|
||||
"!python -m rl_zoo3.enjoy --algo dqn --env BeamRiderNoFrameskip-v4 -n 5000 -f rl_trained/ --no-render"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -803,4 +830,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
}
|
||||
@@ -1,6 +1,5 @@
|
||||
gym
|
||||
git+https://github.com/ntasfi/PyGame-Learning-Environment.git
|
||||
git+https://github.com/qlan3/gym-games.git
|
||||
git+https://github.com/simoninithomas/gym-games
|
||||
huggingface_hub
|
||||
imageio-ffmpeg
|
||||
pyyaml==6.0
|
||||
|
||||
@@ -1357,8 +1357,8 @@
|
||||
"- next blocks bottom y location\n",
|
||||
"\n",
|
||||
"The action space(2) 🎮:\n",
|
||||
"- Up\n",
|
||||
"- Down\n",
|
||||
"- Up (press accelerator) \n",
|
||||
"- Do nothing (don't press accelerator) \n",
|
||||
"\n",
|
||||
"The reward function 💰: \n",
|
||||
"- For each vertical block it passes through it gains a positive reward of +1. Each time a terminal state reached it receives a negative reward of -1."
|
||||
@@ -1620,4 +1620,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
}
|
||||
|
||||
@@ -68,9 +68,7 @@
|
||||
"\n",
|
||||
"### 📚 RL-Library: \n",
|
||||
"\n",
|
||||
"- [ML-Agents (HuggingFace Experimental Version)](https://github.com/huggingface/ml-agents)\n",
|
||||
"\n",
|
||||
"⚠ We're going to use an experimental version of ML-Agents were you can push to hub and load from hub Unity ML-Agents Models **you need to install the same version**"
|
||||
"- [ML-Agents](https://github.com/Unity-Technologies/ml-agents)\n"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "A-cYE0K5iL-w"
|
||||
@@ -146,9 +144,7 @@
|
||||
"source": [
|
||||
"# Let's train our agents 🚀\n",
|
||||
"\n",
|
||||
"The ML-Agents integration on the Hub is **still experimental**, some features will be added in the future. \n",
|
||||
"\n",
|
||||
"But for now, **to validate this hands-on for the certification process, you just need to push your trained models to the Hub**. There’s no results to attain to validate this one. But if you want to get nice results you can try to attain:\n",
|
||||
"**To validate this hands-on for the certification process, you just need to push your trained models to the Hub**. There’s no results to attain to validate this one. But if you want to get nice results you can try to attain:\n",
|
||||
"\n",
|
||||
"- For `Pyramids` : Mean Reward = 1.75\n",
|
||||
"- For `SnowballTarget` : Mean Reward = 15 or 30 targets hit in an episode.\n"
|
||||
@@ -186,8 +182,7 @@
|
||||
"id": "an3ByrXYQ4iK"
|
||||
},
|
||||
"source": [
|
||||
"## Clone the repository and install the dependencies 🔽\n",
|
||||
"- We need to clone the repository, that **contains the experimental version of the library that allows you to push your trained agent to the Hub.**"
|
||||
"## Clone the repository and install the dependencies 🔽\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -200,7 +195,7 @@
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"# Clone the repository\n",
|
||||
"!git clone --depth 1 --branch hf-integration-save https://github.com/huggingface/ml-agents"
|
||||
"!git clone --depth 1 https://github.com/Unity-Technologies/ml-agents"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -218,19 +213,6 @@
|
||||
"!pip3 install -e ./ml-agents"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"# Due to some conflicts between mlagents and tensorflow we need to uninstall it\n",
|
||||
"!pip3 uninstall tensorflow -y"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "ozcA_tl_XTrv"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
@@ -521,7 +503,7 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!mlagents-push-to-hf --run-id=\"SnowballTarget1\" --local-dir=\"./results/SnowballTarget2\" --repo-id=\"ThomasSimonini/ppo-SnowballTargetTESTCOLAB\" --commit-message=\"First Push\""
|
||||
"!mlagents-push-to-hf --run-id=\"SnowballTarget1\" --local-dir=\"./results/SnowballTarget1\" --repo-id=\"ThomasSimonini/ppo-SnowballTarget\" --commit-message=\"First Push\""
|
||||
],
|
||||
"metadata": {
|
||||
"id": "kAFzVB7OYj_H"
|
||||
@@ -575,7 +557,7 @@
|
||||
"\n",
|
||||
"1. Remember your repo-id\n",
|
||||
"\n",
|
||||
"2. Go here: https://singularite.itch.io/snowballtarget\n",
|
||||
"2. Go here: https://huggingface.co/spaces/ThomasSimonini/ML-Agents-SnowballTarget\n",
|
||||
"\n",
|
||||
"3. Launch the game and put it in full screen by clicking on the bottom right button\n",
|
||||
"\n",
|
||||
@@ -761,15 +743,6 @@
|
||||
"- Now that we trained our agent, we’re **ready to push it to the Hub to be able to visualize it playing on your browser🔥.**"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [],
|
||||
"metadata": {
|
||||
"id": "JZ53caJ99sX_"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
@@ -786,7 +759,7 @@
|
||||
"source": [
|
||||
"### Watch your agent playing 👀\n",
|
||||
"\n",
|
||||
"The temporary link for Pyramids demo is: https://singularite.itch.io/pyramids"
|
||||
"👉 https://huggingface.co/spaces/unity/ML-Agents-Pyramids"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "7aZfgxo-CDeQ"
|
||||
@@ -798,7 +771,7 @@
|
||||
"### 🎁 Bonus: Why not train on another environment?\n",
|
||||
"Now that you know how to train an agent using MLAgents, **why not try another environment?** \n",
|
||||
"\n",
|
||||
"MLAgents provides 18 different and we’re building some custom ones. The best way to learn is to try things of your own, have fun.\n",
|
||||
"MLAgents provides 17 different and we’re building some custom ones. The best way to learn is to try things of your own, have fun.\n",
|
||||
"\n"
|
||||
],
|
||||
"metadata": {
|
||||
@@ -817,15 +790,13 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"You have the full list of the one currently available on Hugging Face here 👉 https://github.com/huggingface/ml-agents#the-environments\n",
|
||||
"You have the full list of the Unity official environments here 👉 https://github.com/Unity-Technologies/ml-agents/blob/develop/docs/Learning-Environment-Examples.md\n",
|
||||
"\n",
|
||||
"For the demos to visualize your agent, the temporary link is: https://singularite.itch.io (temporary because we'll also put the demos on Hugging Face Space)\n",
|
||||
"For the demos to visualize your agent 👉 https://huggingface.co/unity\n",
|
||||
"\n",
|
||||
"For now we have integrated: \n",
|
||||
"- [Worm](https://singularite.itch.io/worm) demo where you teach a **worm to crawl**.\n",
|
||||
"- [Walker](https://singularite.itch.io/walker) demo where you teach an agent **to walk towards a goal**.\n",
|
||||
"\n",
|
||||
"If you want new demos to be added, please open an issue: https://github.com/huggingface/deep-rl-class 🤗"
|
||||
"- [Worm](https://huggingface.co/spaces/unity/ML-Agents-Worm) demo where you teach a **worm to crawl**.\n",
|
||||
"- [Walker](https://huggingface.co/spaces/unity/ML-Agents-Walker) demo where you teach an agent **to walk towards a goal**."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "YiyF4FX-04JB"
|
||||
@@ -836,7 +807,7 @@
|
||||
"source": [
|
||||
"That’s all for today. Congrats on finishing this tutorial!\n",
|
||||
"\n",
|
||||
"The best way to learn is to practice and try stuff. Why not try another environment? ML-Agents has 18 different environments, but you can also create your own? Check the documentation and have fun!\n",
|
||||
"The best way to learn is to practice and try stuff. Why not try another environment? ML-Agents has 17 different environments, but you can also create your own? Check the documentation and have fun!\n",
|
||||
"\n",
|
||||
"See you on Unit 6 🔥,\n",
|
||||
"\n",
|
||||
@@ -865,4 +836,4 @@
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
}
|
||||
@@ -5,7 +5,6 @@
|
||||
"colab": {
|
||||
"provenance": [],
|
||||
"private_outputs": true,
|
||||
"authorship_tag": "ABX9TyPDFLK3trc6MCLJLqUUuAbl",
|
||||
"include_colab_link": true
|
||||
},
|
||||
"kernelspec": {
|
||||
@@ -36,7 +35,7 @@
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit8/thumbnail.png\" alt=\"Thumbnail\"/>\n",
|
||||
"\n",
|
||||
"In this notebook, you'll learn to use A2C with PyBullet and Panda-Gym, two set of robotics environments. \n",
|
||||
"In this notebook, you'll learn to use A2C with PyBullet and Panda-Gym, two set of robotics environments.\n",
|
||||
"\n",
|
||||
"With [PyBullet](https://github.com/bulletphysics/bullet3), you're going to **train a robot to move**:\n",
|
||||
"- `AntBulletEnv-v0` 🕸️ More precisely, a spider (they say Ant but come on... it's a spider 😆) 🕸️\n",
|
||||
@@ -62,12 +61,12 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"### 🎮 Environments: \n",
|
||||
"### 🎮 Environments:\n",
|
||||
"\n",
|
||||
"- [PyBullet](https://github.com/bulletphysics/bullet3)\n",
|
||||
"- [Panda-Gym](https://github.com/qgallouedec/panda-gym)\n",
|
||||
"\n",
|
||||
"###📚 RL-Library: \n",
|
||||
"###📚 RL-Library:\n",
|
||||
"\n",
|
||||
"- [Stable-Baselines3](https://stable-baselines3.readthedocs.io/)"
|
||||
],
|
||||
@@ -112,7 +111,7 @@
|
||||
"\n",
|
||||
"- 📖 Study Deep Reinforcement Learning in **theory and practice**.\n",
|
||||
"- 🧑💻 Learn to **use famous Deep RL libraries** such as Stable Baselines3, RL Baselines3 Zoo, CleanRL and Sample Factory 2.0.\n",
|
||||
"- 🤖 Train **agents in unique environments** \n",
|
||||
"- 🤖 Train **agents in unique environments**\n",
|
||||
"\n",
|
||||
"And more check 📚 the syllabus 👉 https://simoninithomas.github.io/deep-rl-course\n",
|
||||
"\n",
|
||||
@@ -192,7 +191,7 @@
|
||||
"source": [
|
||||
"## Create a virtual display 🔽\n",
|
||||
"\n",
|
||||
"During the notebook, we'll need to generate a replay video. To do so, with colab, **we need to have a virtual screen to be able to render the environment** (and thus record the frames). \n",
|
||||
"During the notebook, we'll need to generate a replay video. To do so, with colab, **we need to have a virtual screen to be able to render the environment** (and thus record the frames).\n",
|
||||
"\n",
|
||||
"Hence the following cell will install the librairies and create and run a virtual screen 🖥"
|
||||
],
|
||||
@@ -249,8 +248,8 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"# Install the specific setuptools version required to install the dependencies\n",
|
||||
"!pip install setuptools==65.5.0"
|
||||
"# Install the specific setuptools and wheel version required to install the dependencies\n",
|
||||
"!pip install setuptools==65.5.0 wheel==0.38.4"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "eUamMNshb6ee"
|
||||
@@ -266,7 +265,10 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!pip install -r https://raw.githubusercontent.com/huggingface/deep-rl-class/main/notebooks/unit6/requirements-unit6.txt"
|
||||
"!pip install stable-baselines3[extra]==1.8.0\n",
|
||||
"!pip install huggingface_sb3\n",
|
||||
"!pip install panda_gym==2.0.0\n",
|
||||
"!pip install pyglet==1.5.1"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -403,7 +405,7 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"A good practice in reinforcement learning is to [normalize input features](https://stable-baselines3.readthedocs.io/en/master/guide/rl_tips.html). \n",
|
||||
"A good practice in reinforcement learning is to [normalize input features](https://stable-baselines3.readthedocs.io/en/master/guide/rl_tips.html).\n",
|
||||
"\n",
|
||||
"For that purpose, there is a wrapper that will compute a running average and standard deviation of input features.\n",
|
||||
"\n",
|
||||
@@ -630,7 +632,7 @@
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/notebooks/create-token.jpg\" alt=\"Create HF Token\">\n",
|
||||
"\n",
|
||||
"- Copy the token \n",
|
||||
"- Copy the token\n",
|
||||
"- Run the cell below and paste the token"
|
||||
]
|
||||
},
|
||||
@@ -855,7 +857,7 @@
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"# 6\n",
|
||||
"model_name = \"a2c-PandaReachDense-v2\"; \n",
|
||||
"model_name = \"a2c-PandaReachDense-v2\";\n",
|
||||
"model.save(model_name)\n",
|
||||
"env.save(\"vec_normalize.pkl\")\n",
|
||||
"\n",
|
||||
@@ -927,4 +929,4 @@
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
@@ -7,7 +7,7 @@
|
||||
"colab_type": "text"
|
||||
},
|
||||
"source": [
|
||||
"<a href=\"https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/notebooks/unit8/unit8_part1.ipynb\" target=\"_parent\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Open In Colab\"/></a>"
|
||||
"<a href=\"https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/notebooks/unit8_part1.ipynb\" target=\"_parent\"><img src=\"https://colab.research.google.com/assets/colab-badge.svg\" alt=\"Open In Colab\"/></a>"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -156,6 +156,17 @@
|
||||
"id": "bTpYcVZVMzUI"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!pip install setuptools==65.5.0"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "Fd731S8-NuJA"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -188,17 +199,6 @@
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!pip install setuptools==65.5.0"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "Fd731S8-NuJA"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -206,16 +206,16 @@
|
||||
},
|
||||
"source": [
|
||||
"## Install dependencies 🔽\n",
|
||||
"For this exercise, we use `gym==0.21`\n"
|
||||
"For this exercise, we use `gym==0.22`."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!pip install gym==0.21\n",
|
||||
"!pip install gym==0.22\n",
|
||||
"!pip install imageio-ffmpeg\n",
|
||||
"!pip install huggingface_hub\n",
|
||||
"!pip install box2d"
|
||||
"!pip install gym[box2d]==0.22"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "9xZQFTPcsKUK"
|
||||
@@ -1275,6 +1275,7 @@
|
||||
},
|
||||
"source": [
|
||||
"## Let's start the training 🔥\n",
|
||||
"- ⚠️ ⚠️ ⚠️ Don't use **the same repo id with the one you used for the Unit 1** \n",
|
||||
"- Now that you've coded from scratch PPO and added the Hugging Face Integration, we're ready to start the training 🔥"
|
||||
]
|
||||
},
|
||||
@@ -1352,6 +1353,7 @@
|
||||
"colab": {
|
||||
"private_outputs": true,
|
||||
"provenance": [],
|
||||
"history_visible": true,
|
||||
"include_colab_link": true
|
||||
},
|
||||
"gpuClass": "standard",
|
||||
|
||||
@@ -41,7 +41,7 @@
|
||||
"from IPython.display import HTML\n",
|
||||
"\n",
|
||||
"HTML('''<video width=\"640\" height=\"480\" controls>\n",
|
||||
" <source src=\"https://huggingface.co/edbeeching/doom_health_gathering_supreme_3333/resolve/main/replay.mp4\" \n",
|
||||
" <source src=\"https://huggingface.co/edbeeching/doom_health_gathering_supreme_3333/resolve/main/replay.mp4\"\n",
|
||||
" type=\"video/mp4\">Your browser does not support the video tag.</video>'''\n",
|
||||
")"
|
||||
]
|
||||
@@ -124,15 +124,15 @@
|
||||
"\n",
|
||||
"### How sample-factory works\n",
|
||||
"\n",
|
||||
"Sample-factory is one of the **most highly optimized RL implementations available to the community**. \n",
|
||||
"Sample-factory is one of the **most highly optimized RL implementations available to the community**.\n",
|
||||
"\n",
|
||||
"It works by **spawning multiple processes that run rollout workers, inference workers and a learner worker**. \n",
|
||||
"It works by **spawning multiple processes that run rollout workers, inference workers and a learner worker**.\n",
|
||||
"\n",
|
||||
"The *workers* **communicate through shared memory, which lowers the communication cost between processes**. \n",
|
||||
"The *workers* **communicate through shared memory, which lowers the communication cost between processes**.\n",
|
||||
"\n",
|
||||
"The *rollout workers* interact with the environment and send observations to the *inference workers*. \n",
|
||||
"The *rollout workers* interact with the environment and send observations to the *inference workers*.\n",
|
||||
"\n",
|
||||
"The *inferences workers* query a fixed version of the policy and **send actions back to the rollout worker**. \n",
|
||||
"The *inferences workers* query a fixed version of the policy and **send actions back to the rollout worker**.\n",
|
||||
"\n",
|
||||
"After *k* steps the rollout works send a trajectory of experience to the learner worker, **which it uses to update the agent’s policy network**.\n",
|
||||
"\n",
|
||||
@@ -164,9 +164,9 @@
|
||||
"source": [
|
||||
"## ViZDoom\n",
|
||||
"\n",
|
||||
"[ViZDoom](https://vizdoom.cs.put.edu.pl/) is an **open-source python interface for the Doom Engine**. \n",
|
||||
"[ViZDoom](https://vizdoom.cs.put.edu.pl/) is an **open-source python interface for the Doom Engine**.\n",
|
||||
"\n",
|
||||
"The library was created in 2016 by Marek Wydmuch, Michal Kempka at the Institute of Computing Science, Poznan University of Technology, Poland. \n",
|
||||
"The library was created in 2016 by Marek Wydmuch, Michal Kempka at the Institute of Computing Science, Poznan University of Technology, Poland.\n",
|
||||
"\n",
|
||||
"The library enables the **training of agents directly from the screen pixels in a number of scenarios**, including team deathmatch, shown in the video below. Because the ViZDoom environment is based on a game the was created in the 90s, it can be run on modern hardware at accelerated speeds, **allowing us to learn complex AI behaviors fairly quickly**.\n",
|
||||
"\n",
|
||||
@@ -195,7 +195,7 @@
|
||||
"source": [
|
||||
"## We first need to install some dependencies that are required for the ViZDoom environment\n",
|
||||
"\n",
|
||||
"Now that our Colab runtime is set up, we can start by installing the dependencies required to run ViZDoom on linux. \n",
|
||||
"Now that our Colab runtime is set up, we can start by installing the dependencies required to run ViZDoom on linux.\n",
|
||||
"\n",
|
||||
"If you are following on your machine on Mac, you will want to follow the installation instructions on the [github page](https://github.com/Farama-Foundation/ViZDoom/blob/master/doc/Quickstart.md#-quickstart-for-macos-and-anaconda3-python-36)."
|
||||
]
|
||||
@@ -210,7 +210,7 @@
|
||||
"source": [
|
||||
"%%capture\n",
|
||||
"%%bash\n",
|
||||
"# Install ViZDoom deps from \n",
|
||||
"# Install ViZDoom deps from\n",
|
||||
"# https://github.com/mwydmuch/ViZDoom/blob/master/doc/Building.md#-linux\n",
|
||||
"\n",
|
||||
"apt-get install build-essential zlib1g-dev libsdl2-dev libjpeg-dev \\\n",
|
||||
@@ -244,11 +244,21 @@
|
||||
"source": [
|
||||
"# install python libraries\n",
|
||||
"# thanks toinsson\n",
|
||||
"!pip install sample-factory==2.0.2\n",
|
||||
"!pip install faster-fifo==1.4.2\n",
|
||||
"!pip install vizdoom"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!pip install sample-factory==2.0.2"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "alxUt7Au-O8e"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -330,7 +340,7 @@
|
||||
"- 1 available game variable: HEALTH\n",
|
||||
"- death penalty = 100\n",
|
||||
"\n",
|
||||
"You can find out more about the scenarios available in ViZDoom [here](https://github.com/Farama-Foundation/ViZDoom/tree/master/scenarios). \n",
|
||||
"You can find out more about the scenarios available in ViZDoom [here](https://github.com/Farama-Foundation/ViZDoom/tree/master/scenarios).\n",
|
||||
"\n",
|
||||
"There are also a number of more complex scenarios that have been create for ViZDoom, such as the ones detailed on [this github page](https://github.com/edbeeching/3d_control_deep_rl).\n",
|
||||
"\n"
|
||||
@@ -451,7 +461,7 @@
|
||||
"\n",
|
||||
"<img src=\"https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/notebooks/create-token.jpg\" alt=\"Create HF Token\">\n",
|
||||
"\n",
|
||||
"- Copy the token \n",
|
||||
"- Copy the token\n",
|
||||
"- Run the cell below and paste the token"
|
||||
]
|
||||
},
|
||||
@@ -571,7 +581,7 @@
|
||||
"source": [
|
||||
"## Some additional challenges 🏆: Doom Deathmatch\n",
|
||||
"\n",
|
||||
"Training an agent to play a Doom deathmatch **takes many hours on a more beefy machine than is available in Colab**. \n",
|
||||
"Training an agent to play a Doom deathmatch **takes many hours on a more beefy machine than is available in Colab**.\n",
|
||||
"\n",
|
||||
"Fortunately, we have have **already trained an agent in this scenario and it is available in the 🤗 Hub!** Let’s download the model and visualize the agent’s performance."
|
||||
],
|
||||
|
||||
@@ -1,88 +0,0 @@
|
||||
# DEPRECIATED THE NEW UNIT 1 IS HERE: https://huggingface.co/deep-rl-course/unit1/introduction
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unit1/introduction
|
||||
|
||||
|
||||
# Unit 1: Introduction to Deep Reinforcement Learning 🚀 (DEPRECIATED)
|
||||
|
||||

|
||||
|
||||
In this Unit, you'll learn the foundations of Deep Reinforcement Learning. And **you’ll train your first lander agent 🚀 to land correctly on the Moon 🌕** using Stable-Baselines3 and share it with the community.
|
||||
|
||||
<img src="assets/img/LunarLander.gif" alt="LunarLander"/>
|
||||
|
||||
You'll then be able to **[compare your agent’s results with other classmates thanks to the leaderboard](https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard)** 🔥.
|
||||
|
||||
This course is **self-paced**, you can start whenever you want.
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- **2 hours** for the theory
|
||||
- **1 hour** for the hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣ 📝 **Sign up to the course** , to receive the updates when each Unit is published.
|
||||
|
||||
2️⃣ **Sign up to our Discord Server**. This is the place where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Are you new to Discord? Check our **discord 101 to get the best practices** 👉 https://github.com/huggingface/deep-rl-class/blob/main/DISCORD.Md
|
||||
|
||||
3️⃣ 👋 **Introduce yourself on Discord in #introduce-yourself Discord channel 🤗 and check on the left the Reinforcement Learning section.**
|
||||
|
||||
- In #rl-announcements we give the last information about the course.
|
||||
- #discussions is a place to exchange.
|
||||
- #unity-ml-agents is to exchange about everything related to this library.
|
||||
- #study-groups, to create study groups with your classmates.
|
||||
|
||||
<img src="assets/img/discord_channels.jpg" alt="Discord Channels"/>
|
||||
|
||||
4️⃣ 📖 **Read An [Introduction to Deep Reinforcement Learning](https://huggingface.co/blog/deep-rl-intro)**, where you’ll learn the foundations of Deep RL. You can also watch the video version attached to the article. 👉 https://huggingface.co/blog/deep-rl-intro
|
||||
|
||||
5️⃣ 📝 Take a piece of paper and **check your knowledge with this series of questions** ❔ 👉 https://github.com/huggingface/deep-rl-class/blob/main/unit1/quiz.md
|
||||
|
||||
6️⃣ 👩💻 Then dive on the hands-on, where **you’ll train your first lander agent 🚀 to land correctly on the Moon 🌕 using Stable-Baselines3 and share it with the community.** Thanks to a leaderboard, **you'll be able to compare your results with other classmates** and exchange the best practices to improve your agent's scores Who will win the challenge for Unit 1 🏆?
|
||||
|
||||
👩💻 The hands-on 👉 [](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit1/unit1.ipynb)
|
||||
|
||||
🏆 The leaderboard 👉 https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
You can work directly **with the colab notebook, which allows you not to have to install everything on your machine (and it’s free)**.
|
||||
|
||||
The best way to learn **is to try things on your own**. That’s why we have a challenges section in the colab where we give you some ideas on how you can go further: using another environment, using another model etc.
|
||||
|
||||
7️⃣ (Optional) In order to **find the best training parameters you can try this hands-on** made by [Sambit Mukherjee](https://github.com/sambitmukherjee) 👉 https://github.com/huggingface/deep-rl-class/blob/main/unit1/unit1_optuna_guide.ipynb
|
||||
|
||||
## Additional readings 📚
|
||||
- [Reinforcement Learning: An Introduction, Richard Sutton and Andrew G. Barto Chapter 1, 2 and 3](http://incompleteideas.net/book/RLbook2020.pdf)
|
||||
- [Foundations of Deep RL Series, L1 MDPs, Exact Solution Methods, Max-ent RL by Pieter Abbeel](https://youtu.be/2GwBez0D20A)
|
||||
- [Spinning Up RL by OpenAI Part 1: Key concepts of RL](https://spinningup.openai.com/en/latest/spinningup/rl_intro.html)
|
||||
|
||||
- [Getting Started With OpenAI Gym: The Basic Building Blocks](https://blog.paperspace.com/getting-started-with-openai-gym/)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes.
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳.
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
## Keep learning, stay awesome 🤗,
|
||||

|
Before Width: | Height: | Size: 375 KiB |

|
Before Width: | Height: | Size: 20 KiB |

|
Before Width: | Height: | Size: 295 KiB |

|
Before Width: | Height: | Size: 146 KiB |

|
Before Width: | Height: | Size: 71 KiB |

|
Before Width: | Height: | Size: 64 KiB |

|
Before Width: | Height: | Size: 93 KiB |

|
Before Width: | Height: | Size: 88 KiB |

|
Before Width: | Height: | Size: 324 KiB |

|
Before Width: | Height: | Size: 220 KiB |

|
Before Width: | Height: | Size: 75 KiB |

|
Before Width: | Height: | Size: 56 KiB |
137
unit1/quiz.md
@@ -1,137 +0,0 @@
|
||||
# Knowledge Check ✔️
|
||||
|
||||
The best way to learn and [to avoid the illusion of competence](https://fr.coursera.org/lecture/learning-how-to-learn/illusions-of-competence-BuFzf) **is to test yourself.** This will help you to find **where you need to reinforce your knowledge**.
|
||||
|
||||
📝 Take a piece of paper and try to answer by writing, **then check the solutions**.
|
||||
|
||||
### Q1: What is Reinforcement Learning?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
Reinforcement learning is a **framework for solving control tasks (also called decision problems)** by building agents that learn from the environment by interacting with it through trial and error and **receiving rewards (positive or negative) as unique feedback**.
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#a-formal-definition
|
||||
|
||||
</details>
|
||||
|
||||
### Q2: Define the RL Loop
|
||||
|
||||
<img src="assets/img/rl-loop-ex.jpg" alt="Exercise RL Loop"/>
|
||||
|
||||
At every step:
|
||||
- Our Agent receives ______ from the environment
|
||||
- Based on that ______ the Agent takes an ______
|
||||
- Our Agent will move to the right
|
||||
- The Environment goes to a ______
|
||||
- The Environment gives ______ to the Agent
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
<img src="assets/img/rl-loop-solution.jpg" alt="Exercise RL Solution"/>
|
||||
|
||||
|
||||
At every step:
|
||||
- Our Agent receives **state s0** from the environment
|
||||
- Based on that **state s0** the Agent takes an **action a0**
|
||||
- Our Agent will move to the right
|
||||
- The Environment goes to a **new state s1**
|
||||
- The Environment gives **a reward r1** to the Agent
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#the-rl-process
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
### Q3: What's the difference between a state and an observation?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
- *The state* is a **complete description of the state of the world** (there is no hidden information), in a fully observed environment. For instance, in chess game, we receive a state from the environment since we have access to the whole checkboard information.
|
||||
|
||||
- *The observation* is a **partial description of the state**. In a partially observed environment. For instance, in Super Mario Bros, we only see a part of the level close to the player, so we receive an observation.
|
||||
|
||||
<img src="assets/img/obs_space_recap.jpg" alt="Observation Space Recap"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#observationsstates-space
|
||||
|
||||
</details>
|
||||
|
||||
### Q4: A task is an instance of a Reinforcement Learning problem. What are the two types of tasks?
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
- *Episodic task* : we have a **starting point and an ending point (a terminal state)**. This creates an episode: a list of States, Actions, Rewards, and new States. For instance, think about Super Mario Bros: an episode begin at the launch of a new Mario Level and ending when you’re killed or you reached the end of the level.
|
||||
|
||||
- *Continuous task* : these are tasks that **continue forever (no terminal state)**. In this case, the agent must learn how to choose the best actions and simultaneously interact with the environment.
|
||||
|
||||
<img src="assets/img/tasks.jpg" alt="Task"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#type-of-tasks
|
||||
|
||||
</details>
|
||||
|
||||
### Q5: What is the exploration/exploitation tradeoff?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
In Reinforcement Learning, we need to **balance how much we explore the environment and how much we exploit what we know about the environment**.
|
||||
|
||||
- *Exploration* is exploring the environment by **trying random actions in order to find more information about the environment**.
|
||||
|
||||
- *Exploitation* is **exploiting known information to maximize the reward**.
|
||||
|
||||
<img src="assets/img/expexpltradeoff.jpg" alt="Exploration/exploitation tradeoff"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#exploration-exploitation-tradeoff
|
||||
</details>
|
||||
|
||||
### Q6: What is a policy?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
- The Policy π **is the brain of our Agent**, it’s the function that tell us what action to take given the state we are. So it defines the agent’s behavior at a given time.
|
||||
|
||||
<img src="assets/img/policy.jpg" alt="Policy"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#the-policy-%CF%80-the-agents-brain
|
||||
</details>
|
||||
|
||||
|
||||
### Q7: What are value-based methods?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
- Value-based methods is one of the main approaches for solving RL problems.
|
||||
- In Value-based methods, instead of training a policy function, **we train a value function that maps a state to the expected value of being at that state**.
|
||||
|
||||
<img src="assets/img/value.jpg" alt="Value illustration"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#value-based-methods
|
||||
</details>
|
||||
|
||||
### Q8: What are policy-based methods?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
- In *Policy-Based Methods*, we learn a **policy function directly**.
|
||||
- This policy function will **map from each state to the best corresponding action at that state**. Or a **probability distribution over the set of possible actions at that state**.
|
||||
|
||||
<img src="assets/img/policy.jpg" alt="Policy illustration"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-intro#value-based-methods
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
Congrats on **finishing this Quiz** 🥳, if you missed some elements, take time to [read again the chapter](https://huggingface.co/blog/deep-rl-intro) to reinforce (😏) your knowledge.
|
||||
|
||||
**Keep Learning, Stay Awesome**
|
||||
@@ -1,21 +0,0 @@
|
||||
# Unit 1: Bonus 🎁
|
||||
- Our teammate @Chris Emezue published a new leaderboard where you can compare your trained agents in new environments 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
## Try new environments 🎮
|
||||
Now that you've played with LunarLander-v2 Why not try these environments? 🔥:
|
||||
- 🗻 MountainCar-v0 https://www.gymlibrary.dev/environments/classic_control/mountain_car/
|
||||
- 🏎️ CarRacing-v1 https://www.gymlibrary.dev/environments/box2d/car_racing/
|
||||
- 🥶 FrozenLake-v1 https://www.gymlibrary.dev/environments/toy_text/frozen_lake/
|
||||
|
||||
## A piece of advice 🧐
|
||||
The first Unit, is a very interesting one but also **a very complex one because it's where you learn the fundamentals.**
|
||||
|
||||
That’s normal if you **still feel confused with all these elements**. This was the same for me and for all people who studied RL.
|
||||
|
||||
Take time to really grasp the material before continuing. It’s important to master these elements and having a solid foundations before entering the fun part.
|
||||
|
||||
We published additional readings in the syllabus if you want to go deeper 👉 https://github.com/huggingface/deep-rl-class/blob/main/unit1/README.md
|
||||
|
||||
The hands-on for the first Unit are more funny experiments, but as we'll go deeper, **you'll understand better how to choose the hyperparameters and what model to use. For now, have fun, try stuff you can't break the simulations 🚀 **
|
||||
|
||||
### Keep learning, stay awesome.
|
||||
1207
unit1/unit1.ipynb
@@ -1,571 +0,0 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "59a253e3",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## This notebook will guide you through logging your experiments"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 7,
|
||||
"id": "2e020e33",
|
||||
"metadata": {
|
||||
"ExecuteTime": {
|
||||
"end_time": "2022-05-08T01:11:29.835785Z",
|
||||
"start_time": "2022-05-08T01:11:29.831878Z"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Import libraries \n",
|
||||
"\n",
|
||||
"# The Training Libs\n",
|
||||
"import gym\n",
|
||||
"from stable_baselines3 import PPO\n",
|
||||
"from stable_baselines3.common.evaluation import evaluate_policy\n",
|
||||
"from stable_baselines3.common.env_util import make_vec_env\n",
|
||||
"\n",
|
||||
"from stable_baselines3.common.vec_env import VecVideoRecorder , DummyVecEnv\n",
|
||||
"\n",
|
||||
"# Import wandb stuff\n",
|
||||
"import wandb\n",
|
||||
"from wandb.integration.sb3 import WandbCallback"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "fa321aa8",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Weights and biases (wandb)\n",
|
||||
"\n",
|
||||
"[Weights and Biases](https://wandb.ai/) is a free and open source logging platform that allows you to track multiple results when you are training your model. It collects various metrics, and organizes them in an simple web dashboard. \n",
|
||||
"\n",
|
||||
"In this notebook, we will see how simple it is to start tracking your experiments with weights and biases"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "285ecb67",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"It can log all the training metrics that is output during the training phase, along with a video of our agent at that point in our training. Additionally, it also logs system status like CPU/GPU usage and temperature.\n",
|
||||
"\n",
|
||||
"They have good documentation, which can be found here - https://docs.wandb.ai/"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "fbefa8c4",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Setup for wandb\n",
|
||||
"\n",
|
||||
"1. Create an account on wandb - https://wandb.ai/\n",
|
||||
"\n",
|
||||
"2. Install wandb: \n",
|
||||
"\n",
|
||||
" Wandb is distributed as a python package. To install it, run `pip install wandb`.\n",
|
||||
" \n",
|
||||
"3. Login into wandb:\n",
|
||||
"\n",
|
||||
" To login into wandb, run `wandb login`. Paste the api key. The key can be found here - https://wandb.ai/authorize"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 2,
|
||||
"id": "ae0fd212",
|
||||
"metadata": {
|
||||
"ExecuteTime": {
|
||||
"end_time": "2022-05-08T00:55:11.285850Z",
|
||||
"start_time": "2022-05-08T00:55:05.640088Z"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stderr",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"\u001b[34m\u001b[1mwandb\u001b[0m: Currently logged in as: \u001b[33msupersecurehuman\u001b[0m. Use \u001b[1m`wandb login --relogin`\u001b[0m to force relogin\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"Tracking run with wandb version 0.12.16"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"Run data is saved locally in <code>/home/venom/Desktop/deep-rl-class/unit1/unit1_bonus/wandb/run-20220508_062506-2ovixu73</code>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"Syncing run <strong><a href=\"https://wandb.ai/supersecurehuman/LunarLander-v2/runs/2ovixu73\" target=\"_blank\">warm-gorge-3</a></strong> to <a href=\"https://wandb.ai/supersecurehuman/LunarLander-v2\" target=\"_blank\">Weights & Biases</a> (<a href=\"https://wandb.me/run\" target=\"_blank\">docs</a>)<br/>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Initialize wandb\n",
|
||||
"# https://docs.wandb.ai/guides/integrations/other/stable-baselines-3\n",
|
||||
"\n",
|
||||
"config = {\n",
|
||||
" \"policy_type\": \"MlpPolicy\",\n",
|
||||
" \"total_timesteps\": 100000,\n",
|
||||
" \"env_name\": \"LunarLander-v2\",\n",
|
||||
" \"learning_rate\" : 0.0002,\n",
|
||||
"}\n",
|
||||
"\n",
|
||||
"run = wandb.init(\n",
|
||||
" project=\"LunarLander-v2\", # It creates a project on wandb if it doesnt exist. The logging happens there\n",
|
||||
" config=config,\n",
|
||||
" sync_tensorboard=True, # auto-upload tensorboard metrics\n",
|
||||
" monitor_gym=True, # auto-upload the videos of agents playing the game\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# After running this cell, go to https://wandb.ai/home to see your new project created"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "5ee51e03",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Now, we will create a environment and a model to log the training\n",
|
||||
"\n",
|
||||
"This part is covered in the main notebook\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 3,
|
||||
"id": "0b8046ae",
|
||||
"metadata": {
|
||||
"ExecuteTime": {
|
||||
"end_time": "2022-05-08T00:55:59.965683Z",
|
||||
"start_time": "2022-05-08T00:55:55.396867Z"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Using cuda device\n"
|
||||
]
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"env = make_vec_env('LunarLander-v2', n_envs=16)\n",
|
||||
"# Use the following line with caution. The video recorder will try to render the agent on the screen, so that ffmpeg can capture it. Here, we have 16 envs set. Trying to render 16 envs on screen will\n",
|
||||
"# be pretty resource intensive. \n",
|
||||
"# env = VecVideoRecorder(env, f\"videos/{run.id}\", record_video_trigger=lambda x: x % 2000 == 0, video_length=200) # Set the video recorder, to record our agent during training\n",
|
||||
"\n",
|
||||
"# I would suggest you to add all your hyperparameters in the config dictionary defined before the wandb init step. This would help you to visualize the effect those hyper parameters\n",
|
||||
"# have on your model, via the wandb dashboard\n",
|
||||
"model = PPO(\n",
|
||||
" policy = config[\"policy_type\"],\n",
|
||||
" env = env,\n",
|
||||
" learning_rate=config[\"learning_rate\"],\n",
|
||||
" tensorboard_log=\"logs\",\n",
|
||||
" verbose=1)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 4,
|
||||
"id": "f772cc3f",
|
||||
"metadata": {
|
||||
"ExecuteTime": {
|
||||
"end_time": "2022-05-08T00:59:14.354142Z",
|
||||
"start_time": "2022-05-08T00:56:32.259913Z"
|
||||
},
|
||||
"scrolled": true
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"name": "stdout",
|
||||
"output_type": "stream",
|
||||
"text": [
|
||||
"Logging to logs/PPO_1\n",
|
||||
"---------------------------------\n",
|
||||
"| rollout/ | |\n",
|
||||
"| ep_len_mean | 91.1 |\n",
|
||||
"| ep_rew_mean | -170 |\n",
|
||||
"| time/ | |\n",
|
||||
"| fps | 5432 |\n",
|
||||
"| iterations | 1 |\n",
|
||||
"| time_elapsed | 6 |\n",
|
||||
"| total_timesteps | 32768 |\n",
|
||||
"---------------------------------\n",
|
||||
"-----------------------------------------\n",
|
||||
"| rollout/ | |\n",
|
||||
"| ep_len_mean | 98.9 |\n",
|
||||
"| ep_rew_mean | -132 |\n",
|
||||
"| time/ | |\n",
|
||||
"| fps | 1480 |\n",
|
||||
"| iterations | 2 |\n",
|
||||
"| time_elapsed | 44 |\n",
|
||||
"| total_timesteps | 65536 |\n",
|
||||
"| train/ | |\n",
|
||||
"| approx_kl | 0.009069282 |\n",
|
||||
"| clip_fraction | 0.0836 |\n",
|
||||
"| clip_range | 0.2 |\n",
|
||||
"| entropy_loss | -1.38 |\n",
|
||||
"| explained_variance | 0.00211 |\n",
|
||||
"| learning_rate | 0.0002 |\n",
|
||||
"| loss | 345 |\n",
|
||||
"| n_updates | 10 |\n",
|
||||
"| policy_gradient_loss | -0.00783 |\n",
|
||||
"| value_loss | 810 |\n",
|
||||
"-----------------------------------------\n",
|
||||
"-----------------------------------------\n",
|
||||
"| rollout/ | |\n",
|
||||
"| ep_len_mean | 103 |\n",
|
||||
"| ep_rew_mean | -104 |\n",
|
||||
"| time/ | |\n",
|
||||
"| fps | 1135 |\n",
|
||||
"| iterations | 3 |\n",
|
||||
"| time_elapsed | 86 |\n",
|
||||
"| total_timesteps | 98304 |\n",
|
||||
"| train/ | |\n",
|
||||
"| approx_kl | 0.012206479 |\n",
|
||||
"| clip_fraction | 0.12 |\n",
|
||||
"| clip_range | 0.2 |\n",
|
||||
"| entropy_loss | -1.35 |\n",
|
||||
"| explained_variance | 0.436 |\n",
|
||||
"| learning_rate | 0.0002 |\n",
|
||||
"| loss | 77.5 |\n",
|
||||
"| n_updates | 20 |\n",
|
||||
"| policy_gradient_loss | -0.0125 |\n",
|
||||
"| value_loss | 335 |\n",
|
||||
"-----------------------------------------\n",
|
||||
"-----------------------------------------\n",
|
||||
"| rollout/ | |\n",
|
||||
"| ep_len_mean | 113 |\n",
|
||||
"| ep_rew_mean | -87.2 |\n",
|
||||
"| time/ | |\n",
|
||||
"| fps | 1031 |\n",
|
||||
"| iterations | 4 |\n",
|
||||
"| time_elapsed | 127 |\n",
|
||||
"| total_timesteps | 131072 |\n",
|
||||
"| train/ | |\n",
|
||||
"| approx_kl | 0.012416394 |\n",
|
||||
"| clip_fraction | 0.167 |\n",
|
||||
"| clip_range | 0.2 |\n",
|
||||
"| entropy_loss | -1.31 |\n",
|
||||
"| explained_variance | 0.513 |\n",
|
||||
"| learning_rate | 0.0002 |\n",
|
||||
"| loss | 66.1 |\n",
|
||||
"| n_updates | 30 |\n",
|
||||
"| policy_gradient_loss | -0.015 |\n",
|
||||
"| value_loss | 257 |\n",
|
||||
"-----------------------------------------\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/plain": [
|
||||
"<stable_baselines3.ppo.ppo.PPO at 0x7fb0d70ccd50>"
|
||||
]
|
||||
},
|
||||
"execution_count": 4,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Now we do the magical stuff of logging to wandb. All you have to do is add the wandb callback to the model's callback like this\n",
|
||||
"\n",
|
||||
"model.learn(total_timesteps=config[\"total_timesteps\"], \n",
|
||||
" callback=[WandbCallback(\n",
|
||||
" gradient_save_freq=100\n",
|
||||
" )])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 5,
|
||||
"id": "d2a6341c",
|
||||
"metadata": {
|
||||
"ExecuteTime": {
|
||||
"end_time": "2022-05-08T00:59:27.663456Z",
|
||||
"start_time": "2022-05-08T00:59:14.382414Z"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"Waiting for W&B process to finish... <strong style=\"color:green\">(success).</strong>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"application/vnd.jupyter.widget-view+json": {
|
||||
"model_id": "",
|
||||
"version_major": 2,
|
||||
"version_minor": 0
|
||||
},
|
||||
"text/plain": [
|
||||
"VBox(children=(Label(value='0.002 MB of 0.002 MB uploaded (0.000 MB deduped)\\r'), FloatProgress(value=1.0, max…"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"<style>\n",
|
||||
" table.wandb td:nth-child(1) { padding: 0 10px; text-align: left ; width: auto;} td:nth-child(2) {text-align: left ; width: 100%}\n",
|
||||
" .wandb-row { display: flex; flex-direction: row; flex-wrap: wrap; justify-content: flex-start; width: 100% }\n",
|
||||
" .wandb-col { display: flex; flex-direction: column; flex-basis: 100%; flex: 1; padding: 10px; }\n",
|
||||
" </style>\n",
|
||||
"<div class=\"wandb-row\"><div class=\"wandb-col\"><h3>Run history:</h3><br/><table class=\"wandb\"><tr><td>global_step</td><td>▁▃▆█</td></tr><tr><td>rollout/ep_len_mean</td><td>▁▃▅█</td></tr><tr><td>rollout/ep_rew_mean</td><td>▁▄▇█</td></tr><tr><td>time/fps</td><td>█▂▁▁</td></tr><tr><td>train/approx_kl</td><td>▁██</td></tr><tr><td>train/clip_fraction</td><td>▁▄█</td></tr><tr><td>train/clip_range</td><td>▁▁▁</td></tr><tr><td>train/entropy_loss</td><td>▁▄█</td></tr><tr><td>train/explained_variance</td><td>▁▇█</td></tr><tr><td>train/learning_rate</td><td>▁▁▁</td></tr><tr><td>train/loss</td><td>█▁▁</td></tr><tr><td>train/policy_gradient_loss</td><td>█▃▁</td></tr><tr><td>train/value_loss</td><td>█▂▁</td></tr></table><br/></div><div class=\"wandb-col\"><h3>Run summary:</h3><br/><table class=\"wandb\"><tr><td>global_step</td><td>131072</td></tr><tr><td>rollout/ep_len_mean</td><td>113.48</td></tr><tr><td>rollout/ep_rew_mean</td><td>-87.24881</td></tr><tr><td>time/fps</td><td>1031.0</td></tr><tr><td>train/approx_kl</td><td>0.01242</td></tr><tr><td>train/clip_fraction</td><td>0.16663</td></tr><tr><td>train/clip_range</td><td>0.2</td></tr><tr><td>train/entropy_loss</td><td>-1.30755</td></tr><tr><td>train/explained_variance</td><td>0.51275</td></tr><tr><td>train/learning_rate</td><td>0.0002</td></tr><tr><td>train/loss</td><td>66.06168</td></tr><tr><td>train/policy_gradient_loss</td><td>-0.01496</td></tr><tr><td>train/value_loss</td><td>257.38614</td></tr></table><br/></div></div>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"Synced <strong style=\"color:#cdcd00\">warm-gorge-3</strong>: <a href=\"https://wandb.ai/supersecurehuman/LunarLander-v2/runs/2ovixu73\" target=\"_blank\">https://wandb.ai/supersecurehuman/LunarLander-v2/runs/2ovixu73</a><br/>Synced 6 W&B file(s), 0 media file(s), 0 artifact file(s) and 1 other file(s)"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
},
|
||||
{
|
||||
"data": {
|
||||
"text/html": [
|
||||
"Find logs at: <code>./wandb/run-20220508_062506-2ovixu73/logs</code>"
|
||||
],
|
||||
"text/plain": [
|
||||
"<IPython.core.display.HTML object>"
|
||||
]
|
||||
},
|
||||
"metadata": {},
|
||||
"output_type": "display_data"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# Finish run\n",
|
||||
"run.finish()\n",
|
||||
"\n",
|
||||
"# This cell output will also give a global summary, along with giving you the link to view your run."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "e9f1e6a5",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Note\n",
|
||||
"\n",
|
||||
"You need to enable tensorboard logging to view your training metrics in wandb dashboard."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "629f050a",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Package to 🤗 hub"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 10,
|
||||
"id": "8be43170",
|
||||
"metadata": {
|
||||
"ExecuteTime": {
|
||||
"end_time": "2022-05-08T01:13:41.386029Z",
|
||||
"start_time": "2022-05-08T01:13:41.335337Z"
|
||||
}
|
||||
},
|
||||
"outputs": [
|
||||
{
|
||||
"data": {
|
||||
"text/plain": []
|
||||
},
|
||||
"execution_count": 10,
|
||||
"metadata": {},
|
||||
"output_type": "execute_result"
|
||||
}
|
||||
],
|
||||
"source": [
|
||||
"# You have to disable wandb while packaging it to hub, because it seems to be interfering with package to hub function.\n",
|
||||
"wandb.init(mode=\"disabled\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "481c5eae",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from huggingface_hub import notebook_login # To log to our Hugging Face account to be able to upload models to the Hub."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "91d45e2a",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Note: You just need to run notebook_login() once in any machine you are trying to login. The token is saved in you machine, making future access to your account easier\n",
|
||||
"notebook_login()\n",
|
||||
"!git config --global credential.helper store"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "0192bfe0",
|
||||
"metadata": {
|
||||
"ExecuteTime": {
|
||||
"end_time": "2022-05-08T01:14:35.254796Z",
|
||||
"start_time": "2022-05-08T01:13:43.366135Z"
|
||||
}
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from huggingface_sb3 import package_to_hub\n",
|
||||
"\n",
|
||||
"env_id = config[\"env_name\"]\n",
|
||||
"\n",
|
||||
"model_architecture = \"PPO\"\n",
|
||||
"model_name = \"PPO-LunarLander-v2\"\n",
|
||||
"\n",
|
||||
"repo_id = \"SuperSecureHuman/LunarLander_v2_PPO_wandb\"\n",
|
||||
"\n",
|
||||
"commit_message = \"Initial Commit\"\n",
|
||||
"\n",
|
||||
"eval_env = DummyVecEnv([lambda: gym.make(env_id)])\n",
|
||||
"\n",
|
||||
"package_to_hub(model=model, # Our trained model\n",
|
||||
" model_name=model_name, # The name of our trained model \n",
|
||||
" model_architecture=model_architecture, # The model architecture we used: in our case PPO\n",
|
||||
" env_id=env_id, # Name of the environment\n",
|
||||
" eval_env=eval_env, # Evaluation Environment\n",
|
||||
" repo_id=repo_id, # id of the model repository from the Hugging Face Hub\n",
|
||||
" commit_message=commit_message)\n",
|
||||
"eval_env.close()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "9368a9f9",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Congrats!\n",
|
||||
"\n",
|
||||
"Now you have now started to use wandb in your project. Do checkout the docs to know what are the other amazing stuff it is capable off!"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3 (ipykernel)",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.7.12"
|
||||
},
|
||||
"toc": {
|
||||
"base_numbering": 1,
|
||||
"nav_menu": {},
|
||||
"number_sections": true,
|
||||
"sideBar": true,
|
||||
"skip_h1_title": false,
|
||||
"title_cell": "Table of Contents",
|
||||
"title_sidebar": "Contents",
|
||||
"toc_cell": false,
|
||||
"toc_position": {},
|
||||
"toc_section_display": true,
|
||||
"toc_window_display": false
|
||||
},
|
||||
"varInspector": {
|
||||
"cols": {
|
||||
"lenName": 16,
|
||||
"lenType": 16,
|
||||
"lenVar": 40
|
||||
},
|
||||
"kernels_config": {
|
||||
"python": {
|
||||
"delete_cmd_postfix": "",
|
||||
"delete_cmd_prefix": "del ",
|
||||
"library": "var_list.py",
|
||||
"varRefreshCmd": "print(var_dic_list())"
|
||||
},
|
||||
"r": {
|
||||
"delete_cmd_postfix": ") ",
|
||||
"delete_cmd_prefix": "rm(",
|
||||
"library": "var_list.r",
|
||||
"varRefreshCmd": "cat(var_dic_list()) "
|
||||
}
|
||||
},
|
||||
"types_to_exclude": [
|
||||
"module",
|
||||
"function",
|
||||
"builtin_function_or_method",
|
||||
"instance",
|
||||
"_Feature"
|
||||
],
|
||||
"window_display": false
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 5
|
||||
}
|
||||
@@ -1,546 +0,0 @@
|
||||
{
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0,
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "Unit 1 Special Content: Optuna Guide.ipynb",
|
||||
"provenance": [],
|
||||
"collapsed_sections": []
|
||||
},
|
||||
"kernelspec": {
|
||||
"name": "python3",
|
||||
"display_name": "Python 3"
|
||||
},
|
||||
"language_info": {
|
||||
"name": "python"
|
||||
}
|
||||
},
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"# Unit 1 Special Content: Optuna Guide"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "RpLWg64qubE9"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"In this notebook, we shall see how to use Optuna to perform hyperparameter tuning of Unit 1's <a href=\"https://stable-baselines3.readthedocs.io/en/master/modules/ppo.html\" target=\"_blank\">`PPO`</a> model (created using Stable-Baselines3 for the `\"LunarLander-v2\"` Gym environment).\n",
|
||||
"\n",
|
||||
"Optuna is an open-source, automatic hyperparameter optimization framework. You can read more about it <a href=\"https://tech.preferred.jp/en/blog/optuna-release/\" target=\"_blank\">here</a>.\n",
|
||||
"\n",
|
||||
"**Prerequisite:** Before going through this notebook, you should have completed the <a href=\"https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit1/unit1.ipynb\" target=\"_blank\">Unit 1 hands-on</a>."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "cWpMuD7jrfze"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Virtual Display Setup"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "InZX9_sRtfbO"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"We'll need to generate a replay video. To do so in Colab, we need to have a virtual display to be able to render the environment (and thus record the frames).\n",
|
||||
"\n",
|
||||
"The following cell will install virtual display libraries."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "QvvCztQ5tZxq"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "oUfu-vzL4g97"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"!apt install python-opengl\n",
|
||||
"!apt install ffmpeg\n",
|
||||
"!apt install xvfb\n",
|
||||
"!pip install pyvirtualdisplay"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Now, let's create & start a virtual display."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "UVt5deF2qorb"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"from pyvirtualdisplay import Display\n",
|
||||
"\n",
|
||||
"virtual_display = Display(visible=0, size=(1400, 900))\n",
|
||||
"virtual_display.start()"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "6E1inOK_5Jko"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Dependencies, Imports & Gym Environments"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "B2sWJAj8ti1y"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Let's install all the other dependencies we'll need."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "_HVFbCW5tnyw"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"!pip install gym[box2d]\n",
|
||||
"!pip install stable-baselines3[extra]\n",
|
||||
"!pip install pyglet\n",
|
||||
"!pip install ale-py==0.7.4 # To overcome an issue with Gym (https://github.com/DLR-RM/stable-baselines3/issues/875)\n",
|
||||
"!pip install optuna\n",
|
||||
"!pip install huggingface_sb3"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "liGH8sAg5dk9"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Next, let's perform all the necessary imports."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "WWcb8nUVt-A9"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"import gym\n",
|
||||
"\n",
|
||||
"from stable_baselines3.common.env_util import make_vec_env\n",
|
||||
"from stable_baselines3.common.monitor import Monitor\n",
|
||||
"from stable_baselines3 import PPO\n",
|
||||
"from stable_baselines3.common.evaluation import evaluate_policy\n",
|
||||
"from stable_baselines3.common.vec_env import DummyVecEnv\n",
|
||||
"\n",
|
||||
"import optuna\n",
|
||||
"from optuna.samplers import TPESampler\n",
|
||||
"\n",
|
||||
"from huggingface_hub import notebook_login\n",
|
||||
"from huggingface_sb3 import package_to_hub"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "DivjESMF5i7M"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Finally, let's create our Gym environments. The training environment is a vectorized environment:"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "uaXEISAluKU2"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"env = make_vec_env(\"LunarLander-v2\", n_envs=16)\n",
|
||||
"env"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "WTHPMs_s7YFc"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"And the evaluation environment is a separate environment:"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "NTtoXSFiOR6f"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"eval_env = Monitor(gym.make(\"LunarLander-v2\"))"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "ECDFf_6OOXqO"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"We are now ready to dive into hyperparameter tuning!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "sjyVRth8uSVm"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Hyperparameter Tuning"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "kz0QGAOnust1"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"First, let's define a `run_training()` function that trains a single model (using a particular combination of hyperparameter values), and returns a score. \n",
|
||||
"\n",
|
||||
"The score tells us how good the particular combination of hyperparameters is. (In our case, the score is `mean_reward - std_reward`, which is being used in the <a href=\"https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard\" target=\"_blank\">leaderboard</a>.) \n",
|
||||
"\n",
|
||||
"The function takes a very special argument - `params`, which is a dictionary. **The keys of this dictionary are the names of the hyperparameters we're tuning**, and **the values are sampled at each trial by Optuna's sampler** (from ranges that we'll specify soon).\n",
|
||||
"\n",
|
||||
"For example, in a particular trial, `params` might look like this:\n",
|
||||
"\n",
|
||||
"```\n",
|
||||
"{'n_epochs': 5, 'gamma': 0.9926, 'total_timesteps': 559_621}\n",
|
||||
"```\n",
|
||||
"\n",
|
||||
"And in another trial, `params` might look like this:\n",
|
||||
"\n",
|
||||
"```\n",
|
||||
"{'n_epochs': 3, 'gamma': 0.9974, 'total_timesteps': 1_728_482}\n",
|
||||
"```"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "02BT2bxVXEHj"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"def run_training(params, verbose=0, save_model=False):\n",
|
||||
" model = PPO(\n",
|
||||
" policy='MlpPolicy', \n",
|
||||
" env=env, \n",
|
||||
" n_steps=1024,\n",
|
||||
" batch_size=64, \n",
|
||||
" n_epochs=params['n_epochs'], # We're tuning this.\n",
|
||||
" gamma=params['gamma'], # We're tuning this.\n",
|
||||
" gae_lambda=0.98, \n",
|
||||
" ent_coef=0.01, \n",
|
||||
" verbose=verbose\n",
|
||||
" )\n",
|
||||
" model.learn(total_timesteps=params['total_timesteps']) # We're tuning this.\n",
|
||||
"\n",
|
||||
" mean_reward, std_reward = evaluate_policy(model, eval_env, n_eval_episodes=50, deterministic=True)\n",
|
||||
" score = mean_reward - std_reward\n",
|
||||
"\n",
|
||||
" if save_model:\n",
|
||||
" model.save(\"PPO-LunarLander-v2\")\n",
|
||||
"\n",
|
||||
" return model, score"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "kpDGvnBS6t57"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Next, we define another function - `objective()`. This function has a single parameter `trial`, which is an object of type `optuna.trial.Trial`. Using this `trial` object, we specify the ranges for the different hyperparameters we want to explore:\n",
|
||||
"\n",
|
||||
"- For `n_epochs`: We want to explore integer values between `3` and `5`.\n",
|
||||
"- For `gamma`: We want to explore floating point values between `0.9900` and `0.9999` (drawn from a uniform distribution).\n",
|
||||
"- For `total_timesteps`: We want to explore integer values between `500_000` and `2_000_000`.\n",
|
||||
"\n",
|
||||
"**Note:** If you have more time available, then you can tune other hyperparameters too. Moreover, you can explore wider ranges for each hyperparameter.\n",
|
||||
"\n",
|
||||
"The `trial.suggest_int()` and `trial.suggest_uniform()` methods are used by Optuna to suggest hyperparameter values in the ranges specified. The suggested combination of values are then used to train a model and return the score."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "dORGHcVYdSKp"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"def objective(trial):\n",
|
||||
" params = {\n",
|
||||
" \"n_epochs\": trial.suggest_int(\"n_epochs\", 3, 5), \n",
|
||||
" \"gamma\": trial.suggest_uniform(\"gamma\", 0.9900, 0.9999), \n",
|
||||
" \"total_timesteps\": trial.suggest_int(\"total_timesteps\", 500_000, 2_000_000)\n",
|
||||
" }\n",
|
||||
" model, score = run_training(params)\n",
|
||||
" return score"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "Wapg9hTI-AGz"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Finally, we use Optuna's `create_study()` function to create a study, passing in:\n",
|
||||
"\n",
|
||||
"- `sampler=TPESampler()`: This specifies that we want to employ a Bayesian optimization algorithm called Tree-structured Parzen Estimator. Other options are `GridSampler()`, `RandomSampler()`, etc. (The full list can be found <a href=\"https://optuna.readthedocs.io/en/stable/reference/samplers.html\" target=\"_blank\">here</a>.)\n",
|
||||
"- `study_name=\"PPO-LunarLander-v2\"`: This is a name we give to the study (optional).\n",
|
||||
"- `direction=\"maximize\"`: This is to specify that our objective is to maximize (not minimize) the score.\n",
|
||||
"\n",
|
||||
"Once our study is created, we call the `optimize()` method on it, specifying that we want to conduct `10` trials.\n",
|
||||
"\n",
|
||||
"**Note:** If you have more time available, then you can conduct more than `10` trials.\n",
|
||||
"\n",
|
||||
"**Warning:** The below code cell will take quite a bit of time to run!"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "a2gToNx7gPEG"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"study = optuna.create_study(sampler=TPESampler(), study_name=\"PPO-LunarLander-v2\", direction=\"maximize\")\n",
|
||||
"study.optimize(objective, n_trials=10)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "0v9G57g4-gl_"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Now that all the `10` trials have concluded, let's print out the score and hyperparameters of the best trial."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "9qRTUBAExSLt"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"print(\"Best trial score:\", study.best_trial.values)\n",
|
||||
"print(\"Best trial hyperparameters:\", study.best_trial.params)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "N-JFso9Lvurh"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Recreating & Saving The Best Model"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "qiSBZmZDux4q"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"Let's recreate the best model and save it."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "SuZ4OSayyq36"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"model, score = run_training(study.best_trial.params, verbose=1, save_model=True)"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "8JVUHgljIW1E"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Pushing to Hugging Face Hub"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "0eja4YaFu5Vb"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"To be able to share your model with the community, there are three more steps to follow:\n",
|
||||
"\n",
|
||||
"1. (If not done already) create a Hugging Face account -> https://huggingface.co/join\n",
|
||||
"\n",
|
||||
"2. Sign in and then, get your authentication token from the Hugging Face website.\n",
|
||||
"\n",
|
||||
"- Create a new token (https://huggingface.co/settings/tokens) **with write role**.\n",
|
||||
"- Copy the token.\n",
|
||||
"- Run the cell below and paste the token."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "qDjEim2izuFi"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"notebook_login()\n",
|
||||
"!git config --global credential.helper store"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "msFVH2qhzwpE"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"If you aren't using Google Colab or Jupyter Notebook, you need to use this command instead: `huggingface-cli login`\n",
|
||||
"\n",
|
||||
"3. We're now ready to push our trained agent to the Hub using the `package_to_hub()` function.\n",
|
||||
"\n",
|
||||
"Let's fill in the arguments of the `package_to_hub` function:\n",
|
||||
"\n",
|
||||
"- `model`: our trained model\n",
|
||||
"\n",
|
||||
"- `model_name`: the name of the trained model that we defined in `model.save()`\n",
|
||||
"\n",
|
||||
"- `model_architecture`: the model architecture we used (in our case `\"PPO\"`)\n",
|
||||
"\n",
|
||||
"- `env_id`: the name of the environment (in our case `\"LunarLander-v2\"`)\n",
|
||||
"\n",
|
||||
"- `eval_env`: the evaluation environment\n",
|
||||
"\n",
|
||||
"- `repo_id`: the name of the Hugging Face Hub repository that will be created/updated `(repo_id=\"{username}/{repo_name}\")` (**Note:** A good `repo_id` is `\"{username}/{model_architecture}-{env_id}\"`.)\n",
|
||||
"\n",
|
||||
"- `commit_message`: the commit message"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "lD4ACH160L_5"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"model_name = \"PPO-LunarLander-v2\"\n",
|
||||
"model_architecture = \"PPO\"\n",
|
||||
"env_id = \"LunarLander-v2\"\n",
|
||||
"eval_env = DummyVecEnv([lambda: gym.make(env_id)])\n",
|
||||
"repo_id = \"Sadhaklal/PPO-LunarLander-v2\"\n",
|
||||
"commit_message = \"Upload best PPO LunarLander-v2 agent (tuned with Optuna).\""
|
||||
],
|
||||
"metadata": {
|
||||
"id": "8JkhrjAt0O6a"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"The following function call will evaluate the agent, record a replay, generate a model card, and push your agent to the Hub."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "3HIT-M2C1l4E"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
"package_to_hub(\n",
|
||||
" model=model, \n",
|
||||
" model_name=model_name, \n",
|
||||
" model_architecture=model_architecture, \n",
|
||||
" env_id=env_id, \n",
|
||||
" eval_env=eval_env, \n",
|
||||
" repo_id=repo_id, \n",
|
||||
" commit_message=commit_message\n",
|
||||
")"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "1D0wQ_PU1mTN"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"That's it! You now know how to perform hyperparameter tuning of Stable-Baselines3 models using Optuna.\n",
|
||||
"\n",
|
||||
"To get even better results, try tuning the other hyperparameters of your model."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "7jLc9JDY11EW"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"## Final Tips"
|
||||
],
|
||||
"metadata": {
|
||||
"id": "Fa4TtHLAtq7-"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"source": [
|
||||
"1. Read the <a href=\"https://optuna.readthedocs.io/en/stable/index.html\" target=\"_blank\">Optuna documentation</a> to get more familiar with the library and its features.\n",
|
||||
"2. You may have noticed that hyperparameter tuning is a time consuming process. However, it can be sped up significantly using parallelization. Check out <a href=\"https://optuna.readthedocs.io/en/stable/tutorial/10_key_features/004_distributed.html\" target=\"_blank\">this guide</a> on how to do so."
|
||||
],
|
||||
"metadata": {
|
||||
"id": "tEgxhSjf4loa"
|
||||
}
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"source": [
|
||||
""
|
||||
],
|
||||
"metadata": {
|
||||
"id": "C7CJ7x7n4HuA"
|
||||
},
|
||||
"execution_count": null,
|
||||
"outputs": []
|
||||
}
|
||||
]
|
||||
}
|
||||
101
unit2/README.md
@@ -1,101 +0,0 @@
|
||||
# DEPRECIATED UNIT, THE NEW UNIT 2 IS HERE: https://huggingface.co/deep-rl-course/unit2/introduction
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unit2/introduction"
|
||||
|
||||
|
||||
# Unit 2: Introduction to Q-Learning
|
||||
|
||||
In this Unit, we're going to dive deeper into one of the Reinforcement Learning methods: value-based methods and **study our first RL algorithm: Q-Learning**.
|
||||
|
||||
We'll also implement our **first RL agent from scratch**: a Q-Learning agent and will train it in two environments:
|
||||
|
||||
- [Frozen-Lake-v1 ⛄ (non-slippery version)](https://www.gymlibrary.dev/environments/toy_text/frozen_lake/): where our agent will need to go from the starting state (S) to the goal state (G) by walking only on frozen tiles (F) and avoiding holes (H).
|
||||
- [An autonomous taxi 🚕](https://www.gymlibrary.dev/environments/toy_text/taxi/?highlight=taxi) will need to learn to navigate a city to transport its passengers from point A to point B.
|
||||
|
||||
<img src="assets/img/envs.gif" alt="unit 2 environments"/>
|
||||
|
||||
You'll then be able to **compare your agent’s results with other classmates thanks to a leaderboard** 🔥.
|
||||
|
||||
This Unit is divided into 2 parts:
|
||||
- [Part 1](https://huggingface.co/blog/deep-rl-q-part1)
|
||||
- [Part 2](https://huggingface.co/blog/deep-rl-q-part2)
|
||||
|
||||
<img src="assets/img/two_parts.jpg" alt="Two parts"/>
|
||||
|
||||
This course is **self-paced**, you can start whenever you want.
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- **2-3 hours** for the theory
|
||||
- **1 hour** for the hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣ 📝 If it's not already done, sign up to our Discord Server. This is the place where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Are you new to Discord? Check our **discord 101 to get the best practices** 👉 https://github.com/huggingface/deep-rl-class/blob/main/DISCORD.Md
|
||||
|
||||
2️⃣ 👋 **Introduce yourself on Discord in #introduce-yourself Discord channel 🤗 and check on the left the Reinforcement Learning section.**
|
||||
|
||||
- In #rl-announcements we give the last information about the course.
|
||||
- #discussions is a place to exchange.
|
||||
- #unity-ml-agents is to exchange about everything related to this library.
|
||||
- #study-groups, to create study groups with your classmates.
|
||||
|
||||
<img src="assets/img/discord_channels.jpg" alt="Discord Channels"/>
|
||||
|
||||
3️⃣ 📖 **Read An [Introduction to Q-Learning Part 1](https://huggingface.co/blog/deep-rl-q-part1)**.
|
||||
|
||||
4️⃣ 📝 Take a piece of paper and **check your knowledge with this series of questions** ❔ 👉 https://github.com/huggingface/deep-rl-class/blob/main/unit2/quiz1.md
|
||||
|
||||
5️⃣ 📖 **Read An [Introduction to Q-Learning Part 2](https://huggingface.co/blog/deep-rl-q-part2)**.
|
||||
|
||||
6️⃣ 📝 Take a piece of paper and **check your knowledge with this series of questions** ❔ 👉 https://github.com/huggingface/deep-rl-class/blob/main/unit2/quiz2.md
|
||||
|
||||
7️⃣ 👩💻 Then dive on the hands-on, where **you’ll implement our first RL agent from scratch**, a Q-Learning agent, and will train it in two environments:
|
||||
1. Frozen Lake v1 ❄️: where our agent will need to **go from the starting state (S) to the goal state (G)** by walking only on frozen tiles (F) and avoiding holes (H).
|
||||
2. An autonomous taxi 🚕: where the agent will need **to learn to navigate** a city to **transport its passengers from point A to point B.**
|
||||
|
||||
Thanks to a leaderboard, **you'll be able to compare your results with other classmates** and exchange the best practices to improve your agent's scores Who will win the challenge for Unit 2 🏆?
|
||||
|
||||
👩💻 The hands-on 👉 [](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit2/unit2.ipynb)
|
||||
|
||||
🏆 The leaderboard 👉 https://huggingface.co/spaces/huggingface-projects/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
You can work directly **with the colab notebook, which allows you not to have to install everything on your machine (and it’s free)**.
|
||||
|
||||
8️⃣ The best way to learn **is to try things on your own**. That’s why we have a challenges section in the colab where we give you some ideas on how you can go further: using another environment, using another model etc.
|
||||
|
||||
## Additional readings 📚
|
||||
- [Reinforcement Learning: An Introduction, Richard Sutton and Andrew G. Barto Chapter 5, 6 and 7](http://incompleteideas.net/book/RLbook2020.pdf)
|
||||
- [Foundations of Deep RL Series, L2 Deep Q-Learning by Pieter Abbeel](https://youtu.be/Psrhxy88zww)
|
||||
- To dive deeper on Monte Carlo and Temporal Difference Learning:
|
||||
- [Why do temporal difference (TD) methods have lower variance than Monte Carlo methods?](https://stats.stackexchange.com/questions/355820/why-do-temporal-difference-td-methods-have-lower-variance-than-monte-carlo-met)
|
||||
- [When are Monte Carlo methods preferred over temporal difference ones?](https://stats.stackexchange.com/questions/336974/when-are-monte-carlo-methods-preferred-over-temporal-difference-ones)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
## Keep learning, stay awesome 🤗,
|
||||

|
Before Width: | Height: | Size: 144 KiB |

|
Before Width: | Height: | Size: 220 KiB |

|
Before Width: | Height: | Size: 108 KiB |

|
Before Width: | Height: | Size: 324 KiB |

|
Before Width: | Height: | Size: 217 KiB |

|
Before Width: | Height: | Size: 20 KiB |

|
Before Width: | Height: | Size: 359 KiB |

|
Before Width: | Height: | Size: 131 KiB |

|
Before Width: | Height: | Size: 270 KiB |

|
Before Width: | Height: | Size: 65 KiB |

|
Before Width: | Height: | Size: 93 KiB |

|
Before Width: | Height: | Size: 244 KiB |

|
Before Width: | Height: | Size: 119 KiB |

|
Before Width: | Height: | Size: 445 KiB |

|
Before Width: | Height: | Size: 1.2 MiB |
@@ -1,98 +0,0 @@
|
||||
# Knowledge Check ✔️
|
||||
|
||||
The best way to learn and [avoid the illusion of competence](https://fr.coursera.org/lecture/learning-how-to-learn/illusions-of-competence-BuFzf) **is to test yourself.** This will help you to find **where you need to reinforce your knowledge**.
|
||||
|
||||
📝 Take a piece of paper and try to answer by writing, **then check the solutions**.
|
||||
|
||||
### Q1: What are the two main approaches to find optimal policy?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
The two main approaches are:
|
||||
- *Policy-based methods*: **Train the policy directly** to learn which action to take given a state.
|
||||
- *Value-based methods* : Train a value function to **learn which state is more valuable and use this value function to take the action that leads to it**.
|
||||
|
||||
<img src="assets/img/two-approaches.jpg" alt="Two approaches of Deep RL"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part1#what-is-rl-a-short-recap
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
### Q2: What is the Bellman Equation?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
**The Bellman equation is a recursive equation** that works like this: instead of starting for each state from the beginning and calculating the return, we can consider the value of any state as:
|
||||
|
||||
$R_{t+1} + ( gamma * V(S_{t+1}))$
|
||||
|
||||
The immediate reward + the discounted value of the state that follows
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part1#the-bellman-equation-simplify-our-value-estimation
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
### Q3: Define each part of the Bellman Equation
|
||||
|
||||
<img src="assets/img/bellman4-quiz.jpg" alt="Bellman equation quiz"/>
|
||||
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
<img src="assets/img/bellman4.jpg" alt="Bellman equation solution"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part1#the-bellman-equation-simplify-our-value-estimation
|
||||
|
||||
</details>
|
||||
|
||||
### Q4: What is the difference between Monte Carlo and Temporal Difference learning methods?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
There are two types of methods to learn a policy or a value function:
|
||||
- With the *Monte Carlo method*, we update the value function **from a complete episode**, and so we use the actual accurate discounted return of this episode.
|
||||
- With the *TD Learning method*, we update the value function **from a step, so we replace Gt that we don't have with an estimated return called TD target**.
|
||||
|
||||
<img src="assets/img/summary-learning-mtds.jpg" alt="summary-learning-mtds"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part1#monte-carlo-vs-temporal-difference-learning
|
||||
|
||||
</details>
|
||||
|
||||
### Q5: Define each part of Temporal Difference learning formula
|
||||
|
||||
<img src="assets/img/td-ex.jpg" alt="TD Learning exercise"/>
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
<img src="assets/img/TD-1.jpg" alt="TD Exercise"/>
|
||||
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part1#temporal-difference-learning-learning-at-each-step
|
||||
</details>
|
||||
|
||||
|
||||
### Q6: Define each part of Monte Carlo learning formula
|
||||
|
||||
<img src="assets/img/mc-ex.jpg" alt="MC Learning exercise"/>
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
<img src="assets/img/monte-carlo-approach.jpg" alt="MC Exercise"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part1#monte-carlo-learning-at-the-end-of-the-episode
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
Congrats on **finishing this Quiz** 🥳, if you missed some elements, take time to [read the chapter again](https://huggingface.co/blog/deep-rl-q-part1) to reinforce (😏) your knowledge.
|
||||
|
||||
**Keep Learning, Stay Awesome**
|
||||
@@ -1,81 +0,0 @@
|
||||
# Knowledge Check ✔️
|
||||
|
||||
The best way to learn and [avoid the illusion of competence](https://fr.coursera.org/lecture/learning-how-to-learn/illusions-of-competence-BuFzf) **is to test yourself.** This will help you to find **where you need to reinforce your knowledge**.
|
||||
|
||||
📝 Take a piece of paper and try to answer by writing, **then check the solutions**.
|
||||
|
||||
### Q1: What is Q-Learning?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
Q-Learning is **the algorithm we use to train our Q-Function**, an action-value function that determines the value of being at a particular state and taking a specific action at that state.
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part2#what-is-q-learning
|
||||
</details>
|
||||
|
||||
### Q2: What is a Q-Table?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
Q-table is the "internal memory" of our agent where each cell corresponds to a state-action value pair value. Think of this Q-table as the memory or cheat sheet of our Q-function.
|
||||
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part2#what-is-q-learning
|
||||
</details>
|
||||
|
||||
### Q3: Why if we have an optimal Q-function Q* we have an optimal policy?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
Because if we have an optimal Q-function, we have an optimal policy since we know for each state what is the best action to take.
|
||||
|
||||
<img src="https://huggingface.co/blog/assets/73_deep_rl_q_part2/link-value-policy.jpg" alt="link value policy"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part2#what-is-q-learning
|
||||
</details>
|
||||
|
||||
### Q4: Can you explain what is Epsilon-Greedy Strategy?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
Epsilon Greedy Strategy is a **policy that handles the exploration/exploitation trade-off**.
|
||||
|
||||
The idea is that we define epsilon ɛ = 1.0:
|
||||
|
||||
- With *probability 1 — ɛ* : we do exploitation (aka our agent selects the action with the highest state-action pair value).
|
||||
- With *probability ɛ* : we do exploration (trying random action).
|
||||
|
||||
<img src="https://huggingface.co/blog/assets/73_deep_rl_q_part2/Q-learning-4.jpg" alt="Epsilon Greedy"/>
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part2#the-q-learning-algorithm
|
||||
|
||||
</details>
|
||||
|
||||
### Q5: How do we update the Q value of a state, action pair?
|
||||
<img src="assets/img/q-update-ex.jpg.jpg" alt="Q Update exercise"/>
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
<img src="assets/img/q-update-solution.jpg.jpg" alt="Q Update exercise"/>
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part2#the-q-learning-algorithm
|
||||
</details>
|
||||
|
||||
### Q6: What's the difference between on-policy and off-policy
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
<img src="https://huggingface.co/blog/assets/73_deep_rl_q_part2/off-on-4.jpg" alt="On/off policy"/>
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-q-part2#off-policy-vs-on-policy
|
||||
</details>
|
||||
|
||||
|
||||
---
|
||||
|
||||
Congrats on **finishing this Quiz** 🥳, if you missed some elements, take time to [read the chapter again](https://huggingface.co/blog/deep-rl-q-part2) to reinforce (😏) your knowledge.
|
||||
|
||||
**Keep Learning, Stay Awesome**
|
||||
|
||||
|
||||
@@ -1,14 +0,0 @@
|
||||
# Unit 2 Bonus 🎁
|
||||
If you want to go deeper into Stable Baselines3 before our next week unit about Deep Q-Learning you can **check these cool environments 🚀**:
|
||||
|
||||
<img src="../assets/img/bonus-unit2.jpg" alt="Illustration unit 2 bonus"/>
|
||||
|
||||
- [Minigrid environment](https://github.com/maximecb/gym-minigrid): puzzle environments where your agent needs to find the way out using keys 🔐 and doors 🚪 : https://github.com/maximecb/gym-minigrid
|
||||
|
||||
- [Procgen Benchmark](https://stable-baselines3.readthedocs.io/en/master/guide/examples.html#sb3-and-procgenenv): 16 simple-to-use procedurally-generated gym environments (platform, shooters etc). You have an example with Stable-Baselines3 here: https://stable-baselines3.readthedocs.io/en/master/guide/examples.html#sb3-and-procgenenv
|
||||
|
||||
- [VizDoom: a Doom like environment 🔥](https://github.com/mwydmuch/ViZDoom) Nicholas Renotte made a very good tutorial on how to train an agent playing it using Stable Baselines-3: https://youtu.be/eBCU-tqLGfQ
|
||||
|
||||
Have fun 🥳
|
||||
|
||||
### Keep Learning, Stay awesome
|
||||
1795
unit2/unit2.ipynb
@@ -1,70 +0,0 @@
|
||||
# DEPRECIATED THE NEW VERSION OF THIS UNIT IS HERE: https://huggingface.co/deep-rl-course/unit3/introduction
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unit3/introduction
|
||||
|
||||
|
||||
# Unit 3: Deep Q-Learning with Atari Games 👾
|
||||
|
||||
In this Unit, **we'll study our first Deep Reinforcement Learning agent**: Deep Q-Learning.
|
||||
|
||||
And **we'll train it to play Space Invaders and other Atari environments using [RL-Zoo](https://github.com/DLR-RM/rl-baselines3-zoo)**, a training framework for RL using Stable-Baselines that provides scripts for training, evaluating agents, tuning hyperparameters, plotting results, and recording videos.
|
||||
|
||||
<img src="assets/img/atari-envs.gif" alt="unit 3 environments"/>
|
||||
|
||||
You'll then be able to **compare your agent’s results with other classmates thanks to a leaderboard** 🔥 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
This course is **self-paced**, you can start whenever you want.
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- 1-2 hours for the theory
|
||||
- 1 hour for the hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣ 📖 **Read [Deep Q-Learning with Atari chapter](https://huggingface.co/blog/deep-rl-dqn)**.
|
||||
|
||||
2️⃣ 📝 Take a piece of paper and check your knowledge with this series of questions ❔ 👉 https://github.com/huggingface/deep-rl-class/blob/main/unit3/quiz.md
|
||||
|
||||
3️⃣ 👩💻 Then dive on the hands-on, where **you'll train a Deep Q-Learning agent** playing Space Invaders using [RL Baselines3 Zoo](https://github.com/DLR-RM/rl-baselines3-zoo), a training framework based on [Stable-Baselines3](https://stable-baselines3.readthedocs.io/en/master/) that provides scripts for training, evaluating agents, tuning hyperparameters, plotting results and recording videos.
|
||||
|
||||
Thanks to a leaderboard, **you'll be able to compare your results with other classmates** and exchange the best practices to improve your agent's scores Who will win the challenge for Unit 2 🏆?
|
||||
|
||||
The hands-on 👉 [](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit3/unit3.ipynb)
|
||||
|
||||
The leaderboard 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
You can work directly **with the colab notebook, which allows you not to have to install everything on your machine (and it’s free)**.
|
||||
|
||||
4️⃣ The best way to learn **is to try things on your own**. That’s why we have a challenges section in the colab where we give you some ideas on how you can go further: using another environment, using another model etc.
|
||||
|
||||
## Additional readings 📚
|
||||
- [Foundations of Deep RL Series, L2 Deep Q-Learning by Pieter Abbeel](https://youtu.be/Psrhxy88zww)
|
||||
- [Playing Atari with Deep Reinforcement Learning](https://arxiv.org/abs/1312.5602)
|
||||
- [Double Deep Q-Learning](https://papers.nips.cc/paper/2010/hash/091d584fced301b442654dd8c23b3fc9-Abstract.html)
|
||||
- [Prioritized Experience Replay](https://arxiv.org/abs/1511.05952)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
### Keep learning, stay awesome,
|
||||

|
Before Width: | Height: | Size: 2.6 MiB |
@@ -1 +0,0 @@
|
||||
|
||||
@@ -1,16 +0,0 @@
|
||||
# Automatic Hyperparameter Tuning with Optuna
|
||||
|
||||
One of the most critical task in Deep Reinforcement Learning is to **find a good set of training hyperparameters**.
|
||||
|
||||
<img src="https://raw.githubusercontent.com/optuna/optuna/master/docs/image/optuna-logo.png" alt="Optuna"/>
|
||||
|
||||
Optuna is a library that **helps you to automate the search**. In this Unit, we'll study a little bit of the theory behind automatic hyperparameter tuning. We'll then try to optimize the parameters manually and then see how to automate the search using Optuna.
|
||||
|
||||
The content below comes from [Antonin's Raffin ICRA 2022 presentations](https://twitter.com/araffin2), he's one of the founders of Stable-Baselines and RL-Baselines3-Zoo.
|
||||
|
||||
## The learning steps 📚
|
||||
1️⃣ 📹 First, let study what's [Automatic Hyperparameter Tuning](https://www.youtube.com/watch?v=AidFTOdGNFQ). Don't forget to 👍 the video 🤗.
|
||||
|
||||
2️⃣👩💻 Then let's dive on the [hands-on, where we'll then try to optimize the parameters manually and then see how to automate the search using Optuna](https://youtu.be/ihP7E76KGOI).
|
||||
|
||||
3️⃣ Now that you've learned to use Optuna, why not going back to our **Deep Q-Learning hands-on and implement Optuna to find the best training hyperparameters** 👉 [](https://colab.research.google.com/github/araffin/tools-for-robotic-rl-icra2022/blob/main/notebooks/optuna_lab.ipynb)
|
||||
@@ -1,93 +0,0 @@
|
||||
# Knowledge Check ✔️
|
||||
|
||||
The best way to learn and [avoid the illusion of competence](https://fr.coursera.org/lecture/learning-how-to-learn/illusions-of-competence-BuFzf) **is to test yourself.** This will help you to find **where you need to reinforce your knowledge**.
|
||||
|
||||
📝 Take a piece of paper and try to answer by writing, **then check the solutions**.
|
||||
|
||||
### Q1: What are tabular methods?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
*Tabular methods* are a type of problems in which the state and actions spaces are small enough to approximate value functions to be **represented as arrays and tables**. For instance, **Q-Learning is a tabular method** since we use a table to represent the state,action value pairs.
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-dqn#from-q-learning-to-deep-q-learning
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
### Q2: Why we can't use a classical Q-Learning to solve an Atari Game?
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
Atari environments have an observation space with a shape of (210, 160, 3), containing values ranging from 0 to 255, so that gives us 256^(210x160x3) = 256^100800 (**for comparison, we have approximately 10^80 atoms in the observable universe**).
|
||||
|
||||
Therefore, the state space is gigantic; hence creating and updating a Q-table for that environment **would not be efficient**. In this case, the best idea is to approximate the Q-values instead of a Q-table using a parametrized Q-function $Q_{\theta}(s,a)$.
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-dqn#from-q-learning-to-deep-q-learning
|
||||
</details>
|
||||
|
||||
### Q3: Why do we stack four frames together when we use frames as input in Deep Q-Learning?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
We stack frames together because it helps us **handle the problem of temporal limitation**. Since one frame is not enough to capture temporal information.
|
||||
For instance, in pong, our agent **will be unable to know the ball direction if it gets only one frame**.
|
||||
|
||||
<img src="https://huggingface.co/blog/assets/78_deep_rl_dqn/temporal-limitation.jpg" alt="Temporal limitation"/>
|
||||
<img src="https://huggingface.co/blog/assets/78_deep_rl_dqn/temporal-limitation-2.jpg" alt="Temporal limitation"/>
|
||||
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-dqn#preprocessing-the-input-and-temporal-limitation
|
||||
</details>
|
||||
|
||||
### Q4: What are the two phases of Deep Q-Learning?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
The Deep Q-Learning training algorithm has two phases:
|
||||
- *Sampling* : we perform actions and **store the observed experiences tuples in a replay memory**.
|
||||
- *Training* : Select the small batch of tuple randomly and **learn from it using a gradient descent update step**.
|
||||
|
||||
📖 If you don't remember, check 👉 [https://huggingface.co/blog/deep-rl-dqn#preprocessing-the-input-and-temporal-limitation](https://huggingface.co/blog/deep-rl-dqn#the-deep-q-learning-algorithm)
|
||||
</details>
|
||||
|
||||
### Q5: Why do we create a replay memory in Deep Q-Learning?
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
**1. Make more efficient use of the experiences during the training**
|
||||
|
||||
Usually, in online reinforcement learning, we interact in the environment, get experiences (state, action, reward, and next state), learn from them (update the neural network) and discard them.
|
||||
But with experience replay, **we create a replay buffer that saves experience samples that we can reuse during the training**.
|
||||
|
||||
**2. Avoid forgetting previous experiences and reduce the correlation between experiences**
|
||||
|
||||
The problem we get if we give sequential samples of experiences to our neural network is that it **tends to forget the previous experiences as it overwrites new experiences**. For instance, if we are in the first level and then the second, which is different, our agent can forget how to behave and play in the first level.
|
||||
|
||||
📖 If you don't remember, check 👉 https://huggingface.co/blog/deep-rl-dqn#experience-replay-to-make-more-efficient-use-of-experiences
|
||||
|
||||
</details>
|
||||
|
||||
### Q6: How do we use Double Deep Q-Learning?
|
||||
|
||||
|
||||
<details>
|
||||
<summary>Solution</summary>
|
||||
|
||||
When we compute the Q target, we use two networks to decouple the action selection from the target Q value generation. We:
|
||||
|
||||
- Use our *DQN network* to **select the best action to take for the next state** (the action with the highest Q value).
|
||||
|
||||
- Use our *Target network* to calculate **the target Q value of taking that action at the next state**.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
Congrats on **finishing this Quiz** 🥳, if you missed some elements, take time to [read the chapter again](https://huggingface.co/blog/deep-rl-dqn) to reinforce (😏) your knowledge.
|
||||
|
||||
**Keep Learning, Stay Awesome**
|
||||
@@ -1,57 +0,0 @@
|
||||
# DEPRECIATED THE NEW VERSION OF THIS UNIT IS HERE: https://huggingface.co/deep-rl-course/unit5/introduction
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unit5/introduction
|
||||
|
||||
|
||||
# Unit 4: An Introduction to Unity MLAgents with Hugging Face 🤗
|
||||

|
||||
|
||||
In this Unit, We’ll learn about [ML-Agents](https://huggingface.co/docs/hub/ml-agents) and use one of the pre-made environments: Pyramids. In this environment, we’ll train an agent that needs to press a button to spawn a pyramid, then navigate to the pyramid, knock it over, and move to the gold brick at the top.
|
||||
|
||||
To do that, **it will need to explore its environment, and we will use a technique called curiosity**.
|
||||
|
||||
Then, after training we’ll push the **trained agent to the Hugging Face Hub and you’ll be able to visualize it playing directly on your browser without having to use the Unity Editor. You’ll be also be able to visualize and download others trained agents from the community**.
|
||||
|
||||

|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- 2 hours for the theory and hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣📖 **Read An [An Introduction to Unity ML-Agents with Hugging Face 🤗](https://thomassimonini.medium.com/an-introduction-to-unity-ml-agents-with-hugging-face-efbac62c8c80)**.
|
||||
|
||||
2️⃣👩💻 In the meantime, **you can start the tutorial using Google Colab** 👉 [](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit4/unit4.ipynb)
|
||||
|
||||
You can work directly **with the colab notebook, which allows you not to have to install everything on your machine (and it’s free)**.
|
||||
|
||||
3️⃣ The best way to learn **is to try things on your own**. That’s why we have a challenges section in the colab where we **give you some ideas on how you can go further: using another environment etc**.
|
||||
|
||||
## Additional readings 📚
|
||||
- [MLAgents Documentation](https://github.com/Unity-Technologies/ml-agents/blob/main/docs/Readme.md)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
### Keep learning, stay awesome 🤗,
|
||||

|
Before Width: | Height: | Size: 1.5 MiB |
@@ -1 +0,0 @@
|
||||
|
||||
|
Before Width: | Height: | Size: 64 KiB |
@@ -1,74 +0,0 @@
|
||||
# DEPRECIATED THE NEW VERSION OF THIS UNIT IS HERE: https://huggingface.co/deep-rl-course/unit4/introduction
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unit4/introduction
|
||||
|
||||
|
||||
# Unit 5: Policy Gradient with PyTorch
|
||||
|
||||
In this Unit, **we'll study Policy Gradient Methods**.
|
||||
|
||||
And we'll **implement Reinforce (a policy gradient method) from scratch using PyTorch**. Before testing its robustness using CartPole-v1, PixelCopter, and Pong.
|
||||
|
||||
<img src="assets/img/envs.gif" alt="unit 5 environments"/>
|
||||
|
||||
You'll then be able to **compare your agent’s results with other classmates thanks to a leaderboard** 🔥 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
This course is **self-paced**, you can start whenever you want.
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- 1 hour for the theory
|
||||
- 1-2 hours for the hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣ 📖 **Read [Policy Gradient with PyTorch Chapter](https://huggingface.co/blog/deep-rl-pg)**.
|
||||
|
||||
2️⃣ 👩💻 Then dive on the hands-on where you'll **code your first Deep Reinforcement Learning algorithm from scratch: Reinforce**.
|
||||
|
||||
Reinforce is a *Policy-Based Method*: a Deep Reinforcement Learning algorithm that tries **to optimize the policy directly without using an action-value function**.
|
||||
More precisely, Reinforce is a *Policy-Gradient Method*, a subclass of *Policy-Based Methods* that aims **to optimize the policy directly by estimating the weights of the optimal policy using Gradient Ascent**.
|
||||
|
||||
To test its robustness, we're going to train it in 3 different simple environments:
|
||||
- Cartpole-v1
|
||||
- PongEnv
|
||||
- PixelcopterEnv
|
||||
|
||||
Thanks to a leaderboard, **you'll be able to compare your results with other classmates** and exchange the best practices to improve your agent's scores Who will win the challenge for Unit 5 🏆?
|
||||
|
||||
The hands-on 👉 [](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit5/unit5.ipynb)
|
||||
|
||||
The leaderboard 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
You can work directly **with the colab notebook, which allows you not to have to install everything on your machine (and it’s free)**.
|
||||
|
||||
|
||||
## Additional readings 📚
|
||||
- [Foundations of Deep RL Series, L3 Policy Gradients and Advantage Estimation by Pieter Abbeel](https://youtu.be/AKbX1Zvo7r8)
|
||||
- [Policy Gradient Algorithms](https://lilianweng.github.io/posts/2018-04-08-policy-gradient/)
|
||||
- [An Intuitive Explanation of Policy Gradient](https://towardsdatascience.com/an-intuitive-explanation-of-policy-gradient-part-1-reinforce-aa4392cbfd3c)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
### Keep learning, stay awesome,
|
||||

|
Before Width: | Height: | Size: 1.8 MiB |
1647
unit5/unit5.ipynb
@@ -1,61 +0,0 @@
|
||||
# Towards better explorations methods with Curiosity
|
||||
|
||||
In this Unit, we'll study in theory **Curiosity in Deep Reinforcement Learning**, a technique used to push our agent to better explore its environment and solve two majors flaws in Deep Reinforcement Learning:
|
||||
|
||||
1️⃣ **Sparse rewards environments: environments were most rewards do not contain information, and hence are set to zero.**
|
||||
|
||||
For instance, in [Vizdoom environment](https://github.com/mwydmuch/ViZDoom) “DoomMyWayHome,” your agent is only rewarded if it finds the vest. However, the vest is
|
||||
**far away from your starting point, so most of your rewards will be zero**. Therefore, if our agent does not receive useful feedback (dense rewards), it will take much longer to learn an optimal policy and it **can spend time turning around without finding the goal**.
|
||||
|
||||
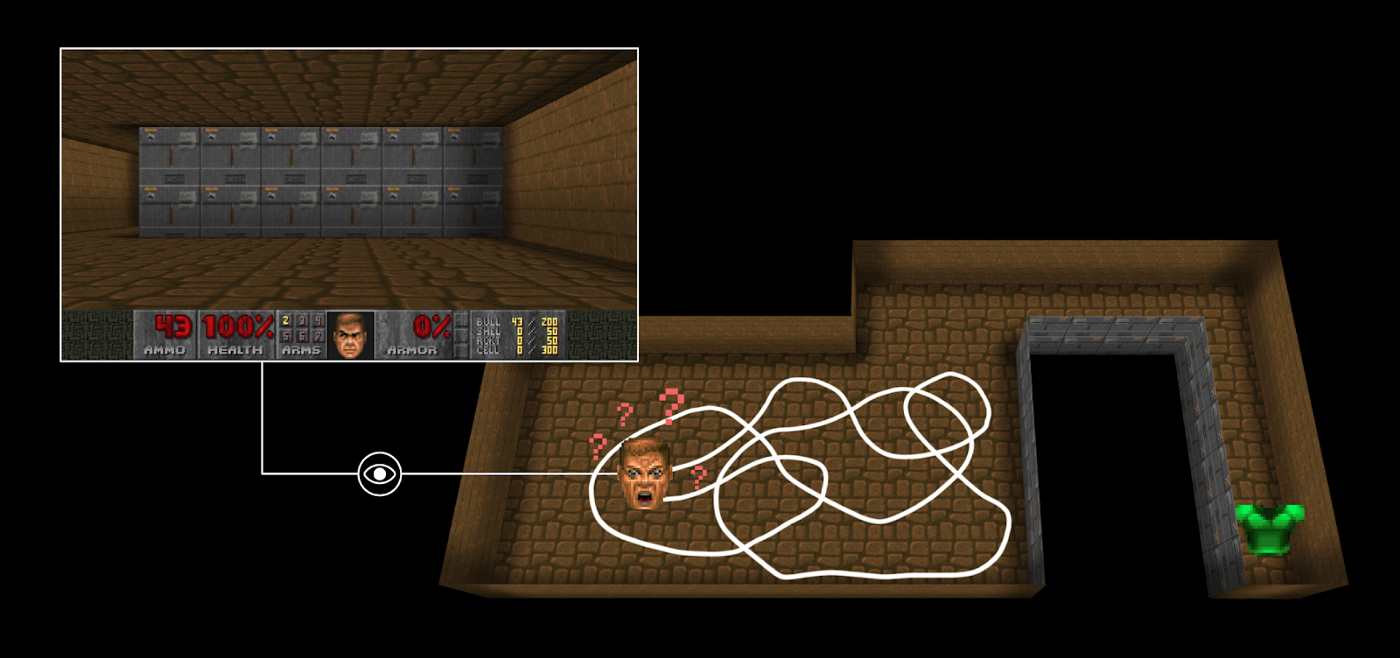
|
||||
|
||||
2️⃣ **The extrinsic reward function (environment reward function) is handmade, that is in each environment, a human has to implement a reward function. But how we can scale that in big and complex environments?**
|
||||
|
||||
Therefore, a solution to these problems is to develop a reward function that is intrinsic to the agent, i.e., generated by the agent itself. The agent will act as a self-learner since it will be the student, but also its own feedback master.
|
||||
|
||||
This intrinsic reward mechanism is known as curiosity because this reward push to explore states that are novel/unfamiliar. **In order to achieve that, our agent will receive a high reward when exploring new trajectories.**
|
||||
|
||||
We'll see two techniques to create this curiosity, both of them are based on a Paper.
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- One hour for the first paper study
|
||||
- One hour for the second paper study
|
||||
|
||||
## Start this Unit 🚀
|
||||
1️⃣ 📖 Read [Curiosity-Driven Learning through Next State Prediction](https://medium.com/data-from-the-trenches/curiosity-driven-learning-through-next-state-prediction-f7f4e2f592fa)
|
||||
|
||||
2️⃣ In addition, you should read the paper 👉 https://pathak22.github.io/noreward-rl/
|
||||
|
||||
3️⃣ 📖 Read [Random Network Distillation: a new take on Curiosity-Driven Learning](https://medium.com/data-from-the-trenches/curiosity-driven-learning-through-random-network-distillation-488ffd8e5938)
|
||||
|
||||
4️⃣ In addition, you should read the paper 👉 https://arxiv.org/pdf/1808.04355.pdf
|
||||
|
||||
## Additional readings 📚
|
||||
- [Curiosity and Procrastination in Reinforcement Learning, Google Brain](https://ai.googleblog.com/2018/10/curiosity-and-procrastination-in.html)
|
||||
- [ML-Agents, Curiosity for Sparse-reward Environments](https://github.com/Unity-Technologies/ml-agents/blob/main/docs/ML-Agents-Overview.md#curiosity-for-sparse-reward-environments)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
### Keep learning, stay awesome,
|
||||
@@ -1,66 +0,0 @@
|
||||
# DEPRECIATED THE NEW VERSION OF THIS UNIT IS HERE: https://huggingface.co/deep-rl-course/unit6/introduction
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unit6/introduction
|
||||
|
||||
|
||||
# Unit 7: Advantage Actor Critic (A2C) using Robotics Simulations with PyBullet 🤖
|
||||
|
||||
One of the major industries that use Reinforcement Learning is robotics. Unfortunately, **having access to robot equipment is very expensive**. Fortunately, some simulations exist to train Robots:
|
||||
1. PyBullet
|
||||
2. MuJoco
|
||||
3. Unity Simulations
|
||||
|
||||
We're going to learn about Advantage Actor Critic (A2C) and how to use PyBullet. And train a spider agent to walk.
|
||||
|
||||
🏆 You'll then be able to **compare your agent’s results with other classmates thanks to a leaderboard** 🔥 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||

|
||||
|
||||
Let's get started 🥳
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- 1 hour for the theory.
|
||||
- 1 hour for the hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣ 📖 [Read Advantage Actor Critic Chapter](https://huggingface.co/blog/deep-rl-a2c).
|
||||
|
||||
2️⃣ 👩💻 Then dive on the hands-on where you'll train two robots to walk.
|
||||
|
||||
The hands-on 👉 [](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit7/unit7.ipynb)
|
||||
|
||||
Thanks to a leaderboard, you'll be able to compare your results with other classmates and exchange the best practices to improve your agent's scores Who will win the challenge for Unit 7 🏆?
|
||||
|
||||
The leaderboard 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
## Additional readings 📚
|
||||
- [Making Sense of the Bias / Variance Trade-off in (Deep) Reinforcement Learning](https://blog.mlreview.com/making-sense-of-the-bias-variance-trade-off-in-deep-reinforcement-learning-79cf1e83d565)
|
||||
- [Bias-variance Tradeoff in Reinforcement Learning](https://www.endtoend.ai/blog/bias-variance-tradeoff-in-reinforcement-learning/)
|
||||
- [Foundations of Deep RL Series, L3 Policy Gradients and Advantage Estimation by Pieter Abbeel](https://youtu.be/AKbX1Zvo7r8)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
### Keep learning, stay awesome 🤗
|
||||

|
Before Width: | Height: | Size: 4.1 MiB |
@@ -1 +0,0 @@
|
||||
|
||||
@@ -1,68 +0,0 @@
|
||||
# DEPRECIATED THE NEW VERSION OF THIS UNIT IS HERE: https://huggingface.co/deep-rl-course/unit8/introduction
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unit8/introduction
|
||||
|
||||
|
||||
# Unit 8: Proximal Policy Optimization (PPO) with PyTorch
|
||||
|
||||
Today we'll learn about Proximal Policy Optimization (PPO), an architecture that improves our agent's training stability by avoiding too large policy updates. To do that, we use a ratio that will indicates the difference between our current and old policy and clip this ratio from a specific range $[1 - \epsilon, 1 + \epsilon]$. Doing this will ensure that our policy update will not be too large and that the training is more stable.
|
||||
|
||||
And then, after the theory, we'll code a PPO architecture from scratch using PyTorch and bulletproof our implementation with CartPole-v1 and LunarLander-v2.
|
||||
|
||||
🏆 You'll then be able to **compare your agent’s results with other classmates thanks to a leaderboard** 🔥 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
<img src="assets/img/LunarLander.gif" alt="LunarLander"/>
|
||||
|
||||
Let's get started 🥳
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- 1 hour for the theory.
|
||||
- 2 hours for the hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣ 📖 [Read Proximal Policy Optimization Chapter](https://huggingface.co/blog/deep-rl-ppo).
|
||||
|
||||
2️⃣ 👩💻 Then dive on the hands-on:
|
||||
|
||||
The hands-on 👉 [](https://colab.research.google.com/github/huggingface/deep-rl-class/blob/main/unit8/unit8.ipynb)
|
||||
|
||||
Thanks to a leaderboard, you'll be able to compare your results with other classmates and exchange the best practices to improve your agent's scores Who will win the challenge for Unit 8 🏆?
|
||||
|
||||
The leaderboard 👉 https://huggingface.co/spaces/chrisjay/Deep-Reinforcement-Learning-Leaderboard
|
||||
|
||||
## Additional readings 📚
|
||||
- [Towards Delivering a Coherent Self-Contained Explanation of Proximal Policy Optimization by Daniel Bick](https://fse.studenttheses.ub.rug.nl/25709/1/mAI_2021_BickD.pdf)
|
||||
- [What is the way to understand Proximal Policy Optimization Algorithm in RL?](https://stackoverflow.com/questions/46422845/what-is-the-way-to-understand-proximal-policy-optimization-algorithm-in-rl)
|
||||
- [Foundations of Deep RL Series, L4 TRPO and PPO by Pieter Abbeel](https://youtu.be/KjWF8VIMGiY)
|
||||
- [OpenAI PPO Blogpost](https://openai.com/blog/openai-baselines-ppo/)
|
||||
- [Spinning Up RL PPO](https://spinningup.openai.com/en/latest/algorithms/ppo.html)
|
||||
- [Paper Proximal Policy Optimization Algorithms](https://arxiv.org/abs/1707.06347)
|
||||
- [The 37 Implementation Details of Proximal Policy Optimization](https://ppo-details.cleanrl.dev//2021/11/05/ppo-implementation-details/)
|
||||
- [Importance Sampling Explained](https://youtu.be/C3p2wI4RAi8)
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
### Keep learning, stay awesome 🤗
|
||||
1329
unit8/unit8.ipynb
@@ -1,55 +0,0 @@
|
||||
# DEPRECIATED THE NEW VERSION OF THIS UNIT IS HERE: https://huggingface.co/deep-rl-course/unitbonus3/decision-transformers
|
||||
**Everything under is depreciated** 👇, the new version of the course is here: https://huggingface.co/deep-rl-course/unitbonus3/decision-transformers
|
||||
|
||||
|
||||
|
||||
# Unit 9: Decision Transformers and offline Reinforcement Learning 🤖
|
||||
|
||||

|
||||
|
||||
In this Unit, you'll learn what is Decision Transformer and Offline Reinforcement Learning. And then, you’ll train your first Offline Decision Transformer model from scratch to make a half-cheetah run.
|
||||
|
||||
This course is **self-paced**, you can start whenever you want.
|
||||
|
||||
## Required time ⏱️
|
||||
The required time for this unit is, approximately:
|
||||
- **1 hour** for the theory
|
||||
- **1 hour** for the hands-on.
|
||||
|
||||
## Start this Unit 🚀
|
||||
Here are the steps for this Unit:
|
||||
|
||||
1️⃣ 📖 Read [Introducing Decision Transformers on Hugging Face 🤗](https://huggingface.co/blog/decision-transformers)
|
||||
|
||||
2️⃣ 👩💻 Then dive on the first hands-on.
|
||||
👩💻 The hands-on 👉 [](https://colab.research.google.com/drive/1K3UuajwoPY1MzRKNkONNRS3gS5DxZ-qF?usp=sharing)
|
||||
|
||||
3️⃣ 📖 Read [Train your first Decision Transformer](https://huggingface.co/blog/train-decision-transformers)
|
||||
|
||||
4️⃣ 👩💻 Then dive on the hands-on, where **you’ll train your first Offline Decision Transformer model from scratch to make a half-cheetah run**.
|
||||
👩💻 The hands-on 👉 https://github.com/huggingface/blog/blob/main/notebooks/101_train-decision-transformers.ipynb
|
||||
|
||||
## How to make the most of this course
|
||||
|
||||
To make the most of the course, my advice is to:
|
||||
|
||||
- **Participate in Discord** and join a study group.
|
||||
- **Read multiple times** the theory part and takes some notes.
|
||||
- Don’t just do the colab. When you learn something, try to change the environment, change the parameters and read the libraries' documentation. Have fun 🥳.
|
||||
- Struggling is **a good thing in learning**. It means that you start to build new skills. Deep RL is a complex topic and it takes time to understand. Try different approaches, use our additional readings, and exchange with classmates on discord.
|
||||
|
||||
## This is a course built with you 👷🏿♀️
|
||||
|
||||
We want to improve and update the course iteratively with your feedback. **If you have some, please fill this form** 👉 https://forms.gle/3HgA7bEHwAmmLfwh9
|
||||
|
||||
## Don’t forget to join the Community 📢
|
||||
|
||||
We have a discord server where you **can exchange with the community and with us, create study groups to grow each other and more**
|
||||
|
||||
👉🏻 [https://discord.gg/aYka4Yhff9](https://discord.gg/aYka4Yhff9).
|
||||
|
||||
Don’t forget to **introduce yourself when you sign up 🤗**
|
||||
|
||||
❓If you have other questions, [please check our FAQ](https://github.com/huggingface/deep-rl-class#faq)
|
||||
|
||||
## Keep learning, stay awesome 🤗,
|
||||
@@ -1 +0,0 @@
|
||||
|
||||

|
Before Width: | Height: | Size: 1.2 MiB |
@@ -122,6 +122,8 @@
|
||||
title: Diving deeper into policy-gradient
|
||||
- local: unit4/pg-theorem
|
||||
title: (Optional) the Policy Gradient Theorem
|
||||
- local: unit4/glossary
|
||||
title: Glossary
|
||||
- local: unit4/hands-on
|
||||
title: Hands-on
|
||||
- local: unit4/quiz
|
||||
|
||||
@@ -3,8 +3,10 @@
|
||||
|
||||
The certification process is **completely free**:
|
||||
|
||||
- To get a *certificate of completion*: you need **to pass 80% of the assignments** before the end of July 2023.
|
||||
- To get a *certificate of excellence*: you need **to pass 100% of the assignments** before the end of July 2023.
|
||||
- To get a *certificate of completion*: you need **to pass 80% of the assignments**.
|
||||
- To get a *certificate of excellence*: you need **to pass 100% of the assignments**.
|
||||
|
||||
There's **no deadlines, the course is self-paced**.
|
||||
|
||||
<img src="https://huggingface.co/datasets/huggingface-deep-rl-course/course-images/resolve/main/en/unit0/certification.jpg" alt="Course certification" width="100%"/>
|
||||
|
||||
|
||||