mirror of
https://github.com/EstrellaXD/Auto_Bangumi.git
synced 2026-11-02 13:45:42 +08:00
Merge remote-tracking branch 'origin/4.0-dev' into feat/notifier-plugins
This commit is contained in:
 Estrella Pan
@@ -1,3 +1,12 @@
|
||||
# [4.0.0-beta.5] - 2026-10-21
|
||||
|
||||
- **修复(搜索订阅)**:从搜索结果(如 Nyaa)建立的订阅,关键词不再带入集号(`S03E02` → `S03`),订阅可以收到整季的更新(#1138)。升级后首次启动会自动修正已有搜索订阅链接里的集号,每条改动记入日志(数据库迁移 v28)
|
||||
- **修复(下载完成通知)**:文件路径不需要改变时(重命名方式为「不重命名」,或文件名已经符合规则),下载完成也会发送通知,每个种子只发一次(#1082,感谢 #1083)。注意:「不重命名」的用户升级后,个别此前从未处理过的已完成种子可能各补发一次通知
|
||||
- **修复(偏移检测)**:复扫没有发现偏移时,自动清除之前的偏移标记;连载中的番剧集数超出 TMDB 时仍会标记,但只通知一次,由用户忽略或应用;仍有偏移时更新原因与建议,不重复通知;未完结番剧的 TMDB 数据缓存 24 小时后刷新;已归档的番剧不再出现在待检查列表(#1072)
|
||||
- **修复(删除规则)**:删除规则时一次批量删除对应的种子记录,缩短数据库写锁时间(#1113)
|
||||
- **修复(WebUI)**:通知设置与 RSS 页面中缺失的图标恢复显示;设置页左侧导航的高亮与滚动位置对齐(参考 #1119,感谢 @JessySnow);HTTP 部署下复制访问令牌与搜索确认页的 RSS 链接可以正常使用,复制令牌失败时会提示
|
||||
- **修复(安全)**:海报接口 `/posters` 改为严格判断文件是否位于海报目录内
|
||||
|
||||
# [4.0.0-beta.4] - 2026-10-20
|
||||
|
||||
- **修复(日志)**:beta.3 中日志文件 `data/log.txt` 一直为空、日志页没有内容,现已恢复
|
||||
|
||||
@@ -170,6 +170,7 @@ Schema migrations are tracked via a `schema_version` table in SQLite. To add a n
|
||||
|
||||
1. Append a `Migration(version, "description", (…SQL…), already_applied=column_exists("table", "col"))` entry to the `MIGRATIONS` tuple in `backend/src/module/database/migrations.py` (`CURRENT_SCHEMA_VERSION` is derived from the list — do not edit it by hand)
|
||||
2. Provide an `already_applied` guard (`column_exists` / `table_exists`) so a schema created out-of-band is detected and skipped
|
||||
- For a one-time data fix, pass `data_step=<fn(conn: Connection)>` (statements may be empty). It runs after the SQL in the same SAVEPOINT. `schema_version` makes it run once, so its guard may only say "nothing to fix here".
|
||||
3. Migrations run automatically on startup via `run_migrations()` (each in a SAVEPOINT, stopping on first failure)
|
||||
|
||||
## Notes
|
||||
|
||||
@@ -123,7 +123,7 @@ ab-plugin pack my-plugin
|
||||
|
||||
## Star History
|
||||
|
||||
[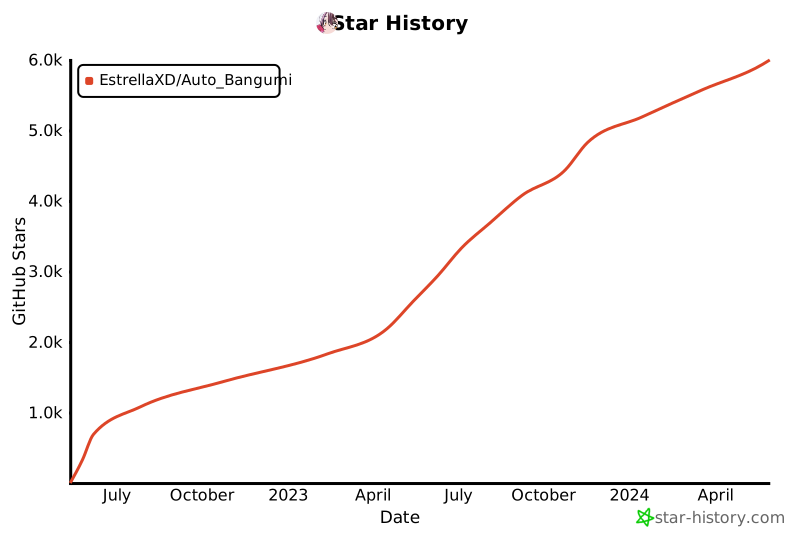](https://star-history.com/#EstrellaXD/Auto_Bangumi)
|
||||
[](https://star-history.dera.page/#EstrellaXD/Auto_Bangumi)
|
||||
|
||||
## Licence
|
||||
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
[project]
|
||||
name = "auto-bangumi"
|
||||
version = "4.0.0-beta.4"
|
||||
version = "4.0.0-beta.5"
|
||||
description = "AutoBangumi - Automated anime download manager"
|
||||
requires-python = ">=3.14"
|
||||
dependencies = [
|
||||
|
||||
@@ -151,7 +151,7 @@ _POSTERS_BASE = Path("data/posters").resolve()
|
||||
@app.get("/posters/{path:path}", tags=["posters"])
|
||||
def posters(path: str):
|
||||
resolved = (_POSTERS_BASE / path).resolve()
|
||||
if not str(resolved).startswith(str(_POSTERS_BASE)):
|
||||
if not resolved.is_relative_to(_POSTERS_BASE):
|
||||
return HTMLResponse(status_code=403)
|
||||
return FileResponse(str(resolved))
|
||||
|
||||
|
||||
@@ -54,11 +54,6 @@ class OffsetScanner:
|
||||
An event describing the flag if the bangumi was flagged for
|
||||
review, None otherwise.
|
||||
"""
|
||||
# Skip if already needs review
|
||||
if bangumi.needs_review:
|
||||
logger.debug(f"Skipping {bangumi.official_title}: already needs review")
|
||||
return None
|
||||
|
||||
# OVA/OAD/SP are persisted as Bangumi for library compatibility, but
|
||||
# they are not weekly episode streams and must never drive offsets.
|
||||
if bangumi.episode_type != "episode":
|
||||
@@ -96,7 +91,45 @@ class OffsetScanner:
|
||||
tmdb_info=tmdb_info,
|
||||
)
|
||||
|
||||
if suggestion and suggestion.confidence in ("high", "medium"):
|
||||
flagged = suggestion is not None and suggestion.confidence in (
|
||||
"high",
|
||||
"medium",
|
||||
)
|
||||
# 已标记的番剧也要重新扫描:TMDB 集数更新或解析修正后,误报不会自己消失
|
||||
# (#1072)。needs_review 只由本扫描器设置;用户忽略或应用后标记已清除,
|
||||
# 手动配了偏移的在上面已跳过,这里清除的只会是扫描器自己的旧标记
|
||||
if bangumi.needs_review:
|
||||
if not flagged:
|
||||
# 建议的偏移全为 0 的标记只是集数超出 TMDB 该季集数:连载中 TMDB
|
||||
# 跟上后清除、下周新集又超出,会每周重复通知,所以不自动清除,
|
||||
# 由用户忽略或应用
|
||||
if bangumi.suggested_season_offset or bangumi.suggested_episode_offset:
|
||||
async with Database() as db:
|
||||
await db.bangumi.clear_needs_review(bangumi.id)
|
||||
logger.info(
|
||||
"Cleared review flag for %s: no mismatch on rescan",
|
||||
bangumi.official_title,
|
||||
)
|
||||
elif suggestion is not None and (
|
||||
suggestion.reason,
|
||||
suggestion.season_offset,
|
||||
suggestion.episode_offset,
|
||||
) != (
|
||||
bangumi.needs_review_reason,
|
||||
bangumi.suggested_season_offset,
|
||||
bangumi.suggested_episode_offset,
|
||||
):
|
||||
# 仍不匹配但原因或建议变了:更新为最新结论,不再重复通知
|
||||
async with Database() as db:
|
||||
await db.bangumi.set_needs_review(
|
||||
bangumi.id,
|
||||
suggestion.reason,
|
||||
suggested_season_offset=suggestion.season_offset,
|
||||
suggested_episode_offset=suggestion.episode_offset,
|
||||
)
|
||||
return None
|
||||
|
||||
if suggestion and flagged:
|
||||
async with Database() as db:
|
||||
await db.bangumi.set_needs_review(
|
||||
bangumi.id,
|
||||
|
||||
@@ -700,6 +700,8 @@ class BangumiDatabase:
|
||||
and_(
|
||||
Bangumi.needs_review == True, # noqa: E712
|
||||
Bangumi.deleted == false(),
|
||||
# 偏移扫描跳过已归档的番剧,其旧标记不会再被清除,不列出
|
||||
Bangumi.archived == false(),
|
||||
)
|
||||
)
|
||||
result = await self.session.execute(statement)
|
||||
|
||||
@@ -11,6 +11,7 @@
|
||||
import logging
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Callable, get_args, get_origin
|
||||
from urllib.parse import parse_qsl, urlsplit
|
||||
|
||||
from pydantic.fields import FieldInfo
|
||||
from pydantic_core import PydanticUndefined
|
||||
@@ -87,6 +88,9 @@ class Migration:
|
||||
statements: tuple[str, ...]
|
||||
already_applied: AppliedCheck
|
||||
guarded_statements: tuple[GuardedStatement, ...] = ()
|
||||
# 一次性的数据修复:在 SQL 语句之后、同一 SAVEPOINT 内执行;
|
||||
# already_applied 为真时跳过
|
||||
data_step: Callable[[Connection], None] | None = None
|
||||
|
||||
def pending_statements(self, inspector) -> tuple[str, ...]:
|
||||
if self.guarded_statements:
|
||||
@@ -120,6 +124,66 @@ def _has_downloader_id(table: str) -> AppliedCheck:
|
||||
return check
|
||||
|
||||
|
||||
def _strip_search_keyword_episodes(conn: Connection) -> None:
|
||||
"""旧版本从搜索结果建的订阅把集号写进了搜索关键词(如 S03E02),刷新时
|
||||
一直按存下的 URL 拉取,订阅锁死在单集(#1138)。
|
||||
|
||||
只改搜索源 URL(主机、路径与某个搜索源模板一致,且带模板里 ``%s`` 所在的
|
||||
关键词参数):按引用该 URL 的番剧存下的 season_raw,把关键词里的季集写法
|
||||
换成只含季的写法,其余参数与编码原样保留;番剧 rss_link 里的同一 URL 一并
|
||||
替换。Mikan 番剧 RSS、用户手填的订阅不变。
|
||||
"""
|
||||
# 延迟导入:searcher 依赖 rss/network,模块级导入会与 database 循环
|
||||
from module.searcher.provider import available_sites, encode_keywords
|
||||
from module.searcher.searcher import strip_season_episode
|
||||
|
||||
keyword_params: dict[tuple[str, str], str] = {}
|
||||
for config in available_sites().values():
|
||||
template = urlsplit(config["url"])
|
||||
for name, value in parse_qsl(template.query):
|
||||
if value == "%s":
|
||||
keyword_params[(template.netloc, template.path)] = name
|
||||
season_by_url: dict[str, str] = {}
|
||||
for raw, rss_link in conn.execute(
|
||||
text(
|
||||
"SELECT season_raw, rss_link FROM bangumi "
|
||||
"WHERE season_raw IS NOT NULL AND rss_link IS NOT NULL"
|
||||
)
|
||||
):
|
||||
for link in rss_link.split(","):
|
||||
season_by_url.setdefault(link.strip(), raw)
|
||||
|
||||
for rss_id, url in conn.execute(text("SELECT id, url FROM rssitem")).all():
|
||||
parts = urlsplit(url)
|
||||
param_name = keyword_params.get((parts.netloc, parts.path))
|
||||
season_raw = season_by_url.get(url)
|
||||
if param_name is None or season_raw is None:
|
||||
continue
|
||||
old = f"+{encode_keywords([season_raw])}+"
|
||||
new = f"+{encode_keywords([strip_season_episode(season_raw)])}+"
|
||||
base, _, query = url.partition("?")
|
||||
params = query.split("&")
|
||||
for i, param in enumerate(params):
|
||||
key, sep, value = param.partition("=")
|
||||
if key == param_name and sep:
|
||||
params[i] = f"{key}={f'+{value}+'.replace(old, new, 1)[1:-1]}"
|
||||
new_url = f"{base}?{'&'.join(params)}"
|
||||
if new_url == url:
|
||||
continue
|
||||
conn.execute(
|
||||
text("UPDATE rssitem SET url = :new WHERE id = :id"),
|
||||
{"new": new_url, "id": rss_id},
|
||||
)
|
||||
conn.execute(
|
||||
text(
|
||||
"UPDATE bangumi SET rss_link = replace(rss_link, :old, :new) "
|
||||
"WHERE instr(rss_link, :old) > 0"
|
||||
),
|
||||
{"old": url, "new": new_url},
|
||||
)
|
||||
logger.info(f"Search subscription keyword drops episode: {url} -> {new_url}")
|
||||
|
||||
|
||||
# 迁移按版本顺序执行;版本号与 3.2.x 的历史保持一致,旧数据库照常升级。
|
||||
MIGRATIONS: tuple[Migration, ...] = (
|
||||
Migration(
|
||||
@@ -858,6 +922,20 @@ MIGRATIONS: tuple[Migration, ...] = (
|
||||
),
|
||||
_has_downloader_id("aria2_gid"),
|
||||
),
|
||||
Migration(
|
||||
28,
|
||||
"strip episode from search subscription keywords",
|
||||
(),
|
||||
# 数据修复没有可检查的 schema 痕迹,由 schema_version 保证只跑一次;
|
||||
# 缺少这些列的库里没有要修的订阅
|
||||
lambda inspector: (
|
||||
not all_checks(
|
||||
column_exists("bangumi", "season_raw"),
|
||||
column_exists("bangumi", "rss_link"),
|
||||
)(inspector)
|
||||
),
|
||||
data_step=_strip_search_keyword_episodes,
|
||||
),
|
||||
)
|
||||
|
||||
# 由迁移列表派生,新增迁移时无需手动同步
|
||||
@@ -908,8 +986,12 @@ def run_migrations_conn(conn: Connection) -> None:
|
||||
if migration.version <= current:
|
||||
continue
|
||||
# 每轮重新 inspect:前一个迁移的 DDL 需要对守卫可见
|
||||
pending = migration.pending_statements(inspect(conn))
|
||||
if not pending:
|
||||
inspector = inspect(conn)
|
||||
pending = migration.pending_statements(inspector)
|
||||
data_step = (
|
||||
None if migration.already_applied(inspector) else migration.data_step
|
||||
)
|
||||
if not pending and data_step is None:
|
||||
logger.debug(
|
||||
f"Migration v{migration.version} skipped "
|
||||
f"(already applied): {migration.description}"
|
||||
@@ -919,6 +1001,8 @@ def run_migrations_conn(conn: Connection) -> None:
|
||||
try:
|
||||
for stmt in pending:
|
||||
conn.execute(text(stmt))
|
||||
if data_step is not None:
|
||||
data_step(conn)
|
||||
savepoint.commit()
|
||||
logger.info(f"Migration v{migration.version}: {migration.description}")
|
||||
except Exception as e:
|
||||
|
||||
@@ -384,12 +384,43 @@ class RenameOperationDatabase:
|
||||
await self.session.commit()
|
||||
return True
|
||||
|
||||
async def prune_done(self, before: datetime) -> int:
|
||||
async def prune_done(
|
||||
self,
|
||||
before: datetime,
|
||||
live_task_ids: set[str],
|
||||
downloader_type: str | None,
|
||||
) -> int:
|
||||
"""清理过期的 done 记录。
|
||||
|
||||
路径未变的记录(重命名方式 none)只在任务已不在下载器里时清理:这类
|
||||
种子不打 ab:renamed、每轮都会再处理,删掉仍在的任务的记录会重建记录并
|
||||
再发一次下载完成通知(#1082)。``live_task_ids`` 是该实例当前的全部任务;
|
||||
为空时不能证明任务已删除,不清理这类记录。``downloader_type`` 为
|
||||
``None`` 时不限实例。
|
||||
"""
|
||||
expired = (
|
||||
col(RenameOperation.state) == "done",
|
||||
col(RenameOperation.updated_at) < before,
|
||||
)
|
||||
unchanged = col(RenameOperation.source_path) == col(RenameOperation.target_path)
|
||||
orphan_ids: list[int | None] = []
|
||||
if live_task_ids:
|
||||
statement = select(RenameOperation.id, RenameOperation.new_task_id).where(
|
||||
*expired, unchanged
|
||||
)
|
||||
if downloader_type is not None:
|
||||
statement = statement.where(
|
||||
RenameOperation.downloader_type == downloader_type
|
||||
)
|
||||
rows = await self.session.execute(statement)
|
||||
orphan_ids = [
|
||||
row_id for row_id, task_id in rows if task_id not in live_task_ids
|
||||
]
|
||||
result = await self.session.execute(
|
||||
delete(RenameOperation)
|
||||
.where(
|
||||
col(RenameOperation.state) == "done",
|
||||
col(RenameOperation.updated_at) < before,
|
||||
*expired,
|
||||
or_(~unchanged, col(RenameOperation.id).in_(orphan_ids)),
|
||||
)
|
||||
.execution_options(synchronize_session=False)
|
||||
)
|
||||
|
||||
@@ -3,7 +3,7 @@ from collections import defaultdict
|
||||
|
||||
from sqlalchemy import delete, func
|
||||
from sqlalchemy.ext.asyncio import AsyncSession
|
||||
from sqlmodel import and_, select, true
|
||||
from sqlmodel import and_, col, select, true
|
||||
|
||||
from module.models import Bangumi, RSSItem, Torrent
|
||||
|
||||
@@ -122,14 +122,15 @@ class TorrentDatabase:
|
||||
|
||||
Returns the number of deleted records.
|
||||
"""
|
||||
statement = select(Torrent).where(Torrent.bangumi_id == bangumi_id)
|
||||
result = await self.session.execute(statement)
|
||||
torrents = list(result.scalars().all())
|
||||
count = len(torrents)
|
||||
for t in torrents:
|
||||
await self.session.delete(t)
|
||||
# 单条 DELETE:逐行 ORM 删除会拉长写事务,与其他写入争 SQLite 锁(#1113)
|
||||
result = await self.session.execute(
|
||||
delete(Torrent)
|
||||
.where(col(Torrent.bangumi_id) == bangumi_id)
|
||||
.execution_options(synchronize_session=False)
|
||||
)
|
||||
await self.session.commit()
|
||||
count = result.rowcount # type: ignore[attr-defined]
|
||||
if count > 0:
|
||||
await self.session.commit()
|
||||
logger.debug(
|
||||
"Deleted %s torrent records for bangumi_id %s.", count, bangumi_id
|
||||
)
|
||||
|
||||
@@ -365,6 +365,7 @@ class Renamer(RevisionSaga):
|
||||
method: str | ProviderEntry,
|
||||
episode_offset: int,
|
||||
episode_type: str,
|
||||
notify_unchanged: bool,
|
||||
) -> MediaRenameReport:
|
||||
try:
|
||||
prepared = self._prepare_media_rename(
|
||||
@@ -561,6 +562,7 @@ class Renamer(RevisionSaga):
|
||||
identity=identity,
|
||||
bangumi_name=bangumi_name,
|
||||
episode_offset=episode_offset,
|
||||
notify_unchanged=notify_unchanged,
|
||||
)
|
||||
|
||||
def _finish_torrent(
|
||||
@@ -876,6 +878,9 @@ class Renamer(RevisionSaga):
|
||||
method=strategy,
|
||||
episode_offset=episode_offset,
|
||||
episode_type=episode_type,
|
||||
# 只认本轮实际用的就是选定策略:未登记而回退到 none 时文件
|
||||
# 保留原名,不记录也不通知,恢复后那一轮才记录并通知
|
||||
notify_unchanged=final_names,
|
||||
)
|
||||
if report.notification:
|
||||
renamed_info.append(report.notification)
|
||||
@@ -920,7 +925,9 @@ class Renamer(RevisionSaga):
|
||||
logger.warning(f"{torrent_name} has no media file")
|
||||
async with Database() as db:
|
||||
await db.rename_operation.prune_done(
|
||||
datetime.now(timezone.utc) - timedelta(days=30)
|
||||
datetime.now(timezone.utc) - timedelta(days=30),
|
||||
live_task_ids=set(info_by_hash),
|
||||
downloader_type=instance_key,
|
||||
)
|
||||
logger.debug("Rename process finished.")
|
||||
return renamed_info
|
||||
|
||||
@@ -112,9 +112,19 @@ class RevisionSaga:
|
||||
episode_offset: int,
|
||||
) -> MediaRenameReport:
|
||||
if prepared.source_path == prepared.target_path:
|
||||
# 文件名已是目标名(重命名方式 none,或已符合命名规则)时不会走真正的
|
||||
# 改名,这里是唯一能发下载完成通知的地方;操作记录随后置为 done,
|
||||
# 之后各轮直接返回,通知只发一次(#1082)
|
||||
return MediaRenameReport(
|
||||
result=RenameResult(RenameOutcome.ALREADY_APPLIED),
|
||||
prepared=prepared,
|
||||
notification=Notification(
|
||||
official_title=bangumi_name,
|
||||
season=prepared.episode.season,
|
||||
episode=self._adjust_episode(
|
||||
prepared.episode.episode, episode_offset
|
||||
),
|
||||
),
|
||||
)
|
||||
result = await self.client.rename_torrent_file(
|
||||
_hash=_hash,
|
||||
@@ -837,9 +847,17 @@ class RevisionSaga:
|
||||
identity: RevisionIdentity | None,
|
||||
bangumi_name: str,
|
||||
episode_offset: int,
|
||||
notify_unchanged: bool = False,
|
||||
) -> MediaRenameReport:
|
||||
"""Claim and execute one non-replacement rename exactly once at a time."""
|
||||
|
||||
if prepared.source_path == prepared.target_path and not notify_unchanged:
|
||||
# 选定策略未登记、本轮回退到 none:原名不是最终名,不建操作记录也不
|
||||
# 通知;策略恢复后那一轮再建记录并通知(#1082)
|
||||
return MediaRenameReport(
|
||||
result=RenameResult(RenameOutcome.ALREADY_APPLIED),
|
||||
prepared=prepared,
|
||||
)
|
||||
template = self._build_operation(
|
||||
info=info,
|
||||
prepared=prepared,
|
||||
|
||||
@@ -30,6 +30,12 @@ _TMDB_CACHE_MAX = 512
|
||||
# 否定/回退结果(无匹配、回退到电影)的存活时间:既避免对同一个查不到的标题
|
||||
# 反复请求 TMDB,又不让一次临时故障把标题永久毒化
|
||||
_TMDB_NEGATIVE_TTL = 6 * 3600.0
|
||||
# 未完结剧集的各季集数每周都在变;永久缓存会让偏移扫描一直拿旧集数误报,
|
||||
# 也无法在 TMDB 更新后自动清除标记(#1072)
|
||||
_TMDB_AIRING_TTL = 24 * 3600.0
|
||||
# TMDB 剧集的终态;其余状态(Returning Series、In Production、Planned、Pilot、
|
||||
# 未知)都可能继续更新集数
|
||||
FINAL_SERIES_STATUSES = frozenset({"Ended", "Canceled"})
|
||||
# 值为 (过期的 monotonic 时刻, 结果);inf 表示不过期
|
||||
_tmdb_cache: OrderedDict[str, "tuple[float, TMDBInfo | None]"] = OrderedDict()
|
||||
|
||||
@@ -265,11 +271,12 @@ async def tmdb_parser(
|
||||
logger.warning("TMDB request failed for %s: %s", title, e)
|
||||
return None
|
||||
# 剧集结果的 season 非空;None 与电影回退(season=[])都按否定结果限时缓存
|
||||
expires = (
|
||||
time.monotonic() + _TMDB_NEGATIVE_TTL
|
||||
if result is None or not result.season
|
||||
else float("inf")
|
||||
)
|
||||
if result is None or not result.season:
|
||||
expires = time.monotonic() + _TMDB_NEGATIVE_TTL
|
||||
elif result.series_status not in FINAL_SERIES_STATUSES:
|
||||
expires = time.monotonic() + _TMDB_AIRING_TTL
|
||||
else:
|
||||
expires = float("inf")
|
||||
_tmdb_cache[cache_key] = (expires, result)
|
||||
_tmdb_cache.move_to_end(cache_key)
|
||||
if len(_tmdb_cache) > _TMDB_CACHE_MAX:
|
||||
|
||||
@@ -496,7 +496,8 @@ def _extract_numbers(working: list[_WorkingSegment], state: _State) -> None:
|
||||
work.consume(match)
|
||||
_extract_episode_title(work, match, state)
|
||||
state.season = int(match.group(1))
|
||||
state.season_raw = match.group(0)
|
||||
# 只记季的写法(S03 / Season 2),不带集数(#1138)
|
||||
state.season_raw = match.string[match.start() : match.end(1)]
|
||||
state.set_episode(
|
||||
_number(match.group(2)),
|
||||
priority=100,
|
||||
|
||||
@@ -770,7 +770,8 @@ def _collect_structural_candidates(collector: _CandidateCollector) -> None:
|
||||
match=match,
|
||||
claims=Claims(
|
||||
season=int(match.group(1)),
|
||||
season_raw=match.group(0),
|
||||
# 只记季的写法(S03 / Season 2),不带集数(#1138)
|
||||
season_raw=match.string[match.start() : match.end(1)],
|
||||
episode=start,
|
||||
episode_end=end,
|
||||
release_kind=ReleaseKind.RANGE,
|
||||
@@ -879,7 +880,8 @@ def _collect_structural_candidates(collector: _CandidateCollector) -> None:
|
||||
match=match,
|
||||
claims=Claims(
|
||||
season=int(match.group(1)),
|
||||
season_raw=match.group(0),
|
||||
# 只记季的写法(S03 / Season 2),不带集数(#1138)
|
||||
season_raw=match.string[match.start() : match.end(1)],
|
||||
episode=_number(match.group(2)),
|
||||
episode_title=episode_title,
|
||||
version=_int(match.group(3)),
|
||||
|
||||
@@ -28,9 +28,13 @@ def available_sites() -> dict[str, ProviderConfig]:
|
||||
return sites
|
||||
|
||||
|
||||
def encode_keywords(keywords: list[str]) -> str:
|
||||
"""把关键词拼成搜索 URL 里的查询串:非单词字符都换成 ``+``。"""
|
||||
return re.sub(r"[\W_ ]", "+", "+".join(keywords))
|
||||
|
||||
|
||||
def search_url(site: str, keywords: list[str]) -> RSSItem:
|
||||
keyword = "+".join(keywords)
|
||||
search_str = re.sub(r"[\W_ ]", "+", keyword)
|
||||
search_str = encode_keywords(keywords)
|
||||
providers = available_sites()
|
||||
if site in providers:
|
||||
# str.replace, not re.sub: the template is a literal "%s" placeholder,
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
import json
|
||||
import logging
|
||||
import re
|
||||
from collections import OrderedDict
|
||||
|
||||
from module.conf import settings
|
||||
@@ -21,6 +22,18 @@ SEARCH_KEY = [
|
||||
"dpi",
|
||||
]
|
||||
|
||||
# 解析器现在只把季的写法存进 season_raw;旧版本存下的「S03E02」「Season 2 EPs
|
||||
# 01-12」这类季集合写仍留在数据库里(补全整季时会读到),只保留季的部分,
|
||||
# 否则订阅关键词锁死在单集(#1138)
|
||||
_SEASON_WITH_EPISODE = re.compile(
|
||||
r"^(S\d{1,2}|Season\s+\d{1,2})\s*E(?:Ps?|pisodes?)?\.?\s*\d.*$", re.I
|
||||
)
|
||||
|
||||
|
||||
def strip_season_episode(season_raw: str) -> str:
|
||||
"""季集合写的 season_raw 只保留季的部分(S03E02 -> S03)。"""
|
||||
return _SEASON_WITH_EPISODE.sub(r"\1", season_raw)
|
||||
|
||||
|
||||
# Cache for TMDB preview lookups by official_title. Bounded (LRU-ish,
|
||||
# oldest-evicted) like _tmdb_cache/_mikan_cache — was previously a plain dict
|
||||
@@ -103,7 +116,11 @@ class SearchTorrent:
|
||||
|
||||
@staticmethod
|
||||
def special_url(data: Bangumi | Movie, site: str) -> RSSItem:
|
||||
keywords = [value for key in SEARCH_KEY if (value := getattr(data, key, None))]
|
||||
keywords = [
|
||||
strip_season_episode(value) if key == "season_raw" else value
|
||||
for key in SEARCH_KEY
|
||||
if (value := getattr(data, key, None))
|
||||
]
|
||||
url = search_url(site, keywords)
|
||||
return url
|
||||
|
||||
|
||||
@@ -45,7 +45,7 @@
|
||||
"title_en": "Anime Title",
|
||||
"group": "Group",
|
||||
"season": 2,
|
||||
"season_raw": "S02E05",
|
||||
"season_raw": "S02",
|
||||
"episode": 5,
|
||||
"media_type": "episode",
|
||||
"resolution": "1080p",
|
||||
@@ -56,7 +56,7 @@
|
||||
"title_zh": null,
|
||||
"title_jp": null,
|
||||
"season": 2,
|
||||
"season_raw": "S02E05",
|
||||
"season_raw": "S02",
|
||||
"episode": 5,
|
||||
"sub": null,
|
||||
"group": "Group",
|
||||
@@ -666,7 +666,7 @@
|
||||
"expected": {
|
||||
"title_en": "Anime Title",
|
||||
"season": 2,
|
||||
"season_raw": "S02E05",
|
||||
"season_raw": "S02",
|
||||
"episode": 5,
|
||||
"media_type": "episode",
|
||||
"resolution": "1080p"
|
||||
@@ -676,7 +676,7 @@
|
||||
"title_zh": null,
|
||||
"title_jp": null,
|
||||
"season": 2,
|
||||
"season_raw": "S02E05",
|
||||
"season_raw": "S02",
|
||||
"episode": 5,
|
||||
"sub": null,
|
||||
"group": "",
|
||||
@@ -886,7 +886,7 @@
|
||||
"expected": {
|
||||
"title_en": "Mob Psycho 100",
|
||||
"season": 3,
|
||||
"season_raw": "S03E05",
|
||||
"season_raw": "S03",
|
||||
"episode": 5,
|
||||
"episode_title": "Divine Tree 2 ~Peace~",
|
||||
"media_type": "episode",
|
||||
@@ -897,7 +897,7 @@
|
||||
"title_zh": null,
|
||||
"title_jp": null,
|
||||
"season": 3,
|
||||
"season_raw": "S03E05",
|
||||
"season_raw": "S03",
|
||||
"episode": 5,
|
||||
"sub": null,
|
||||
"group": "",
|
||||
@@ -1483,7 +1483,7 @@
|
||||
"title_en": "Anime Title",
|
||||
"group": "Group",
|
||||
"season": 2,
|
||||
"season_raw": "Season 2 Episode 08",
|
||||
"season_raw": "Season 2",
|
||||
"episode": 8,
|
||||
"media_type": "episode",
|
||||
"resolution": "1080p"
|
||||
@@ -1493,7 +1493,7 @@
|
||||
"title_zh": null,
|
||||
"title_jp": null,
|
||||
"season": 2,
|
||||
"season_raw": "Season 2 Episode 08",
|
||||
"season_raw": "Season 2",
|
||||
"episode": 8,
|
||||
"sub": null,
|
||||
"group": "Group",
|
||||
|
||||
@@ -946,6 +946,25 @@ class TestSearchByBangumiId:
|
||||
assert await db.search_by_bangumi_id(999) == []
|
||||
|
||||
|
||||
async def test_get_needs_review_excludes_archived(db_session):
|
||||
"""已归档的番剧不再参与偏移扫描,旧的检查标记不应继续列出。"""
|
||||
db = BangumiDatabase(db_session)
|
||||
for title, archived in (("Active Review", False), ("Archived Review", True)):
|
||||
db_session.add(
|
||||
Bangumi(
|
||||
official_title=title,
|
||||
title_raw=f"{title} Raw",
|
||||
group_name="TestGroup",
|
||||
rss_link="r",
|
||||
needs_review=True,
|
||||
archived=archived,
|
||||
)
|
||||
)
|
||||
await db_session.commit()
|
||||
|
||||
assert [b.official_title for b in await db.get_needs_review()] == ["Active Review"]
|
||||
|
||||
|
||||
class TestApplyOffset:
|
||||
"""Tests for BangumiDatabase.apply_offset."""
|
||||
|
||||
|
||||
@@ -261,7 +261,59 @@ async def test_conflict_query_and_done_pruning(db_session):
|
||||
conflict.updated_at = now - timedelta(days=31)
|
||||
db_session.add(conflict)
|
||||
await db_session.commit()
|
||||
assert await repo.prune_done(before=now - timedelta(days=30)) == 1
|
||||
assert (
|
||||
await repo.prune_done(
|
||||
before=now - timedelta(days=30),
|
||||
live_task_ids={"conflict-v4"},
|
||||
downloader_type=None,
|
||||
)
|
||||
== 1
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("live_task_ids", "downloader_type", "pruned"),
|
||||
[
|
||||
({"new-v2"}, None, False),
|
||||
({"other-task"}, None, True),
|
||||
(set(), None, False),
|
||||
({"other-task"}, "qbittorrent", True),
|
||||
({"other-task"}, "aria2", False),
|
||||
],
|
||||
ids=[
|
||||
"task-present",
|
||||
"task-gone",
|
||||
"empty-snapshot",
|
||||
"same-instance",
|
||||
"other-instance",
|
||||
],
|
||||
)
|
||||
async def test_prune_done_unchanged_path_rows_only_when_task_gone(
|
||||
db_session, live_task_ids, downloader_type, pruned
|
||||
):
|
||||
"""路径未变(重命名方式 none)的 done 记录是只通知一次的依据:任务仍在、
|
||||
快照为空或属于别的实例时保留,任务已从该实例删除时清理(#1082)。"""
|
||||
repo = RenameOperationDatabase(db_session)
|
||||
now = datetime.now(timezone.utc)
|
||||
row, _ = await repo.get_or_create(
|
||||
_operation(
|
||||
kind="conflict",
|
||||
state="done",
|
||||
source_path="Anime - 01.mkv",
|
||||
target_path="Anime - 01.mkv",
|
||||
)
|
||||
)
|
||||
row.updated_at = now - timedelta(days=31)
|
||||
db_session.add(row)
|
||||
await db_session.commit()
|
||||
|
||||
assert await repo.prune_done(
|
||||
before=now - timedelta(days=30),
|
||||
live_task_ids=live_task_ids,
|
||||
downloader_type=downloader_type,
|
||||
) == int(pruned)
|
||||
db_session.expunge_all()
|
||||
assert (await repo.get(row.id) is None) is pruned
|
||||
|
||||
|
||||
async def test_database_facade_exposes_rename_operation_repository(db_engine):
|
||||
|
||||
27
backend/src/test/test_main_posters.py
Normal file
27
backend/src/test/test_main_posters.py
Normal file
@@ -0,0 +1,27 @@
|
||||
"""/posters 路由只能读海报目录内的文件。"""
|
||||
|
||||
import pytest
|
||||
from fastapi.responses import FileResponse
|
||||
|
||||
import main
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("path", "allowed"),
|
||||
[
|
||||
("a.jpg", True),
|
||||
# 同名前缀的兄弟目录:按字符串前缀检查时会被放行
|
||||
("../posters_x/secret.jpg", False),
|
||||
("../secret.jpg", False),
|
||||
],
|
||||
)
|
||||
def test_posters_rejects_paths_outside_base(tmp_path, monkeypatch, path, allowed):
|
||||
base = tmp_path / "posters"
|
||||
base.mkdir()
|
||||
monkeypatch.setattr(main, "_POSTERS_BASE", base)
|
||||
|
||||
resp = main.posters(path)
|
||||
|
||||
assert isinstance(resp, FileResponse) is allowed
|
||||
if not allowed:
|
||||
assert resp.status_code == 403
|
||||
@@ -6,7 +6,7 @@ import pytest
|
||||
from sqlalchemy import inspect, text
|
||||
from sqlalchemy.engine import Engine
|
||||
from sqlalchemy.exc import IntegrityError, OperationalError
|
||||
from sqlmodel import SQLModel, create_engine
|
||||
from sqlmodel import SQLModel, create_engine, select
|
||||
|
||||
import module.database.migrations as migration_module
|
||||
from module.database.migrations import (
|
||||
@@ -894,3 +894,82 @@ class TestRunMigrations:
|
||||
inspector = inspect(engine)
|
||||
rssitem_cols = {c["name"] for c in inspector.get_columns("rssitem")}
|
||||
assert "connection_status" not in rssitem_cols
|
||||
|
||||
|
||||
class TestSearchKeywordEpisodeMigration:
|
||||
NYAA = "https://nyaa.si/?page=rss&q=%s&c=0_0&f=0"
|
||||
PROVIDERS = {
|
||||
"nyaa": {"url": NYAA, "parser": "tmdb"},
|
||||
"dmhy": {
|
||||
"url": "http://dmhy.org/topics/rss/rss.xml?keyword=%s",
|
||||
"parser": "tmdb",
|
||||
},
|
||||
"mikan": {
|
||||
"url": "https://mikanani.me/RSS/Search?searchstr=%s",
|
||||
"parser": "mikan",
|
||||
},
|
||||
}
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("season_raw", "url", "expected"),
|
||||
[
|
||||
(
|
||||
"S03E02",
|
||||
NYAA.replace(
|
||||
"%s",
|
||||
"ToonsHub+The+Apothecary+Diaries+S03E02+Multi+Subs+NF+WEB+DL+1080p",
|
||||
),
|
||||
NYAA.replace(
|
||||
"%s",
|
||||
"ToonsHub+The+Apothecary+Diaries+S03+Multi+Subs+NF+WEB+DL+1080p",
|
||||
),
|
||||
),
|
||||
(
|
||||
"Season 2 EPs 01-12",
|
||||
"http://dmhy.org/topics/rss/rss.xml?keyword=ANi+葬送的芙莉莲+Season+2+EPs+01+12+1080P",
|
||||
"http://dmhy.org/topics/rss/rss.xml?keyword=ANi+葬送的芙莉莲+Season+2+1080P",
|
||||
),
|
||||
("S03", NYAA.replace("%s", "Show+S03+1080p"), None),
|
||||
(
|
||||
"S03E02",
|
||||
"https://mikanani.me/RSS/Bangumi?bangumiId=3519&subgroupid=583",
|
||||
None,
|
||||
),
|
||||
],
|
||||
ids=["nyaa-episode", "dmhy-multi-token", "no-episode", "mikan-bangumi-feed"],
|
||||
)
|
||||
def test_strips_episode_from_search_subscription_once(
|
||||
self, monkeypatch, season_raw, url, expected
|
||||
):
|
||||
"""旧版本搜索订阅关键词里的集号在启动时去掉一次,非搜索 URL 不变(#1138)。"""
|
||||
from sqlmodel import Session
|
||||
|
||||
from module.models import Bangumi, RSSItem
|
||||
from test.factories import make_bangumi
|
||||
|
||||
monkeypatch.setattr(
|
||||
"module.searcher.provider.get_provider", lambda: self.PROVIDERS
|
||||
)
|
||||
engine = create_engine("sqlite://")
|
||||
SQLModel.metadata.create_all(engine)
|
||||
with engine.begin() as conn:
|
||||
ensure_schema_version_table(conn)
|
||||
set_schema_version(conn, CURRENT_SCHEMA_VERSION - 1)
|
||||
other = "https://mikanani.me/RSS/Bangumi?bangumiId=1"
|
||||
with Session(engine) as session:
|
||||
session.add(RSSItem(id=1, url=url))
|
||||
session.add(make_bangumi(season_raw=season_raw, rss_link=f"{other},{url}"))
|
||||
session.commit()
|
||||
|
||||
run_migrations(engine)
|
||||
with engine.begin() as conn:
|
||||
assert get_schema_version(conn) == CURRENT_SCHEMA_VERSION
|
||||
# 再跑一次不再改动
|
||||
migration_module._strip_search_keyword_episodes(conn)
|
||||
|
||||
with Session(engine) as session:
|
||||
rss = session.get(RSSItem, 1)
|
||||
bangumi = session.exec(select(Bangumi)).one()
|
||||
assert rss is not None
|
||||
assert rss.url == (expected or url)
|
||||
assert bangumi.rss_link == f"{other},{expected or url}"
|
||||
|
||||
@@ -358,3 +358,114 @@ class TestCheckBangumiUsesRealSignal:
|
||||
assert updated.needs_review_reason is not None
|
||||
assert "13" in updated.needs_review_reason
|
||||
assert "12" in updated.needs_review_reason
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("season", "episode", "kept_after_catch_up"),
|
||||
[
|
||||
(1, 13, True), # 只超出集数:TMDB 跟上后也不自动清除,由用户处理
|
||||
(2, 5, False), # 季度对不上:TMDB 跟上后不再不匹配,自动清除
|
||||
],
|
||||
ids=["overflow-only", "season-mismatch"],
|
||||
)
|
||||
async def test_airing_show_flag_notifies_once(
|
||||
self, season, episode, kept_after_catch_up
|
||||
):
|
||||
"""连载中的番剧标记后只通知一次;只超出集数的标记不随复扫清除(#1072)。"""
|
||||
scanner = OffsetScanner()
|
||||
async with Database() as db:
|
||||
bangumi = make_bangumi(
|
||||
title_raw="Airing Anime",
|
||||
season=season,
|
||||
season_offset=0,
|
||||
episode_offset=0,
|
||||
)
|
||||
await db.bangumi.add(bangumi)
|
||||
await db.torrent.add(
|
||||
Torrent(
|
||||
name=f"[TestGroup] Airing Anime - {episode:02d} [1080p].mkv",
|
||||
url="https://example.com/airing",
|
||||
refer_id=bangumi.id,
|
||||
)
|
||||
)
|
||||
|
||||
tmdb_info = self._ended_twelve_episode_season()
|
||||
tmdb_info.series_status = "Returning Series"
|
||||
|
||||
async def scan():
|
||||
async with Database() as db:
|
||||
current = await db.bangumi.search_id(bangumi.id)
|
||||
with patch(
|
||||
"module.core.offset_scanner.tmdb_parser",
|
||||
new=AsyncMock(return_value=tmdb_info),
|
||||
):
|
||||
event = await scanner._check_bangumi(current)
|
||||
async with Database() as db:
|
||||
updated = await db.bangumi.search_id(bangumi.id)
|
||||
return event, updated.needs_review
|
||||
|
||||
# 首次扫描:标记并通知一次
|
||||
event, needs_review = await scan()
|
||||
assert isinstance(event, OffsetReviewEvent)
|
||||
assert needs_review is True
|
||||
|
||||
# 复扫仍是同样的不匹配:保留标记,不再通知
|
||||
assert await scan() == (None, True)
|
||||
|
||||
# TMDB 跟上(多了第 13 集和第 2 季)后复扫:不再通知
|
||||
tmdb_info.last_season = 2
|
||||
tmdb_info.season_episode_counts = {1: 13, 2: 12}
|
||||
assert await scan() == (None, kept_after_catch_up)
|
||||
|
||||
|
||||
class TestRescanFlaggedBangumi:
|
||||
"""已标记的番剧重新扫描:误报自动清除,其余情况保留标记(#1072)。"""
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("episode", "season_offset", "tmdb_found", "expected_reason"),
|
||||
[
|
||||
(6, 0, True, None), # TMDB 已更新 / 解析已修正:不再不匹配,清除
|
||||
(13, 0, True, "调整后集数13超出TMDB该季的12集"), # 仍不匹配:换成新原因
|
||||
(6, -1, True, "旧原因"), # 用户已手动配置偏移:不动
|
||||
(6, 0, False, "旧原因"), # TMDB 暂时查不到:没有新结论,不动
|
||||
],
|
||||
ids=["no-mismatch", "still-mismatch", "user-offset", "tmdb-miss"],
|
||||
)
|
||||
async def test_rescan_clears_only_stale_scanner_flag(
|
||||
self, episode, season_offset, tmdb_found, expected_reason
|
||||
):
|
||||
scanner = OffsetScanner()
|
||||
reason = "旧原因"
|
||||
async with Database() as db:
|
||||
bangumi = make_bangumi(
|
||||
title_raw="Rescan Anime",
|
||||
season=1,
|
||||
season_offset=season_offset,
|
||||
episode_offset=0,
|
||||
)
|
||||
await db.bangumi.add(bangumi)
|
||||
# 建议偏移非 0 的真实不匹配标记;只超出集数的标记不自动清除
|
||||
await db.bangumi.set_needs_review(
|
||||
bangumi.id, reason, suggested_season_offset=-1
|
||||
)
|
||||
await db.torrent.add(
|
||||
Torrent(
|
||||
name=f"[TestGroup] Rescan Anime - {episode:02d} [1080p].mkv",
|
||||
url="https://example.com/rescan",
|
||||
refer_id=bangumi.id,
|
||||
)
|
||||
)
|
||||
bangumi = await db.bangumi.search_id(bangumi.id)
|
||||
|
||||
tmdb_info = TestCheckBangumiUsesRealSignal._ended_twelve_episode_season()
|
||||
with patch(
|
||||
"module.core.offset_scanner.tmdb_parser",
|
||||
new=AsyncMock(return_value=tmdb_info if tmdb_found else None),
|
||||
):
|
||||
event = await scanner._check_bangumi(bangumi)
|
||||
|
||||
# 已标记过的番剧不再重复发送检查通知
|
||||
assert event is None
|
||||
async with Database() as db:
|
||||
updated = await db.bangumi.search_id(bangumi.id)
|
||||
assert updated.needs_review is (expected_reason is not None)
|
||||
assert updated.needs_review_reason == expected_reason
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
"""Tests for Renamer: gen_path, single-file / collection rename, rename flow."""
|
||||
|
||||
from datetime import datetime, timedelta, timezone
|
||||
from unittest.mock import AsyncMock, MagicMock, patch
|
||||
|
||||
import pytest
|
||||
@@ -7,7 +8,7 @@ import pytest
|
||||
from module.conf import settings
|
||||
from module.downloader import DownloadClient, RenameOutcome, RenameResult
|
||||
from module.manager.renamer import PreparedMediaRename, Renamer
|
||||
from module.models import EpisodeFile, Notification, SubtitleFile
|
||||
from module.models import EpisodeFile, Notification, RenameOperation, SubtitleFile
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# gen_path
|
||||
@@ -452,7 +453,8 @@ class TestRenameSingleFile:
|
||||
)
|
||||
result = await self._rename(renamer, ep, media_path="My Anime S01E05.mkv")
|
||||
|
||||
assert result == []
|
||||
# 首次处理即完成,下载完成通知照发(#1082)
|
||||
assert result == [Notification(official_title="My Anime", season=1, episode=5)]
|
||||
renamer.client.client.torrents_rename_file.assert_not_awaited()
|
||||
renamer.client.client.add_tag.assert_awaited_once_with("hash123", "ab:renamed")
|
||||
|
||||
@@ -504,6 +506,119 @@ class TestRenameSingleFile:
|
||||
renamer.client.client.torrents_rename_file.assert_not_awaited()
|
||||
renamer.client.client.add_tag.assert_not_awaited()
|
||||
|
||||
async def test_none_method_notifies_once_across_loops(self, renamer):
|
||||
"""none 方法不改名也要发下载完成通知;种子每轮都会再处理,通知只发一次(#1082)。"""
|
||||
ep = EpisodeFile(
|
||||
media_path="old.mkv", title="My Anime", season=1, episode=5, suffix=".mkv"
|
||||
)
|
||||
first = await self._rename(renamer, ep, method="none", _hash="hash-none")
|
||||
second = await self._rename(renamer, ep, method="none", _hash="hash-none")
|
||||
|
||||
assert first == [Notification(official_title="My Anime", season=1, episode=5)]
|
||||
assert second == []
|
||||
renamer.client.client.torrents_rename_file.assert_not_awaited()
|
||||
|
||||
async def test_unchanged_path_notifies_once_for_configured_strategy(self, renamer):
|
||||
"""文件名已是目标名时首轮通知一次(#1082)。"""
|
||||
ep = EpisodeFile(
|
||||
media_path="My Anime S01E05.mkv",
|
||||
title="My Anime",
|
||||
season=1,
|
||||
episode=5,
|
||||
suffix=".mkv",
|
||||
)
|
||||
loops = [
|
||||
await self._rename(
|
||||
renamer,
|
||||
ep,
|
||||
media_path="My Anime S01E05.mkv",
|
||||
_hash="hash-unchanged",
|
||||
)
|
||||
for _ in range(2)
|
||||
]
|
||||
|
||||
expected = [Notification(official_title="My Anime", season=1, episode=5)]
|
||||
assert loops == [expected, []]
|
||||
renamer.client.client.torrents_rename_file.assert_not_awaited()
|
||||
|
||||
async def test_unchanged_path_fallback_round_defers_record_and_notification(
|
||||
self, renamer
|
||||
):
|
||||
"""选定策略未登记、本轮回退到 none 时原名不是最终名:不建操作记录也不
|
||||
通知;策略恢复后那一轮文件名仍未变,也要通知一次(#1082)。"""
|
||||
from module.database import Database
|
||||
|
||||
ep = EpisodeFile(
|
||||
media_path="My Anime S01E05.mkv",
|
||||
title="My Anime",
|
||||
season=1,
|
||||
episode=5,
|
||||
suffix=".mkv",
|
||||
)
|
||||
|
||||
async def loop(method: str) -> list[Notification]:
|
||||
return await self._rename(
|
||||
renamer,
|
||||
ep,
|
||||
media_path="My Anime S01E05.mkv",
|
||||
method=method,
|
||||
_hash="hash-fallback",
|
||||
)
|
||||
|
||||
async def operation() -> RenameOperation | None:
|
||||
async with Database() as db:
|
||||
return await db.rename_operation.get_by_target(
|
||||
downloader_type=renamer._downloader_type(),
|
||||
save_path=self.SAVE_PATH,
|
||||
target_path="My Anime S01E05.mkv",
|
||||
active_only=False,
|
||||
)
|
||||
|
||||
assert await loop("not-installed") == []
|
||||
assert await operation() is None
|
||||
assert [await loop("pn") for _ in range(2)] == [
|
||||
[Notification(official_title="My Anime", season=1, episode=5)],
|
||||
[],
|
||||
]
|
||||
row = await operation()
|
||||
assert row is not None and row.state == "done"
|
||||
renamer.client.client.torrents_rename_file.assert_not_awaited()
|
||||
|
||||
async def test_unchanged_path_done_row_pruned_only_after_task_removed(
|
||||
self, renamer
|
||||
):
|
||||
"""路径未变的 done 记录过期后,任务仍在时保留且不再通知;任务从下载器
|
||||
删除后清理,表不会随已删除的种子无限增长(#1082)。"""
|
||||
from module.database import Database
|
||||
|
||||
ep = EpisodeFile(
|
||||
media_path="old.mkv", title="My Anime", season=1, episode=5, suffix=".mkv"
|
||||
)
|
||||
assert await self._rename(renamer, ep, method="none", _hash="hash-gone")
|
||||
async with Database() as db:
|
||||
row = await db.rename_operation.get_by_target(
|
||||
downloader_type=renamer._downloader_type(),
|
||||
save_path=self.SAVE_PATH,
|
||||
target_path="old.mkv",
|
||||
active_only=False,
|
||||
)
|
||||
assert row is not None
|
||||
row_id = row.id
|
||||
row.updated_at = datetime.now(timezone.utc) - timedelta(days=31)
|
||||
db.session.add(row)
|
||||
await db.session.commit()
|
||||
|
||||
assert await self._rename(renamer, ep, method="none", _hash="hash-gone") == []
|
||||
async with Database() as db:
|
||||
assert await db.rename_operation.get(row_id) is not None
|
||||
|
||||
# 下载器里只剩另一个任务:原任务已删除
|
||||
await self._rename(
|
||||
renamer, ep, media_path="other.mkv", method="none", _hash="hash-other"
|
||||
)
|
||||
async with Database() as db:
|
||||
assert await db.rename_operation.get(row_id) is None
|
||||
|
||||
@pytest.mark.parametrize("remove_bad_torrent", [False, True])
|
||||
async def test_parse_fails(self, renamer, remove_bad_torrent):
|
||||
"""解析失败时不返回通知;仅 remove_bad_torrent=True 时删除种子。"""
|
||||
|
||||
@@ -173,6 +173,80 @@ class TestSpecialUrl:
|
||||
# Only title_raw should be in the URL
|
||||
assert "Test" in result.url
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("title", "keyword"),
|
||||
[
|
||||
(
|
||||
"[ToonsHub] The Apothecary Diaries S03E02 Multi Subs NF WEB-DL 1080p",
|
||||
"ToonsHub+The+Apothecary+Diaries+S03+Multi+Subs+NF+1080p",
|
||||
),
|
||||
(
|
||||
"[ToonsHub] The Apothecary Diaries S03 E02 1080p NF WEB-DL",
|
||||
"ToonsHub+The+Apothecary+Diaries+S03+NF+1080p",
|
||||
),
|
||||
(
|
||||
"[ANi] 葬送的芙莉莲 第二季 - 05 [1080P][Baha][WEB-DL][AAC AVC][CHT][MP4]",
|
||||
"ANi+葬送的芙莉莲+第二季+CHT+Baha+1080P",
|
||||
),
|
||||
(
|
||||
"[Lilith-Raws] Kusuriya no Hitorigoto S2 - 05 [Baha][WebDL 1080p AVC AAC][CHT]",
|
||||
"Lilith+Raws+Kusuriya+no+Hitorigoto+S2+CHT+Baha+1080p",
|
||||
),
|
||||
(
|
||||
"[SubsPlease] Spy x Family Season 2 - 05 (1080p) [ABCDEF12].mkv",
|
||||
"SubsPlease+Spy+x+Family+Season+2+1080p",
|
||||
),
|
||||
(
|
||||
"[Erai-raws] Mushoku Tensei 2nd Season - 05 [1080p][Multiple Subtitle]",
|
||||
"Erai+raws+Mushoku+Tensei+2nd+Season+Multiple+Subtitle+1080p",
|
||||
),
|
||||
],
|
||||
)
|
||||
async def test_keyword_keeps_season_but_drops_episode(self, title, keyword):
|
||||
"""搜索结果生成订阅时关键词保留季、去掉集数,订阅才能收到后续集(#1138)。"""
|
||||
from module.parser.title_parser import TitleParser
|
||||
from module.searcher.searcher import SearchTorrent
|
||||
|
||||
bangumi = await TitleParser.raw_parser(title)
|
||||
assert isinstance(bangumi, Bangumi)
|
||||
with patch(
|
||||
"module.searcher.provider.get_provider",
|
||||
return_value={"nyaa": {"url": "https://nyaa.si/?q=%s", "parser": "tmdb"}},
|
||||
):
|
||||
result = SearchTorrent.special_url(bangumi, "nyaa")
|
||||
|
||||
assert result.url == f"https://nyaa.si/?q={keyword}"
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("season_raw", "keyword"),
|
||||
[
|
||||
("S03E02", "S03"),
|
||||
("Season 3 Episode 2", "Season+3"),
|
||||
("S03E01-E03", "S03"),
|
||||
("Season 2 EPs 01-12", "Season+2"),
|
||||
],
|
||||
)
|
||||
def test_legacy_season_raw_drops_episode(self, season_raw, keyword):
|
||||
"""旧版本存进数据库的季集合写 season_raw,生成关键词时只保留季(#1138)。"""
|
||||
from module.searcher.searcher import SearchTorrent
|
||||
from test.factories import make_bangumi
|
||||
|
||||
bangumi = make_bangumi(
|
||||
group_name=None,
|
||||
title_raw="Test",
|
||||
season_raw=season_raw,
|
||||
dpi=None,
|
||||
source=None,
|
||||
subtitle=None,
|
||||
)
|
||||
with patch(
|
||||
"module.searcher.provider.get_provider",
|
||||
return_value={"nyaa": {"url": "https://nyaa.si/?q=%s", "parser": "tmdb"}},
|
||||
):
|
||||
result = SearchTorrent.special_url(bangumi, "nyaa")
|
||||
|
||||
assert result.url == f"https://nyaa.si/?q=Test+{keyword}"
|
||||
|
||||
def test_supports_movie_without_season_fields(self):
|
||||
"""Movie search results do not expose Bangumi-only season fields."""
|
||||
from module.searcher.searcher import SearchTorrent
|
||||
|
||||
@@ -344,6 +344,42 @@ async def test_tmdb_parser_negative_result_is_cached_until_ttl_expires(mocker):
|
||||
assert len(requests) == 2 * first
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("status", "refetched"),
|
||||
[
|
||||
("Ended", False),
|
||||
("Canceled", False),
|
||||
("Returning Series", True),
|
||||
("In Production", True),
|
||||
("Planned", True),
|
||||
("Pilot", True),
|
||||
(None, True),
|
||||
],
|
||||
)
|
||||
async def test_tmdb_parser_airing_show_cache_expires(mocker, status, refetched):
|
||||
"""未完结剧集的集数会变,缓存过期后重新查询;已完结/已取消的永久缓存(#1072)。"""
|
||||
requests: list[str] = []
|
||||
|
||||
async def fake_get_json(url: str) -> dict:
|
||||
requests.append(url)
|
||||
if "/search/tv" in url or "/season/" in url:
|
||||
return await _fake_get_json(url)
|
||||
return {**_SHOW_INFO, "status": status}
|
||||
|
||||
mocker.patch.object(
|
||||
tmdb_parser_module.RequestContent, "get_json", side_effect=fake_get_json
|
||||
)
|
||||
now = mocker.patch.object(tmdb_parser_module.time, "monotonic", return_value=0.0)
|
||||
tmdb_parser_module._tmdb_cache.clear()
|
||||
|
||||
await tmdb_parser("海盗战记", "zh", test=True)
|
||||
first = len(requests)
|
||||
now.return_value = tmdb_parser_module._TMDB_AIRING_TTL + 1
|
||||
await tmdb_parser("海盗战记", "zh", test=True)
|
||||
|
||||
assert len(requests) == (2 * first if refetched else first)
|
||||
|
||||
|
||||
async def test_tmdb_parser_cache_hit_refreshes_lru_order(mocker):
|
||||
"""命中的条目移到队尾,满员淘汰的是最久未用而非最早写入的条目。"""
|
||||
mocker.patch.object(tmdb_parser_module, "_TMDB_CACHE_MAX", 2)
|
||||
|
||||
2
backend/uv.lock
generated
2
backend/uv.lock
generated
@@ -139,7 +139,7 @@ wheels = [
|
||||
|
||||
[[package]]
|
||||
name = "auto-bangumi"
|
||||
version = "4.0.0b4"
|
||||
version = "4.0.0b5"
|
||||
source = { virtual = "." }
|
||||
dependencies = [
|
||||
{ name = "anthropic" },
|
||||
|
||||
@@ -126,7 +126,7 @@ const infoTags = computed(() => {
|
||||
});
|
||||
|
||||
// Copy RSS link
|
||||
const { copy, copied } = useClipboard({ copiedDuring: 2000 });
|
||||
const { copy, copied } = useClipboard({ copiedDuring: 2000, legacy: true });
|
||||
|
||||
async function copyRssLink() {
|
||||
const rssLink = localBangumi.value.rss_link?.[0] || '';
|
||||
|
||||
@@ -17,6 +17,7 @@ import { useAccessStore } from '@/store/access';
|
||||
import { useMessage } from '@/hooks/useMessage';
|
||||
import { useMyI18n } from '@/hooks/useMyI18n';
|
||||
import { useConfirm } from '@/hooks/useConfirm';
|
||||
import { copyText } from '@/utils/clipboard';
|
||||
|
||||
const store = useAccessStore();
|
||||
const { users, tokens, loading } = storeToRefs(store);
|
||||
@@ -137,9 +138,13 @@ async function handleCreateToken(): Promise<void> {
|
||||
}
|
||||
}
|
||||
|
||||
// 令牌只显示一次:复制失败时如实提示,令牌保持显示供手动复制
|
||||
async function copyIssuedToken(): Promise<void> {
|
||||
await navigator.clipboard.writeText(issuedToken.value);
|
||||
message.success(t('access.token_copied'));
|
||||
if (await copyText(issuedToken.value)) {
|
||||
message.success(t('access.token_copied'));
|
||||
} else {
|
||||
message.error(t('access.token_copy_failed'));
|
||||
}
|
||||
}
|
||||
|
||||
async function revokeToken(tokenId: number): Promise<void> {
|
||||
|
||||
@@ -1,4 +1,18 @@
|
||||
<script lang="ts" setup>
|
||||
import {
|
||||
Bell,
|
||||
BellRing,
|
||||
Eye,
|
||||
EyeOff,
|
||||
LoaderCircle,
|
||||
Pencil,
|
||||
Play,
|
||||
Plus,
|
||||
Smartphone,
|
||||
Trash2,
|
||||
Webhook,
|
||||
} from '@lucide/vue';
|
||||
import type { Component } from 'vue';
|
||||
import { NSelect } from 'naive-ui';
|
||||
import { useConfirm } from '@/hooks/useConfirm';
|
||||
import type { NotificationProviderConfig, NotificationType } from '#/config';
|
||||
@@ -174,19 +188,19 @@ function getProviderLabel(type: string): string {
|
||||
return providerTypes.value.find((p) => p.value === type)?.label || type;
|
||||
}
|
||||
|
||||
function getProviderIcon(type: string): string {
|
||||
const icons: Record<string, string> = {
|
||||
telegram: 'i-simple-icons-telegram',
|
||||
discord: 'i-simple-icons-discord',
|
||||
bark: 'i-carbon-notification',
|
||||
'server-chan': 'i-simple-icons-wechat',
|
||||
wecom: 'i-simple-icons-wechat',
|
||||
gotify: 'i-carbon-notification-filled',
|
||||
pushover: 'i-carbon-mobile',
|
||||
webhook: 'i-carbon-webhook',
|
||||
};
|
||||
return icons[type] || 'i-carbon-notification';
|
||||
}
|
||||
// 品牌图标走 simple-icons,其余类型用 Lucide,未知(插件)类型回落到 Bell
|
||||
const brandIcons: Record<string, string> = {
|
||||
telegram: 'i-simple-icons-telegram',
|
||||
discord: 'i-simple-icons-discord',
|
||||
'server-chan': 'i-simple-icons-wechat',
|
||||
wecom: 'i-simple-icons-wechat',
|
||||
};
|
||||
const lucideIcons: Record<string, Component> = {
|
||||
bark: Bell,
|
||||
gotify: BellRing,
|
||||
pushover: Smartphone,
|
||||
webhook: Webhook,
|
||||
};
|
||||
|
||||
function openAddDialog() {
|
||||
newProvider.value = {
|
||||
@@ -319,7 +333,8 @@ function getFieldsForType(type: string) {
|
||||
>
|
||||
<div class="provider-info">
|
||||
<div class="provider-name">
|
||||
<div :class="getProviderIcon(provider.type)" />
|
||||
<div v-if="brandIcons[provider.type]" :class="brandIcons[provider.type]" />
|
||||
<component :is="lucideIcons[provider.type] ?? Bell" v-else :size="16" />
|
||||
{{ getProviderLabel(provider.type) }}
|
||||
<span v-if="!provider.enabled" class="disabled-badge">
|
||||
{{ $t('config.notification_set.disabled') }}
|
||||
@@ -333,18 +348,15 @@ function getFieldsForType(type: string) {
|
||||
:label="$t('config.notification_set.test')"
|
||||
@click="testProvider(index)"
|
||||
>
|
||||
<div
|
||||
v-if="testingIndex === index"
|
||||
class="i-carbon-circle-dash animate-spin"
|
||||
/>
|
||||
<div v-else class="i-carbon-play" />
|
||||
<LoaderCircle v-if="testingIndex === index" :size="16" class="animate-spin" />
|
||||
<Play v-else :size="16" />
|
||||
</ab-icon-button>
|
||||
<ab-icon-button
|
||||
size="sm"
|
||||
:label="$t('config.notification_set.edit')"
|
||||
@click="openEditDialog(index)"
|
||||
>
|
||||
<div class="i-carbon-edit" />
|
||||
<Pencil :size="16" />
|
||||
</ab-icon-button>
|
||||
<ab-icon-button
|
||||
size="sm"
|
||||
@@ -355,11 +367,7 @@ function getFieldsForType(type: string) {
|
||||
"
|
||||
@click="toggleProvider(index)"
|
||||
>
|
||||
<div
|
||||
:class="
|
||||
provider.enabled ? 'i-carbon-view' : 'i-carbon-view-off'
|
||||
"
|
||||
/>
|
||||
<component :is="provider.enabled ? Eye : EyeOff" :size="16" />
|
||||
</ab-icon-button>
|
||||
<ab-icon-button
|
||||
size="sm"
|
||||
@@ -367,7 +375,7 @@ function getFieldsForType(type: string) {
|
||||
:label="$t('config.notification_set.remove')"
|
||||
@click="onRemoveProvider(index)"
|
||||
>
|
||||
<div class="i-carbon-trash-can" />
|
||||
<Trash2 :size="16" />
|
||||
</ab-icon-button>
|
||||
</div>
|
||||
</div>
|
||||
@@ -386,7 +394,7 @@ function getFieldsForType(type: string) {
|
||||
<!-- Add provider button -->
|
||||
<div class="flex justify-end">
|
||||
<ab-button size="sm" variant="primary" @click="openAddDialog">
|
||||
<div class="i-carbon-add" />
|
||||
<Plus :size="16" />
|
||||
{{ $t('config.notification_set.add_provider') }}
|
||||
</ab-button>
|
||||
</div>
|
||||
@@ -455,11 +463,8 @@ function getFieldsForType(type: string) {
|
||||
:disabled="testingIndex === -999"
|
||||
@click="testNewProvider"
|
||||
>
|
||||
<div
|
||||
v-if="testingIndex === -999"
|
||||
class="i-carbon-circle-dash animate-spin"
|
||||
/>
|
||||
<div v-else class="i-carbon-play" />
|
||||
<LoaderCircle v-if="testingIndex === -999" :size="16" class="animate-spin" />
|
||||
<Play v-else :size="16" />
|
||||
{{ $t('config.notification_set.test') }}
|
||||
</ab-button>
|
||||
<ab-button size="sm" @click="showAddDialog = false">
|
||||
@@ -534,11 +539,8 @@ function getFieldsForType(type: string) {
|
||||
:disabled="testingIndex === -999"
|
||||
@click="testNewProvider"
|
||||
>
|
||||
<div
|
||||
v-if="testingIndex === -999"
|
||||
class="i-carbon-circle-dash animate-spin"
|
||||
/>
|
||||
<div v-else class="i-carbon-play" />
|
||||
<LoaderCircle v-if="testingIndex === -999" :size="16" class="animate-spin" />
|
||||
<Play v-else :size="16" />
|
||||
{{ $t('config.notification_set.test') }}
|
||||
</ab-button>
|
||||
<ab-button size="sm" @click="showEditDialog = false">
|
||||
|
||||
@@ -744,6 +744,7 @@
|
||||
"token_once": "Copy this token now. It cannot be shown again.",
|
||||
"one_time_token": "One-time token",
|
||||
"token_copied": "Token copied",
|
||||
"token_copy_failed": "Copy failed. Select the token and copy it manually.",
|
||||
"copy": "Copy",
|
||||
"revoke": "Revoke",
|
||||
"revoke_token_confirm": "Revoke this token?",
|
||||
|
||||
@@ -744,6 +744,7 @@
|
||||
"token_once": "请立即复制此令牌,之后无法再次显示。",
|
||||
"one_time_token": "一次性令牌",
|
||||
"token_copied": "令牌已复制",
|
||||
"token_copy_failed": "复制失败,请手动选中令牌复制",
|
||||
"copy": "复制",
|
||||
"revoke": "撤销",
|
||||
"revoke_token_confirm": "确认撤销此令牌?",
|
||||
|
||||
@@ -20,6 +20,7 @@ import ConfigAccess from '@/components/setting/config-access.vue';
|
||||
import UpdateCard from '@/components/setting/update-card.vue';
|
||||
import ConfigPlugins from '@/components/setting/config-plugins.vue';
|
||||
import { configSectionMatches } from '@/utils/config-search';
|
||||
import { isAtBottom, pickActiveSection } from '@/utils/scroll-spy';
|
||||
|
||||
definePage({
|
||||
name: 'Config',
|
||||
@@ -271,21 +272,41 @@ function setSectionEl(id: string, el: unknown) {
|
||||
else sectionEls.delete(id);
|
||||
}
|
||||
|
||||
// 程序化平滑滚动期间暂停 scroll-spy,避免高亮在途经的分区间跳动
|
||||
let isProgrammaticScroll = false;
|
||||
let scrollTimer: ReturnType<typeof setTimeout> | null = null;
|
||||
|
||||
function endProgrammaticScroll() {
|
||||
isProgrammaticScroll = false;
|
||||
if (scrollTimer) clearTimeout(scrollTimer);
|
||||
scrollTimer = null;
|
||||
}
|
||||
|
||||
function onScroll() {
|
||||
const container = scrollEl.value;
|
||||
if (!container) return;
|
||||
const anchor = container.scrollTop + 80;
|
||||
let current = visibleSections.value[0]?.id ?? baseSections[0].id;
|
||||
for (const section of visibleSections.value) {
|
||||
const el = sectionEls.get(section.id);
|
||||
if (el && el.offsetTop <= anchor) current = section.id;
|
||||
}
|
||||
activeSection.value = current;
|
||||
if (!container || isProgrammaticScroll) return;
|
||||
const containerTop = container.getBoundingClientRect().top;
|
||||
const tops = visibleSections.value.flatMap(({ id }) => {
|
||||
const el = sectionEls.get(id);
|
||||
return el ? [{ id, top: el.getBoundingClientRect().top - containerTop }] : [];
|
||||
});
|
||||
activeSection.value =
|
||||
pickActiveSection(tops, isAtBottom(container)) ??
|
||||
visibleSections.value[0]?.id ??
|
||||
baseSections[0].id;
|
||||
}
|
||||
|
||||
function jumpTo(id: string) {
|
||||
const el = sectionEls.get(id);
|
||||
if (!el) return;
|
||||
activeSection.value = id;
|
||||
isProgrammaticScroll = true;
|
||||
// scrollend 不可用(Safari)或未触发时,由定时器兜底解除
|
||||
if (scrollTimer) clearTimeout(scrollTimer);
|
||||
scrollTimer = setTimeout(endProgrammaticScroll, 600);
|
||||
scrollEl.value?.addEventListener('scrollend', endProgrammaticScroll, {
|
||||
once: true,
|
||||
});
|
||||
const reduceMotion = window.matchMedia(
|
||||
'(prefers-reduced-motion: reduce)'
|
||||
).matches;
|
||||
@@ -293,7 +314,6 @@ function jumpTo(id: string) {
|
||||
behavior: reduceMotion ? 'auto' : 'smooth',
|
||||
block: 'start',
|
||||
});
|
||||
activeSection.value = id;
|
||||
}
|
||||
|
||||
// --- 保存 / 放弃 ---
|
||||
@@ -370,7 +390,14 @@ onBeforeRouteLeave(() => {
|
||||
</button>
|
||||
</nav>
|
||||
|
||||
<div ref="scrollEl" class="config-scroll" @scroll.passive="onScroll">
|
||||
<div
|
||||
ref="scrollEl"
|
||||
class="config-scroll"
|
||||
@scroll.passive="onScroll"
|
||||
@wheel.passive="endProgrammaticScroll"
|
||||
@touchmove.passive="endProgrammaticScroll"
|
||||
@pointerdown.passive="endProgrammaticScroll"
|
||||
>
|
||||
<div v-if="visibleSections.length === 0" class="config-no-match">
|
||||
<p>{{ $t('config.no_match') }}</p>
|
||||
<ab-button size="sm" @click="searchQuery = ''">
|
||||
@@ -496,6 +523,7 @@ onBeforeRouteLeave(() => {
|
||||
}
|
||||
|
||||
.config-scroll {
|
||||
position: relative;
|
||||
flex: 1;
|
||||
min-width: 0;
|
||||
overflow-y: auto;
|
||||
|
||||
@@ -1,4 +1,5 @@
|
||||
<script lang="ts" setup>
|
||||
import { RefreshCw } from '@lucide/vue';
|
||||
import { type DataTableColumns, NDataTable, NTooltip } from 'naive-ui';
|
||||
import AbButton from '@/components/basic/ab-button.vue';
|
||||
import AbTag from '@/components/basic/ab-tag.vue';
|
||||
@@ -119,10 +120,9 @@ const rssColumns = computed<DataTableColumns<RSS>>(() => [
|
||||
onClick: () => onRefreshOne(rss.id),
|
||||
},
|
||||
() =>
|
||||
h('div', {
|
||||
class: isRowRefreshing
|
||||
? 'i-carbon-renew animate-spin'
|
||||
: 'i-carbon-renew',
|
||||
h(RefreshCw, {
|
||||
size: 14,
|
||||
class: isRowRefreshing ? 'animate-spin' : undefined,
|
||||
})
|
||||
);
|
||||
},
|
||||
@@ -147,13 +147,7 @@ function onSelectedRSSUpdate(keys: unknown[]) {
|
||||
@click="refreshAllRSS"
|
||||
>
|
||||
<template #icon>
|
||||
<div
|
||||
:class="
|
||||
isRefreshingAll
|
||||
? 'i-carbon-renew animate-spin'
|
||||
: 'i-carbon-renew'
|
||||
"
|
||||
/>
|
||||
<RefreshCw :size="14" :class="{ 'animate-spin': isRefreshingAll }" />
|
||||
</template>
|
||||
{{ $t('rss.refresh_all') }}
|
||||
</AbButton>
|
||||
@@ -214,13 +208,7 @@ function onSelectedRSSUpdate(keys: unknown[]) {
|
||||
:disabled="refreshingId === item.id"
|
||||
@click="onRefreshOne(item.id)"
|
||||
>
|
||||
<div
|
||||
:class="
|
||||
refreshingId === item.id
|
||||
? 'i-carbon-renew animate-spin'
|
||||
: 'i-carbon-renew'
|
||||
"
|
||||
/>
|
||||
<RefreshCw :size="14" :class="{ 'animate-spin': refreshingId === item.id }" />
|
||||
{{ $t('rss.refresh') }}
|
||||
</AbButton>
|
||||
</div>
|
||||
|
||||
43
webui/src/utils/__tests__/clipboard.test.ts
Normal file
43
webui/src/utils/__tests__/clipboard.test.ts
Normal file
@@ -0,0 +1,43 @@
|
||||
import { afterEach, describe, expect, it, vi } from 'vitest';
|
||||
import { copyText } from '../clipboard';
|
||||
|
||||
function setSecureContext(secure: boolean) {
|
||||
Object.defineProperty(window, 'isSecureContext', {
|
||||
value: secure,
|
||||
configurable: true,
|
||||
});
|
||||
}
|
||||
|
||||
describe('copyText', () => {
|
||||
afterEach(() => {
|
||||
vi.restoreAllMocks();
|
||||
});
|
||||
|
||||
it('should use navigator.clipboard when the context is secure', async () => {
|
||||
setSecureContext(true);
|
||||
const writeText = vi.fn().mockResolvedValue(undefined);
|
||||
Object.defineProperty(navigator, 'clipboard', {
|
||||
value: { writeText },
|
||||
configurable: true,
|
||||
});
|
||||
|
||||
expect(await copyText('token')).toBe(true);
|
||||
expect(writeText).toHaveBeenCalledWith('token');
|
||||
});
|
||||
|
||||
it.each([true, false])(
|
||||
'should return the execCommand result %s when the context is not secure',
|
||||
async (result) => {
|
||||
setSecureContext(false);
|
||||
const execCommand = vi.fn().mockReturnValue(result);
|
||||
Object.defineProperty(document, 'execCommand', {
|
||||
value: execCommand,
|
||||
configurable: true,
|
||||
});
|
||||
|
||||
expect(await copyText('token')).toBe(result);
|
||||
expect(execCommand).toHaveBeenCalledWith('copy');
|
||||
expect(document.querySelector('textarea')).toBeNull();
|
||||
}
|
||||
);
|
||||
});
|
||||
48
webui/src/utils/__tests__/scroll-spy.test.ts
Normal file
48
webui/src/utils/__tests__/scroll-spy.test.ts
Normal file
@@ -0,0 +1,48 @@
|
||||
import { describe, expect, it } from 'vitest';
|
||||
import { isAtBottom, pickActiveSection } from '../scroll-spy';
|
||||
|
||||
const tops = [
|
||||
{ id: 'a', top: -300 },
|
||||
{ id: 'b', top: 40 },
|
||||
{ id: 'c', top: 500 },
|
||||
];
|
||||
|
||||
describe('pickActiveSection', () => {
|
||||
it('should return the last section crossing the anchor when not at bottom', () => {
|
||||
expect(pickActiveSection(tops, false)).toBe('b');
|
||||
});
|
||||
|
||||
it('should return the first section when none crossed the anchor', () => {
|
||||
expect(pickActiveSection([{ id: 'a', top: 200 }], false)).toBe('a');
|
||||
});
|
||||
|
||||
it('should return the last section when scrolled to the bottom', () => {
|
||||
expect(pickActiveSection(tops, true)).toBe('c');
|
||||
});
|
||||
|
||||
it('should return undefined when there are no sections', () => {
|
||||
expect(pickActiveSection([], true)).toBeUndefined();
|
||||
});
|
||||
});
|
||||
|
||||
describe('isAtBottom', () => {
|
||||
it.each([
|
||||
{
|
||||
when: 'the container cannot scroll',
|
||||
el: { scrollTop: 0, scrollHeight: 500, clientHeight: 500 },
|
||||
expected: false,
|
||||
},
|
||||
{
|
||||
when: 'a scrollable container is at the bottom',
|
||||
el: { scrollTop: 495, scrollHeight: 1000, clientHeight: 500 },
|
||||
expected: true,
|
||||
},
|
||||
{
|
||||
when: 'a scrollable container is above the bottom',
|
||||
el: { scrollTop: 100, scrollHeight: 1000, clientHeight: 500 },
|
||||
expected: false,
|
||||
},
|
||||
])('should return $expected when $when', ({ el, expected }) => {
|
||||
expect(isAtBottom(el)).toBe(expected);
|
||||
});
|
||||
});
|
||||
28
webui/src/utils/clipboard.ts
Normal file
28
webui/src/utils/clipboard.ts
Normal file
@@ -0,0 +1,28 @@
|
||||
/**
|
||||
* 复制文本,返回是否真的复制成功。非安全上下文(HTTP)下没有
|
||||
* navigator.clipboard,回落到 textarea + execCommand('copy') 并采用其返回值。
|
||||
*/
|
||||
export async function copyText(text: string): Promise<boolean> {
|
||||
if (window.isSecureContext && navigator.clipboard) {
|
||||
try {
|
||||
await navigator.clipboard.writeText(text);
|
||||
return true;
|
||||
} catch {
|
||||
return false;
|
||||
}
|
||||
}
|
||||
const textarea = document.createElement('textarea');
|
||||
textarea.value = text;
|
||||
textarea.setAttribute('readonly', '');
|
||||
textarea.style.position = 'fixed';
|
||||
textarea.style.opacity = '0';
|
||||
document.body.appendChild(textarea);
|
||||
textarea.select();
|
||||
try {
|
||||
return document.execCommand('copy');
|
||||
} catch {
|
||||
return false;
|
||||
} finally {
|
||||
textarea.remove();
|
||||
}
|
||||
}
|
||||
42
webui/src/utils/scroll-spy.ts
Normal file
42
webui/src/utils/scroll-spy.ts
Normal file
@@ -0,0 +1,42 @@
|
||||
export interface SectionTop {
|
||||
id: string;
|
||||
/** 分区上缘相对滚动容器上缘的距离(px) */
|
||||
top: number;
|
||||
}
|
||||
|
||||
/** 滚动到底部的容差(px) */
|
||||
const SCROLL_BOTTOM_EPSILON = 10;
|
||||
/** 分区上缘越过该锚线即视为当前分区(px) */
|
||||
export const SCROLL_ANCHOR_OFFSET = 80;
|
||||
|
||||
/**
|
||||
* 计算当前高亮分区:触底时取最后一个;否则取上缘已越过锚线的最后一个,
|
||||
* 都未越过则取第一个。列表为空返回 undefined。
|
||||
*/
|
||||
export function pickActiveSection(
|
||||
tops: SectionTop[],
|
||||
atBottom: boolean
|
||||
): string | undefined {
|
||||
if (tops.length === 0) return undefined;
|
||||
if (atBottom) return tops[tops.length - 1].id;
|
||||
let current = tops[0].id;
|
||||
for (const { id, top } of tops) {
|
||||
if (top <= SCROLL_ANCHOR_OFFSET) current = id;
|
||||
}
|
||||
return current;
|
||||
}
|
||||
|
||||
/**
|
||||
* 容器是否已滚动到底部。内容不足一屏、容器无法滚动时不算触底,
|
||||
* 否则最后一个分区会一直高亮。
|
||||
*/
|
||||
export function isAtBottom({
|
||||
scrollTop,
|
||||
scrollHeight,
|
||||
clientHeight,
|
||||
}: Pick<HTMLElement, 'scrollTop' | 'scrollHeight' | 'clientHeight'>): boolean {
|
||||
return (
|
||||
scrollHeight - clientHeight > SCROLL_BOTTOM_EPSILON &&
|
||||
scrollHeight - scrollTop - clientHeight <= SCROLL_BOTTOM_EPSILON
|
||||
);
|
||||
}
|
||||
8
webui/types/dts/auto-imports.d.ts
vendored
8
webui/types/dts/auto-imports.d.ts
vendored
@@ -11,6 +11,8 @@ declare global {
|
||||
const EffectScope: typeof import('vue').EffectScope
|
||||
const MARKET_CATEGORIES: typeof import('../../src/utils/plugin-market').MARKET_CATEGORIES
|
||||
const MARKET_STATES: typeof import('../../src/utils/plugin-market').MARKET_STATES
|
||||
const SCROLL_ANCHOR_OFFSET: typeof import('../../src/utils/scroll-spy').SCROLL_ANCHOR_OFFSET
|
||||
const SCROLL_BOTTOM_EPSILON: typeof import('../../src/utils/scroll-spy').SCROLL_BOTTOM_EPSILON
|
||||
const acceptHMRUpdate: typeof import('pinia').acceptHMRUpdate
|
||||
const apiAuth: typeof import('../../src/api/auth').apiAuth
|
||||
const apiBangumi: typeof import('../../src/api/bangumi').apiBangumi
|
||||
@@ -36,6 +38,7 @@ declare global {
|
||||
const categoryCounts: typeof import('../../src/utils/plugin-market').categoryCounts
|
||||
const computed: typeof import('vue').computed
|
||||
const configSectionMatches: typeof import('../../src/utils/config-search').configSectionMatches
|
||||
const copyText: typeof import('../../src/utils/clipboard').copyText
|
||||
const countLogLevels: typeof import('../../src/utils/log-parse').countLogLevels
|
||||
const createApp: typeof import('vue').createApp
|
||||
const createPinia: typeof import('pinia').createPinia
|
||||
@@ -61,6 +64,7 @@ declare global {
|
||||
const i18n: typeof import('../../src/hooks/useMyI18n').i18n
|
||||
const idLabel: typeof import('../../src/utils/id-label').idLabel
|
||||
const inject: typeof import('vue').inject
|
||||
const isAtBottom: typeof import('../../src/utils/scroll-spy').isAtBottom
|
||||
const isProxy: typeof import('vue').isProxy
|
||||
const isReactive: typeof import('vue').isReactive
|
||||
const isReadonly: typeof import('vue').isReadonly
|
||||
@@ -96,6 +100,7 @@ declare global {
|
||||
const onWatcherCleanup: typeof import('vue').onWatcherCleanup
|
||||
const parseLogLines: typeof import('../../src/utils/log-parse').parseLogLines
|
||||
const permissionDiff: typeof import('../../src/utils/plugin-market').permissionDiff
|
||||
const pickActiveSection: typeof import('../../src/utils/scroll-spy').pickActiveSection
|
||||
const pluginDescription: typeof import('../../src/utils/plugin-text').pluginDescription
|
||||
const pluginName: typeof import('../../src/utils/plugin-text').pluginName
|
||||
const pluginReason: typeof import('../../src/utils/plugin-text').pluginReason
|
||||
@@ -224,4 +229,7 @@ declare global {
|
||||
// @ts-ignore
|
||||
export type { SchemaFieldKind, SchemaField } from '../../src/utils/plugin-schema'
|
||||
import('../../src/utils/plugin-schema')
|
||||
// @ts-ignore
|
||||
export type { SectionTop } from '../../src/utils/scroll-spy'
|
||||
import('../../src/utils/scroll-spy')
|
||||
}
|
||||
|
||||
Reference in New Issue
Block a user