mirror of
https://github.com/EstrellaXD/Auto_Bangumi.git
synced 2026-11-06 07:29:09 +08:00
 Estrella Pan
@@ -33,6 +33,8 @@ config/bangumi.json/config/bangumi.json
|
||||
dist.zip
|
||||
data
|
||||
config
|
||||
/src/config
|
||||
/src/data
|
||||
.pytest_cache
|
||||
test
|
||||
.env
|
||||
|
||||
22
.github/workflows/dev-latest.yml
vendored
22
.github/workflows/dev-latest.yml
vendored
@@ -24,6 +24,7 @@ jobs:
|
||||
- name: Test
|
||||
working-directory: ./src
|
||||
run: |
|
||||
mkdir -p config
|
||||
pytest
|
||||
|
||||
dev-latest:
|
||||
@@ -43,6 +44,17 @@ jobs:
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v2
|
||||
|
||||
- name: Docker metadata
|
||||
id: meta
|
||||
uses: docker/metadata-action@v4
|
||||
with:
|
||||
images: |
|
||||
estrellaxd/auto_bangumi
|
||||
ghcr.io/${{ github.repository }}
|
||||
tags: |
|
||||
type=raw,value=${{ github.ref_name }}
|
||||
type=raw,value=dev-latest
|
||||
|
||||
- name: Login to Docker Hub
|
||||
uses: docker/login-action@v2
|
||||
with:
|
||||
@@ -53,7 +65,7 @@ jobs:
|
||||
uses: docker/login-action@v2
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GITHUB_USERNAME }}
|
||||
username: ${{ github.actor }}
|
||||
password: ${{ secrets.ACCESS_TOKEN }}
|
||||
|
||||
- name: Build and push
|
||||
@@ -61,11 +73,7 @@ jobs:
|
||||
with:
|
||||
context: .
|
||||
push: true
|
||||
tags: |
|
||||
estrellaxd/auto_bangumi:dev-latest
|
||||
estrellaxd/auto_bangumi:${{ github.ref_name }}
|
||||
ghcr.io/estrellaxd/auto_bangumi:dev-latest
|
||||
ghcr.io/estrellaxd/auto_bangumi:${{ github.ref_name }}
|
||||
tags: ${{ steps.meta.outputs.tags }}
|
||||
file: Dockerfile
|
||||
|
||||
generate_release:
|
||||
@@ -73,7 +81,7 @@ jobs:
|
||||
needs: [test]
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v2
|
||||
uses: actions/checkout@v3
|
||||
- name: Generate Release
|
||||
uses: softprops/action-gh-release@v1
|
||||
with:
|
||||
|
||||
8
.github/workflows/docker.yml
vendored
8
.github/workflows/docker.yml
vendored
@@ -23,6 +23,7 @@ jobs:
|
||||
- name: Test
|
||||
working-directory: ./src
|
||||
run: |
|
||||
mkdir -p config
|
||||
pytest
|
||||
|
||||
|
||||
@@ -50,6 +51,7 @@ jobs:
|
||||
with:
|
||||
images: |
|
||||
estrellaxd/auto_bangumi
|
||||
ghcr.io/${{ github.repository }}
|
||||
tags: |
|
||||
type=semver,pattern={{version}}
|
||||
type=raw,value=latest
|
||||
@@ -74,11 +76,9 @@ jobs:
|
||||
with:
|
||||
context: .
|
||||
builder: ${{ steps.buildx.output.name }}
|
||||
platforms: linux/amd64,linux/arm64,linux/arm
|
||||
platforms: linux/amd64,linux/arm64,linux/arm/v7
|
||||
push: ${{ github.event_name == 'push' }}
|
||||
tags: |
|
||||
docker.io/estrellaxd/auto_bangumi:${{ steps.meta.outputs.tags }}
|
||||
ghcr.io/estrellaxd/auto_bangumi:${{ steps.meta.outputs.tags }}
|
||||
tags: ${{ steps.meta.outputs.tags }}
|
||||
labels: ${{ steps.meta.outputs.labels }}
|
||||
cache-from: type=gha, scope=${{ github.workflow }}
|
||||
cache-to: type=gha, scope=${{ github.workflow }}
|
||||
|
||||
32
.github/workflows/pull-request.yml
vendored
Normal file
32
.github/workflows/pull-request.yml
vendored
Normal file
@@ -0,0 +1,32 @@
|
||||
name: Create Pull Request
|
||||
|
||||
on:
|
||||
push:
|
||||
tags:
|
||||
- '\d+\.\d+\.\d+'
|
||||
- '\d+\.\d+'
|
||||
|
||||
jobs:
|
||||
create-pull-request:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v2
|
||||
- name: Generate pull request body
|
||||
id: pr
|
||||
run: |
|
||||
echo "docs/changelog/${{ github.ref }}.md"
|
||||
- name: Create Pull Request
|
||||
uses: peter-evans/create-pull-request@v3
|
||||
with:
|
||||
token: ${{ secrets.ACCESS_TOKEN }}
|
||||
commit-message: 'chore: release ${{ github.ref }}'
|
||||
title: 'chore: release ${{ github.ref }}'
|
||||
body: |
|
||||
${{ steps.pr.outputs.body }}
|
||||
branch: release/${{ github.ref }}
|
||||
base: main
|
||||
labels: release
|
||||
draft: false
|
||||
branch-suffix: timestamp
|
||||
delete-branch: false
|
||||
15
Dockerfile
15
Dockerfile
@@ -1,6 +1,6 @@
|
||||
# syntax=docker/dockerfile:1
|
||||
|
||||
FROM python:3.11-alpine AS APP
|
||||
FROM alpine:3.18 AS APP
|
||||
|
||||
ENV S6_SERVICES_GRACETIME=30000 \
|
||||
S6_KILL_GRACETIME=60000 \
|
||||
@@ -18,12 +18,21 @@ WORKDIR /app
|
||||
|
||||
COPY requirements.txt .
|
||||
RUN apk add --no-cache \
|
||||
bash \
|
||||
ca-certificates \
|
||||
coreutils \
|
||||
curl \
|
||||
jq \
|
||||
shadow \
|
||||
netcat-openbsd \
|
||||
procps-ng \
|
||||
python3 \
|
||||
py3-bcrypt \
|
||||
py3-pip \
|
||||
s6-overlay \
|
||||
bash && \
|
||||
shadow \
|
||||
tzdata && \
|
||||
python3 -m pip install --upgrade pip && \
|
||||
sed -i '/bcrypt/d' requirements.txt && \
|
||||
pip install --no-cache-dir -r requirements.txt && \
|
||||
# Download WebUI
|
||||
curl -sL "https://github.com/Rewrite0/Auto_Bangumi_WebUI/releases/latest/download/dist.zip" | busybox unzip -q -d /app - && \
|
||||
|
||||
30
README.md
30
README.md
@@ -1,39 +1,32 @@
|
||||
<p align="center">
|
||||
<img src="https://github.com/EstrellaXD/Auto_Bangumi/blob/main/docs/image/auto_bangumi_v2.png#gh-light-mode-only" width=50%/ alt="">
|
||||
<img src="https://github.com/EstrellaXD/Auto_Bangumi/blob/main/docs/image/auto_bangumi_icon_v2-dark.png#gh-dark-mode-only" width=50%/ alt="">
|
||||
<img src="docs/image/light-icon.png#gh-light-mode-only" width=50%/ alt="">
|
||||
<img src="docs/image/dark-icon.png#gh-dark-mode-only" width=50%/ alt="">
|
||||
</p>
|
||||
<p align="center">
|
||||
<img title="docker build version" src="https://img.shields.io/docker/v/estrellaxd/auto_bangumi" alt="">
|
||||
<img title="release date" src="https://img.shields.io/github/release-date/estrellaxd/auto_bangumi" alt="">
|
||||
<img title="docker pull" src="https://img.shields.io/docker/pulls/estrellaxd/auto_bangumi" alt="">
|
||||
<img title="python version" src="https://img.shields.io/badge/python-3.11-blue" alt="">
|
||||
<img title="telegram" src="https://img.shields.io/badge/telegram-autobangumi_update-blue" herf="https://t.me/autobangumi_update" alt="">
|
||||
</p>
|
||||
|
||||
|
||||
# 项目说明
|
||||
|
||||
<p align="center">
|
||||
<img title="mikan project" src="https://mikanani.me/images/mikan-pic.png" alt="" width="10%">
|
||||
<img title="qbittorrent" src="https://upload.wikimedia.org/wikipedia/commons/thumb/6/66/New_qBittorrent_Logo.svg/600px-New_qBittorrent_Logo.svg.png" width="10%">
|
||||
<img title="AutoBangumi" src="docs/image/window.png" alt="" width=75%>
|
||||
</p>
|
||||
|
||||
本项目是基于 [Mikan Project](https://mikanani.me)、[qBittorrent](https://qbittorrent.org) 的全自动追番整理下载工具。只需要在 [Mikan Project](https://mikanani.me) 上订阅番剧,就可以全自动追番。并且整理完成的名称和目录可以直接被 [Plex]()、[Jellyfin]() 等媒体库软件识别,无需二次刮削。
|
||||
|
||||
基于 [infuse](https://firecore.com/infuse) 与 [Plex](https://plex.tv) 的效果如下:
|
||||
|
||||
<img title="plex" src="https://tva1.sinaimg.cn/large/e6c9d24ely1h47zd0v04zj21a50u0gvr.jpg" alt="" width=50%><img title="infuse" src="https://tva1.sinaimg.cn/large/e6c9d24ely1h47zd0gqz3j21a50u0dqc.jpg" alt="" width=50%>
|
||||
|
||||
[主项目地址](https://www.github.com/EstrellaXD/Auto_Bangumi)
|
||||
/ [WebUI 仓库](https://github.com/Rewrite0/Auto_Bangumi_WebUI)
|
||||
/ [WebUI 仓库](https://github.com/Rewrite0/Auto_Bangumi_WebUI)
|
||||
/ [Wiki 说明](https://www.github.com/EstrellaXD/Auto_Bangumi/wiki)
|
||||
|
||||
|
||||
## AutoBangumi 功能说明
|
||||
|
||||
- 简易单次配置就能持续使用
|
||||
- 无需介入的 `RSS` 解析器,解析番组信息并且自动生成下载规则。
|
||||
- 番剧文件整理:
|
||||
|
||||
```
|
||||
Bangumi
|
||||
├── bangumi_A_title
|
||||
@@ -50,12 +43,15 @@
|
||||
├── bangumi_B_title
|
||||
│ └─── Season 1
|
||||
```
|
||||
- 全自动重命名,重命名后 95% 以上的番剧可以直接被媒体库软件直接刮削
|
||||
|
||||
- 全自动重命名,重命名后 99% 以上的番剧可以直接被媒体库软件直接刮削
|
||||
|
||||
```
|
||||
[Lilith-Raws] Kakkou no Iinazuke - 07 [Baha][WEB-DL][1080p][AVC AAC][CHT][MP4].mp4
|
||||
>>
|
||||
Kakkou no Iinazuke S01E07.mp4
|
||||
```
|
||||
|
||||
- 自定义重命名,可以根据上级文件夹对所有子文件重命名。
|
||||
- 季中追番可以补全当季遗漏的所有剧集
|
||||
- 高度可自定义的功能选项,可以针对不同媒体库软件微调
|
||||
@@ -77,6 +73,7 @@
|
||||
## Roadmap
|
||||
|
||||
***开发中的功能:***
|
||||
|
||||
- Web UI #57 ✅
|
||||
- 文件统一整理,对单个规则或者文件微调文件夹可以自动调整所有对应的文件。
|
||||
- 通知功能,可以通过 IFTTT 等方式通知用户番剧更新进度。✅
|
||||
@@ -84,14 +81,16 @@
|
||||
- 各类 API 接口。
|
||||
|
||||
***计划开发的功能:***
|
||||
|
||||
- 对其他站点种子的解析归类。
|
||||
- 本地化番剧订阅方式。
|
||||
- Transmission & Aria2 的支持。
|
||||
- 更完善的 WebUI。
|
||||
|
||||
|
||||
# 声明
|
||||
|
||||
## 致谢
|
||||
|
||||
感谢 [Sean](https://github.com/findix) 提供的大量帮助
|
||||
感谢 [Rewrite0](https://github.com/Rewrite0) 开发的 WebUI
|
||||
|
||||
@@ -100,6 +99,5 @@
|
||||
[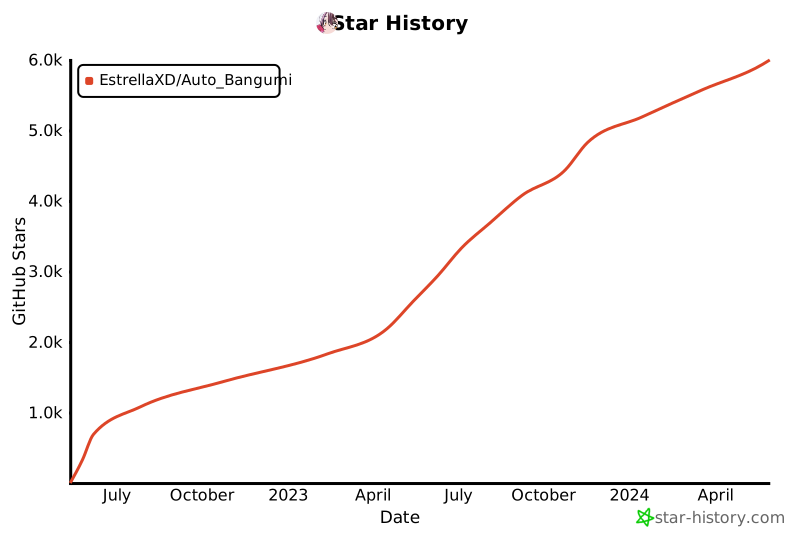](https://star-history.com/#EstrellaXD/Auto_Bangumi)
|
||||
|
||||
## Licence
|
||||
|
||||
[MIT licence](https://github.com/EstrellaXD/Auto_Bangumi/blob/main/LICENSE)
|
||||
|
||||
|
||||
|
||||
24
dev.sh
Normal file
24
dev.sh
Normal file
@@ -0,0 +1,24 @@
|
||||
#!/bin/bash
|
||||
|
||||
|
||||
# This script is used to run the development environment.
|
||||
|
||||
python3 -m pip install -i https://pypi.tuna.tsinghua.edu.cn/simple install -r requirements.txt
|
||||
|
||||
cd src || exit
|
||||
|
||||
CONFIG_DIR="config"
|
||||
|
||||
if [ ! -d "$CONFIG_DIR" ]; then
|
||||
echo "The directory '$CONFIG_DIR' is missing."
|
||||
mkdir config
|
||||
fi
|
||||
|
||||
VERSION_FILE="module/__version__.py"
|
||||
|
||||
if [ ! -f "$VERSION_FILE" ]; then
|
||||
echo "The file '$VERSION_FILE' is missing."
|
||||
echo "VERSION='DEV_VERSION'" >> "$VERSION_FILE"
|
||||
fi
|
||||
|
||||
python3 main.py
|
||||
46
docs/changelog/3.0.md
Normal file
46
docs/changelog/3.0.md
Normal file
@@ -0,0 +1,46 @@
|
||||
## New
|
||||
|
||||
### 全新的 WebUI
|
||||
|
||||
- 登陆功能,现在 AB 可以设定用户名和密码进行登陆。部分操作需要在登陆后才可以进行。
|
||||
- 全新的海报墙
|
||||
- 番剧管理功能
|
||||
- 可以对番剧的季度信息名称进行修改,修改完成之后会自动修改**自动下载规则**/**已经下载完成的文件路径**, 并重命名。
|
||||
- 全新的链接解析器,解析完成链接之后可以手动更改下载信息,选择下载季度或者增加自动下载规则。
|
||||
- 删除番剧,可以一键删除番剧以及其种子文件。
|
||||
- 可以对单独番剧自定义下载规则,此规则与全局规则不冲突。
|
||||
- 全新的配置界面,可以更方便的配置应用程序规则。
|
||||
- 新增初始化启动页面,在第一次启动 AB 时会引导填入相关配置。
|
||||
- 下载器链接检查器,可以检查与 qBittorrent 的连通性
|
||||
- RSS 地址检查器,可以检查 RSS 是否有效。
|
||||
- 新增程序管理按钮,可以在 WebUI 中启动停止程序。且可以重启容器。
|
||||
|
||||
### 解析器
|
||||
|
||||
- 全新的解析器,可以选择不同类型来源获取官方标题和海报地址。
|
||||
- 支持更换 RSS 订阅源而不用重新生成数据库。
|
||||
|
||||
### 通知模块
|
||||
|
||||
- 新增 `Bark` 通知模块.
|
||||
- 全新的通知方式,现在可以给 Telegram 推送海报,番剧名称,更新集数。
|
||||
|
||||
### 数据迁移
|
||||
|
||||
- 现在从旧版本升级可以自动迁移数据。
|
||||
- 从旧版本迁移的数据也可以自动匹配海报。
|
||||
|
||||
## Fix
|
||||
|
||||
- 针对 Windows 路径可能出现的重命名 Bug。
|
||||
|
||||
## Change
|
||||
|
||||
- 从 `json` 迁移至 `sqlite` 存储数据
|
||||
- 从多进程迁移至多线程
|
||||
- 重构主程序
|
||||
- 加速启动关闭时间
|
||||
- 重构解析器模块
|
||||
- 重构重命名模块
|
||||
- 暂时移除 `normal` 模式
|
||||
- 增加 `ghcr.io` 镜像
|
||||
@@ -28,8 +28,6 @@ services:
|
||||
- PGID=${GID}
|
||||
- PUID=${UID}
|
||||
- AB_DOWNLOADER_HOST=qbittorrent:${QB_PORT}
|
||||
- AB_RSS=${AB_RSS}
|
||||
- AB_DOWNLOAD_PATH=/downloads/Bangumi
|
||||
volumes:
|
||||
- ./config:/app/config
|
||||
- ./data:/app/data
|
||||
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 24 KiB |

Binary file not shown.
|
Before Width: | Height: | Size: 45 KiB |
BIN
docs/image/dark-icon.png
Normal file
BIN
docs/image/dark-icon.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 21 KiB |
BIN
docs/image/light-icon.png
Normal file
BIN
docs/image/light-icon.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 136 KiB |
BIN
docs/image/window.png
Normal file
BIN
docs/image/window.png
Normal file

Binary file not shown.
|
After Width: | Height: | Size: 791 KiB |
Submodule docs/wiki updated: 9dc9f4f4e3...df8c30d2c3
@@ -1,5 +1,5 @@
|
||||
anyio
|
||||
beautifulsoup4
|
||||
bs4
|
||||
certifi
|
||||
charset-normalizer
|
||||
click
|
||||
@@ -19,3 +19,7 @@ uvicorn
|
||||
attrdict
|
||||
jinja2
|
||||
python-dotenv
|
||||
python-jose
|
||||
passlib
|
||||
bcrypt
|
||||
python-multipart
|
||||
|
||||
115
src/main.py
115
src/main.py
@@ -1,102 +1,29 @@
|
||||
import os
|
||||
import signal
|
||||
import logging
|
||||
import uvicorn
|
||||
import multiprocessing
|
||||
|
||||
from fastapi import Request
|
||||
from fastapi.responses import HTMLResponse, RedirectResponse
|
||||
from fastapi.staticfiles import StaticFiles
|
||||
from fastapi.templating import Jinja2Templates
|
||||
|
||||
from module import app
|
||||
from module.api import router
|
||||
from module.conf import VERSION, settings
|
||||
|
||||
from module.conf import settings, setup_logger
|
||||
|
||||
setup_logger(reset=True)
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
main_process = multiprocessing.Process(target=app.run, args=(settings,))
|
||||
|
||||
|
||||
@router.on_event("startup")
|
||||
async def startup():
|
||||
global main_process
|
||||
main_process.start()
|
||||
|
||||
|
||||
@router.on_event("shutdown")
|
||||
async def shutdown():
|
||||
global main_process
|
||||
if main_process.is_alive():
|
||||
os.kill(main_process.pid, signal.SIGTERM)
|
||||
|
||||
|
||||
@router.get("/api/v1/restart", tags=["program"])
|
||||
async def restart():
|
||||
global main_process
|
||||
if main_process.is_alive():
|
||||
os.kill(main_process.pid, signal.SIGTERM)
|
||||
logger.info("Restarting...")
|
||||
else:
|
||||
logger.info("Starting...")
|
||||
settings.reload()
|
||||
main_process = multiprocessing.Process(target=app.run, args=(settings,))
|
||||
main_process.start()
|
||||
logger.info("Restarted")
|
||||
return {"status": "success"}
|
||||
|
||||
|
||||
@router.get("/api/v1/stop", tags=["program"])
|
||||
async def stop():
|
||||
global main_process
|
||||
if not main_process.is_alive():
|
||||
return {"status": "failed", "reason": "Already stopped"}
|
||||
logger.info("Stopping...")
|
||||
os.kill(main_process.pid, signal.SIGTERM)
|
||||
logger.info("Stopped")
|
||||
return {"status": "success"}
|
||||
|
||||
|
||||
@router.get("/api/v1/start", tags=["program"])
|
||||
async def start():
|
||||
global main_process
|
||||
if main_process.is_alive():
|
||||
return {"status": "failed", "reason": "Already started"}
|
||||
logger.info("Starting...")
|
||||
settings.reload()
|
||||
main_process = multiprocessing.Process(target=app.run, args=(settings,))
|
||||
main_process.start()
|
||||
logger.info("Started")
|
||||
return {"status": "success"}
|
||||
|
||||
|
||||
@router.get("/api/v1/status", tags=["program"])
|
||||
async def status():
|
||||
global main_process
|
||||
if main_process.is_alive():
|
||||
return True
|
||||
else:
|
||||
return False
|
||||
|
||||
|
||||
if VERSION != "DEV_VERSION":
|
||||
router.mount("/assets", StaticFiles(directory="templates/assets"), name="assets")
|
||||
templates = Jinja2Templates(directory="templates")
|
||||
|
||||
# HTML Response
|
||||
@router.get("/{full_path:path}", response_class=HTMLResponse, tags=["html"])
|
||||
def index(request: Request):
|
||||
context = {"request": request}
|
||||
return templates.TemplateResponse("index.html", context)
|
||||
else:
|
||||
@router.get("/", status_code=302, tags=["html"])
|
||||
def index():
|
||||
return RedirectResponse("/docs")
|
||||
|
||||
uvicorn_logging_config = {
|
||||
"version": 1,
|
||||
"disable_existing_loggers": False,
|
||||
"handlers": logger.handlers,
|
||||
"loggers": {
|
||||
"uvicorn": {
|
||||
"level": logger.level,
|
||||
},
|
||||
"uvicorn.access": {
|
||||
"level": "WARNING",
|
||||
},
|
||||
},
|
||||
}
|
||||
|
||||
if __name__ == "__main__":
|
||||
log_config = uvicorn.config.LOGGING_CONFIG
|
||||
log_config["formatters"]["default"]["fmt"] = "[%(asctime)s] %(levelname)-8s %(message)s"
|
||||
uvicorn.run(router, host="0.0.0.0", port=settings.program.webui_port, log_config=log_config)
|
||||
|
||||
uvicorn.run(
|
||||
router,
|
||||
host="0.0.0.0",
|
||||
port=settings.program.webui_port,
|
||||
log_config=uvicorn_logging_config,
|
||||
)
|
||||
|
||||
@@ -16,6 +16,7 @@ def qb_connect_failed_wait(func):
|
||||
logger.warning("Cannot connect to qBittorrent. Wait 5 min and retry...")
|
||||
time.sleep(300)
|
||||
times += 1
|
||||
|
||||
return wrapper
|
||||
|
||||
|
||||
@@ -27,4 +28,5 @@ def api_failed(func):
|
||||
logger.debug(f"URL: {args[0]}")
|
||||
logger.warning("Wrong API response.")
|
||||
logger.debug(e)
|
||||
|
||||
return wrapper
|
||||
|
||||
@@ -1,114 +0,0 @@
|
||||
import logging
|
||||
import os
|
||||
|
||||
from fastapi import FastAPI
|
||||
from fastapi.responses import FileResponse, Response
|
||||
|
||||
from module.core import APIProcess
|
||||
from module.conf import DATA_PATH, LOG_PATH, settings
|
||||
from module.utils import json_config
|
||||
from module.models.api import *
|
||||
from module.models import Config
|
||||
|
||||
|
||||
router = FastAPI()
|
||||
api_func = APIProcess(settings)
|
||||
|
||||
|
||||
@router.get("/api/v1/data", tags=["info"])
|
||||
async def get_data():
|
||||
try:
|
||||
data = json_config.load(DATA_PATH)
|
||||
return data
|
||||
except FileNotFoundError:
|
||||
return {
|
||||
"rss_link": "",
|
||||
"data_version": settings.data_version,
|
||||
"bangumi_info": [],
|
||||
}
|
||||
|
||||
|
||||
@router.get("/api/v1/log", tags=["info"])
|
||||
async def get_log():
|
||||
if os.path.isfile(LOG_PATH):
|
||||
return FileResponse(LOG_PATH)
|
||||
else:
|
||||
return Response("Log file not found", status_code=404)
|
||||
|
||||
|
||||
@router.get("/api/v1/resetRule")
|
||||
def reset_rule():
|
||||
return api_func.reset_rule()
|
||||
|
||||
|
||||
@router.get("api/v1/removeRule/{bangumi_id}")
|
||||
def remove_rule(bangumi_id: str):
|
||||
bangumi_id = int(bangumi_id)
|
||||
return api_func.remove_rule(bangumi_id)
|
||||
|
||||
|
||||
@router.post("/api/v1/collection", tags=["download"])
|
||||
async def collection(link: RssLink):
|
||||
response = api_func.download_collection(link.rss_link)
|
||||
if response:
|
||||
return response.dict()
|
||||
else:
|
||||
return {"status": "Failed to parse link"}
|
||||
|
||||
|
||||
@router.post("/api/v1/subscribe", tags=["download"])
|
||||
async def subscribe(link: RssLink):
|
||||
response = api_func.add_subscribe(link.rss_link)
|
||||
if response:
|
||||
return response.dict()
|
||||
else:
|
||||
return {"status": "Failed to parse link"}
|
||||
|
||||
|
||||
@router.post("/api/v1/addRule", tags=["download"])
|
||||
async def add_rule(info: AddRule):
|
||||
return api_func.add_rule(info.title, info.season)
|
||||
|
||||
|
||||
@router.get("/api/v1/getConfig", tags=["config"])
|
||||
async def get_config():
|
||||
return api_func.get_config()
|
||||
|
||||
|
||||
@router.post("/api/v1/updateConfig", tags=["config"])
|
||||
async def update_config(config: Config):
|
||||
return api_func.update_config(config)
|
||||
|
||||
|
||||
@router.get("/RSS/MyBangumi", tags=["proxy"])
|
||||
async def get_my_bangumi(token: str):
|
||||
full_path = "MyBangumi?token=" + token
|
||||
content = api_func.get_rss(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/RSS/Search", tags=["proxy"])
|
||||
async def get_search_result(searchstr: str):
|
||||
full_path = "Search?searchstr=" + searchstr
|
||||
content = api_func.get_rss(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/RSS/Bangumi", tags=["proxy"])
|
||||
async def get_bangumi(bangumiId: str, groupid: str):
|
||||
full_path = "Bangumi?bangumiId=" + bangumiId + "&groupid=" + groupid
|
||||
content = api_func.get_rss(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/RSS/{full_path:path}", tags=["proxy"])
|
||||
async def get_rss(full_path: str):
|
||||
content = api_func.get_rss(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/Download/{full_path:path}", tags=["proxy"])
|
||||
async def download(full_path: str):
|
||||
torrent = api_func.get_torrent(full_path)
|
||||
return Response(torrent, media_type="application/x-bittorrent")
|
||||
|
||||
1
src/module/api/__init__.py
Normal file
1
src/module/api/__init__.py
Normal file
@@ -0,0 +1 @@
|
||||
from .web import router
|
||||
63
src/module/api/auth.py
Normal file
63
src/module/api/auth.py
Normal file
@@ -0,0 +1,63 @@
|
||||
from datetime import timedelta
|
||||
|
||||
from fastapi import Depends, HTTPException, status
|
||||
from fastapi.security import OAuth2PasswordRequestForm
|
||||
|
||||
from module.security import (
|
||||
create_access_token,
|
||||
get_current_user,
|
||||
update_user_info,
|
||||
auth_user,
|
||||
)
|
||||
from module.models.user import User
|
||||
|
||||
from .program import router
|
||||
|
||||
|
||||
@router.post("/api/v1/auth/login", response_model=dict, tags=["auth"])
|
||||
async def login(form_data: OAuth2PasswordRequestForm = Depends()):
|
||||
username = form_data.username
|
||||
password = form_data.password
|
||||
auth_user(username, password)
|
||||
token = create_access_token(
|
||||
data={"sub": username}, expires_delta=timedelta(days=1)
|
||||
)
|
||||
|
||||
return {"access_token": token, "token_type": "bearer", "expire": 86400}
|
||||
|
||||
|
||||
@router.get("/api/v1/auth/refresh_token", response_model=dict, tags=["auth"])
|
||||
async def refresh(current_user: User = Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
token = create_access_token(
|
||||
data = {"sub": current_user.username}
|
||||
|
||||
)
|
||||
return {"access_token": token, "token_type": "bearer", "expire": 86400}
|
||||
|
||||
|
||||
@router.get("/api/v1/auth/logout", response_model=dict, tags=["auth"])
|
||||
async def logout(current_user: User = Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
return {"message": "logout success"}
|
||||
|
||||
|
||||
@router.post("/api/v1/auth/update", response_model=dict, tags=["auth"])
|
||||
async def update_user(user_data: User, current_user: User = Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
if update_user_info(user_data, current_user):
|
||||
return {
|
||||
"message": "update success",
|
||||
"access_token": create_access_token({"sub": user_data.username}),
|
||||
"token_type": "bearer",
|
||||
"expire": 86400,
|
||||
}
|
||||
85
src/module/api/bangumi.py
Normal file
85
src/module/api/bangumi.py
Normal file
@@ -0,0 +1,85 @@
|
||||
from fastapi import Depends, HTTPException, status
|
||||
|
||||
from .log import router
|
||||
|
||||
from module.models import BangumiData
|
||||
from module.database import BangumiDatabase
|
||||
from module.manager import TorrentManager
|
||||
from module.security import get_current_user
|
||||
|
||||
|
||||
@router.get(
|
||||
"/api/v1/bangumi/getAll", tags=["bangumi"], response_model=list[BangumiData]
|
||||
)
|
||||
async def get_all_data(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
with TorrentManager() as torrent:
|
||||
return torrent.search_all()
|
||||
|
||||
|
||||
@router.get(
|
||||
"/api/v1/bangumi/getData/{bangumi_id}", tags=["bangumi"], response_model=BangumiData
|
||||
)
|
||||
async def get_data(bangumi_id: str, current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
with TorrentManager() as torrent:
|
||||
return torrent.search_one(bangumi_id)
|
||||
|
||||
|
||||
@router.post("/api/v1/bangumi/updateRule", tags=["bangumi"])
|
||||
async def update_data(data: BangumiData, current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
with TorrentManager() as torrent:
|
||||
return torrent.update_rule(data)
|
||||
|
||||
|
||||
@router.delete("/api/v1/bangumi/deleteRule/{bangumi_id}", tags=["bangumi"])
|
||||
async def delete_data(bangumi_id: str, file:bool = False, current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
with TorrentManager() as torrent:
|
||||
return torrent.delete_rule(bangumi_id, file)
|
||||
|
||||
|
||||
@router.delete("/api/v1/bangumi/disableRule/{bangumi_id}", tags=["bangumi"])
|
||||
async def delete_rule(
|
||||
bangumi_id: str, file: bool = False, current_user=Depends(get_current_user)
|
||||
):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
with TorrentManager() as torrent:
|
||||
return torrent.disable_rule(bangumi_id, file)
|
||||
|
||||
|
||||
@router.get("/api/v1/bangumi/enableRule/{bangumi_id}", tags=["bangumi"])
|
||||
async def enable_rule(bangumi_id: str, current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
with TorrentManager() as torrent:
|
||||
return torrent.enable_rule(bangumi_id)
|
||||
|
||||
|
||||
@router.get("/api/v1/bangumi/resetAll", tags=["bangumi"])
|
||||
async def reset_all(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
with BangumiDatabase() as database:
|
||||
database.delete_all()
|
||||
return {"status": "ok"}
|
||||
36
src/module/api/config.py
Normal file
36
src/module/api/config.py
Normal file
@@ -0,0 +1,36 @@
|
||||
import logging
|
||||
|
||||
from fastapi import Depends, HTTPException, status
|
||||
|
||||
from .bangumi import router
|
||||
|
||||
from module.conf import settings
|
||||
from module.models import Config
|
||||
from module.security import get_current_user
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@router.get("/api/v1/getConfig", tags=["config"], response_model=Config)
|
||||
async def get_config(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
return settings
|
||||
|
||||
|
||||
@router.post("/api/v1/updateConfig", tags=["config"])
|
||||
async def update_config(config: Config, current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
try:
|
||||
settings.save(config_dict=config.dict())
|
||||
settings.load()
|
||||
logger.info("Config updated")
|
||||
return {"message": "Success"}
|
||||
except Exception as e:
|
||||
logger.warning(e)
|
||||
return {"message": "Failed to update config"}
|
||||
52
src/module/api/download.py
Normal file
52
src/module/api/download.py
Normal file
@@ -0,0 +1,52 @@
|
||||
from fastapi import Depends, HTTPException, status
|
||||
|
||||
from .config import router
|
||||
|
||||
from module.models.api import *
|
||||
from module.models import BangumiData
|
||||
from module.manager import SeasonCollector
|
||||
from module.rss import analyser
|
||||
from module.security import get_current_user
|
||||
|
||||
|
||||
@router.post("/api/v1/download/analysis", tags=["download"])
|
||||
async def analysis(link: RssLink, current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
data = analyser.link_to_data(link.rss_link)
|
||||
if data:
|
||||
return data
|
||||
else:
|
||||
return {"status": "Failed to parse link"}
|
||||
|
||||
|
||||
@router.post("/api/v1/download/collection", tags=["download"])
|
||||
async def download_collection(
|
||||
data: BangumiData, current_user=Depends(get_current_user)
|
||||
):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
if data:
|
||||
with SeasonCollector() as collector:
|
||||
collector.collect_season(data, data.rss_link[0])
|
||||
return {"status": "Success"}
|
||||
else:
|
||||
return {"status": "Failed to parse link"}
|
||||
|
||||
|
||||
@router.post("/api/v1/download/subscribe", tags=["download"])
|
||||
async def subscribe(data: BangumiData, current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
if data:
|
||||
with SeasonCollector() as collector:
|
||||
collector.subscribe_season(data)
|
||||
return {"status": "Success"}
|
||||
else:
|
||||
return {"status": "Failed to parse link"}
|
||||
34
src/module/api/log.py
Normal file
34
src/module/api/log.py
Normal file
@@ -0,0 +1,34 @@
|
||||
import os
|
||||
from fastapi import Response, HTTPException, Depends, status
|
||||
|
||||
from .auth import router
|
||||
|
||||
from module.conf import LOG_PATH
|
||||
from module.security import get_current_user
|
||||
|
||||
|
||||
@router.get("/api/v1/log", tags=["log"])
|
||||
async def get_log(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
if os.path.isfile(LOG_PATH):
|
||||
with open(LOG_PATH, "r") as f:
|
||||
return Response(f.read(), media_type="text/plain")
|
||||
else:
|
||||
return Response("Log file not found", status_code=404)
|
||||
|
||||
|
||||
@router.get("/api/v1/log/clear", tags=["log"])
|
||||
async def clear_log(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
if os.path.isfile(LOG_PATH):
|
||||
with open(LOG_PATH, "w") as f:
|
||||
f.write("")
|
||||
return {"status": "ok"}
|
||||
else:
|
||||
return Response("Log file not found", status_code=404)
|
||||
104
src/module/api/program.py
Normal file
104
src/module/api/program.py
Normal file
@@ -0,0 +1,104 @@
|
||||
import signal
|
||||
import logging
|
||||
import os
|
||||
|
||||
from fastapi import HTTPException, status, Depends
|
||||
from fastapi import FastAPI
|
||||
|
||||
from module.core import Program
|
||||
from module.security import get_current_user
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
program = Program()
|
||||
router = FastAPI()
|
||||
|
||||
|
||||
@router.on_event("startup")
|
||||
async def startup():
|
||||
program.startup()
|
||||
|
||||
|
||||
@router.on_event("shutdown")
|
||||
async def shutdown():
|
||||
program.stop()
|
||||
|
||||
|
||||
@router.get("/api/v1/restart", tags=["program"])
|
||||
async def restart(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
try:
|
||||
program.restart()
|
||||
return {"status": "ok"}
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
logger.warning("Failed to restart program")
|
||||
raise HTTPException(status_code=500, detail="Failed to restart program")
|
||||
|
||||
|
||||
@router.get("/api/v1/start", tags=["program"])
|
||||
async def start(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
try:
|
||||
return program.start()
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
logger.warning("Failed to start program")
|
||||
raise HTTPException(status_code=500, detail="Failed to start program")
|
||||
|
||||
|
||||
@router.get("/api/v1/stop", tags=["program"])
|
||||
async def stop(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
return program.stop()
|
||||
|
||||
|
||||
@router.get("/api/v1/status", tags=["program"])
|
||||
async def status(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
if not program.is_running:
|
||||
return {"status": "stop"}
|
||||
else:
|
||||
return {"status": "running"}
|
||||
|
||||
|
||||
@router.get("/api/v1/shutdown", tags=["program"])
|
||||
async def shutdown_program(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
program.stop()
|
||||
logger.info("Shutting down program...")
|
||||
os.kill(os.getpid(), signal.SIGINT)
|
||||
return {"status": "ok"}
|
||||
|
||||
|
||||
# Check status
|
||||
@router.get("/api/v1/check/downloader", tags=["check"])
|
||||
async def check_downloader_status(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
return program.check_downloader()
|
||||
|
||||
|
||||
@router.get("/api/v1/check/rss", tags=["check"])
|
||||
async def check_rss_status(current_user=Depends(get_current_user)):
|
||||
if not current_user:
|
||||
raise HTTPException(
|
||||
status_code=status.HTTP_401_UNAUTHORIZED, detail="invalid token"
|
||||
)
|
||||
return program.check_analyser()
|
||||
84
src/module/api/proxy.py
Normal file
84
src/module/api/proxy.py
Normal file
@@ -0,0 +1,84 @@
|
||||
import re
|
||||
import logging
|
||||
|
||||
from fastapi.responses import Response
|
||||
from fastapi.exceptions import HTTPException
|
||||
|
||||
from .download import router
|
||||
|
||||
from module.conf import settings
|
||||
from module.network import RequestContent
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def get_rss_content(full_path):
|
||||
url = f"https://mikanani.me/RSS/{full_path}"
|
||||
custom_url = settings.rss_parser.custom_url
|
||||
if "://" not in custom_url:
|
||||
custom_url = f"https://{custom_url}"
|
||||
try:
|
||||
with RequestContent() as request:
|
||||
content = request.get_html(url)
|
||||
return re.sub(r"https://mikanani.me", custom_url, content)
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
logger.warning("Failed to get RSS content")
|
||||
raise HTTPException(status_code=500, detail="Failed to get RSS content")
|
||||
|
||||
|
||||
def get_torrent(full_path):
|
||||
url = f"https://mikanani.me/Download/{full_path}"
|
||||
try:
|
||||
with RequestContent() as request:
|
||||
return request.get_content(url)
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
logger.warning("Failed to get torrent")
|
||||
raise HTTPException(status_code=500, detail="Failed to get torrent")
|
||||
|
||||
|
||||
@router.get("/RSS/MyBangumi", tags=["proxy"])
|
||||
async def get_my_bangumi(token: str):
|
||||
full_path = "MyBangumi?token=" + token
|
||||
content = get_rss_content(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/RSS/Search", tags=["proxy"])
|
||||
async def get_search_result(searchstr: str):
|
||||
full_path = "Search?searchstr=" + searchstr
|
||||
content = get_rss_content(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/RSS/Bangumi", tags=["proxy"])
|
||||
async def get_bangumi(bangumiId: str, groupid: str):
|
||||
full_path = "Bangumi?bangumiId=" + bangumiId + "&groupid=" + groupid
|
||||
content = get_rss_content(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/RSS/{full_path:path}", tags=["proxy"])
|
||||
async def get_rss(full_path: str):
|
||||
content = get_rss_content(full_path)
|
||||
return Response(content, media_type="application/xml")
|
||||
|
||||
|
||||
@router.get("/Download/{full_path:path}", tags=["proxy"])
|
||||
async def download(full_path: str):
|
||||
torrent = get_torrent(full_path)
|
||||
return Response(torrent, media_type="application/x-bittorrent")
|
||||
|
||||
|
||||
@router.get("/Home/Episode/{full_path:path}", tags=["proxy"])
|
||||
async def get_ep_info(full_path: str):
|
||||
url = f"https://mikanani.me/Home/Episode/{full_path}"
|
||||
try:
|
||||
with RequestContent() as request:
|
||||
return Response(request.get_html(url), media_type="text/html")
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
logger.warning("Failed to get ep info")
|
||||
raise HTTPException(status_code=500, detail="Failed to get ep info")
|
||||
38
src/module/api/web.py
Normal file
38
src/module/api/web.py
Normal file
@@ -0,0 +1,38 @@
|
||||
from fastapi import Request
|
||||
from fastapi.responses import HTMLResponse, RedirectResponse, FileResponse
|
||||
from fastapi.staticfiles import StaticFiles
|
||||
from fastapi.templating import Jinja2Templates
|
||||
|
||||
from .proxy import router
|
||||
|
||||
from module.conf import VERSION
|
||||
|
||||
|
||||
if VERSION != "DEV_VERSION":
|
||||
router.mount("/assets", StaticFiles(directory="templates/assets"), name="assets")
|
||||
templates = Jinja2Templates(directory="templates")
|
||||
|
||||
# Resource
|
||||
@router.get("/favicon.svg", tags=["html"])
|
||||
def favicon():
|
||||
return FileResponse("templates/favicon.svg")
|
||||
|
||||
@router.get("/AutoBangumi.svg", tags=["html"])
|
||||
def logo():
|
||||
return FileResponse("templates/AutoBangumi.svg")
|
||||
|
||||
@router.get("/favicon-light.svg", tags=["html"])
|
||||
def favicon_light():
|
||||
return FileResponse("templates/favicon-light.svg")
|
||||
|
||||
# HTML Response
|
||||
@router.get("/{full_path:path}", response_class=HTMLResponse, tags=["html"])
|
||||
def index(request: Request):
|
||||
context = {"request": request}
|
||||
return templates.TemplateResponse("index.html", context)
|
||||
|
||||
else:
|
||||
|
||||
@router.get("/", status_code=302, tags=["html"])
|
||||
def index():
|
||||
return RedirectResponse("/docs")
|
||||
@@ -1,82 +0,0 @@
|
||||
import os
|
||||
import time
|
||||
import logging
|
||||
|
||||
from module.conf import setup_logger, LOG_PATH, DATA_PATH, RSSLink, VERSION
|
||||
from module.utils import load_program_data, save_program_data
|
||||
|
||||
from module.core import DownloadClient
|
||||
from module.manager import Renamer, FullSeasonGet
|
||||
from module.rss import RSSAnalyser
|
||||
from module.models import ProgramData, Config
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def reset_log():
|
||||
if os.path.exists(LOG_PATH):
|
||||
os.remove(LOG_PATH)
|
||||
|
||||
|
||||
def load_data_file(rss_link: str, data_version) -> ProgramData:
|
||||
empty_data = ProgramData(
|
||||
rss_link=rss_link,
|
||||
data_version=data_version,
|
||||
)
|
||||
if not os.path.exists(DATA_PATH):
|
||||
program_data = empty_data
|
||||
save_program_data(DATA_PATH, program_data)
|
||||
logger.info("Building data information...")
|
||||
else:
|
||||
program_data = load_program_data(DATA_PATH)
|
||||
if program_data.rss_link != rss_link or program_data.data_version != data_version:
|
||||
program_data = empty_data
|
||||
logger.info("Rebuilding data information...")
|
||||
return program_data
|
||||
|
||||
|
||||
def main_process(program_data: ProgramData, download_client: DownloadClient, _settings: Config):
|
||||
rename = Renamer(download_client, _settings)
|
||||
rss_analyser = RSSAnalyser(_settings)
|
||||
while True:
|
||||
times = 0
|
||||
if _settings.rss_parser.enable:
|
||||
rss_analyser.run(program_data.bangumi_info, program_data.rss_link)
|
||||
download_client.add_rules(program_data.bangumi_info, program_data.rss_link)
|
||||
if _settings.bangumi_manage.eps_complete and program_data.bangumi_info != []:
|
||||
FullSeasonGet(settings=_settings).eps_complete(program_data.bangumi_info, download_client)
|
||||
logger.info("Running....")
|
||||
save_program_data(DATA_PATH, program_data)
|
||||
while times < _settings.program.rename_times:
|
||||
if _settings.bangumi_manage.enable:
|
||||
rename.rename()
|
||||
times += 1
|
||||
time.sleep(_settings.program.sleep_time / _settings.program.rename_times)
|
||||
|
||||
|
||||
def show_info():
|
||||
with open("icon", "r") as f:
|
||||
for line in f.readlines():
|
||||
logger.info(line.strip("\n"))
|
||||
logger.info(f"Version {VERSION} Author: EstrellaXD Twitter: https://twitter.com/Estrella_Pan")
|
||||
logger.info("GitHub: https://github.com/EstrellaXD/Auto_Bangumi/")
|
||||
logger.info("Starting AutoBangumi...")
|
||||
|
||||
|
||||
def run(settings: Config):
|
||||
# 初始化
|
||||
rss_link = RSSLink()
|
||||
reset_log()
|
||||
setup_logger()
|
||||
show_info()
|
||||
if settings.rss_parser.token in ["", "token", None]:
|
||||
logger.error("Please set your RSS token in config file.")
|
||||
exit(1)
|
||||
download_client = DownloadClient(settings)
|
||||
download_client.auth()
|
||||
download_client.init_downloader()
|
||||
download_client.rss_feed(rss_link)
|
||||
bangumi_data = load_data_file(rss_link, settings.data_version)
|
||||
# 主程序循环
|
||||
main_process(bangumi_data, download_client, settings)
|
||||
1
src/module/checker/__init__.py
Normal file
1
src/module/checker/__init__.py
Normal file
@@ -0,0 +1 @@
|
||||
from .checker import Checker
|
||||
51
src/module/checker/checker.py
Normal file
51
src/module/checker/checker.py
Normal file
@@ -0,0 +1,51 @@
|
||||
import os.path
|
||||
|
||||
from module.downloader import DownloadClient
|
||||
from module.network import RequestContent
|
||||
from module.conf import settings, DATA_PATH
|
||||
|
||||
|
||||
class Checker:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
def check_renamer(self) -> bool:
|
||||
if self.check_downloader() and settings.bangumi_manage.enable:
|
||||
return True
|
||||
else:
|
||||
return False
|
||||
|
||||
def check_analyser(self) -> bool:
|
||||
if self.check_downloader() and settings.rss_parser.enable:
|
||||
return True
|
||||
else:
|
||||
return False
|
||||
|
||||
@staticmethod
|
||||
def check_downloader() -> bool:
|
||||
with DownloadClient() as client:
|
||||
if client.authed:
|
||||
return True
|
||||
else:
|
||||
return False
|
||||
|
||||
@staticmethod
|
||||
def check_torrents() -> bool:
|
||||
with RequestContent() as req:
|
||||
try:
|
||||
torrents = req.get_torrents(settings.rss_link, retry=2)
|
||||
if torrents:
|
||||
return True
|
||||
except AttributeError:
|
||||
link = f"https://mikanani.me/RSS/MyBangumi?token={settings.rss_parser.token}"
|
||||
if req.get_torrents(link):
|
||||
return True
|
||||
return False
|
||||
|
||||
@staticmethod
|
||||
def check_first_run() -> bool:
|
||||
token_exist = False if settings.rss_parser.token in ["", "token"] else True
|
||||
if token_exist:
|
||||
return False
|
||||
else:
|
||||
return True
|
||||
@@ -1,17 +1,8 @@
|
||||
from .log import setup_logger, LOG_PATH
|
||||
from .config import settings, VERSION
|
||||
from .config import VERSION, settings
|
||||
|
||||
|
||||
TMDB_API = "32b19d6a05b512190a056fa4e747cbbc"
|
||||
DATA_PATH = "data/data.json"
|
||||
|
||||
|
||||
class RSSLink(str):
|
||||
def __new__(cls):
|
||||
if "://" not in settings.rss_parser.custom_url:
|
||||
return f"https://{settings.rss_parser.custom_url}/RSS/MyBangumi?token={settings.rss_parser.token}"
|
||||
return f"{settings.rss_parser.custom_url}/RSS/MyBangumi?token={settings.rss_parser.token}"
|
||||
|
||||
DATA_PATH = "data/data.db"
|
||||
|
||||
PLATFORM = "Windows" if "\\" in settings.downloader.path else "Unix"
|
||||
MIKANANI_URL = "mikanani.me"
|
||||
|
||||
@@ -3,80 +3,85 @@ import os
|
||||
import logging
|
||||
from dotenv import load_dotenv
|
||||
|
||||
from module.conf.const import ENV_TO_ATTR
|
||||
from .const import ENV_TO_ATTR
|
||||
from module.models.config import Config
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
try:
|
||||
from ..__version__ import VERSION
|
||||
from module.__version__ import VERSION
|
||||
|
||||
if VERSION == "DEV_VERSION":
|
||||
logger.info("Can't find version info, use DEV_VERSION instead")
|
||||
CONFIG_PATH = "config/config_dev.json"
|
||||
else:
|
||||
CONFIG_PATH = f"config/config.json"
|
||||
except ImportError:
|
||||
logger.info("Can't find version info, use DEV_VERSION instead")
|
||||
VERSION = "DEV_VERSION"
|
||||
|
||||
|
||||
class Setting(Config):
|
||||
@staticmethod
|
||||
def reload():
|
||||
load_config_from_file(CONFIG_PATH)
|
||||
|
||||
def save(self):
|
||||
save_config_to_file(self, CONFIG_PATH)
|
||||
|
||||
|
||||
def save_config_to_file(config: Config, path: str):
|
||||
config_dict = config.dict()
|
||||
with open(path, "w", encoding="utf-8") as f:
|
||||
json.dump(config_dict, f, indent=4)
|
||||
logger.info(f"Config saved")
|
||||
|
||||
|
||||
def load_config_from_file(path: str) -> Config:
|
||||
with open(path, "r", encoding="utf-8") as f:
|
||||
config = json.load(f)
|
||||
return Setting(**config)
|
||||
|
||||
|
||||
def _val_from_env(env: str, attr: tuple):
|
||||
if isinstance(attr, tuple):
|
||||
conv_func = attr[1]
|
||||
return conv_func(os.environ[env])
|
||||
else:
|
||||
return os.environ[env]
|
||||
|
||||
|
||||
def env_to_config() -> Setting:
|
||||
_settings = Setting().dict()
|
||||
for key, section in ENV_TO_ATTR.items():
|
||||
for env, attr in section.items():
|
||||
if env in os.environ:
|
||||
if isinstance(attr, list):
|
||||
for _attr in attr:
|
||||
attr_name = _attr[0] if isinstance(_attr, tuple) else _attr
|
||||
_settings[key][attr_name] = _val_from_env(env, _attr)
|
||||
else:
|
||||
attr_name = attr[0] if isinstance(attr, tuple) else attr
|
||||
_settings[key][attr_name] = _val_from_env(env, attr)
|
||||
return Setting(**_settings)
|
||||
|
||||
|
||||
if os.path.isdir("config") and VERSION == "DEV_VERSION":
|
||||
CONFIG_PATH = "config/config_dev.json"
|
||||
if os.path.isfile(CONFIG_PATH):
|
||||
settings = load_config_from_file(CONFIG_PATH)
|
||||
else:
|
||||
|
||||
|
||||
class Settings(Config):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
if os.path.exists(CONFIG_PATH):
|
||||
self.load()
|
||||
self.save()
|
||||
else:
|
||||
self.init()
|
||||
|
||||
def load(self):
|
||||
with open(CONFIG_PATH, "r", encoding="utf-8") as f:
|
||||
config = json.load(f)
|
||||
config_obj = Config.parse_obj(config)
|
||||
self.__dict__.update(config_obj.__dict__)
|
||||
logger.info(f"Config loaded")
|
||||
|
||||
def save(self, config_dict: dict | None = None):
|
||||
if not config_dict:
|
||||
config_dict = self.dict()
|
||||
with open(CONFIG_PATH, "w", encoding="utf-8") as f:
|
||||
json.dump(config_dict, f, indent=4)
|
||||
|
||||
def init(self):
|
||||
load_dotenv(".env")
|
||||
settings = env_to_config()
|
||||
save_config_to_file(settings, CONFIG_PATH)
|
||||
elif os.path.isdir("config") and VERSION != "DEV_VERSION":
|
||||
CONFIG_PATH = "config/config.json"
|
||||
if os.path.isfile(CONFIG_PATH):
|
||||
settings = load_config_from_file(CONFIG_PATH)
|
||||
else:
|
||||
settings = env_to_config()
|
||||
save_config_to_file(settings, CONFIG_PATH)
|
||||
else:
|
||||
settings = Setting()
|
||||
|
||||
self.__load_from_env()
|
||||
self.save()
|
||||
|
||||
@property
|
||||
def rss_link(self) -> str:
|
||||
if "://" not in self.rss_parser.custom_url:
|
||||
return f"https://{self.rss_parser.custom_url}/RSS/MyBangumi?token={self.rss_parser.token}"
|
||||
return (
|
||||
f"{self.rss_parser.custom_url}/RSS/MyBangumi?token={self.rss_parser.token}"
|
||||
)
|
||||
|
||||
def __load_from_env(self):
|
||||
config_dict = self.dict()
|
||||
for key, section in ENV_TO_ATTR.items():
|
||||
for env, attr in section.items():
|
||||
if env in os.environ:
|
||||
if isinstance(attr, list):
|
||||
for _attr in attr:
|
||||
attr_name = _attr[0] if isinstance(_attr, tuple) else _attr
|
||||
config_dict[key][attr_name] = self.__val_from_env(
|
||||
env, _attr
|
||||
)
|
||||
else:
|
||||
attr_name = attr[0] if isinstance(attr, tuple) else attr
|
||||
config_dict[key][attr_name] = self.__val_from_env(env, attr)
|
||||
config_obj = Config.parse_obj(config_dict)
|
||||
self.__dict__.update(config_obj.__dict__)
|
||||
logger.info(f"Config loaded from env")
|
||||
|
||||
@staticmethod
|
||||
def __val_from_env(env: str, attr: tuple):
|
||||
if isinstance(attr, tuple):
|
||||
conv_func = attr[1]
|
||||
return conv_func(os.environ[env])
|
||||
else:
|
||||
return os.environ[env]
|
||||
|
||||
|
||||
settings = Settings()
|
||||
|
||||
@@ -7,7 +7,7 @@ DEFAULT_SETTINGS = {
|
||||
"sleep_time": 7200,
|
||||
"times": 20,
|
||||
"webui_port": 7892,
|
||||
"data_version": 4.0
|
||||
"data_version": 4.0,
|
||||
},
|
||||
"downloader": {
|
||||
"type": "qbittorrent",
|
||||
@@ -15,7 +15,7 @@ DEFAULT_SETTINGS = {
|
||||
"username": "admin",
|
||||
"password": "adminadmin",
|
||||
"path": "/downloads/Bangumi",
|
||||
"ssl": False
|
||||
"ssl": False,
|
||||
},
|
||||
"rss_parser": {
|
||||
"enable": True,
|
||||
@@ -24,14 +24,14 @@ DEFAULT_SETTINGS = {
|
||||
"token": "",
|
||||
"enable_tmdb": False,
|
||||
"filter": ["720", "\\d+-\\d+"],
|
||||
"language": "zh"
|
||||
"language": "zh",
|
||||
},
|
||||
"bangumi_manage": {
|
||||
"enable": True,
|
||||
"eps_complete": False,
|
||||
"rename_method": "pn",
|
||||
"group_tag": False,
|
||||
"remove_bad_torrent": False
|
||||
"remove_bad_torrent": False,
|
||||
},
|
||||
"log": {
|
||||
"debug_enable": False,
|
||||
@@ -42,14 +42,9 @@ DEFAULT_SETTINGS = {
|
||||
"host": "",
|
||||
"port": 1080,
|
||||
"username": "",
|
||||
"password": ""
|
||||
"password": "",
|
||||
},
|
||||
"notification": {
|
||||
"enable": False,
|
||||
"type": "telegram",
|
||||
"token": "",
|
||||
"chat_id": ""
|
||||
}
|
||||
"notification": {"enable": False, "type": "telegram", "token": "", "chat_id": ""},
|
||||
}
|
||||
|
||||
|
||||
@@ -80,7 +75,10 @@ ENV_TO_ATTR = {
|
||||
"AB_METHOD": ("rename_method", lambda e: e.lower()),
|
||||
"AB_GROUP_TAG": ("group_tag", lambda e: e.lower() in ("true", "1", "t")),
|
||||
"AB_EP_COMPLETE": ("eps_complete", lambda e: e.lower() in ("true", "1", "t")),
|
||||
"AB_REMOVE_BAD_BT": ("remove_bad_torrent", lambda e: e.lower() in ("true", "1", "t")),
|
||||
"AB_REMOVE_BAD_BT": (
|
||||
"remove_bad_torrent",
|
||||
lambda e: e.lower() in ("true", "1", "t"),
|
||||
),
|
||||
},
|
||||
"log": {
|
||||
"AB_DEBUG_MODE": ("debug_enable", lambda e: e.lower() in ("true", "1", "t")),
|
||||
|
||||
@@ -1,3 +1,4 @@
|
||||
import os
|
||||
import logging
|
||||
|
||||
from .config import settings
|
||||
@@ -5,18 +6,24 @@ from .config import settings
|
||||
LOG_PATH = "data/log.txt"
|
||||
|
||||
|
||||
def setup_logger():
|
||||
level = logging.DEBUG if settings.log.debug_enable else logging.INFO
|
||||
logging.addLevelName(logging.DEBUG, 'DEBUG:')
|
||||
logging.addLevelName(logging.INFO, 'INFO:')
|
||||
logging.addLevelName(logging.WARNING, 'WARNING:')
|
||||
def setup_logger(level: int = logging.INFO, reset: bool = False):
|
||||
level = logging.DEBUG if settings.log.debug_enable else level
|
||||
if not os.path.isdir("data"):
|
||||
os.mkdir("data")
|
||||
if reset and os.path.isfile(LOG_PATH):
|
||||
os.remove(LOG_PATH)
|
||||
logging.addLevelName(logging.DEBUG, "DEBUG:")
|
||||
logging.addLevelName(logging.INFO, "INFO:")
|
||||
logging.addLevelName(logging.WARNING, "WARNING:")
|
||||
LOGGING_FORMAT = "[%(asctime)s] %(levelname)-8s %(message)s"
|
||||
TIME_FORMAT = "%Y-%m-%d %H:%M:%S"
|
||||
logging.basicConfig(
|
||||
level=level,
|
||||
format=LOGGING_FORMAT,
|
||||
datefmt=TIME_FORMAT,
|
||||
encoding="utf-8",
|
||||
handlers=[
|
||||
logging.FileHandler(LOG_PATH, encoding="utf-8"),
|
||||
logging.StreamHandler(),
|
||||
]
|
||||
],
|
||||
)
|
||||
|
||||
@@ -1,72 +0,0 @@
|
||||
[loggers]
|
||||
keys=root, gunicorn.error, gunicorn.access,uvicorn.error,uvicorn.access
|
||||
|
||||
[handlers]
|
||||
keys=console, error_file, access_file, accesscustom
|
||||
|
||||
[formatters]
|
||||
keys=generic, access, AccessFormatter
|
||||
|
||||
[logger_root]
|
||||
level=INFO
|
||||
handlers=console
|
||||
propagate=1
|
||||
|
||||
[logger_gunicorn.error]
|
||||
level=INFO
|
||||
handlers=error_file
|
||||
propagate=0
|
||||
qualname=gunicorn.error
|
||||
|
||||
[logger_gunicorn.access]
|
||||
level=INFO
|
||||
handlers=accesscustom
|
||||
propagate=0
|
||||
qualname=gunicorn.access
|
||||
|
||||
[logger_uvicorn.error]
|
||||
level=INFO
|
||||
handlers=error_file
|
||||
propagate=0
|
||||
qualname=uvicorn.error
|
||||
|
||||
[logger_uvicorn.access]
|
||||
level=INFO
|
||||
handlers=accesscustom
|
||||
propagate=0
|
||||
qualname=uvicorn.access
|
||||
|
||||
[handler_console]
|
||||
class=StreamHandler
|
||||
formatter=generic
|
||||
args=(sys.stdout, )
|
||||
|
||||
[handler_error_file]
|
||||
class=StreamHandler
|
||||
formatter=generic
|
||||
args=(sys.stdout, )
|
||||
|
||||
[handler_access_file]
|
||||
class=StreamHandler
|
||||
formatter=access
|
||||
args=(sys.stdout, )
|
||||
|
||||
[handler_accesscustom]
|
||||
class=StreamHandler
|
||||
formatter=AccessFormatter
|
||||
args=(sys.stdout, )
|
||||
|
||||
[formatter_generic]
|
||||
format=%(levelname)s: %(message)s
|
||||
datefmt=%Y-%m-%dT%H:%M:%S
|
||||
class=uvicorn.logging.DefaultFormatter
|
||||
|
||||
[formatter_access]
|
||||
format=%(levelname)s: %(message)s
|
||||
datefmt=%Y-%m-%dT%H:%M:%S
|
||||
class=customlogger.CustomFormatter
|
||||
|
||||
[formatter_AccessFormatter]
|
||||
format={"event":"access_log","ip":"%(h)s","status":"%(s)s","method":"%(m)s","path":"%(U)s","referer":"%(f)s","x_session_id":"%(x-session-id)s","x_google_id":"%(x-google-id)s","x_server_time":"%(x-server-time)s","agent":"%(a)s"}
|
||||
datefmt=%Y-%m-%dT%H:%M:%S
|
||||
class=customlogger.CustomFormatter
|
||||
@@ -12,4 +12,4 @@ def parse():
|
||||
)
|
||||
|
||||
parser.add_argument("-d", "--debug", action="store_true", help="debug mode")
|
||||
return parser.parse_args()
|
||||
return parser.parse_args()
|
||||
|
||||
38
src/module/conf/uvicorn_logging.py
Normal file
38
src/module/conf/uvicorn_logging.py
Normal file
@@ -0,0 +1,38 @@
|
||||
from .log import LOG_PATH
|
||||
|
||||
logging_config = {
|
||||
"version": 1,
|
||||
"disable_existing_loggers": False,
|
||||
"formatters": {
|
||||
"default": {
|
||||
"format": "[%(asctime)s] %(levelname)-8s %(message)s",
|
||||
"datefmt": "%Y-%m-%d %H:%M:%S",
|
||||
}
|
||||
},
|
||||
"handlers": {
|
||||
"file": {
|
||||
"class": "logging.FileHandler",
|
||||
"filename": LOG_PATH,
|
||||
"formatter": "default",
|
||||
"encoding": "utf-8",
|
||||
},
|
||||
"console": {
|
||||
"class": "logging.StreamHandler",
|
||||
"formatter": "default",
|
||||
},
|
||||
},
|
||||
"loggers": {
|
||||
"uvicorn": {
|
||||
"handlers": ["console"],
|
||||
"level": "INFO",
|
||||
},
|
||||
"uvicorn.error": {
|
||||
"level": "WARNING",
|
||||
},
|
||||
"uvicorn.access": {
|
||||
"handlers": ["console"],
|
||||
"level": "DEBUG",
|
||||
"propagate": False,
|
||||
},
|
||||
},
|
||||
}
|
||||
@@ -1,2 +1 @@
|
||||
from .download_client import DownloadClient
|
||||
from .api_func import APIProcess
|
||||
from .program import Program
|
||||
|
||||
@@ -1,101 +0,0 @@
|
||||
import re
|
||||
import logging
|
||||
|
||||
from module.core import DownloadClient
|
||||
from module.manager import FullSeasonGet
|
||||
from module.rss import RSSAnalyser
|
||||
from module.utils import json_config
|
||||
from module.conf import DATA_PATH
|
||||
from module.conf.config import save_config_to_file, CONFIG_PATH
|
||||
from module.models import Config
|
||||
from module.network import RequestContent
|
||||
|
||||
from module.ab_decorator import api_failed
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class APIProcess:
|
||||
def __init__(self, settings: Config):
|
||||
self._rss_analyser = RSSAnalyser(settings)
|
||||
self._client = DownloadClient(settings)
|
||||
self._full_season_get = FullSeasonGet(settings)
|
||||
self._custom_url = settings.rss_parser.custom_url
|
||||
|
||||
def link_process(self, link):
|
||||
return self._rss_analyser.rss_to_data(link, _filter=False)
|
||||
|
||||
@api_failed
|
||||
def download_collection(self, link):
|
||||
if not self._client.authed:
|
||||
self._client.auth()
|
||||
data = self.link_process(link)
|
||||
self._full_season_get.download_collection(data, link, self._client)
|
||||
return data
|
||||
|
||||
@api_failed
|
||||
def add_subscribe(self, link):
|
||||
if not self._client.authed:
|
||||
self._client.auth()
|
||||
data = self.link_process(link)
|
||||
self._client.add_rss_feed(link, data.official_title)
|
||||
self._client.set_rule(data, link)
|
||||
return data
|
||||
|
||||
@staticmethod
|
||||
def reset_rule():
|
||||
data = json_config.load(DATA_PATH)
|
||||
data["bangumi_info"] = []
|
||||
json_config.save(DATA_PATH, data)
|
||||
return "Success"
|
||||
|
||||
@staticmethod
|
||||
def remove_rule(_id: int):
|
||||
datas = json_config.load(DATA_PATH)["bangumi_info"]
|
||||
for data in datas:
|
||||
if data["id"] == _id:
|
||||
datas.remove(data)
|
||||
break
|
||||
json_config.save(DATA_PATH, datas)
|
||||
return "Success"
|
||||
|
||||
@staticmethod
|
||||
def add_rule(title, season):
|
||||
data = json_config.load(DATA_PATH)
|
||||
extra_data = {
|
||||
"official_title": title,
|
||||
"title_raw": title,
|
||||
"season": season,
|
||||
"season_raw": "",
|
||||
"dpi": "",
|
||||
"group": "",
|
||||
"eps_complete": False,
|
||||
"added": False,
|
||||
}
|
||||
data["bangumi_info"].append(extra_data)
|
||||
json_config.save(DATA_PATH, data)
|
||||
return "Success"
|
||||
|
||||
@staticmethod
|
||||
def update_config(config: Config):
|
||||
save_config_to_file(config, CONFIG_PATH)
|
||||
return {"message": "Success"}
|
||||
|
||||
@staticmethod
|
||||
def get_config() -> dict:
|
||||
return json_config.load(CONFIG_PATH)
|
||||
|
||||
def get_rss(self, full_path: str):
|
||||
url = f"https://mikanani.me/RSS/{full_path}"
|
||||
custom_url = self._custom_url
|
||||
if "://" not in custom_url:
|
||||
custom_url = f"https://{custom_url}"
|
||||
with RequestContent() as request:
|
||||
content = request.get_html(url)
|
||||
return re.sub(r"https://mikanani.me", custom_url, content)
|
||||
|
||||
@staticmethod
|
||||
def get_torrent(full_path):
|
||||
url = f"https://mikanani.me/Download/{full_path}"
|
||||
with RequestContent() as request:
|
||||
return request.get_content(url)
|
||||
@@ -1,125 +0,0 @@
|
||||
import re
|
||||
import logging
|
||||
import os
|
||||
|
||||
from module.downloader import getClient
|
||||
from module.models import BangumiData, Config
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class DownloadClient:
|
||||
def __init__(self, settings: Config):
|
||||
self.client = getClient(settings)
|
||||
self.authed = False
|
||||
self.download_path = settings.downloader.path
|
||||
self.group_tag = settings.bangumi_manage.group_tag
|
||||
|
||||
def auth(self):
|
||||
self.client.auth()
|
||||
self.authed = True
|
||||
|
||||
def init_downloader(self):
|
||||
prefs = {
|
||||
"rss_auto_downloading_enabled": True,
|
||||
"rss_max_articles_per_feed": 500,
|
||||
"rss_processing_enabled": True,
|
||||
"rss_refresh_interval": 30,
|
||||
}
|
||||
self.client.prefs_init(prefs=prefs)
|
||||
try:
|
||||
self.client.add_category("BangumiCollection")
|
||||
except Exception as e:
|
||||
logger.warning("Cannot add new category, maybe already exists.")
|
||||
logger.debug(e)
|
||||
if self.download_path == "":
|
||||
prefs = self.client.get_app_prefs()
|
||||
self.download_path = os.path.join(prefs["save_path"], "Bangumi")
|
||||
|
||||
def set_rule(self, info: BangumiData, rss_link):
|
||||
official_name, raw_name, season, group = info.official_title, info.title_raw, info.season, info.group
|
||||
rule = {
|
||||
"enable": True,
|
||||
"mustContain": raw_name,
|
||||
"mustNotContain": "|".join(info.filter),
|
||||
"useRegex": True,
|
||||
"episodeFilter": "",
|
||||
"smartFilter": False,
|
||||
"previouslyMatchedEpisodes": [],
|
||||
"affectedFeeds": [rss_link],
|
||||
"ignoreDays": 0,
|
||||
"lastMatch": "",
|
||||
"addPaused": False,
|
||||
"assignedCategory": "Bangumi",
|
||||
"savePath": str(
|
||||
os.path.join(
|
||||
self.download_path,
|
||||
re.sub(r"[:/.]", " ", official_name).strip(),
|
||||
f"Season {season}",
|
||||
)
|
||||
),
|
||||
}
|
||||
rule_name = f"[{group}] {official_name}" if self.group_tag else official_name
|
||||
self.client.rss_set_rule(rule_name=f"{rule_name} S{season}", rule_def=rule)
|
||||
logger.info(f"Add {official_name} Season {season}")
|
||||
|
||||
def rss_feed(self, rss_link, item_path="Mikan_RSS"):
|
||||
# TODO: 定时刷新 RSS
|
||||
self.client.rss_add_feed(url=rss_link, item_path=item_path)
|
||||
|
||||
def add_collection_feed(self, rss_link, item_path):
|
||||
self.client.rss_add_feed(url=rss_link, item_path=item_path)
|
||||
logger.info("Add Collection RSS Feed successfully.")
|
||||
|
||||
def add_rules(self, bangumi_info: list[BangumiData], rss_link: str):
|
||||
logger.debug("Start adding rules.")
|
||||
for info in bangumi_info:
|
||||
if not info.added:
|
||||
self.set_rule(info, rss_link)
|
||||
info.added = True
|
||||
logger.debug("Finished.")
|
||||
|
||||
def get_torrent_info(self, category="Bangumi"):
|
||||
return self.client.torrents_info(
|
||||
status_filter="completed", category=category
|
||||
)
|
||||
|
||||
def rename_torrent_file(self, _hash, old_path, new_path):
|
||||
self.client.torrents_rename_file(
|
||||
torrent_hash=_hash, old_path=old_path, new_path=new_path
|
||||
)
|
||||
logger.info(f"{old_path} >> {new_path}")
|
||||
|
||||
def delete_torrent(self, hashes):
|
||||
self.client.torrents_delete(
|
||||
hashes
|
||||
)
|
||||
logger.info(f"Remove bad torrents.")
|
||||
|
||||
def add_torrent(self, torrent: dict):
|
||||
self.client.torrents_add(
|
||||
urls=torrent["url"],
|
||||
save_path=torrent["save_path"],
|
||||
category="Bangumi"
|
||||
)
|
||||
|
||||
def move_torrent(self, hashes, location):
|
||||
self.client.move_torrent(
|
||||
hashes=hashes,
|
||||
new_location=location
|
||||
)
|
||||
|
||||
def add_rss_feed(self, rss_link, item_path):
|
||||
self.client.rss_add_feed(url=rss_link, item_path=item_path)
|
||||
logger.info("Add RSS Feed successfully.")
|
||||
|
||||
def get_download_rules(self):
|
||||
return self.client.get_download_rule()
|
||||
|
||||
def get_torrent_path(self, hashes):
|
||||
return self.client.get_torrent_path(hashes)
|
||||
|
||||
def set_category(self, hashes, category):
|
||||
self.client.set_category(hashes, category)
|
||||
|
||||
@@ -1,25 +0,0 @@
|
||||
import re
|
||||
import logging
|
||||
import xml.etree.ElementTree
|
||||
from typing import Tuple
|
||||
|
||||
from module.conf import settings
|
||||
from module.utils import json_config
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class RSSFilter:
|
||||
def __init__(self):
|
||||
self.filter_rule = json_config.load(settings.filter_rule)
|
||||
|
||||
def filter(self, item: xml.etree.ElementTree.Element) -> Tuple[bool, str]:
|
||||
title = item.find('title').text
|
||||
torrent = item.find("enclosure").attrib['url']
|
||||
download = False
|
||||
for rule in self.filter_rule:
|
||||
if re.search(rule["include"], title):
|
||||
if not re.search(rule["exclude"], title):
|
||||
download = True
|
||||
logger.debug(f"{title} added")
|
||||
return download, torrent
|
||||
61
src/module/core/program.py
Normal file
61
src/module/core/program.py
Normal file
@@ -0,0 +1,61 @@
|
||||
import logging
|
||||
|
||||
from .sub_thread import RenameThread, RSSThread
|
||||
from .rss_feed import add_rss_feed
|
||||
|
||||
from module.conf import settings, VERSION
|
||||
from module.update import data_migration
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class Program(RenameThread, RSSThread):
|
||||
@staticmethod
|
||||
def __start_info():
|
||||
with open("icon", "r") as f:
|
||||
for line in f.readlines():
|
||||
logger.info(line.strip("\n"))
|
||||
logger.info(
|
||||
f"Version {VERSION} Author: EstrellaXD Twitter: https://twitter.com/Estrella_Pan"
|
||||
)
|
||||
logger.info("GitHub: https://github.com/EstrellaXD/Auto_Bangumi/")
|
||||
logger.info("Starting AutoBangumi...")
|
||||
|
||||
def startup(self):
|
||||
self.__start_info()
|
||||
if self.first_run:
|
||||
logger.info("First run detected, please configure the program in webui.")
|
||||
return {"status": "First run detected."}
|
||||
if self.legacy_data:
|
||||
logger.info(
|
||||
"Legacy data detected, starting data migration, please wait patiently."
|
||||
)
|
||||
data_migration()
|
||||
add_rss_feed()
|
||||
self.start()
|
||||
|
||||
def start(self):
|
||||
if self.first_run:
|
||||
return {"status": "Not ready to start."}
|
||||
self.stop_event.clear()
|
||||
settings.load()
|
||||
if self.enable_renamer:
|
||||
self.rename_start()
|
||||
if self.enable_rss:
|
||||
self.rss_start()
|
||||
logger.info("Program running.")
|
||||
return {"status": "Program started."}
|
||||
|
||||
def stop(self):
|
||||
if self.is_running:
|
||||
self.stop_event.set()
|
||||
self.rename_stop()
|
||||
self.rss_stop()
|
||||
return {"status": "Program stopped."}
|
||||
else:
|
||||
return {"status": "Program is not running."}
|
||||
|
||||
def restart(self):
|
||||
self.stop()
|
||||
self.start()
|
||||
return {"status": "Program restarted."}
|
||||
34
src/module/core/rss_feed.py
Normal file
34
src/module/core/rss_feed.py
Normal file
@@ -0,0 +1,34 @@
|
||||
import logging
|
||||
|
||||
from module.downloader import DownloadClient
|
||||
from module.conf import settings
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def add_rss_feed():
|
||||
with DownloadClient() as client:
|
||||
# Check Feed if exists
|
||||
add = True
|
||||
remove = False
|
||||
feeds = client.get_rss_feed()
|
||||
for item_path, value in feeds.items():
|
||||
if value.url == settings.rss_link:
|
||||
add = False
|
||||
break
|
||||
elif item_path == "Mikan_RSS":
|
||||
remove = True
|
||||
if remove:
|
||||
client.remove_rss_feed("Mikan_RSS")
|
||||
logger.info("Remove Old RSS Feed: Mikan_RSS")
|
||||
# Add Feed
|
||||
if add:
|
||||
client.add_rss_feed(settings.rss_link)
|
||||
logger.info(f"Add RSS Feed: {settings.rss_link}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
from module.conf import setup_logger
|
||||
|
||||
setup_logger()
|
||||
add_rss_feed()
|
||||
54
src/module/core/status.py
Normal file
54
src/module/core/status.py
Normal file
@@ -0,0 +1,54 @@
|
||||
import os.path
|
||||
import threading
|
||||
import asyncio
|
||||
|
||||
from module.checker import Checker
|
||||
|
||||
|
||||
class ProgramStatus(Checker):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.stop_event = threading.Event()
|
||||
self.lock = threading.Lock()
|
||||
self._downloader_status = False
|
||||
self._torrents_status = False
|
||||
self.event = asyncio.Event()
|
||||
|
||||
@property
|
||||
def is_running(self):
|
||||
if self.stop_event.is_set() or self.check_first_run():
|
||||
return False
|
||||
else:
|
||||
return True
|
||||
|
||||
@property
|
||||
def is_stopped(self):
|
||||
return self.stop_event.is_set()
|
||||
|
||||
@property
|
||||
def downloader_status(self):
|
||||
if not self._downloader_status:
|
||||
self._downloader_status = self.check_downloader()
|
||||
return self._downloader_status
|
||||
|
||||
@property
|
||||
def torrents_status(self):
|
||||
if not self._torrents_status:
|
||||
self._torrents_status = self.check_torrents()
|
||||
return self._torrents_status
|
||||
|
||||
@property
|
||||
def enable_rss(self):
|
||||
return self.check_analyser()
|
||||
|
||||
@property
|
||||
def enable_renamer(self):
|
||||
return self.check_renamer()
|
||||
|
||||
@property
|
||||
def first_run(self):
|
||||
return self.check_first_run()
|
||||
|
||||
@property
|
||||
def legacy_data(self):
|
||||
return os.path.exists("data/data.json")
|
||||
84
src/module/core/sub_thread.py
Normal file
84
src/module/core/sub_thread.py
Normal file
@@ -0,0 +1,84 @@
|
||||
import threading
|
||||
import time
|
||||
|
||||
from .status import ProgramStatus
|
||||
|
||||
from module.rss import analyser
|
||||
from module.downloader import DownloadClient
|
||||
from module.manager import Renamer, eps_complete
|
||||
from module.notification import PostNotification
|
||||
from module.database import BangumiDatabase
|
||||
from module.conf import settings
|
||||
|
||||
|
||||
class RSSThread(ProgramStatus):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self._rss_thread = threading.Thread(
|
||||
target=self.rss_loop,
|
||||
)
|
||||
|
||||
def rss_loop(self):
|
||||
while not self.stop_event.is_set():
|
||||
# Analyse RSS
|
||||
with BangumiDatabase() as db:
|
||||
new_data = analyser.rss_to_data(rss_link=settings.rss_link, database=db)
|
||||
if new_data:
|
||||
db.insert_list(new_data)
|
||||
bangumi_list = db.not_added()
|
||||
if bangumi_list:
|
||||
with DownloadClient() as client:
|
||||
client.set_rules(bangumi_list)
|
||||
db.update_list(bangumi_list)
|
||||
if settings.bangumi_manage.eps_complete:
|
||||
eps_complete()
|
||||
self.stop_event.wait(settings.program.rss_time)
|
||||
|
||||
def rss_start(self):
|
||||
self.rss_thread.start()
|
||||
|
||||
def rss_stop(self):
|
||||
if self._rss_thread.is_alive():
|
||||
self._rss_thread.join()
|
||||
|
||||
@property
|
||||
def rss_thread(self):
|
||||
if not self._rss_thread.is_alive():
|
||||
self._rss_thread = threading.Thread(
|
||||
target=self.rss_loop,
|
||||
)
|
||||
return self._rss_thread
|
||||
|
||||
|
||||
class RenameThread(ProgramStatus):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self._rename_thread = threading.Thread(
|
||||
target=self.rename_loop,
|
||||
)
|
||||
|
||||
def rename_loop(self):
|
||||
while not self.stop_event.is_set():
|
||||
with Renamer() as renamer:
|
||||
renamed_info = renamer.rename()
|
||||
if settings.notification.enable:
|
||||
with PostNotification() as notifier:
|
||||
for info in renamed_info:
|
||||
notifier.send_msg(info)
|
||||
time.sleep(2)
|
||||
self.stop_event.wait(settings.program.rename_time)
|
||||
|
||||
def rename_start(self):
|
||||
self.rename_thread.start()
|
||||
|
||||
def rename_stop(self):
|
||||
if self._rename_thread.is_alive():
|
||||
self._rename_thread.join()
|
||||
|
||||
@property
|
||||
def rename_thread(self):
|
||||
if not self._rename_thread.is_alive():
|
||||
self._rename_thread = threading.Thread(
|
||||
target=self.rename_loop,
|
||||
)
|
||||
return self._rename_thread
|
||||
1
src/module/database/__init__.py
Normal file
1
src/module/database/__init__.py
Normal file
@@ -0,0 +1 @@
|
||||
from .bangumi import BangumiDatabase
|
||||
235
src/module/database/bangumi.py
Normal file
235
src/module/database/bangumi.py
Normal file
@@ -0,0 +1,235 @@
|
||||
import logging
|
||||
|
||||
from module.database.connector import DataConnector
|
||||
from module.models import BangumiData
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class BangumiDatabase(DataConnector):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.__table_name = "bangumi"
|
||||
|
||||
def update_table(self):
|
||||
db_data = self.__data_to_db(BangumiData())
|
||||
self._update_table(self.__table_name, db_data)
|
||||
|
||||
@staticmethod
|
||||
def __data_to_db(data: BangumiData) -> dict:
|
||||
db_data = data.dict()
|
||||
for key, value in db_data.items():
|
||||
if isinstance(value, bool):
|
||||
db_data[key] = int(value)
|
||||
elif isinstance(value, list):
|
||||
db_data[key] = ",".join(value)
|
||||
return db_data
|
||||
|
||||
@staticmethod
|
||||
def __db_to_data(db_data: dict) -> BangumiData:
|
||||
for key, item in db_data.items():
|
||||
if isinstance(item, int):
|
||||
if key not in ["id", "offset", "season", "year"]:
|
||||
db_data[key] = bool(item)
|
||||
elif key in ["filter", "rss_link"]:
|
||||
db_data[key] = item.split(",")
|
||||
return BangumiData(**db_data)
|
||||
|
||||
def __fetch_data(self) -> list[BangumiData]:
|
||||
values = self._cursor.fetchall()
|
||||
if values is None:
|
||||
return []
|
||||
keys = [x[0] for x in self._cursor.description]
|
||||
dict_data = [dict(zip(keys, value)) for value in values]
|
||||
return [self.__db_to_data(x) for x in dict_data]
|
||||
|
||||
def insert(self, data: BangumiData):
|
||||
if self.__check_exist(data):
|
||||
self.update_one(data)
|
||||
else:
|
||||
db_data = self.__data_to_db(data)
|
||||
db_data["id"] = self.gen_id()
|
||||
self._insert(db_data=db_data, table_name=self.__table_name)
|
||||
logger.debug(f"[Database] Insert {data.official_title} into database.")
|
||||
|
||||
def insert_list(self, data: list[BangumiData]):
|
||||
_id = self.gen_id()
|
||||
for i, item in enumerate(data):
|
||||
item.id = _id + i
|
||||
data_list = [self.__data_to_db(x) for x in data]
|
||||
self._insert_list(data_list=data_list, table_name=self.__table_name)
|
||||
logger.debug(f"[Database] Insert {len(data)} bangumi into database.")
|
||||
|
||||
def update_one(self, data: BangumiData) -> bool:
|
||||
db_data = self.__data_to_db(data)
|
||||
return self._update(db_data=db_data, table_name=self.__table_name)
|
||||
|
||||
def update_list(self, data: list[BangumiData]):
|
||||
data_list = [self.__data_to_db(x) for x in data]
|
||||
self._update_list(data_list=data_list, table_name=self.__table_name)
|
||||
|
||||
def update_rss(self, title_raw, rss_set: str):
|
||||
# Update rss and added
|
||||
self._cursor.execute(
|
||||
"""
|
||||
UPDATE bangumi
|
||||
SET rss_link = :rss_link, added = 0
|
||||
WHERE title_raw = :title_raw
|
||||
""",
|
||||
{"rss_link": rss_set, "title_raw": title_raw},
|
||||
)
|
||||
self._conn.commit()
|
||||
logger.debug(f"[Database] Update {title_raw} rss_link to {rss_set}.")
|
||||
|
||||
def update_poster(self, title_raw, poster_link: str):
|
||||
self._cursor.execute(
|
||||
"""
|
||||
UPDATE bangumi
|
||||
SET poster_link = :poster_link
|
||||
WHERE title_raw = :title_raw
|
||||
""",
|
||||
{"poster_link": poster_link, "title_raw": title_raw},
|
||||
)
|
||||
self._conn.commit()
|
||||
logger.debug(f"[Database] Update {title_raw} poster_link to {poster_link}.")
|
||||
|
||||
def delete_one(self, _id: int) -> bool:
|
||||
self._cursor.execute(
|
||||
"""
|
||||
DELETE FROM bangumi WHERE id = :id
|
||||
""",
|
||||
{"id": _id},
|
||||
)
|
||||
self._conn.commit()
|
||||
logger.debug(f"[Database] Delete bangumi id: {_id}.")
|
||||
return self._cursor.rowcount == 1
|
||||
|
||||
def delete_all(self):
|
||||
self._delete_all(self.__table_name)
|
||||
|
||||
def search_all(self) -> list[BangumiData]:
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT * FROM bangumi
|
||||
"""
|
||||
)
|
||||
return self.__fetch_data()
|
||||
|
||||
def search_id(self, _id: int) -> BangumiData | None:
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT * FROM bangumi WHERE id = :id
|
||||
""",
|
||||
{"id": _id},
|
||||
)
|
||||
values = self._cursor.fetchone()
|
||||
if values is None:
|
||||
return None
|
||||
keys = [x[0] for x in self._cursor.description]
|
||||
dict_data = dict(zip(keys, values))
|
||||
return self.__db_to_data(dict_data)
|
||||
|
||||
def search_official_title(self, official_title: str) -> BangumiData | None:
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT * FROM bangumi WHERE official_title = :official_title
|
||||
""",
|
||||
{"official_title": official_title},
|
||||
)
|
||||
values = self._cursor.fetchone()
|
||||
if values is None:
|
||||
return None
|
||||
keys = [x[0] for x in self._cursor.description]
|
||||
dict_data = dict(zip(keys, values))
|
||||
return self.__db_to_data(dict_data)
|
||||
|
||||
def match_poster(self, bangumi_name: str) -> str:
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT official_title, poster_link
|
||||
FROM bangumi
|
||||
WHERE INSTR(:bangumi_name, official_title) > 0
|
||||
""",
|
||||
{"bangumi_name": bangumi_name},
|
||||
)
|
||||
data = self._cursor.fetchone()
|
||||
if not data:
|
||||
return ""
|
||||
official_title, poster_link = data
|
||||
if not poster_link:
|
||||
return ""
|
||||
return poster_link
|
||||
|
||||
def match_list(self, torrent_list: list, rss_link: str) -> list:
|
||||
# Match title_raw in database
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT title_raw, rss_link, poster_link FROM bangumi
|
||||
"""
|
||||
)
|
||||
data = self._cursor.fetchall()
|
||||
if not data:
|
||||
return torrent_list
|
||||
# Match title
|
||||
i = 0
|
||||
while i < len(torrent_list):
|
||||
torrent = torrent_list[i]
|
||||
for title_raw, rss_set, poster_link in data:
|
||||
if title_raw in torrent.name:
|
||||
if rss_link not in rss_set:
|
||||
rss_set += "," + rss_link
|
||||
self.update_rss(title_raw, rss_set)
|
||||
if not poster_link:
|
||||
self.update_poster(title_raw, torrent.poster_link)
|
||||
torrent_list.pop(i)
|
||||
break
|
||||
else:
|
||||
i += 1
|
||||
return torrent_list
|
||||
|
||||
def not_complete(self) -> list[BangumiData]:
|
||||
# Find eps_complete = False
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT * FROM bangumi WHERE eps_collect = 0
|
||||
"""
|
||||
)
|
||||
return self.__fetch_data()
|
||||
|
||||
def not_added(self) -> list[BangumiData]:
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT * FROM bangumi
|
||||
WHERE added = 0 OR rule_name IS NULL OR save_path IS NULL
|
||||
"""
|
||||
)
|
||||
return self.__fetch_data()
|
||||
|
||||
def gen_id(self) -> int:
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT id FROM bangumi ORDER BY id DESC LIMIT 1
|
||||
"""
|
||||
)
|
||||
data = self._cursor.fetchone()
|
||||
if data is None:
|
||||
return 1
|
||||
return data[0] + 1
|
||||
|
||||
def __check_exist(self, data: BangumiData):
|
||||
self._cursor.execute(
|
||||
"""
|
||||
SELECT * FROM bangumi WHERE official_title = :official_title
|
||||
""",
|
||||
{"official_title": data.official_title},
|
||||
)
|
||||
values = self._cursor.fetchone()
|
||||
if values is None:
|
||||
return False
|
||||
return True
|
||||
|
||||
def __check_list_exist(self, data_list: list[BangumiData]):
|
||||
for data in data_list:
|
||||
if self.__check_exist(data):
|
||||
return True
|
||||
return False
|
||||
128
src/module/database/connector.py
Normal file
128
src/module/database/connector.py
Normal file
@@ -0,0 +1,128 @@
|
||||
import os
|
||||
import sqlite3
|
||||
import logging
|
||||
|
||||
from module.conf import DATA_PATH
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class DataConnector:
|
||||
def __init__(self):
|
||||
# Create folder if not exists
|
||||
if not os.path.exists(os.path.dirname(DATA_PATH)):
|
||||
os.makedirs(os.path.dirname(DATA_PATH))
|
||||
self._conn = sqlite3.connect(DATA_PATH)
|
||||
self._cursor = self._conn.cursor()
|
||||
|
||||
def _update_table(self, table_name: str, db_data: dict):
|
||||
columns = ", ".join(
|
||||
[
|
||||
f"{key} {self.__python_to_sqlite_type(value)}"
|
||||
for key, value in db_data.items()
|
||||
]
|
||||
)
|
||||
create_table_sql = f"CREATE TABLE IF NOT EXISTS {table_name} ({columns});"
|
||||
self._cursor.execute(create_table_sql)
|
||||
self._cursor.execute(f"PRAGMA table_info({table_name})")
|
||||
existing_columns = {
|
||||
column_info[1]: column_info for column_info in self._cursor.fetchall()
|
||||
}
|
||||
for key, value in db_data.items():
|
||||
if key not in existing_columns:
|
||||
insert_column = self.__python_to_sqlite_type(value)
|
||||
if value is None:
|
||||
value = "NULL"
|
||||
add_column_sql = f"ALTER TABLE {table_name} ADD COLUMN {key} {insert_column} DEFAULT {value};"
|
||||
self._cursor.execute(add_column_sql)
|
||||
self._conn.commit()
|
||||
logger.debug(f"Create / Update table {table_name}.")
|
||||
|
||||
def _insert(self, table_name: str, db_data: dict):
|
||||
columns = ", ".join(db_data.keys())
|
||||
values = ", ".join([f":{key}" for key in db_data.keys()])
|
||||
self._cursor.execute(
|
||||
f"INSERT INTO {table_name} ({columns}) VALUES ({values})", db_data
|
||||
)
|
||||
self._conn.commit()
|
||||
|
||||
def _insert_list(self, table_name: str, data_list: list[dict]):
|
||||
columns = ", ".join(data_list[0].keys())
|
||||
values = ", ".join([f":{key}" for key in data_list[0].keys()])
|
||||
self._cursor.executemany(
|
||||
f"INSERT INTO {table_name} ({columns}) VALUES ({values})", data_list
|
||||
)
|
||||
self._conn.commit()
|
||||
|
||||
def _select(self, keys: list[str], table_name: str, condition: str = None) -> dict:
|
||||
if condition is None:
|
||||
self._cursor.execute(f"SELECT {', '.join(keys)} FROM {table_name}")
|
||||
else:
|
||||
self._cursor.execute(
|
||||
f"SELECT {', '.join(keys)} FROM {table_name} WHERE {condition}"
|
||||
)
|
||||
return dict(zip(keys, self._cursor.fetchone()))
|
||||
|
||||
def _update(self, table_name: str, db_data: dict):
|
||||
_id = db_data.get("id")
|
||||
if _id is None:
|
||||
raise ValueError("No _id in db_data.")
|
||||
set_sql = ", ".join([f"{key} = :{key}" for key in db_data.keys()])
|
||||
self._cursor.execute(
|
||||
f"UPDATE {table_name} SET {set_sql} WHERE id = {_id}", db_data
|
||||
)
|
||||
self._conn.commit()
|
||||
return self._cursor.rowcount == 1
|
||||
|
||||
def _update_list(self, table_name: str, data_list: list[dict]):
|
||||
if len(data_list) == 0:
|
||||
return
|
||||
set_sql = ", ".join(
|
||||
[f"{key} = :{key}" for key in data_list[0].keys() if key != "id"]
|
||||
)
|
||||
self._cursor.executemany(
|
||||
f"UPDATE {table_name} SET {set_sql} WHERE id = :id", data_list
|
||||
)
|
||||
self._conn.commit()
|
||||
|
||||
def _update_section(self, table_name: str, location: dict, update_dict: dict):
|
||||
set_sql = ", ".join([f"{key} = :{key}" for key in update_dict.keys()])
|
||||
sql_loc = f"{location['key']} = {location['value']}"
|
||||
self._cursor.execute(
|
||||
f"UPDATE {table_name} SET {set_sql} WHERE {sql_loc}", update_dict
|
||||
)
|
||||
self._conn.commit()
|
||||
|
||||
def _delete_all(self, table_name: str):
|
||||
self._cursor.execute(f"DELETE FROM {table_name}")
|
||||
self._conn.commit()
|
||||
|
||||
def _table_exists(self, table_name: str) -> bool:
|
||||
self._cursor.execute(
|
||||
f"SELECT name FROM sqlite_master WHERE type='table' AND name=?;",
|
||||
(table_name,),
|
||||
)
|
||||
return len(self._cursor.fetchall()) == 1
|
||||
|
||||
@staticmethod
|
||||
def __python_to_sqlite_type(value) -> str:
|
||||
if isinstance(value, int):
|
||||
return "INTEGER NOT NULL"
|
||||
elif isinstance(value, float):
|
||||
return "REAL NOT NULL"
|
||||
elif isinstance(value, str):
|
||||
return "TEXT NOT NULL"
|
||||
elif isinstance(value, bool):
|
||||
return "INTEGER NOT NULL"
|
||||
elif isinstance(value, list):
|
||||
return "TEXT NOT NULL"
|
||||
elif value is None:
|
||||
return "TEXT"
|
||||
else:
|
||||
raise ValueError(f"Unsupported data type: {type(value)}")
|
||||
|
||||
def __enter__(self):
|
||||
return self
|
||||
|
||||
def __exit__(self, exc_type, exc_val, exc_tb):
|
||||
self._conn.close()
|
||||
47
src/module/database/torrent.py
Normal file
47
src/module/database/torrent.py
Normal file
@@ -0,0 +1,47 @@
|
||||
import logging
|
||||
|
||||
from .connector import DataConnector
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class TorrentDatabase(DataConnector):
|
||||
def update_table(self):
|
||||
table_name = "torrent"
|
||||
db_data = self.__data_to_db()
|
||||
self._update_table(table_name, db_data)
|
||||
|
||||
def __data_to_db(self, data: SaveTorrent):
|
||||
db_data = data.dict()
|
||||
for key, value in db_data.items():
|
||||
if isinstance(value, bool):
|
||||
db_data[key] = int(value)
|
||||
elif isinstance(value, list):
|
||||
db_data[key] = ",".join(value)
|
||||
return db_data
|
||||
|
||||
def __db_to_data(self, db_data: dict):
|
||||
for key, item in db_data.items():
|
||||
if isinstance(item, int):
|
||||
if key not in ["id", "offset", "season", "year"]:
|
||||
db_data[key] = bool(item)
|
||||
elif key in ["filter", "rss_link"]:
|
||||
db_data[key] = item.split(",")
|
||||
return SaveTorrent(**db_data)
|
||||
|
||||
def if_downloaded(self, torrent_url: str, torrent_name: str) -> bool:
|
||||
self._cursor.execute(
|
||||
"SELECT * FROM torrent WHERE torrent_url = ? OR torrent_name = ?",
|
||||
(torrent_url, torrent_name),
|
||||
)
|
||||
return bool(self._cursor.fetchone())
|
||||
|
||||
def insert(self, data: SaveTorrent):
|
||||
db_data = self.__data_to_db(data)
|
||||
columns = ", ".join(db_data.keys())
|
||||
values = ", ".join([f":{key}" for key in db_data.keys()])
|
||||
self._cursor.execute(
|
||||
f"INSERT INTO torrent ({columns}) VALUES ({values})", db_data
|
||||
)
|
||||
logger.debug(f"Add {data.torrent_name} into database.")
|
||||
self._conn.commit()
|
||||
74
src/module/database/user.py
Normal file
74
src/module/database/user.py
Normal file
@@ -0,0 +1,74 @@
|
||||
import logging
|
||||
|
||||
from fastapi import HTTPException
|
||||
|
||||
from module.database.connector import DataConnector
|
||||
|
||||
from module.security.jwt import get_password_hash, verify_password
|
||||
from module.models.user import User
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class AuthDB(DataConnector):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.__table_name = "user"
|
||||
if not self._table_exists(self.__table_name):
|
||||
self.__update_table()
|
||||
|
||||
def __update_table(self):
|
||||
db_data = self.__data_to_db(User())
|
||||
self._update_table(self.__table_name, db_data)
|
||||
self._insert(self.__table_name, db_data)
|
||||
|
||||
@staticmethod
|
||||
def __data_to_db(data: User) -> dict:
|
||||
db_data = data.dict()
|
||||
db_data["password"] = get_password_hash(db_data["password"])
|
||||
return db_data
|
||||
|
||||
@staticmethod
|
||||
def __db_to_data(db_data: dict) -> User:
|
||||
return User(**db_data)
|
||||
|
||||
def get_user(self, username):
|
||||
self._cursor.execute(
|
||||
f"SELECT * FROM {self.__table_name} WHERE username=?", (username,)
|
||||
)
|
||||
result = self._cursor.fetchone()
|
||||
if not result:
|
||||
return None
|
||||
db_data = dict(zip([x[0] for x in self._cursor.description], result))
|
||||
return self.__db_to_data(db_data)
|
||||
|
||||
def auth_user(self, username, password) -> bool:
|
||||
self._cursor.execute(
|
||||
f"SELECT username, password FROM {self.__table_name} WHERE username=?",
|
||||
(username,),
|
||||
)
|
||||
result = self._cursor.fetchone()
|
||||
if not result:
|
||||
raise HTTPException(status_code=404, detail="User not found")
|
||||
if not verify_password(password, result[1]):
|
||||
raise HTTPException(status_code=401, detail="Password error")
|
||||
return True
|
||||
|
||||
def update_user(self, username, update_user: User):
|
||||
# Update username and password
|
||||
new_username = update_user.username
|
||||
new_password = update_user.password
|
||||
self._cursor.execute(
|
||||
f"""
|
||||
UPDATE {self.__table_name}
|
||||
SET username = '{new_username}', password = '{get_password_hash(new_password)}'
|
||||
WHERE username = '{username}'
|
||||
"""
|
||||
)
|
||||
self._conn.commit()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
with AuthDB() as db:
|
||||
# db.update_user(UserLogin(username="admin", password="adminadmin"), User(username="admin", password="cica1234"))
|
||||
db.update_user("admin", User(username="estrella", password="cica1234"))
|
||||
@@ -1,15 +1 @@
|
||||
from module.models import Config
|
||||
|
||||
|
||||
def getClient(settings: Config):
|
||||
# TODO 多下载器支持
|
||||
type = settings.downloader.type
|
||||
host = settings.downloader.host
|
||||
username = settings.downloader.username
|
||||
password = settings.downloader.password
|
||||
ssl = settings.downloader.ssl
|
||||
if type == "qbittorrent":
|
||||
from .qb_downloader import QbDownloader
|
||||
return QbDownloader(host, username, password, ssl)
|
||||
else:
|
||||
raise Exception(f"Unsupported downloader type: {type}")
|
||||
from .download_client import DownloadClient
|
||||
|
||||
@@ -6,7 +6,7 @@ from aria2p import Client, ClientException, API
|
||||
|
||||
from module.conf import settings
|
||||
|
||||
from .exceptions import ConflictError
|
||||
from module.downloader.exceptions import ConflictError
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
@@ -15,13 +15,7 @@ class QbDownloader:
|
||||
def __init__(self, host, username, password):
|
||||
while True:
|
||||
try:
|
||||
self._client = API(
|
||||
Client(
|
||||
host=host,
|
||||
port=6800,
|
||||
secret=password
|
||||
)
|
||||
)
|
||||
self._client = API(Client(host=host, port=6800, secret=password))
|
||||
break
|
||||
except ClientException:
|
||||
logger.warning(
|
||||
@@ -35,4 +29,4 @@ class QbDownloader:
|
||||
torrent_file_path=urls,
|
||||
save_path=save_path,
|
||||
category=category,
|
||||
)
|
||||
)
|
||||
@@ -2,7 +2,11 @@ import logging
|
||||
import time
|
||||
|
||||
from qbittorrentapi import Client, LoginFailed
|
||||
from qbittorrentapi.exceptions import Conflict409Error
|
||||
from qbittorrentapi.exceptions import (
|
||||
Conflict409Error,
|
||||
Forbidden403Error,
|
||||
APIConnectionError,
|
||||
)
|
||||
|
||||
from module.ab_decorator import qb_connect_failed_wait
|
||||
from module.downloader.exceptions import ConflictError
|
||||
@@ -16,22 +20,40 @@ class QbDownloader:
|
||||
host=host,
|
||||
username=username,
|
||||
password=password,
|
||||
VERIFY_WEBUI_CERTIFICATE=ssl
|
||||
VERIFY_WEBUI_CERTIFICATE=ssl,
|
||||
DISABLE_LOGGING_DEBUG_OUTPUT=True,
|
||||
REQUESTS_ARGS={"timeout": (3.1, 10)},
|
||||
)
|
||||
self.host = host
|
||||
self.username = username
|
||||
|
||||
@qb_connect_failed_wait
|
||||
def auth(self):
|
||||
while True:
|
||||
times = 0
|
||||
while times < 3:
|
||||
try:
|
||||
self._client.auth_log_in()
|
||||
break
|
||||
return True
|
||||
except LoginFailed:
|
||||
logger.error(
|
||||
f"Can't login qBittorrent Server {self.host} by {self.username}, retry in {5} seconds."
|
||||
)
|
||||
time.sleep(5)
|
||||
time.sleep(5)
|
||||
times += 1
|
||||
except Forbidden403Error:
|
||||
logger.error(f"Login refused by qBittorrent Server")
|
||||
logger.info(f"Please release the IP in qBittorrent Server")
|
||||
break
|
||||
except APIConnectionError:
|
||||
logger.error(f"Cannot connect to qBittorrent Server")
|
||||
logger.info(f"Please check the IP and port in WebUI settings")
|
||||
time.sleep(30)
|
||||
except Exception as e:
|
||||
logger.error(f"Unknown error: {e}")
|
||||
break
|
||||
return False
|
||||
|
||||
def logout(self):
|
||||
self._client.auth_log_out()
|
||||
|
||||
@qb_connect_failed_wait
|
||||
def prefs_init(self, prefs):
|
||||
@@ -45,8 +67,8 @@ class QbDownloader:
|
||||
return self._client.torrents_createCategory(name=category)
|
||||
|
||||
@qb_connect_failed_wait
|
||||
def torrents_info(self, status_filter, category):
|
||||
return self._client.torrents_info(status_filter, category)
|
||||
def torrents_info(self, status_filter, category, tag=None):
|
||||
return self._client.torrents_info(status_filter=status_filter, category=category, tag=tag)
|
||||
|
||||
def torrents_add(self, urls, save_path, category):
|
||||
return self._client.torrents_add(
|
||||
@@ -54,46 +76,24 @@ class QbDownloader:
|
||||
urls=urls,
|
||||
save_path=save_path,
|
||||
category=category,
|
||||
use_auto_torrent_management=False
|
||||
)
|
||||
|
||||
def torrents_delete(self, hash):
|
||||
return self._client.torrents_delete(
|
||||
delete_files=True,
|
||||
torrent_hashes=hash
|
||||
)
|
||||
return self._client.torrents_delete(delete_files=True, torrent_hashes=hash)
|
||||
|
||||
def torrents_rename_file(self, torrent_hash, old_path, new_path):
|
||||
self._client.torrents_rename_file(torrent_hash=torrent_hash, old_path=old_path, new_path=new_path)
|
||||
|
||||
def check_rss(self, url, item_path) -> tuple[str | None, bool]:
|
||||
items = self._client.rss_items()
|
||||
for key, value in items.items():
|
||||
rss_url = value.get("url")
|
||||
if key == item_path:
|
||||
if rss_url != url:
|
||||
return key, False
|
||||
return None, True
|
||||
else:
|
||||
if rss_url == url:
|
||||
return key, True
|
||||
return None, False
|
||||
def torrents_rename_file(self, torrent_hash, old_path, new_path) -> bool:
|
||||
try:
|
||||
self._client.torrents_rename_file(
|
||||
torrent_hash=torrent_hash, old_path=old_path, new_path=new_path
|
||||
)
|
||||
return True
|
||||
except Conflict409Error:
|
||||
logger.debug(f"Conflict409Error: {old_path} >> {new_path}")
|
||||
return False
|
||||
|
||||
def rss_add_feed(self, url, item_path):
|
||||
path, added = self.check_rss(url, item_path)
|
||||
if path:
|
||||
if not added:
|
||||
logger.info("RSS Exist, Update URL.")
|
||||
self._client.rss_remove_item(path)
|
||||
self._client.rss_add_feed(url, item_path)
|
||||
else:
|
||||
logger.info("RSS Exist.")
|
||||
else:
|
||||
if added:
|
||||
logger.info("RSS Exist.")
|
||||
else:
|
||||
logger.info("Add new RSS")
|
||||
self._client.rss_add_feed(url, item_path)
|
||||
logger.info("Successfully added RSS")
|
||||
self._client.rss_add_feed(url, item_path)
|
||||
|
||||
def rss_remove_item(self, item_path):
|
||||
try:
|
||||
@@ -103,6 +103,9 @@ class QbDownloader:
|
||||
logger.info("Add new RSS")
|
||||
raise ConflictError()
|
||||
|
||||
def rss_get_feeds(self):
|
||||
return self._client.rss_items()
|
||||
|
||||
def rss_set_rule(self, rule_name, rule_def):
|
||||
self._client.rss_set_rule(rule_name, rule_def)
|
||||
|
||||
@@ -120,3 +123,9 @@ class QbDownloader:
|
||||
|
||||
def check_connection(self):
|
||||
return self._client.app_version()
|
||||
|
||||
def remove_rule(self, rule_name):
|
||||
self._client.rss_remove_rule(rule_name)
|
||||
|
||||
def add_tag(self, _hash, tag):
|
||||
self._client.torrents_add_tags(tags=tag, hashes=_hash)
|
||||
0
src/module/downloader/client/tr_downloader.py
Normal file
0
src/module/downloader/client/tr_downloader.py
Normal file
135
src/module/downloader/download_client.py
Normal file
135
src/module/downloader/download_client.py
Normal file
@@ -0,0 +1,135 @@
|
||||
import logging
|
||||
|
||||
from .path import TorrentPath
|
||||
|
||||
from module.models import BangumiData
|
||||
from module.conf import settings
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class DownloadClient(TorrentPath):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.client = self.__getClient()
|
||||
self.authed = False
|
||||
|
||||
@staticmethod
|
||||
def __getClient():
|
||||
# TODO 多下载器支持
|
||||
type = settings.downloader.type
|
||||
host = settings.downloader.host
|
||||
username = settings.downloader.username
|
||||
password = settings.downloader.password
|
||||
ssl = settings.downloader.ssl
|
||||
if type == "qbittorrent":
|
||||
from .client.qb_downloader import QbDownloader
|
||||
|
||||
return QbDownloader(host, username, password, ssl)
|
||||
else:
|
||||
logger.error(f"[Downloader] Unsupported downloader type: {type}")
|
||||
raise Exception(f"Unsupported downloader type: {type}")
|
||||
|
||||
def __enter__(self):
|
||||
if not self.authed:
|
||||
self.auth()
|
||||
return self
|
||||
|
||||
def __exit__(self, exc_type, exc_val, exc_tb):
|
||||
if self.authed:
|
||||
self.client.logout()
|
||||
self.authed = False
|
||||
|
||||
def auth(self):
|
||||
self.authed = self.client.auth()
|
||||
logger.debug("Authed.")
|
||||
|
||||
def init_downloader(self):
|
||||
prefs = {
|
||||
"rss_auto_downloading_enabled": True,
|
||||
"rss_max_articles_per_feed": 500,
|
||||
"rss_processing_enabled": True,
|
||||
"rss_refresh_interval": 30,
|
||||
}
|
||||
self.client.prefs_init(prefs=prefs)
|
||||
try:
|
||||
self.client.add_category("BangumiCollection")
|
||||
except Exception as e:
|
||||
logger.debug("[Downloader] Cannot add new category, maybe already exists.")
|
||||
if settings.downloader.path == "":
|
||||
prefs = self.client.get_app_prefs()
|
||||
settings.downloader.path = self._join_path(prefs["save_path"], "Bangumi")
|
||||
|
||||
def set_rule(self, data: BangumiData):
|
||||
data.rule_name = self._rule_name(data)
|
||||
data.save_path = self._gen_save_path(data)
|
||||
rule = {
|
||||
"enable": True,
|
||||
"mustContain": data.title_raw,
|
||||
"mustNotContain": "|".join(data.filter),
|
||||
"useRegex": True,
|
||||
"episodeFilter": "",
|
||||
"smartFilter": False,
|
||||
"previouslyMatchedEpisodes": [],
|
||||
"affectedFeeds": data.rss_link,
|
||||
"ignoreDays": 0,
|
||||
"lastMatch": "",
|
||||
"addPaused": False,
|
||||
"assignedCategory": "Bangumi",
|
||||
"savePath": data.save_path,
|
||||
}
|
||||
self.client.rss_set_rule(rule_name=data.rule_name, rule_def=rule)
|
||||
data.added = True
|
||||
logger.info(
|
||||
f"[Downloader] Add {data.official_title} Season {data.season} to auto download rules."
|
||||
)
|
||||
|
||||
def set_rules(self, bangumi_info: list[BangumiData]):
|
||||
logger.debug("[Downloader] Start adding rules.")
|
||||
for info in bangumi_info:
|
||||
self.set_rule(info)
|
||||
logger.debug("[Downloader] Finished.")
|
||||
|
||||
def get_torrent_info(self, category="Bangumi", status_filter="completed", tag=None):
|
||||
return self.client.torrents_info(status_filter=status_filter, category=category, tag=tag)
|
||||
|
||||
def rename_torrent_file(self, _hash, old_path, new_path) -> bool:
|
||||
logger.info(f"{old_path} >> {new_path}")
|
||||
return self.client.torrents_rename_file(
|
||||
torrent_hash=_hash, old_path=old_path, new_path=new_path
|
||||
)
|
||||
|
||||
def delete_torrent(self, hashes):
|
||||
self.client.torrents_delete(hashes)
|
||||
logger.info(f"[Downloader] Remove torrents.")
|
||||
|
||||
def add_torrent(self, torrent: dict):
|
||||
self.client.torrents_add(
|
||||
urls=torrent["url"], save_path=torrent["save_path"], category="Bangumi"
|
||||
)
|
||||
|
||||
def move_torrent(self, hashes, location):
|
||||
self.client.move_torrent(hashes=hashes, new_location=location)
|
||||
|
||||
# RSS Parts
|
||||
def add_rss_feed(self, rss_link, item_path="Mikan_RSS"):
|
||||
self.client.rss_add_feed(url=rss_link, item_path=item_path)
|
||||
|
||||
def remove_rss_feed(self, item_path):
|
||||
self.client.rss_remove_item(item_path=item_path)
|
||||
|
||||
def get_rss_feed(self):
|
||||
return self.client.rss_get_feeds()
|
||||
|
||||
def get_download_rules(self):
|
||||
return self.client.get_download_rule()
|
||||
|
||||
def get_torrent_path(self, hashes):
|
||||
return self.client.get_torrent_path(hashes)
|
||||
|
||||
def set_category(self, hashes, category):
|
||||
self.client.set_category(hashes, category)
|
||||
|
||||
def remove_rule(self, rule_name):
|
||||
self.client.remove_rule(rule_name)
|
||||
logger.info(f"[Downloader] Delete rule: {rule_name}")
|
||||
71
src/module/downloader/path.py
Normal file
71
src/module/downloader/path.py
Normal file
@@ -0,0 +1,71 @@
|
||||
import re
|
||||
import logging
|
||||
|
||||
from module.conf import settings
|
||||
from module.models import BangumiData
|
||||
|
||||
if ":\\" in settings.downloader.path:
|
||||
import ntpath as path
|
||||
else:
|
||||
import os.path as path
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class TorrentPath:
|
||||
def __init__(self):
|
||||
self.download_path = settings.downloader.path
|
||||
|
||||
@staticmethod
|
||||
def check_files(info):
|
||||
media_list = []
|
||||
subtitle_list = []
|
||||
for f in info.files:
|
||||
file_name = f.name
|
||||
suffix = path.splitext(file_name)[-1]
|
||||
if suffix.lower() in [".mp4", ".mkv"]:
|
||||
media_list.append(file_name)
|
||||
elif suffix.lower() in [".ass", ".srt"]:
|
||||
subtitle_list.append(file_name)
|
||||
return media_list, subtitle_list
|
||||
|
||||
def _path_to_bangumi(self, save_path):
|
||||
# Split save path and download path
|
||||
save_parts = save_path.split(path.sep)
|
||||
download_parts = self.download_path.split(path.sep)
|
||||
# Get bangumi name and season
|
||||
bangumi_name = ""
|
||||
season = 1
|
||||
for part in save_parts:
|
||||
if re.match(r"S\d+|[Ss]eason \d+", part):
|
||||
season = int(re.findall(r"\d+", part)[0])
|
||||
elif part not in download_parts:
|
||||
bangumi_name = part
|
||||
return bangumi_name, season
|
||||
|
||||
@staticmethod
|
||||
def _file_depth(path):
|
||||
return len(path.split(path.sep))
|
||||
|
||||
def is_ep(self, path):
|
||||
return self._file_depth(path) <= 2
|
||||
|
||||
def _gen_save_path(self, data: BangumiData):
|
||||
folder = (
|
||||
f"{data.official_title} ({data.year})" if data.year else data.official_title
|
||||
)
|
||||
save_path = path.join(self.download_path, folder, f"Season {data.season}")
|
||||
return save_path
|
||||
|
||||
@staticmethod
|
||||
def _rule_name(data: BangumiData):
|
||||
rule_name = (
|
||||
f"[{data.group_name}] {data.official_title} S{data.season}"
|
||||
if settings.bangumi_manage.group_tag
|
||||
else f"{data.official_title} S{data.season}"
|
||||
)
|
||||
return rule_name
|
||||
|
||||
@staticmethod
|
||||
def _join_path(*args):
|
||||
return path.join(*args)
|
||||
@@ -1,2 +1,3 @@
|
||||
from .eps_complete import FullSeasonGet
|
||||
from .collector import SeasonCollector, eps_complete
|
||||
from .renamer import Renamer
|
||||
from .torrent import TorrentManager
|
||||
|
||||
56
src/module/manager/collector.py
Normal file
56
src/module/manager/collector.py
Normal file
@@ -0,0 +1,56 @@
|
||||
import logging
|
||||
|
||||
from module.downloader import DownloadClient
|
||||
from module.models import BangumiData
|
||||
from module.database import BangumiDatabase
|
||||
from module.searcher import SearchTorrent
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class SeasonCollector(DownloadClient):
|
||||
def add_season_torrents(self, data: BangumiData, torrents):
|
||||
for torrent in torrents:
|
||||
download_info = {
|
||||
"url": torrent.torrent_link,
|
||||
"save_path": self._gen_save_path(data),
|
||||
}
|
||||
self.add_torrent(download_info)
|
||||
|
||||
def collect_season(self, data: BangumiData, link: str = None):
|
||||
logger.info(f"Start collecting {data.official_title} Season {data.season}...")
|
||||
with SearchTorrent() as st:
|
||||
if not link:
|
||||
torrents = st.search_season(data)
|
||||
else:
|
||||
torrents = st.get_torrents(link)
|
||||
self.add_season_torrents(data, torrents)
|
||||
logger.info("Completed!")
|
||||
|
||||
def subscribe_season(self, data: BangumiData):
|
||||
with BangumiDatabase() as db:
|
||||
data.added = True
|
||||
data.eps_collect = True
|
||||
db.insert(data)
|
||||
self.add_rss_feed(data.rss_link[0], item_path=data.official_title)
|
||||
self.set_rule(data)
|
||||
|
||||
|
||||
def eps_complete():
|
||||
with BangumiDatabase() as bd:
|
||||
datas = bd.not_complete()
|
||||
if datas:
|
||||
logger.info("Start collecting full season...")
|
||||
for data in datas:
|
||||
if not data.eps_collect:
|
||||
with SeasonCollector() as sc:
|
||||
sc.collect_season(data)
|
||||
data.eps_collect = True
|
||||
bd.update_list(datas)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
from module.conf import setup_logger
|
||||
|
||||
setup_logger()
|
||||
eps_complete()
|
||||
@@ -1,75 +0,0 @@
|
||||
import os.path
|
||||
import re
|
||||
import logging
|
||||
|
||||
from module.network import RequestContent
|
||||
|
||||
from module.core import DownloadClient
|
||||
from module.models import BangumiData, Config
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class FullSeasonGet:
|
||||
def __init__(self, settings: Config):
|
||||
self.SEARCH_KEY = ["group", "title_raw", "season_raw", "subtitle", "source", "dpi"]
|
||||
self.CUSTOM_URL = "https://mikanani.me" if settings.rss_parser.custom_url == "" else settings.rss_parser.custom_url
|
||||
if "://" not in self.CUSTOM_URL:
|
||||
if re.match(r"\d{1,3}\.\d{1,3}\.\d{1,3}\.\d{1,3}", self.CUSTOM_URL):
|
||||
self.CUSTOM_URL = f"http://{self.CUSTOM_URL}"
|
||||
self.CUSTOM_URL = f"https://{self.CUSTOM_URL}"
|
||||
self.save_path = settings.downloader.path
|
||||
|
||||
def init_eps_complete_search_str(self, data: BangumiData):
|
||||
test = []
|
||||
for key in self.SEARCH_KEY:
|
||||
data_dict = data.dict()
|
||||
if data_dict[key] is not None:
|
||||
test.append(data_dict[key])
|
||||
search_str_pre = "+".join(test)
|
||||
search_str = re.sub(r"[\W_ ]", "+", search_str_pre)
|
||||
return search_str
|
||||
|
||||
def get_season_torrents(self, data: BangumiData):
|
||||
keyword = self.init_eps_complete_search_str(data)
|
||||
with RequestContent() as req:
|
||||
torrents = req.get_torrents(f"{self.CUSTOM_URL}/RSS/Search?searchstr={keyword}")
|
||||
return [torrent for torrent in torrents if data.title_raw in torrent.name]
|
||||
|
||||
def collect_season_torrents(self, data: BangumiData, torrents):
|
||||
downloads = []
|
||||
for torrent in torrents:
|
||||
download_info = {
|
||||
"url": torrent.torrent_link,
|
||||
"save_path": os.path.join(
|
||||
self.save_path,
|
||||
data.official_title,
|
||||
f"Season {data.season}")
|
||||
}
|
||||
downloads.append(download_info)
|
||||
return downloads
|
||||
|
||||
def download_eps(self, data: BangumiData, download_client: DownloadClient):
|
||||
logger.info(f"Start collecting {data.official_title} Season {data.season}...")
|
||||
torrents = self.get_season_torrents(data)
|
||||
downloads = self.collect_season_torrents(data, torrents)
|
||||
for download in downloads:
|
||||
download_client.add_torrent(download)
|
||||
logger.info("Completed!")
|
||||
data.eps_collect = False
|
||||
|
||||
def eps_complete(self, bangumi_info: list[BangumiData], download_client: DownloadClient):
|
||||
for data in bangumi_info:
|
||||
if data.eps_collect:
|
||||
self.download_eps(data, download_client)
|
||||
|
||||
def download_collection(self, data: BangumiData, link, download_client: DownloadClient):
|
||||
with RequestContent() as req:
|
||||
torrents = req.get_torrents(link)
|
||||
downloads = self.collect_season_torrents(data, torrents)
|
||||
logger.info(f"Starting download {data.official_title} Season {data.season}...")
|
||||
for download in downloads:
|
||||
download_client.add_torrent(download)
|
||||
logger.info("Completed!")
|
||||
|
||||
|
||||
@@ -1,200 +1,184 @@
|
||||
import logging
|
||||
import os.path
|
||||
import re
|
||||
from pathlib import PurePath, PureWindowsPath
|
||||
|
||||
from module.core.download_client import DownloadClient
|
||||
from module.downloader import DownloadClient
|
||||
|
||||
from module.parser import TitleParser
|
||||
from module.network import PostNotification
|
||||
from module.models import Config
|
||||
from module.models import SubtitleFile, EpisodeFile, Notification
|
||||
from module.conf import settings
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class Renamer:
|
||||
def __init__(self, download_client: DownloadClient, settings: Config):
|
||||
self._client = download_client
|
||||
self._renamer = TitleParser()
|
||||
self._notification = PostNotification()
|
||||
self.settings = settings
|
||||
class Renamer(DownloadClient):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self._parser = TitleParser()
|
||||
|
||||
@staticmethod
|
||||
def print_result(torrent_count, rename_count):
|
||||
if rename_count != 0:
|
||||
logger.info(f"Finished checking {torrent_count} files' name, renamed {rename_count} files.")
|
||||
logger.info(
|
||||
f"Finished checking {torrent_count} files' name, renamed {rename_count} files."
|
||||
)
|
||||
logger.debug(f"Checked {torrent_count} files")
|
||||
|
||||
def get_torrent_info(self, category="Bangumi"):
|
||||
recent_info = self._client.get_torrent_info(category=category)
|
||||
torrent_count = len(recent_info)
|
||||
return recent_info, torrent_count
|
||||
|
||||
@staticmethod
|
||||
def check_files(info):
|
||||
media_list = []
|
||||
subtitle_list = []
|
||||
for f in info.files:
|
||||
file_name = f.name
|
||||
suffix = os.path.splitext(file_name)[-1]
|
||||
if suffix.lower() in [".mp4", ".mkv"]:
|
||||
media_list.append(file_name)
|
||||
elif suffix.lower() in [".ass", ".srt"]:
|
||||
subtitle_list.append(file_name)
|
||||
return media_list, subtitle_list
|
||||
|
||||
def rename_file(self, info, media_path: str, method: str, bangumi_name: str, season: int, remove_bad_torrents: bool):
|
||||
torrent_name = info.name
|
||||
suffix = os.path.splitext(media_path)[-1]
|
||||
compare_name = self.get_file_name(media_path)
|
||||
new_path = self._renamer.torrent_parser(
|
||||
torrent_name=torrent_name,
|
||||
bangumi_name=bangumi_name,
|
||||
season=season,
|
||||
suffix=suffix,
|
||||
method=method
|
||||
def gen_path(
|
||||
file_info: EpisodeFile | SubtitleFile, bangumi_name: str, method: str
|
||||
) -> str:
|
||||
season = f"0{file_info.season}" if file_info.season < 10 else file_info.season
|
||||
episode = (
|
||||
f"0{file_info.episode}" if file_info.episode < 10 else file_info.episode
|
||||
)
|
||||
if compare_name != new_path:
|
||||
try:
|
||||
self._client.rename_torrent_file(_hash=info.hash, old_path=media_path, new_path=new_path)
|
||||
self._notification.send_msg(bangumi_name, f"{new_path}已经更新,已自动重命名。")
|
||||
except Exception as e:
|
||||
logger.warning(f"{torrent_name} rename failed")
|
||||
logger.warning(f"Season name: {bangumi_name}, Season: {season}, Suffix: {suffix}")
|
||||
logger.debug(e)
|
||||
# Delete bad torrent
|
||||
self.delete_bad_torrent(info, remove_bad_torrents)
|
||||
if method == "none" or method == "subtitle_none":
|
||||
return file_info.media_path
|
||||
elif method == "pn":
|
||||
return f"{file_info.title} S{season}E{episode}{file_info.suffix}"
|
||||
elif method == "advance":
|
||||
return f"{bangumi_name} S{season}E{episode}{file_info.suffix}"
|
||||
elif method == "normal":
|
||||
logger.warning(
|
||||
"[Renamer] Normal rename method is deprecated."
|
||||
)
|
||||
return file_info.media_path
|
||||
elif method == "subtitle_pn":
|
||||
return f"{file_info.title} S{season}E{episode}.{file_info.language}{file_info.suffix}"
|
||||
elif method == "subtitle_advance":
|
||||
return f"{bangumi_name} S{season}E{episode}.{file_info.language}{file_info.suffix}"
|
||||
else:
|
||||
logger.error(f"[Renamer] Unknown rename method: {method}")
|
||||
return file_info.media_path
|
||||
|
||||
def rename_collection(self, info, media_list: list[str], bangumi_name: str, season: int, remove_bad_torrents: bool, method: str):
|
||||
_hash = info.hash
|
||||
for media_path in media_list:
|
||||
path_len = len(media_path.split(os.path.sep))
|
||||
if path_len <= 2:
|
||||
suffix = os.path.splitext(media_path)[-1]
|
||||
torrent_name = self.get_file_name(media_path)
|
||||
new_name = self._renamer.torrent_parser(
|
||||
torrent_name=torrent_name,
|
||||
bangumi_name=bangumi_name,
|
||||
season=season,
|
||||
suffix=suffix,
|
||||
method=method
|
||||
def rename_file(
|
||||
self,
|
||||
torrent_name: str,
|
||||
media_path: str,
|
||||
bangumi_name: str,
|
||||
method: str,
|
||||
season: int,
|
||||
_hash: str,
|
||||
**kwargs,
|
||||
):
|
||||
ep = self._parser.torrent_parser(
|
||||
torrent_name=torrent_name,
|
||||
torrent_path=media_path,
|
||||
season=season,
|
||||
)
|
||||
if ep:
|
||||
new_path = self.gen_path(ep, bangumi_name, method=method)
|
||||
if media_path != new_path:
|
||||
renamed = self.rename_torrent_file(
|
||||
_hash=_hash, old_path=media_path, new_path=new_path
|
||||
)
|
||||
if torrent_name != new_name:
|
||||
try:
|
||||
self._client.rename_torrent_file(_hash=_hash, old_path=media_path, new_path=new_name)
|
||||
except Exception as e:
|
||||
logger.warning(f"{torrent_name} rename failed")
|
||||
logger.warning(f"Bangumi name: {bangumi_name}, Season: {season}, Suffix: {suffix}")
|
||||
logger.debug(e)
|
||||
# Delete bad torrent.
|
||||
self.delete_bad_torrent(info, remove_bad_torrents)
|
||||
self._client.set_category(category="BangumiCollection", hashes=_hash)
|
||||
if renamed:
|
||||
n = Notification(
|
||||
official_title=bangumi_name,
|
||||
season=ep.season,
|
||||
episode=ep.episode,
|
||||
)
|
||||
return n
|
||||
else:
|
||||
logger.warning(f"[Renamer] {media_path} parse failed")
|
||||
if settings.bangumi_manage.remove_bad_torrent:
|
||||
self.delete_torrent(hashes=_hash)
|
||||
return None
|
||||
|
||||
def rename_collection(
|
||||
self,
|
||||
media_list: list[str],
|
||||
bangumi_name: str,
|
||||
season: int,
|
||||
method: str,
|
||||
_hash: str,
|
||||
**kwargs,
|
||||
):
|
||||
for media_path in media_list:
|
||||
if self.is_ep(media_path):
|
||||
ep = self._parser.torrent_parser(
|
||||
torrent_path=media_path,
|
||||
season=season,
|
||||
)
|
||||
if ep:
|
||||
new_path = self.gen_path(ep, bangumi_name, method=method)
|
||||
if media_path != new_path:
|
||||
renamed = self.rename_torrent_file(
|
||||
_hash=_hash, old_path=media_path, new_path=new_path
|
||||
)
|
||||
if not renamed:
|
||||
logger.warning(f"[Renamrr] {media_path} rename failed")
|
||||
# Delete bad torrent.
|
||||
if settings.bangumi_manage.remove_bad_torrent:
|
||||
self.delete_torrent(_hash)
|
||||
break
|
||||
|
||||
def rename_subtitles(
|
||||
self,
|
||||
subtitle_list: list[str],
|
||||
bangumi_name: str,
|
||||
season: int,
|
||||
method: str,
|
||||
_hash
|
||||
self,
|
||||
subtitle_list: list[str],
|
||||
torrent_name: str,
|
||||
bangumi_name: str,
|
||||
season: int,
|
||||
method: str,
|
||||
_hash,
|
||||
**kwargs,
|
||||
):
|
||||
method = "subtitle_" + method
|
||||
for subtitle_path in subtitle_list:
|
||||
suffix = os.path.splitext(subtitle_path)[-1]
|
||||
old_name = self.get_file_name(subtitle_path)
|
||||
new_name = self._renamer.torrent_parser(
|
||||
method=method,
|
||||
torrent_name=old_name,
|
||||
bangumi_name=bangumi_name,
|
||||
sub = self._parser.torrent_parser(
|
||||
torrent_path=subtitle_path,
|
||||
torrent_name=torrent_name,
|
||||
season=season,
|
||||
suffix=suffix
|
||||
file_type="subtitle",
|
||||
)
|
||||
if old_name != new_name:
|
||||
try:
|
||||
self._client.rename_torrent_file(_hash=_hash, old_path=subtitle_path, new_path=new_name)
|
||||
except Exception as e:
|
||||
logger.warning(f"{old_name} rename failed")
|
||||
logger.warning(f"Suffix: {suffix}")
|
||||
logger.debug(e)
|
||||
|
||||
def delete_bad_torrent(self, info, remove_bad_torrent: bool):
|
||||
if remove_bad_torrent:
|
||||
self._client.delete_torrent(info.hash)
|
||||
logger.info(f"{info.name} have been deleted.")
|
||||
|
||||
@staticmethod
|
||||
def get_season_info(save_path: str, download_path: str):
|
||||
if "\\" in download_path:
|
||||
import ntpath as path
|
||||
else:
|
||||
import posixpath as path
|
||||
# Split save path and download path
|
||||
save_parts = save_path.split(path.sep)
|
||||
download_parts = download_path.split(path.sep)
|
||||
# Get bangumi name and season
|
||||
bangumi_name = ""
|
||||
season = 1
|
||||
for part in save_parts:
|
||||
if re.match(r"S\d+|[Ss]eason \d+", part):
|
||||
season = int(re.findall(r"\d+", part)[0])
|
||||
elif part not in download_parts:
|
||||
bangumi_name = part
|
||||
return bangumi_name, season
|
||||
|
||||
@staticmethod
|
||||
def get_file_name(file_path: str):
|
||||
# Check windows or linux path
|
||||
path_parts = PurePath(file_path).parts \
|
||||
if PurePath(file_path).name != file_path \
|
||||
else PureWindowsPath(file_path).parts
|
||||
# Get file name
|
||||
file_name = path_parts[-1]
|
||||
return file_name
|
||||
if sub:
|
||||
new_path = self.gen_path(sub, bangumi_name, method=method)
|
||||
if subtitle_path != new_path:
|
||||
renamed = self.rename_torrent_file(
|
||||
_hash=_hash, old_path=subtitle_path, new_path=new_path
|
||||
)
|
||||
if not renamed:
|
||||
logger.warning(f"[Renamer] {subtitle_path} rename failed")
|
||||
|
||||
def rename(self):
|
||||
# Get torrent info
|
||||
download_path = self.settings.downloader.path
|
||||
rename_method = self.settings.bangumi_manage.rename_method
|
||||
remove_bad_torrents = self.settings.bangumi_manage.remove_bad_torrent
|
||||
recent_info, torrent_count = self.get_torrent_info()
|
||||
for info in recent_info:
|
||||
logger.debug("[Renamer] Start rename process.")
|
||||
rename_method = settings.bangumi_manage.rename_method
|
||||
torrents_info = self.get_torrent_info()
|
||||
renamed_info = []
|
||||
for info in torrents_info:
|
||||
media_list, subtitle_list = self.check_files(info)
|
||||
bangumi_name, season = self.get_season_info(info.save_path, download_path)
|
||||
bangumi_name, season = self._path_to_bangumi(info.save_path)
|
||||
kwargs = {
|
||||
"torrent_name": info.name,
|
||||
"bangumi_name": bangumi_name,
|
||||
"method": rename_method,
|
||||
"season": season,
|
||||
"_hash": info.hash,
|
||||
}
|
||||
# Rename single media file
|
||||
if len(media_list) == 1:
|
||||
self.rename_file(
|
||||
info=info,
|
||||
media_path=media_list[0],
|
||||
method=rename_method,
|
||||
bangumi_name=bangumi_name,
|
||||
season=season,
|
||||
remove_bad_torrents=remove_bad_torrents
|
||||
)
|
||||
notify_info = self.rename_file(media_path=media_list[0], **kwargs)
|
||||
if notify_info:
|
||||
renamed_info.append(notify_info)
|
||||
# Rename subtitle file
|
||||
if len(subtitle_list) > 0:
|
||||
self.rename_subtitles(
|
||||
subtitle_list=subtitle_list,
|
||||
bangumi_name=bangumi_name,
|
||||
season=season,
|
||||
method=rename_method,
|
||||
_hash=info.hash
|
||||
)
|
||||
self.rename_subtitles(subtitle_list=subtitle_list, **kwargs)
|
||||
# Rename collection
|
||||
elif len(media_list) > 1:
|
||||
logger.info("Start rename collection")
|
||||
self.rename_collection(
|
||||
info=info,
|
||||
media_list=media_list,
|
||||
bangumi_name=bangumi_name,
|
||||
season=season,
|
||||
remove_bad_torrents=remove_bad_torrents,
|
||||
method=rename_method
|
||||
)
|
||||
logger.info("[Renamer] Start rename collection")
|
||||
self.rename_collection(media_list=media_list, **kwargs)
|
||||
if len(subtitle_list) > 0:
|
||||
self.rename_subtitles(
|
||||
subtitle_list=subtitle_list,
|
||||
bangumi_name=bangumi_name,
|
||||
season=season,
|
||||
method=rename_method,
|
||||
_hash=info.hash
|
||||
)
|
||||
self.rename_subtitles(subtitle_list=subtitle_list, **kwargs)
|
||||
self.set_category(info.hash, "BangumiCollection")
|
||||
else:
|
||||
logger.warning(f"{info.name} has no media file")
|
||||
logger.warning(f"[Renamer] {info.name} has no media file")
|
||||
logger.debug("[Renamer] Rename process finished.")
|
||||
return renamed_info
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
from module.conf import setup_logger
|
||||
settings.log.debug_enable = True
|
||||
setup_logger()
|
||||
with Renamer() as renamer:
|
||||
renamer.rename()
|
||||
|
||||
@@ -1,87 +0,0 @@
|
||||
import logging
|
||||
import re
|
||||
from dataclasses import dataclass
|
||||
from pathlib import PurePath, PureWindowsPath
|
||||
|
||||
from module.core import DownloadClient
|
||||
from module.conf import settings
|
||||
from module.utils import json_config
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@dataclass
|
||||
class RuleInfo:
|
||||
rule_name: str
|
||||
contain: str
|
||||
season: int
|
||||
folder_name: str
|
||||
new_path: str
|
||||
|
||||
|
||||
@dataclass
|
||||
class RepathInfo:
|
||||
path: str
|
||||
hashes: list
|
||||
|
||||
|
||||
class RepathTorrents:
|
||||
def __init__(self, download_client: DownloadClient):
|
||||
self._client = download_client
|
||||
self.re_season = re.compile(r"S\d{1,2}")
|
||||
|
||||
@staticmethod
|
||||
def analyse_path(path: str):
|
||||
path_parts = PurePath(path).parts
|
||||
folder_name = path_parts[-2]
|
||||
season_folder = path_parts[-1]
|
||||
season = int(re.search(r"\d{1,2}", season_folder).group())
|
||||
return season, folder_name
|
||||
|
||||
def get_rule(self) -> [RuleInfo]:
|
||||
rules = self._client.get_download_rules()
|
||||
all_rule = []
|
||||
for rule in rules:
|
||||
path = rules.get(rule).savePath
|
||||
must_contain = rules.get(rule).mustContain
|
||||
season, folder_name = self.analyse_path(path)
|
||||
new_path = PurePath(settings.downloader.path, folder_name, f"Season {season}").__str__()
|
||||
all_rule.append(RuleInfo(rule, must_contain, season, folder_name, new_path))
|
||||
return all_rule
|
||||
|
||||
@staticmethod
|
||||
def get_difference(bangumi_data: list, rules: [RuleInfo]) -> [RuleInfo]:
|
||||
different_data = []
|
||||
for data in bangumi_data:
|
||||
for rule in rules:
|
||||
rule_name = re.sub(r"S\d", "", rule.rule_name).strip()
|
||||
if data.get("official_title") == rule_name:
|
||||
if data.get("season") != rule.season:
|
||||
different_data.append(rule)
|
||||
data["season"] = rule.season
|
||||
break
|
||||
return different_data
|
||||
|
||||
def get_matched_torrents_list(self, repath_rules: [RuleInfo]) -> [RePathInfo]:
|
||||
infos = self._client.get_torrent_info()
|
||||
repath_list = []
|
||||
for rule in repath_rules:
|
||||
hashes = []
|
||||
for info in infos:
|
||||
if re.search(rule.contain, info.name):
|
||||
if rule.new_path != info.save_path:
|
||||
hashes.append(info.hash)
|
||||
infos.remove(info)
|
||||
if hashes:
|
||||
repath_list.append(RepathInfo(rule.new_path, hashes))
|
||||
return repath_list
|
||||
|
||||
def re_path(self, repath_info: RepathInfo):
|
||||
self._client.move_torrent(repath_info.hashes, repath_info.path)
|
||||
|
||||
def run(self):
|
||||
rules = self.get_rule()
|
||||
match_list = self.get_matched_torrents_list(rules)
|
||||
logging.info(f"Starting repath process.")
|
||||
for list in match_list:
|
||||
self.re_path(list)
|
||||
134
src/module/manager/torrent.py
Normal file
134
src/module/manager/torrent.py
Normal file
@@ -0,0 +1,134 @@
|
||||
import logging
|
||||
|
||||
from module.downloader import DownloadClient
|
||||
from module.models import BangumiData
|
||||
from module.database import BangumiDatabase
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class TorrentManager(BangumiDatabase):
|
||||
@staticmethod
|
||||
def __match_torrents_list(data: BangumiData) -> list:
|
||||
with DownloadClient() as client:
|
||||
torrents = client.get_torrent_info(status_filter=None)
|
||||
return [torrent.hash for torrent in torrents if torrent.save_path == data.save_path]
|
||||
|
||||
def delete_torrents(self, data: BangumiData, client: DownloadClient):
|
||||
hash_list = self.__match_torrents_list(data)
|
||||
if hash_list:
|
||||
client.delete_torrent(hash_list)
|
||||
logger.info(f"Delete rule and torrents for {data.official_title}")
|
||||
return {
|
||||
"status": "success",
|
||||
"msg": f"Delete torrents for {data.official_title}",
|
||||
}
|
||||
else:
|
||||
return {
|
||||
"status": "error",
|
||||
"msg": f"Can't find torrents for {data.official_title}",
|
||||
}
|
||||
|
||||
def delete_rule(self, _id: int | str, file: bool = False):
|
||||
data = self.search_id(int(_id))
|
||||
if isinstance(data, BangumiData):
|
||||
with DownloadClient() as client:
|
||||
client.remove_rule(data.rule_name)
|
||||
self.delete_one(int(_id))
|
||||
if file:
|
||||
self.delete_torrents(data, client)
|
||||
return {
|
||||
"status": "success",
|
||||
"msg": f"Delete rule and torrents for {data.official_title}",
|
||||
}
|
||||
logger.info(f"[Manager] Delete rule for {data.official_title}")
|
||||
return {
|
||||
"status": "success",
|
||||
"msg": f"Delete rule for {data.official_title}",
|
||||
}
|
||||
else:
|
||||
return {"status": "error", "msg": f"Can't find id {_id}"}
|
||||
# data = self.search_id(int(_id))
|
||||
# if isinstance(data, BangumiData):
|
||||
# self.delete_one(int(_id))
|
||||
# if file:
|
||||
# self.delete_torrents(data)
|
||||
# logger.info(f"Delete {data.official_title} and torrents.")
|
||||
# return {
|
||||
# "status": "success",
|
||||
# "msg": f"Delete {data.official_title} and torrents.",
|
||||
# }
|
||||
# logger.info(f"Delete {data.official_title}")
|
||||
# return {"status": "success", "msg": f"Delete {data.official_title}"}
|
||||
# else:
|
||||
# return data
|
||||
|
||||
def disable_rule(self, _id: str | int, file: bool = False):
|
||||
data = self.search_id(int(_id))
|
||||
if isinstance(data, BangumiData):
|
||||
with DownloadClient() as client:
|
||||
client.remove_rule(data.rule_name)
|
||||
data.deleted = True
|
||||
self.update_one(data)
|
||||
if file:
|
||||
self.delete_torrents(data, client)
|
||||
return {
|
||||
"status": "success",
|
||||
"msg": f"Disable rule and delete torrents for {data.official_title}",
|
||||
}
|
||||
logger.info(f"[Manager] Disable rule for {data.official_title}")
|
||||
return {
|
||||
"status": "success",
|
||||
"msg": f"Disable rule for {data.official_title}",
|
||||
}
|
||||
else:
|
||||
return {"status": "error", "msg": f"Can't find data with id {_id}"}
|
||||
|
||||
def enable_rule(self, _id: str | int):
|
||||
data = self.search_id(int(_id))
|
||||
if isinstance(data, BangumiData):
|
||||
data.deleted = False
|
||||
self.update_one(data)
|
||||
with DownloadClient() as client:
|
||||
client.set_rule(data)
|
||||
logger.info(f"[Manager] Enable rule for {data.official_title}")
|
||||
return {
|
||||
"status": "success",
|
||||
"msg": f"Enable rule for {data.official_title}",
|
||||
}
|
||||
|
||||
def update_rule(self, data: BangumiData):
|
||||
old_data = self.search_id(data.id)
|
||||
if not old_data:
|
||||
logger.error(f"[Manager] Can't find data with id {data.id}")
|
||||
return {"status": "error", "msg": f"Can't find data with id {data.id}"}
|
||||
else:
|
||||
# Set torrent path
|
||||
match_list = self.__match_torrents_list(data)
|
||||
with DownloadClient() as client:
|
||||
path = client._gen_save_path(data)
|
||||
if match_list:
|
||||
client.move_torrent(match_list, path)
|
||||
# Set new download rule
|
||||
client.remove_rule(data.rule_name)
|
||||
client.set_rule(data)
|
||||
self.update_one(data)
|
||||
return {
|
||||
"status": "success",
|
||||
"msg": f"Set new path for {data.official_title}",
|
||||
}
|
||||
|
||||
def search_all_bangumi(self):
|
||||
datas = self.search_all()
|
||||
if not datas:
|
||||
return []
|
||||
return [data for data in datas if not data.deleted]
|
||||
|
||||
def search_one(self, _id: int | str):
|
||||
data = self.search_id(int(_id))
|
||||
if not data:
|
||||
logger.error(f"[Manager] Can't find data with id {_id}")
|
||||
return {"status": "error", "msg": f"Can't find data with id {_id}"}
|
||||
else:
|
||||
return data
|
||||
@@ -1,2 +1,5 @@
|
||||
from .bangumi import *
|
||||
from .config import Config
|
||||
from .torrent import EpisodeFile, SubtitleFile
|
||||
from .user import UserLogin
|
||||
from .torrent import TorrentBase
|
||||
|
||||
@@ -16,4 +16,3 @@ class ChangeConfig(BaseModel):
|
||||
|
||||
class ChangeRule(BaseModel):
|
||||
rule: dict
|
||||
|
||||
|
||||
@@ -3,39 +3,31 @@ from dataclasses import dataclass
|
||||
|
||||
|
||||
class BangumiData(BaseModel):
|
||||
id: int | None = Field(None, alias="id", title="番剧ID")
|
||||
official_title: str = Field(..., alias="official_title", title="番剧中文名")
|
||||
year: int | None = Field(None, alias="year", title="番剧年份")
|
||||
title_raw: str = Field(..., alias="title_raw", title="番剧原名")
|
||||
season: int = Field(..., alias="season", title="番剧季度")
|
||||
id: int = Field(0, alias="id", title="番剧ID")
|
||||
official_title: str = Field("official_title", alias="official_title", title="番剧中文名")
|
||||
year: str | None = Field(None, alias="year", title="番剧年份")
|
||||
title_raw: str = Field("title_raw", alias="title_raw", title="番剧原名")
|
||||
season: int = Field(1, alias="season", title="番剧季度")
|
||||
season_raw: str | None = Field(None, alias="season_raw", title="番剧季度原名")
|
||||
group: str | None = Field(None, alias="group", title="字幕组")
|
||||
group_name: str | None = Field(None, alias="group_name", title="字幕组")
|
||||
dpi: str | None = Field(None, alias="dpi", title="分辨率")
|
||||
source: str | None = Field(None, alias="source", title="来源")
|
||||
subtitle: str | None = Field(None, alias="subtitle", title="字幕")
|
||||
added: bool = Field(False, alias="added", title="是否已添加")
|
||||
eps_collect: bool = Field(False, alias="eps_collect", title="是否已收集")
|
||||
offset: int = Field(0, alias="offset", title="番剧偏移量")
|
||||
filter: list[str] = Field(..., alias="filter", title="番剧过滤器")
|
||||
filter: list[str] = Field(["720", "\\d+-\\d+"], alias="filter", title="番剧过滤器")
|
||||
rss_link: list[str] = Field([], alias="rss_link", title="番剧RSS链接")
|
||||
poster_link: str | None = Field(None, alias="poster_link", title="番剧海报链接")
|
||||
added: bool = Field(False, alias="added", title="是否已添加")
|
||||
rule_name: str | None = Field(None, alias="rule_name", title="番剧规则名")
|
||||
save_path: str | None = Field(None, alias="save_path", title="番剧保存路径")
|
||||
deleted: bool = Field(False, alias="deleted", title="是否已删除")
|
||||
|
||||
|
||||
class ProgramData(BaseModel):
|
||||
rss_link: str = Field(..., alias="rss_link", title="RSS链接")
|
||||
data_version: float = Field(..., alias="data_version", title="数据版本")
|
||||
bangumi_info: list[BangumiData] = Field([], alias="bangumi_info", title="番剧信息")
|
||||
|
||||
|
||||
@dataclass
|
||||
class MatchRule:
|
||||
keyword: str
|
||||
filter: list
|
||||
rss_link: str
|
||||
|
||||
|
||||
@dataclass
|
||||
class GroupFilter:
|
||||
name: str
|
||||
filter: list
|
||||
class Notification(BaseModel):
|
||||
official_title: str = Field(..., alias="official_title", title="番剧名")
|
||||
season: int = Field(..., alias="season", title="番剧季度")
|
||||
episode: int = Field(..., alias="episode", title="番剧集数")
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -66,6 +58,3 @@ class SeasonInfo(dict):
|
||||
subtitle: str
|
||||
added: bool
|
||||
eps_collect: bool
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -4,8 +4,8 @@ from pydantic import BaseModel, Field
|
||||
|
||||
|
||||
class Program(BaseModel):
|
||||
sleep_time: int = Field(7200, description="Sleep time")
|
||||
rename_times: int = Field(20, description="Rename times in one loop")
|
||||
rss_time: int = Field(7200, description="Sleep time")
|
||||
rename_time: int = Field(60, description="Rename times in one loop")
|
||||
webui_port: int = Field(7892, description="WebUI port")
|
||||
|
||||
|
||||
@@ -23,7 +23,7 @@ class RSSParser(BaseModel):
|
||||
type: str = Field("mikan", description="RSS parser type")
|
||||
token: str = Field("token", description="RSS parser token")
|
||||
custom_url: str = Field("mikanani.me", description="Custom RSS host url")
|
||||
enable_tmdb: bool = Field(False, description="Enable TMDB")
|
||||
parser_type: str = Field("parser", description="Parser type")
|
||||
filter: list[str] = Field(["720", r"\d+-\d"], description="Filter")
|
||||
language: str = "zh"
|
||||
|
||||
@@ -57,7 +57,6 @@ class Notification(BaseModel):
|
||||
|
||||
|
||||
class Config(BaseModel):
|
||||
data_version: float = Field(5.0, description="Data version")
|
||||
program: Program = Program()
|
||||
downloader: Downloader = Downloader()
|
||||
rss_parser: RSSParser = RSSParser()
|
||||
|
||||
@@ -1,12 +1,32 @@
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
|
||||
class TorrentInfo(BaseModel):
|
||||
class TorrentBase(BaseModel):
|
||||
name: str = Field(...)
|
||||
link: str = Field(...)
|
||||
torrent_link: str = Field(...)
|
||||
homepage: str | None = Field(None)
|
||||
|
||||
|
||||
class FileSet(BaseModel):
|
||||
media_path: str = Field(...)
|
||||
sc_subtitle: str | None = Field(None)
|
||||
tc_subtitle: str | None = Field(None)
|
||||
tc_subtitle: str | None = Field(None)
|
||||
|
||||
|
||||
class EpisodeFile(BaseModel):
|
||||
media_path: str = Field(...)
|
||||
group: str | None = Field(None)
|
||||
title: str = Field(...)
|
||||
season: int = Field(...)
|
||||
episode: int = Field(None)
|
||||
suffix: str = Field(..., regex=r"\.(mkv|mp4|MKV|MP4)$")
|
||||
|
||||
|
||||
class SubtitleFile(BaseModel):
|
||||
media_path: str = Field(...)
|
||||
group: str | None = Field(None)
|
||||
title: str = Field(...)
|
||||
season: int = Field(...)
|
||||
episode: int = Field(None)
|
||||
language: str = Field(..., regex=r"(zh|zh-tw)")
|
||||
suffix: str = Field(..., regex=r"\.(ass|srt|ASS|SRT)$")
|
||||
|
||||
22
src/module/models/user.py
Normal file
22
src/module/models/user.py
Normal file
@@ -0,0 +1,22 @@
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
|
||||
class User(BaseModel):
|
||||
username: str = Field(
|
||||
"admin", min_length=4, max_length=20, regex=r"^[a-zA-Z0-9_]+$"
|
||||
)
|
||||
password: str = Field("adminadmin", min_length=8)
|
||||
|
||||
|
||||
class UserLogin(BaseModel):
|
||||
username: str
|
||||
password: str = Field(..., min_length=8)
|
||||
|
||||
|
||||
class Token(BaseModel):
|
||||
token: str
|
||||
token_type: str
|
||||
|
||||
|
||||
class TokenData(BaseModel):
|
||||
username: str | None = None
|
||||
@@ -1,2 +1 @@
|
||||
from .request_contents import RequestContent
|
||||
from .notification import PostNotification, ServerChanNotification
|
||||
from .request_contents import RequestContent, TorrentInfo
|
||||
|
||||
@@ -1,63 +0,0 @@
|
||||
import logging
|
||||
|
||||
from .request_contents import RequestContent
|
||||
from module.conf import settings
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class PostNotification:
|
||||
def __init__(self):
|
||||
self.client = self.getClient()
|
||||
|
||||
@staticmethod
|
||||
def getClient():
|
||||
if settings.notification.type.lower() == "telegram":
|
||||
return TelegramNotification()
|
||||
elif settings.notification.type.lower() == "server-chan":
|
||||
return ServerChanNotification()
|
||||
else:
|
||||
return None
|
||||
|
||||
def send_msg(self, title: str, desp: str) -> bool:
|
||||
if not settings.notification.enable:
|
||||
return False
|
||||
if self.client is None:
|
||||
return False
|
||||
return self.client.send_msg(title, desp)
|
||||
|
||||
|
||||
class TelegramNotification:
|
||||
def __init__(self):
|
||||
self.token = settings.notification.token
|
||||
self.chat_id = settings.notification.chat_id
|
||||
self.notification_url = f"https://api.telegram.org/bot{self.token}/sendMessage"
|
||||
|
||||
def send_msg(self, title: str, desp: str):
|
||||
data = {
|
||||
"chat_id": settings.notification.chat_id,
|
||||
"text": f"{title}\n{desp}",
|
||||
"disable_notification": True,
|
||||
}
|
||||
with RequestContent() as req:
|
||||
resp = req.post_data(self.notification_url, data)
|
||||
logger.debug(f"Telegram notification: {resp.status_code}")
|
||||
return resp.status_code == 200
|
||||
|
||||
|
||||
class ServerChanNotification:
|
||||
"""Server酱推送"""
|
||||
def __init__(self):
|
||||
self.token = settings.notification.token
|
||||
self.notification_url = f"https://sctapi.ftqq.com/{self.token}.send"
|
||||
|
||||
def send_msg(self, title: str, desp: str) -> bool:
|
||||
data = {
|
||||
"title": title,
|
||||
"desp": desp,
|
||||
}
|
||||
with RequestContent() as req:
|
||||
resp = req.post_data(self.notification_url, data)
|
||||
logger.debug(f"ServerChan notification: {resp.status_code}")
|
||||
return resp.status_code == 200
|
||||
@@ -2,40 +2,76 @@ import re
|
||||
import xml.etree.ElementTree
|
||||
from dataclasses import dataclass
|
||||
|
||||
from .request_url import RequestURL
|
||||
from module.conf import settings
|
||||
from bs4 import BeautifulSoup
|
||||
|
||||
FILTER = "|".join(settings.rss_parser.filter)
|
||||
from .request_url import RequestURL
|
||||
from .site import mikan_parser
|
||||
from module.conf import settings
|
||||
|
||||
|
||||
@dataclass
|
||||
class TorrentInfo:
|
||||
name: str
|
||||
torrent_link: str
|
||||
homepage: str
|
||||
_poster_link: str | None = None
|
||||
_official_title: str | None = None
|
||||
|
||||
def __fetch_mikan_info(self):
|
||||
if self._poster_link is None or self._official_title is None:
|
||||
with RequestContent() as req:
|
||||
self._poster_link, self._official_title = req.get_mikan_info(
|
||||
self.homepage
|
||||
)
|
||||
|
||||
@property
|
||||
def poster_link(self) -> str:
|
||||
self.__fetch_mikan_info()
|
||||
return self._poster_link
|
||||
|
||||
@property
|
||||
def official_title(self) -> str:
|
||||
self.__fetch_mikan_info()
|
||||
return self._official_title
|
||||
|
||||
|
||||
class RequestContent(RequestURL):
|
||||
# Mikanani RSS
|
||||
def get_torrents(self, _url: str, _filter: bool = True) -> [TorrentInfo]:
|
||||
soup = self.get_xml(_url)
|
||||
torrent_titles = []
|
||||
torrent_urls = []
|
||||
def get_torrents(
|
||||
self,
|
||||
_url: str,
|
||||
_filter: str = "|".join(settings.rss_parser.filter),
|
||||
retry: int = 3,
|
||||
) -> [TorrentInfo]:
|
||||
try:
|
||||
soup = self.get_xml(_url, retry)
|
||||
torrent_titles, torrent_urls, torrent_homepage = mikan_parser(soup)
|
||||
|
||||
for item in soup.findall("./channel/item"):
|
||||
torrent_titles.append(item.find("title").text)
|
||||
torrent_urls.append(item.find("enclosure").attrib['url'])
|
||||
torrents = []
|
||||
for _title, torrent_url, homepage in zip(
|
||||
torrent_titles, torrent_urls, torrent_homepage
|
||||
):
|
||||
if re.search(_filter, _title) is None:
|
||||
torrents.append(TorrentInfo(name=_title, torrent_link=torrent_url, homepage=homepage))
|
||||
return torrents
|
||||
except ConnectionError:
|
||||
return []
|
||||
|
||||
torrents = []
|
||||
for _title, torrent_url in zip(torrent_titles, torrent_urls):
|
||||
if _filter:
|
||||
if re.search(FILTER, _title) is None:
|
||||
torrents.append(TorrentInfo(_title, torrent_url))
|
||||
else:
|
||||
torrents.append(TorrentInfo(_title, torrent_url))
|
||||
return torrents
|
||||
def get_mikan_info(self, _url) -> tuple[str, str]:
|
||||
content = self.get_html(_url)
|
||||
soup = BeautifulSoup(content, "html.parser")
|
||||
poster_div = soup.find("div", {"class": "bangumi-poster"})
|
||||
poster_style = poster_div.get("style")
|
||||
official_title = soup.select_one(
|
||||
'p.bangumi-title a[href^="/Home/Bangumi/"]'
|
||||
).text
|
||||
if poster_style:
|
||||
poster_path = poster_style.split("url('")[1].split("')")[0]
|
||||
return poster_path, official_title
|
||||
return "", ""
|
||||
|
||||
def get_xml(self, _url) -> xml.etree.ElementTree.ElementTree:
|
||||
return xml.etree.ElementTree.fromstring(self.get_url(_url).text)
|
||||
def get_xml(self, _url, retry: int = 3) -> xml.etree.ElementTree.Element:
|
||||
return xml.etree.ElementTree.fromstring(self.get_url(_url, retry).text)
|
||||
|
||||
# API JSON
|
||||
def get_json(self, _url) -> dict:
|
||||
@@ -52,3 +88,6 @@ class RequestContent(RequestURL):
|
||||
|
||||
def get_content(self, _url):
|
||||
return self.get_url(_url).content
|
||||
|
||||
def check_connection(self, _url):
|
||||
return self.check_url(_url)
|
||||
|
||||
@@ -12,64 +12,83 @@ logger = logging.getLogger(__name__)
|
||||
|
||||
class RequestURL:
|
||||
def __init__(self):
|
||||
self.header = {
|
||||
"user-agent": "Mozilla/5.0",
|
||||
"Accept": "application/xml"
|
||||
}
|
||||
self.header = {"user-agent": "Mozilla/5.0", "Accept": "application/xml"}
|
||||
|
||||
def get_url(self, url):
|
||||
def get_url(self, url, retry=3):
|
||||
try_time = 0
|
||||
while try_time < 5:
|
||||
while True:
|
||||
try:
|
||||
req = self.session.get(url=url, headers=self.header)
|
||||
req = self.session.get(url=url, headers=self.header, timeout=5)
|
||||
req.raise_for_status()
|
||||
return req
|
||||
except requests.RequestException as e:
|
||||
logger.debug(f"URL: {url}")
|
||||
logger.debug(e)
|
||||
logger.warning(f"Cannot connect to {url}. Wait for 5 seconds.")
|
||||
logger.warning("Please check DNS/Connection settings")
|
||||
time.sleep(5)
|
||||
except requests.RequestException:
|
||||
logger.warning(f"[Network] Cannot connect to {url}. Wait for 5 seconds.")
|
||||
try_time += 1
|
||||
if try_time >= retry:
|
||||
break
|
||||
time.sleep(5)
|
||||
except Exception as e:
|
||||
logger.debug(f"URL: {url}")
|
||||
logger.debug(e)
|
||||
break
|
||||
logger.error(f"[Network] Failed connecting to {url}")
|
||||
logger.warning("[Network] Please check DNS/Connection settings")
|
||||
raise ConnectionError(f"Failed connecting to {url}")
|
||||
|
||||
def post_url(self, url: str, data: dict):
|
||||
def post_url(self, url: str, data: dict, retry=3):
|
||||
try_time = 0
|
||||
while try_time < 5:
|
||||
while True:
|
||||
try:
|
||||
req = self.session.post(url=url, headers=self.header, data=data)
|
||||
req = self.session.post(
|
||||
url=url, headers=self.header, data=data, timeout=5
|
||||
)
|
||||
req.raise_for_status()
|
||||
return req
|
||||
except requests.RequestException as e:
|
||||
logger.debug(e)
|
||||
logger.warning(f"Cannot connect to {url}.")
|
||||
logger.warning("Please check DNS/Connection settings")
|
||||
time.sleep(5)
|
||||
except requests.RequestException:
|
||||
logger.warning(f"[Network] Cannot connect to {url}. Wait for 5 seconds.")
|
||||
try_time += 1
|
||||
if try_time >= retry:
|
||||
break
|
||||
time.sleep(5)
|
||||
except Exception as e:
|
||||
logger.debug(f"URL: {url}")
|
||||
logger.debug(e)
|
||||
break
|
||||
logger.error(f"[Network] Failed connecting to {url}")
|
||||
logger.warning("[Network] Please check DNS/Connection settings")
|
||||
raise ConnectionError(f"Failed connecting to {url}")
|
||||
|
||||
def check_url(self, url: str):
|
||||
if "://" not in url:
|
||||
url = f"http://{url}"
|
||||
try:
|
||||
req = requests.head(url=url, headers=self.header, timeout=5)
|
||||
req.raise_for_status()
|
||||
return True
|
||||
except requests.RequestException as e:
|
||||
logger.debug(f"[Network] Cannot connect to {url}.")
|
||||
return False
|
||||
|
||||
def __enter__(self):
|
||||
self.session = requests.Session()
|
||||
if settings.proxy.enable:
|
||||
if settings.proxy.type == "http":
|
||||
url = f"http://{settings.proxy.host}:{settings.proxy.port}"
|
||||
if "http" in settings.proxy.type:
|
||||
url = f"{settings.proxy.type}://{settings.proxy.host}:{settings.proxy.port}"
|
||||
self.session.proxies = {
|
||||
"https": url,
|
||||
"http": url,
|
||||
}
|
||||
elif settings.proxy.type == "socks5":
|
||||
socks.set_default_proxy(socks.SOCKS5, addr=settings.proxy.host, port=settings.proxy.port, rdns=True,
|
||||
username=settings.proxy.username, password=settings.proxy.password)
|
||||
socks.set_default_proxy(
|
||||
socks.SOCKS5,
|
||||
addr=settings.proxy.host,
|
||||
port=settings.proxy.port,
|
||||
rdns=True,
|
||||
username=settings.proxy.username,
|
||||
password=settings.proxy.password,
|
||||
)
|
||||
socket.socket = socks.socksocket
|
||||
else:
|
||||
logger.error(f"[Network] Unsupported proxy type: {settings.proxy.type}")
|
||||
return self
|
||||
|
||||
def __exit__(self, exc_type, exc_val, exc_tb):
|
||||
self.session.close()
|
||||
|
||||
|
||||
|
||||
1
src/module/network/site/__init__.py
Normal file
1
src/module/network/site/__init__.py
Normal file
@@ -0,0 +1 @@
|
||||
from .mikan import mikan_parser
|
||||
9
src/module/network/site/mikan.py
Normal file
9
src/module/network/site/mikan.py
Normal file
@@ -0,0 +1,9 @@
|
||||
def mikan_parser(soup):
|
||||
torrent_titles = []
|
||||
torrent_urls = []
|
||||
torrent_homepage = []
|
||||
for item in soup.findall("./channel/item"):
|
||||
torrent_titles.append(item.find("title").text)
|
||||
torrent_urls.append(item.find("enclosure").attrib["url"])
|
||||
torrent_homepage.append(item.find("link").text)
|
||||
return torrent_titles, torrent_urls, torrent_homepage
|
||||
1
src/module/notification/__init__.py
Normal file
1
src/module/notification/__init__.py
Normal file
@@ -0,0 +1 @@
|
||||
from .notification import PostNotification
|
||||
63
src/module/notification/notification.py
Normal file
63
src/module/notification/notification.py
Normal file
@@ -0,0 +1,63 @@
|
||||
import logging
|
||||
|
||||
from .plugin import *
|
||||
|
||||
from module.models import Notification
|
||||
from module.conf import settings
|
||||
from module.database import BangumiDatabase
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def getClient(type=settings.notification.type):
|
||||
if type.lower() == "telegram":
|
||||
return TelegramNotification
|
||||
elif type.lower() == "server-chan":
|
||||
return ServerChanNotification
|
||||
elif type.lower() == "bark":
|
||||
return BarkNotification
|
||||
else:
|
||||
return None
|
||||
|
||||
|
||||
class PostNotification(getClient()):
|
||||
def __init__(self):
|
||||
super().__init__(
|
||||
token=settings.notification.token,
|
||||
chat_id=settings.notification.chat_id
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _gen_message(notify: Notification) -> str:
|
||||
with BangumiDatabase() as db:
|
||||
poster_path = db.match_poster(notify.official_title)
|
||||
if poster_path:
|
||||
poster_link = "https://mikanani.me" + poster_path
|
||||
text = f"""
|
||||
番剧名称:{notify.official_title}\n季度: 第{notify.season}季\n更新集数: 第{notify.episode}集\n{poster_link}\n
|
||||
"""
|
||||
else:
|
||||
text = f"""
|
||||
番剧名称:{notify.official_title}\n季度: 第{notify.season}季\n更新集数: 第{notify.episode}集\n
|
||||
"""
|
||||
return text
|
||||
|
||||
def send_msg(self, notify: Notification) -> bool:
|
||||
text = self._gen_message(notify)
|
||||
try:
|
||||
self.post_msg(text)
|
||||
logger.debug(f"Send notification: {notify.official_title}")
|
||||
except Exception as e:
|
||||
logger.warning(f"Failed to send notification: {e}")
|
||||
return False
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
info = Notification(
|
||||
official_title="魔法纪录 魔法少女小圆外传",
|
||||
season=2,
|
||||
episode=1,
|
||||
)
|
||||
with PostNotification() as client:
|
||||
client.send_msg(info)
|
||||
3
src/module/notification/plugin/__init__.py
Normal file
3
src/module/notification/plugin/__init__.py
Normal file
@@ -0,0 +1,3 @@
|
||||
from .bark import BarkNotification
|
||||
from .server_chan import ServerChanNotification
|
||||
from .telegram import TelegramNotification
|
||||
18
src/module/notification/plugin/bark.py
Normal file
18
src/module/notification/plugin/bark.py
Normal file
@@ -0,0 +1,18 @@
|
||||
import logging
|
||||
from module.network import RequestContent
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class BarkNotification(RequestContent):
|
||||
def __init__(self, token, **kwargs):
|
||||
super().__init__()
|
||||
self.token = token
|
||||
self.notification_url = "https://api.day.app/push"
|
||||
|
||||
def post_msg(self, text) -> bool:
|
||||
data = {"title": "AutoBangumi 番剧更新", "body": text, "device_key": self.token}
|
||||
resp = self.post_data(self.notification_url, data)
|
||||
logger.debug(f"Bark notification: {resp.status_code}")
|
||||
return resp.status_code == 200
|
||||
22
src/module/notification/plugin/server_chan.py
Normal file
22
src/module/notification/plugin/server_chan.py
Normal file
@@ -0,0 +1,22 @@
|
||||
import logging
|
||||
|
||||
from module.network import RequestContent
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class ServerChanNotification(RequestContent):
|
||||
"""Server酱推送"""
|
||||
|
||||
def __init__(self, token, **kwargs):
|
||||
super().__init__()
|
||||
self.notification_url = f"https://sctapi.ftqq.com/{token}.send"
|
||||
|
||||
def post_msg(self, text: str) -> bool:
|
||||
data = {
|
||||
"title": "AutoBangumi 番剧更新",
|
||||
"desp": text,
|
||||
}
|
||||
resp = self.post_data(self.notification_url, data)
|
||||
logger.debug(f"ServerChan notification: {resp.status_code}")
|
||||
return resp.status_code == 200
|
||||
18
src/module/notification/plugin/slack.py
Normal file
18
src/module/notification/plugin/slack.py
Normal file
@@ -0,0 +1,18 @@
|
||||
import logging
|
||||
|
||||
from module.network import RequestContent
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class SlackNotification(RequestContent):
|
||||
def __init__(self, token, **kwargs):
|
||||
super().__init__()
|
||||
self.token = token
|
||||
self.notification_url = "https://api.day.app/push"
|
||||
|
||||
def post_msg(self, text) -> bool:
|
||||
data = {"title": "AutoBangumi 番剧更新", "body": text, "device_key": self.token}
|
||||
resp = self.post_data(self.notification_url, data)
|
||||
logger.debug(f"Bark notification: {resp.status_code}")
|
||||
return resp.status_code == 200
|
||||
22
src/module/notification/plugin/telegram.py
Normal file
22
src/module/notification/plugin/telegram.py
Normal file
@@ -0,0 +1,22 @@
|
||||
import logging
|
||||
|
||||
from module.network.request_contents import RequestContent
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class TelegramNotification(RequestContent):
|
||||
def __init__(self, token, chat_id):
|
||||
super().__init__()
|
||||
self.notification_url = f"https://api.telegram.org/bot{token}/sendMessage"
|
||||
self.chat_id = chat_id
|
||||
|
||||
def post_msg(self, text: str) -> bool:
|
||||
data = {
|
||||
"chat_id": self.chat_id,
|
||||
"text": text,
|
||||
"disable_notification": True,
|
||||
}
|
||||
resp = self.post_data(self.notification_url, data)
|
||||
logger.debug(f"Telegram notification: {resp.status_code}")
|
||||
return resp.status_code == 200
|
||||
@@ -1,4 +1,3 @@
|
||||
from .raw_parser import raw_parser
|
||||
from .torrent_parser import torrent_parser
|
||||
from .tmdb_parser import TMDBMatcher
|
||||
|
||||
from .tmdb_parser import tmdb_parser
|
||||
|
||||
@@ -1,17 +1,14 @@
|
||||
from module.network import RequestContent
|
||||
|
||||
|
||||
class BgmAPI:
|
||||
def __init__(self):
|
||||
self.search_url = lambda e: \
|
||||
f"https://api.bgm.tv/search/subject/{e}?type=2"
|
||||
self.info_url = lambda e: \
|
||||
f"https://api.bgm.tv/subject/{e}"
|
||||
search_url = lambda e: f"https://api.bgm.tv/search/subject/{e}?responseGroup=large"
|
||||
|
||||
def search(self, title):
|
||||
url = self.search_url(title)
|
||||
with RequestContent() as req:
|
||||
contents = req.get_json(url)["list"]
|
||||
if contents.__len__() == 0:
|
||||
return None
|
||||
return contents[0]["name"], contents[0]["name_cn"]
|
||||
|
||||
def bgm_parser(title):
|
||||
url = search_url(title)
|
||||
with RequestContent() as req:
|
||||
contents = req.get_json(url)
|
||||
if contents:
|
||||
return contents[0]
|
||||
else:
|
||||
return None
|
||||
|
||||
@@ -108,6 +108,7 @@ def name_process(name: str):
|
||||
name_en = item.strip()
|
||||
return name_en, name_zh, name_jp
|
||||
|
||||
|
||||
def find_tags(other):
|
||||
elements = re.sub(r"[\[\]()()]", " ", other).split(" ")
|
||||
# find CHT
|
||||
@@ -136,9 +137,9 @@ def process(raw_title: str):
|
||||
# 翻译组的名字
|
||||
match_obj = TITLE_RE.match(content_title)
|
||||
# 处理标题
|
||||
season_info, episode_info, other = list(map(
|
||||
lambda x: x.strip(), match_obj.groups()
|
||||
))
|
||||
season_info, episode_info, other = list(
|
||||
map(lambda x: x.strip(), match_obj.groups())
|
||||
)
|
||||
process_raw = prefix_process(season_info, group)
|
||||
# 处理 前缀
|
||||
raw_name, season_raw, season = season_process(process_raw)
|
||||
@@ -155,7 +156,18 @@ def process(raw_title: str):
|
||||
if raw_episode is not None:
|
||||
episode = int(raw_episode.group())
|
||||
sub, dpi, source = find_tags(other) # 剩余信息处理
|
||||
return name_en, name_zh, name_jp, season, season_raw, episode, sub, dpi, source, group
|
||||
return (
|
||||
name_en,
|
||||
name_zh,
|
||||
name_jp,
|
||||
season,
|
||||
season_raw,
|
||||
episode,
|
||||
sub,
|
||||
dpi,
|
||||
source,
|
||||
group,
|
||||
)
|
||||
|
||||
|
||||
def raw_parser(raw: str) -> Episode | None:
|
||||
@@ -163,14 +175,7 @@ def raw_parser(raw: str) -> Episode | None:
|
||||
if ret is None:
|
||||
logger.error(f"Parser cannot analyse {raw}")
|
||||
return None
|
||||
name_en, name_zh, name_jp, season, sr, episode, \
|
||||
sub, dpi, source, group = ret
|
||||
return Episode(name_en, name_zh, name_jp, season, sr, episode, sub, group, dpi, source)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
title = "【幻樱字幕组】【4月新番】【古见同学有交流障碍症 第二季 Komi-san wa, Komyushou Desu. S02】【22】【GB_MP4】【1920X1080】"
|
||||
ep = raw_parser(title)
|
||||
print(ep)
|
||||
|
||||
|
||||
name_en, name_zh, name_jp, season, sr, episode, sub, dpi, source, group = ret
|
||||
return Episode(
|
||||
name_en, name_zh, name_jp, season, sr, episode, sub, group, dpi, source
|
||||
)
|
||||
|
||||
@@ -9,65 +9,70 @@ from module.conf import TMDB_API
|
||||
@dataclass
|
||||
class TMDBInfo:
|
||||
id: int
|
||||
title_jp: str
|
||||
title_zh: str
|
||||
title: str
|
||||
original_title: str
|
||||
season: list[dict]
|
||||
last_season: int
|
||||
year_number: int
|
||||
year: str
|
||||
|
||||
|
||||
class TMDBMatcher:
|
||||
def __init__(self):
|
||||
self.search_url = lambda e: \
|
||||
f"https://api.themoviedb.org/3/search/tv?api_key={TMDB_API}&page=1&query={e}&include_adult=false"
|
||||
self.info_url = lambda e: \
|
||||
f"https://api.themoviedb.org/3/tv/{e}?api_key={TMDB_API}&language=zh-CN"
|
||||
LANGUAGE = {
|
||||
"zh": "zh-CN",
|
||||
"jp": "ja-JP",
|
||||
"en": "en-US"
|
||||
}
|
||||
|
||||
def is_animation(self, tv_id) -> bool:
|
||||
url_info = self.info_url(tv_id)
|
||||
with RequestContent() as req:
|
||||
type_id = req.get_json(url_info)["genres"]
|
||||
for type in type_id:
|
||||
if type.get("id") == 16:
|
||||
return True
|
||||
return False
|
||||
search_url = lambda e: \
|
||||
f"https://api.themoviedb.org/3/search/tv?api_key={TMDB_API}&page=1&query={e}&include_adult=false"
|
||||
info_url = lambda e, key: \
|
||||
f"https://api.themoviedb.org/3/tv/{e}?api_key={TMDB_API}&language={LANGUAGE[key]}"
|
||||
|
||||
# def get_zh_title(self, id):
|
||||
# alt_title_url = self.alt_title_url(id)
|
||||
# titles = self._request.get_content(alt_title_url, content="json")
|
||||
# for title in titles:
|
||||
# if title["iso_3166_1"] == "CN":
|
||||
# return title["title"]
|
||||
# return None
|
||||
|
||||
@staticmethod
|
||||
def get_season(seasons: list) -> int:
|
||||
for season in seasons:
|
||||
if re.search(r"第 \d 季", season.get("season")) is not None:
|
||||
date = season.get("air_date").split("-")
|
||||
[year, _ , _] = date
|
||||
now_year = time.localtime().tm_year
|
||||
if int(year) == now_year:
|
||||
return int(re.findall(r"\d", season.get("season"))[0])
|
||||
def is_animation(tv_id, language) -> bool:
|
||||
url_info = info_url(tv_id, language)
|
||||
with RequestContent() as req:
|
||||
type_id = req.get_json(url_info)["genres"]
|
||||
for type in type_id:
|
||||
if type.get("id") == 16:
|
||||
return True
|
||||
return False
|
||||
|
||||
def tmdb_search(self, title) -> TMDBInfo:
|
||||
with RequestContent() as req:
|
||||
url = self.search_url(title)
|
||||
|
||||
def get_season(seasons: list) -> int:
|
||||
for season in seasons:
|
||||
if re.search(r"第 \d 季", season.get("season")) is not None:
|
||||
date = season.get("air_date").split("-")
|
||||
[year, _ , _] = date
|
||||
now_year = time.localtime().tm_year
|
||||
if int(year) <= now_year:
|
||||
return int(re.findall(r"\d", season.get("season"))[0])
|
||||
|
||||
|
||||
def tmdb_parser(title, language) -> TMDBInfo | None:
|
||||
with RequestContent() as req:
|
||||
url = search_url(title)
|
||||
contents = req.get_json(url).get("results")
|
||||
if contents.__len__() == 0:
|
||||
url = search_url(title.replace(" ", ""))
|
||||
contents = req.get_json(url).get("results")
|
||||
if contents.__len__() == 0:
|
||||
url = self.search_url(title.replace(" ", ""))
|
||||
contents = req.get_json(url).get("results")
|
||||
# 判断动画
|
||||
# 判断动画
|
||||
if contents:
|
||||
for content in contents:
|
||||
id = content["id"]
|
||||
if self.is_animation(id):
|
||||
if is_animation(id, language):
|
||||
break
|
||||
url_info = self.info_url(id)
|
||||
url_info = info_url(id, language)
|
||||
info_content = req.get_json(url_info)
|
||||
season = [{"season": s.get("name"), "air_date": s.get("air_date"), "poster_path": s.get("poster_path")} for s in info_content.get("seasons")]
|
||||
last_season = get_season(season)
|
||||
original_title = info_content.get("original_name")
|
||||
official_title = info_content.get("name")
|
||||
year_number = info_content.get("first_air_date").split("-")[0]
|
||||
return TMDBInfo(id, official_title, original_title, season, last_season, str(year_number))
|
||||
else:
|
||||
return None
|
||||
|
||||
season = [{"season": s.get("name"), "air_date": s.get("air_date")} for s in info_content.get("seasons")]
|
||||
last_season = self.get_season(season)
|
||||
title_jp = info_content.get("original_name")
|
||||
title_zh = info_content.get("name")
|
||||
year_number = info_content.get("first_air_date").split("-")[0]
|
||||
return TMDBInfo(id, title_jp, title_zh, season, last_season, year_number)
|
||||
|
||||
if __name__ == '__main__':
|
||||
title = "鬼灭之刃"
|
||||
print(tmdb_parser(title, "zh"))
|
||||
@@ -1,21 +1,16 @@
|
||||
import re
|
||||
import logging
|
||||
from dataclasses import dataclass
|
||||
import os.path as unix_path
|
||||
import ntpath as win_path
|
||||
|
||||
from module.models import EpisodeFile, SubtitleFile
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@dataclass
|
||||
class DownloadInfo:
|
||||
name: str
|
||||
season: int
|
||||
suffix: str
|
||||
file_name: str
|
||||
folder_name: str
|
||||
|
||||
PLATFORM = "Unix"
|
||||
|
||||
RULES = [
|
||||
r"(.*) - (\d{1,4}|\d{1,4}\.\d{1,2})(?:v\d{1,2})?(?: )?(?:END)?(.*)",
|
||||
r"(.*) - (\d{1,4}(?!\d|p)|\d{1,4}\.\d{1,2}(?!\d|p))(?:v\d{1,2})?(?: )?(?:END)?(.*)",
|
||||
r"(.*)[\[\ E](\d{1,4}|\d{1,4}\.\d{1,2})(?:v\d{1,2})?(?: )?(?:END)?[\]\ ](.*)",
|
||||
r"(.*)\[(?:第)?(\d*\.*\d*)[话集話](?:END)?\](.*)",
|
||||
r"(.*)第(\d*\.*\d*)[话話集](?:END)?(.*)",
|
||||
@@ -28,145 +23,78 @@ SUBTITLE_LANG = {
|
||||
}
|
||||
|
||||
|
||||
def rename_init(name, folder_name, season, suffix) -> DownloadInfo:
|
||||
n = re.split(r"[\[\]()【】()]", name)
|
||||
suffix = suffix if suffix else n[-1]
|
||||
if len(n) > 1:
|
||||
file_name = name.replace(f"[{n[1]}]", "")
|
||||
def split_path(torrent_path: str) -> str:
|
||||
if PLATFORM == "Windows":
|
||||
return win_path.split(torrent_path)[-1]
|
||||
else:
|
||||
file_name = name
|
||||
if season < 10:
|
||||
season = f"0{season}"
|
||||
return DownloadInfo(name, season, suffix, file_name, folder_name)
|
||||
return unix_path.split(torrent_path)[-1]
|
||||
|
||||
|
||||
def rename_normal(info: DownloadInfo):
|
||||
for rule in RULES:
|
||||
match_obj = re.match(rule, info.name, re.I)
|
||||
if match_obj is not None:
|
||||
episode = match_obj.group(2)
|
||||
title = re.sub(r"([Ss]|Season )\d{1,3}", "", match_obj.group(1)).strip()
|
||||
new_name = f"{title} S{info.season}E{episode}{match_obj.group(3)}"
|
||||
return new_name
|
||||
def get_group(group_and_title) -> tuple[str | None, str]:
|
||||
n = re.split(r"[\[\]()【】()]", group_and_title)
|
||||
while "" in n:
|
||||
n.remove("")
|
||||
if len(n) > 1:
|
||||
if re.match(r"\d+", n[1]):
|
||||
return None, group_and_title
|
||||
return n[0], n[1]
|
||||
else:
|
||||
return None, n[0]
|
||||
|
||||
|
||||
def rename_pn(info: DownloadInfo):
|
||||
for rule in RULES:
|
||||
match_obj = re.match(rule, info.file_name, re.I)
|
||||
if match_obj is not None:
|
||||
title = re.sub(r"([Ss]|Season )\d{1,3}", "", match_obj.group(1)).strip()
|
||||
title = title if title != "" else info.folder_name
|
||||
episode = match_obj.group(2)
|
||||
new_name = re.sub(
|
||||
r"[\[\]]",
|
||||
"",
|
||||
f"{title} S{info.season}E{episode}{info.suffix}",
|
||||
)
|
||||
return new_name
|
||||
def get_season_and_title(season_and_title) -> tuple[str, int]:
|
||||
title = re.sub(r"([Ss]|Season )\d{1,3}", "", season_and_title).strip()
|
||||
try:
|
||||
season = re.search(r"([Ss]|Season )(\d{1,3})", season_and_title, re.I).group(2)
|
||||
except AttributeError:
|
||||
season = 1
|
||||
return title, int(season)
|
||||
|
||||
|
||||
def rename_advance(info: DownloadInfo):
|
||||
for rule in RULES:
|
||||
match_obj = re.match(rule, info.file_name, re.I)
|
||||
if match_obj is not None:
|
||||
episode = match_obj.group(2)
|
||||
new_name = re.sub(
|
||||
r"[\[\]]",
|
||||
"",
|
||||
f"{info.folder_name} S{info.season}E{episode}{info.suffix}",
|
||||
)
|
||||
return new_name
|
||||
|
||||
|
||||
def rename_no_season_pn(info: DownloadInfo):
|
||||
for rule in RULES:
|
||||
match_obj = re.match(rule, info.file_name, re.I)
|
||||
if match_obj is not None:
|
||||
title = match_obj.group(1).strip()
|
||||
episode = match_obj.group(2)
|
||||
new_name = re.sub(
|
||||
r"[\[\]]",
|
||||
"",
|
||||
f"{title} E{episode}{info.suffix}",
|
||||
)
|
||||
return new_name
|
||||
|
||||
|
||||
def rename_none(info: DownloadInfo):
|
||||
return info.name
|
||||
|
||||
|
||||
def rename_subtitle(info: DownloadInfo):
|
||||
subtitle_lang = "zh"
|
||||
break_flag = False
|
||||
def get_subtitle_lang(subtitle_name: str) -> str:
|
||||
for key, value in SUBTITLE_LANG.items():
|
||||
for lang in value:
|
||||
if lang in info.name:
|
||||
subtitle_lang = key
|
||||
break_flag = True
|
||||
break
|
||||
if break_flag:
|
||||
break
|
||||
for rule in RULES:
|
||||
match_obj = re.match(rule, info.file_name, re.I)
|
||||
if match_obj is not None:
|
||||
title = re.sub(r"([Ss]|Season )\d{1,3}", "", match_obj.group(1)).strip()
|
||||
title = title if title != "" else info.folder_name
|
||||
new_name = re.sub(
|
||||
r"[\[\]]",
|
||||
"",
|
||||
f"{title} S{info.season}E{match_obj.group(2)}.{subtitle_lang}{info.suffix}",
|
||||
)
|
||||
return new_name
|
||||
|
||||
|
||||
def rename_subtitle_advance(info: DownloadInfo):
|
||||
subtitle_lang = "zh"
|
||||
break_flag = False
|
||||
for key, value in SUBTITLE_LANG.items():
|
||||
for lang in value:
|
||||
if lang in info.name:
|
||||
subtitle_lang = key
|
||||
break_flag = True
|
||||
break
|
||||
if break_flag:
|
||||
break
|
||||
for rule in RULES:
|
||||
match_obj = re.match(rule, info.file_name, re.I)
|
||||
if match_obj is not None:
|
||||
new_name = re.sub(
|
||||
r"[\[\]]",
|
||||
"",
|
||||
f"{info.folder_name} S{info.season}E{match_obj.group(2)}.{subtitle_lang}{info.suffix}",
|
||||
)
|
||||
return new_name
|
||||
|
||||
|
||||
METHODS = {
|
||||
"normal": rename_normal,
|
||||
"pn": rename_pn,
|
||||
"advance": rename_advance,
|
||||
"no_season_pn": rename_no_season_pn,
|
||||
"none": rename_none,
|
||||
"subtitle_pn": rename_subtitle,
|
||||
"subtitle_advance": rename_subtitle_advance,
|
||||
}
|
||||
for v in value:
|
||||
if v in subtitle_name:
|
||||
return key
|
||||
|
||||
|
||||
def torrent_parser(
|
||||
file_name: str,
|
||||
folder_name: str,
|
||||
season: int,
|
||||
suffix: str,
|
||||
method: str = "pn",
|
||||
):
|
||||
info = rename_init(file_name, folder_name, season, suffix)
|
||||
return METHODS[method.lower()](info)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
title = "海盗战记 S02E17.zh.ass"
|
||||
folder_name = "海盗战记"
|
||||
season = 2
|
||||
suffix = ".ass"
|
||||
print(torrent_parser(title, folder_name, season, suffix, method="advance"))
|
||||
torrent_path: str,
|
||||
torrent_name: str | None = None,
|
||||
season: int | None = None,
|
||||
file_type: str = "media",
|
||||
) -> EpisodeFile | SubtitleFile:
|
||||
media_path = split_path(torrent_path)
|
||||
for rule in RULES:
|
||||
if torrent_name:
|
||||
match_obj = re.match(rule, torrent_name, re.I)
|
||||
else:
|
||||
match_obj = re.match(rule, media_path, re.I)
|
||||
if match_obj:
|
||||
group, title = get_group(match_obj.group(1))
|
||||
if not season:
|
||||
title, season = get_season_and_title(title)
|
||||
else:
|
||||
title, _ = get_season_and_title(title)
|
||||
episode = int(match_obj.group(2))
|
||||
suffix = unix_path.splitext(torrent_path)[-1]
|
||||
if file_type == "media":
|
||||
return EpisodeFile(
|
||||
media_path=torrent_path,
|
||||
group=group,
|
||||
title=title,
|
||||
season=season,
|
||||
episode=episode,
|
||||
suffix=suffix,
|
||||
)
|
||||
elif file_type == "subtitle":
|
||||
language = get_subtitle_lang(media_path)
|
||||
return SubtitleFile(
|
||||
media_path=torrent_path,
|
||||
group=group,
|
||||
title=title,
|
||||
season=season,
|
||||
language=language,
|
||||
episode=episode,
|
||||
suffix=suffix,
|
||||
)
|
||||
|
||||
@@ -1,2 +1 @@
|
||||
|
||||
|
||||
|
||||
@@ -1,86 +1,73 @@
|
||||
import logging
|
||||
|
||||
from .analyser import raw_parser, torrent_parser, TMDBMatcher
|
||||
from .analyser import raw_parser, torrent_parser, tmdb_parser
|
||||
|
||||
from module.models import BangumiData, Config
|
||||
from module.models import BangumiData
|
||||
from module.conf import settings
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class TitleParser:
|
||||
def __init__(self):
|
||||
self._tmdb_parser = TMDBMatcher()
|
||||
pass
|
||||
|
||||
@staticmethod
|
||||
def torrent_parser(
|
||||
method: str,
|
||||
torrent_name: str,
|
||||
bangumi_name: str | None = None,
|
||||
season: int | None = None,
|
||||
suffix: str | None = None,
|
||||
torrent_path: str,
|
||||
torrent_name: str | None = None,
|
||||
season: int | None = None,
|
||||
file_type: str = "media",
|
||||
):
|
||||
return torrent_parser(torrent_name, bangumi_name, season, suffix, method)
|
||||
|
||||
def tmdb_parser(self, title: str, season: int, language: str):
|
||||
official_title, tmdb_season = None, None
|
||||
try:
|
||||
tmdb_info = self._tmdb_parser.tmdb_search(title)
|
||||
logger.debug(f"TMDB Matched, official title is {tmdb_info.title_zh}")
|
||||
return torrent_parser(torrent_path, torrent_name, season, file_type)
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
logger.warning(f"{title} can not Matched with TMDB")
|
||||
logger.info("Please change the bangumi info in webui")
|
||||
return title, season
|
||||
if language == "zh":
|
||||
official_title = f"{tmdb_info.title_zh} ({tmdb_info.year_number})"
|
||||
elif language == "jp":
|
||||
official_title = f"{tmdb_info.title_jp} ({tmdb_info.year_number})"
|
||||
tmdb_season = tmdb_info.last_season if tmdb_info.last_season else season
|
||||
official_title = official_title if official_title else title
|
||||
return official_title, tmdb_season
|
||||
logger.warning(f"Cannot parse {torrent_path} with error {e}")
|
||||
|
||||
def raw_parser(
|
||||
self,
|
||||
raw: str,
|
||||
settings: Config,
|
||||
_id: int | None = None
|
||||
) -> BangumiData:
|
||||
@staticmethod
|
||||
def tmdb_parser(title: str, season: int, language: str):
|
||||
official_title, tmdb_season, year = title, season, None
|
||||
tmdb_info = tmdb_parser(title, language)
|
||||
if tmdb_info:
|
||||
logger.debug(f"TMDB Matched, official title is {tmdb_info.title}")
|
||||
tmdb_season = tmdb_info.last_season if tmdb_info.last_season else season
|
||||
official_title = tmdb_info.title
|
||||
year = tmdb_info.year
|
||||
else:
|
||||
logger.warning(f"Cannot match {title} in TMDB. Use raw title instead.")
|
||||
logger.warning("Please change bangumi info manually.")
|
||||
return official_title, tmdb_season, year
|
||||
|
||||
@staticmethod
|
||||
def raw_parser(raw: str, rss_link: str) -> BangumiData | None:
|
||||
language = settings.rss_parser.language
|
||||
try:
|
||||
episode = raw_parser(raw)
|
||||
titles = {
|
||||
"zh": episode.title_zh,
|
||||
"en": episode.title_en,
|
||||
"jp": episode.title_jp
|
||||
"jp": episode.title_jp,
|
||||
}
|
||||
title_search = episode.title_zh if episode.title_zh else episode.title_en
|
||||
title_raw = episode.title_en if episode.title_en else episode.title_zh
|
||||
if settings.rss_parser.enable_tmdb:
|
||||
official_title, _season = self.tmdb_parser(
|
||||
title_search,
|
||||
episode.season,
|
||||
language
|
||||
)
|
||||
else:
|
||||
official_title = titles[language] if titles[language] else titles["zh"]
|
||||
_season = episode.season
|
||||
official_title = titles[language] if titles[language] else titles["zh"]
|
||||
_season = episode.season
|
||||
data = BangumiData(
|
||||
id=_id,
|
||||
official_title=official_title,
|
||||
title_raw=title_raw,
|
||||
season=_season,
|
||||
season_raw=episode.season_raw,
|
||||
group=episode.group,
|
||||
group_name=episode.group,
|
||||
dpi=episode.resolution,
|
||||
source=episode.source,
|
||||
subtitle=episode.sub,
|
||||
added=False,
|
||||
eps_collect=True if episode.episode > 1 else False,
|
||||
eps_collect=False if episode.episode > 1 else True,
|
||||
offset=0,
|
||||
filter=settings.rss_parser.filter
|
||||
filter=settings.rss_parser.filter,
|
||||
rss_link=[rss_link],
|
||||
)
|
||||
logger.debug(f"RAW:{raw} >> {episode.title_en}")
|
||||
logger.debug(f"RAW:{raw} >> {title_raw}")
|
||||
return data
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
print(e)
|
||||
logger.warning(f"Cannot parse {raw}.")
|
||||
return None
|
||||
|
||||
@@ -1 +1,4 @@
|
||||
from .rss_analyser import RSSAnalyser
|
||||
from .analyser import RSSAnalyser
|
||||
|
||||
|
||||
analyser = RSSAnalyser()
|
||||
|
||||
96
src/module/rss/analyser.py
Normal file
96
src/module/rss/analyser.py
Normal file
@@ -0,0 +1,96 @@
|
||||
import re
|
||||
import logging
|
||||
|
||||
from module.network import RequestContent, TorrentInfo
|
||||
from module.parser import TitleParser
|
||||
from module.models import BangumiData
|
||||
from module.database import BangumiDatabase
|
||||
from module.conf import settings
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class RSSAnalyser:
|
||||
def __init__(self):
|
||||
self._title_analyser = TitleParser()
|
||||
with BangumiDatabase() as db:
|
||||
db.update_table()
|
||||
|
||||
def official_title_parser(self, data: BangumiData, mikan_title: str):
|
||||
if settings.rss_parser.parser_type == "mikan":
|
||||
data.official_title = mikan_title if mikan_title else data.official_title
|
||||
elif settings.rss_parser.parser_type == "tmdb":
|
||||
tmdb_title, season, year = self._title_analyser.tmdb_parser(
|
||||
data.official_title, data.season, settings.rss_parser.language
|
||||
)
|
||||
data.official_title = tmdb_title
|
||||
data.year = year
|
||||
data.season = season
|
||||
else:
|
||||
pass
|
||||
data.official_title = re.sub(r"[/:.\\]", " ", data.official_title)
|
||||
|
||||
@staticmethod
|
||||
def get_rss_torrents(rss_link: str, full_parse: bool = True) -> list:
|
||||
with RequestContent() as req:
|
||||
if full_parse:
|
||||
rss_torrents = req.get_torrents(rss_link)
|
||||
else:
|
||||
rss_torrents = req.get_torrents(rss_link, "\\d+-\\d+")
|
||||
return rss_torrents
|
||||
|
||||
def torrents_to_data(
|
||||
self, torrents: list, rss_link: str, full_parse: bool = True
|
||||
) -> list:
|
||||
new_data = []
|
||||
for torrent in torrents:
|
||||
data = self._title_analyser.raw_parser(raw=torrent.name, rss_link=rss_link)
|
||||
if data and data.title_raw not in [i.title_raw for i in new_data]:
|
||||
try:
|
||||
poster_link, mikan_title = (
|
||||
torrent.poster_link,
|
||||
torrent.official_title,
|
||||
)
|
||||
except AttributeError:
|
||||
poster_link, mikan_title = None, None
|
||||
data.poster_link = poster_link
|
||||
self.official_title_parser(data, mikan_title)
|
||||
if not full_parse:
|
||||
return [data]
|
||||
new_data.append(data)
|
||||
logger.debug(f"[RSS] New title found: {data.official_title}")
|
||||
return new_data
|
||||
|
||||
def torrent_to_data(self, torrent: TorrentInfo, rss_link: str | None = None) -> BangumiData:
|
||||
data = self._title_analyser.raw_parser(raw=torrent.name, rss_link=rss_link)
|
||||
if data:
|
||||
try:
|
||||
poster_link, mikan_title = (
|
||||
torrent.poster_link,
|
||||
torrent.official_title,
|
||||
)
|
||||
except AttributeError:
|
||||
poster_link, mikan_title = None, None
|
||||
data.poster_link = poster_link
|
||||
self.official_title_parser(data, mikan_title)
|
||||
return data
|
||||
|
||||
def rss_to_data(self, rss_link: str, database: BangumiDatabase, full_parse: bool = True) -> list[BangumiData]:
|
||||
rss_torrents = self.get_rss_torrents(rss_link, full_parse)
|
||||
torrents_to_add = database.match_list(rss_torrents, rss_link)
|
||||
if not torrents_to_add:
|
||||
logger.debug("[RSS] No new title has been found.")
|
||||
return []
|
||||
# New List
|
||||
new_data = self.torrents_to_data(torrents_to_add, rss_link, full_parse)
|
||||
if new_data:
|
||||
return new_data
|
||||
else:
|
||||
return []
|
||||
|
||||
def link_to_data(self, link: str) -> BangumiData:
|
||||
torrents = self.get_rss_torrents(link, False)
|
||||
for torrent in torrents:
|
||||
data = self.torrent_to_data(torrent, link)
|
||||
if data:
|
||||
return data
|
||||
57
src/module/rss/filter.py
Normal file
57
src/module/rss/filter.py
Normal file
@@ -0,0 +1,57 @@
|
||||
import logging
|
||||
|
||||
from module.database import BangumiDatabase
|
||||
from module.downloader import DownloadClient
|
||||
from module.network import RequestContent
|
||||
from module.conf import settings
|
||||
from module.models import BangumiData
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def matched(torrent_title: str):
|
||||
with BangumiDatabase() as db:
|
||||
return db.match_torrent(torrent_title)
|
||||
|
||||
|
||||
def save_path(data: BangumiData):
|
||||
folder = (
|
||||
f"{data.official_title}({data.year})" if data.year else f"{data.official_title}"
|
||||
)
|
||||
season = f"Season {data.season}"
|
||||
return path.join(
|
||||
settings.downloader.path,
|
||||
folder,
|
||||
season,
|
||||
)
|
||||
|
||||
|
||||
def add_download(data: BangumiData, torrent: TorrentInfo):
|
||||
torrent = {
|
||||
"url": torrent.url,
|
||||
"save_path": save_path(data),
|
||||
}
|
||||
with DownloadClient() as client:
|
||||
client.add_torrent(torrent)
|
||||
with TorrentDatabase() as db:
|
||||
db.add_torrent(torrent)
|
||||
|
||||
|
||||
def downloaded(torrent: TorrentInfo):
|
||||
with TorrentDatabase() as db:
|
||||
return db.if_downloaded(torrent)
|
||||
|
||||
|
||||
def get_downloads(rss_link: str):
|
||||
with RequestContent() as req:
|
||||
torrents = req.get_torrents(rss_link)
|
||||
for torrent in torrents:
|
||||
if not downloaded(torrent):
|
||||
data = matched(torrent.title)
|
||||
if data:
|
||||
add_download(data, torrent)
|
||||
logger.info(f"Add {torrent.title} to download list")
|
||||
else:
|
||||
logger.debug(f"{torrent.title} not matched")
|
||||
else:
|
||||
logger.debug(f"{torrent.title} already downloaded")
|
||||
@@ -1,68 +0,0 @@
|
||||
import re
|
||||
import logging
|
||||
|
||||
from module.network import RequestContent
|
||||
from module.parser import TitleParser
|
||||
from module.core import DownloadClient
|
||||
from module.models import BangumiData, Config
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class RSSAnalyser:
|
||||
def __init__(self, settings: Config):
|
||||
self._title_analyser = TitleParser()
|
||||
self.settings = settings
|
||||
|
||||
@staticmethod
|
||||
def find_id(bangumi_info: list[BangumiData]) -> int:
|
||||
_id = 0
|
||||
for info in bangumi_info:
|
||||
if info.id > _id:
|
||||
_id = info.id
|
||||
return _id
|
||||
|
||||
def rss_to_datas(self, bangumi_info: list[BangumiData], rss_link: str) -> list[BangumiData]:
|
||||
with RequestContent() as req:
|
||||
rss_torrents = req.get_torrents(rss_link)
|
||||
# Find largest bangumi id
|
||||
_id = self.find_id(bangumi_info)
|
||||
for torrent in rss_torrents:
|
||||
raw_title = torrent.name
|
||||
extra_add = True
|
||||
if bangumi_info is not []:
|
||||
for info in bangumi_info:
|
||||
if re.search(info.title_raw, raw_title) is not None:
|
||||
logger.debug(f"Had added {info.official_title} in auto_download rule before")
|
||||
extra_add = False
|
||||
break
|
||||
if extra_add:
|
||||
_id += 1
|
||||
data = self._title_analyser.raw_parser(
|
||||
raw=raw_title,
|
||||
_id=_id,
|
||||
settings=self.settings)
|
||||
if data is not None and data.official_title not in bangumi_info:
|
||||
bangumi_info.append(data)
|
||||
return bangumi_info
|
||||
|
||||
def rss_to_data(self, url, _filter: bool = True) -> BangumiData:
|
||||
with RequestContent() as req:
|
||||
rss_torrents = req.get_torrents(url, _filter)
|
||||
for torrent in rss_torrents:
|
||||
try:
|
||||
data = self._title_analyser.raw_parser(
|
||||
torrent.name,
|
||||
settings=self.settings
|
||||
)
|
||||
return data
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
|
||||
def run(self, bangumi_info: list[BangumiData], rss_link: str):
|
||||
logger.info("Start collecting RSS info.")
|
||||
try:
|
||||
self.rss_to_datas(bangumi_info, rss_link)
|
||||
except Exception as e:
|
||||
logger.debug(e)
|
||||
logger.info("Finished")
|
||||
@@ -3,7 +3,6 @@ from module.conf import settings
|
||||
|
||||
|
||||
class RSSSearcher(RequestContent):
|
||||
|
||||
def __search_url(self, keywords: str) -> str:
|
||||
keywords.replace(" ", "+")
|
||||
url = f"{settings.rss_parser.custom_url}/RSS/Search?keyword={keywords}"
|
||||
|
||||
1
src/module/searcher/__init__.py
Normal file
1
src/module/searcher/__init__.py
Normal file
@@ -0,0 +1 @@
|
||||
from .searcher import SearchTorrent
|
||||
8
src/module/searcher/plugin/__init__.py
Normal file
8
src/module/searcher/plugin/__init__.py
Normal file
@@ -0,0 +1,8 @@
|
||||
from .mikan import mikan_url
|
||||
|
||||
|
||||
def search_url(site: str, keywords: list[str]):
|
||||
if site == "mikan":
|
||||
return mikan_url(keywords)
|
||||
else:
|
||||
raise NotImplementedError(f"site {site} is not supported")
|
||||
12
src/module/searcher/plugin/mikan.py
Normal file
12
src/module/searcher/plugin/mikan.py
Normal file
@@ -0,0 +1,12 @@
|
||||
import re
|
||||
|
||||
from module.conf import settings
|
||||
|
||||
|
||||
def mikan_url(keywords: list[str]):
|
||||
keyword = "+".join(keywords)
|
||||
search_str = re.sub(r"[\W_ ]", "+", keyword)
|
||||
url = f"{settings.rss_parser.custom_url}/RSS/Search?searchstr={search_str}"
|
||||
if "://" not in url:
|
||||
url = f"https://{url}"
|
||||
return url
|
||||
39
src/module/searcher/searcher.py
Normal file
39
src/module/searcher/searcher.py
Normal file
@@ -0,0 +1,39 @@
|
||||
from module.searcher.plugin import search_url
|
||||
from module.network import RequestContent
|
||||
from module.models import BangumiData, TorrentBase
|
||||
|
||||
SEARCH_KEY = [
|
||||
"group_name",
|
||||
"title_raw",
|
||||
"season_raw",
|
||||
"subtitle",
|
||||
"source",
|
||||
"dpi",
|
||||
]
|
||||
|
||||
|
||||
class SearchTorrent(RequestContent):
|
||||
def search_torrents(self, keywords: list[str], site: str = "mikan") -> list[TorrentBase]:
|
||||
url = search_url(site, keywords)
|
||||
# TorrentInfo to TorrentBase
|
||||
torrents = self.get_torrents(url)
|
||||
|
||||
def to_dict():
|
||||
for torrent in torrents:
|
||||
yield {
|
||||
"name": torrent.name,
|
||||
"torrent_link": torrent.torrent_link,
|
||||
"homepage": torrent.homepage,
|
||||
}
|
||||
return [TorrentBase(**d) for d in to_dict()]
|
||||
|
||||
def search_season(self, data: BangumiData):
|
||||
keywords = [getattr(data, key) for key in SEARCH_KEY if getattr(data, key)]
|
||||
torrents = self.search_torrents(keywords)
|
||||
return [torrent for torrent in torrents if data.title_raw in torrent.name]
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
with SearchTorrent() as st:
|
||||
for t in st.search_torrents(["魔法科高校の劣等生"]):
|
||||
print(t)
|
||||
2
src/module/security/__init__.py
Normal file
2
src/module/security/__init__.py
Normal file
@@ -0,0 +1,2 @@
|
||||
from .jwt import create_access_token
|
||||
from .api import get_current_user, get_token_data, auth_user, update_user_info
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user