mirror of
https://github.com/Light-City/CPlusPlusThings.git
synced 2026-10-30 03:45:03 +08:00
- const README: rewrite the space-saving claim per issue #5 follow-ups (constant-expression const vs #define immediates; which const qualify as constant expressions) - const README: fix the class-section diagnosis per issue #338 (overload resolution picks the const overload; the restriction only surfaces once that overload is removed) - sizeof README: virtual-inheritance result is compiler-dependent (GCC merges vbptr+vfptr -> 16, MSVC keeps them separate -> 32) #246 - static README: new section on internal linkage / access restriction with anonymous-namespace comparison #142 - 10-day practice: full problem list table + fixed day links #136 - new design_pattern/singleton/singleton_default.hpp: reusable thread-safe CRTP singleton template, compile+concurrency tested #303
This commit is contained in:
 light-city
@@ -1,10 +1,12 @@
|
||||
# 纯虚函数和抽象类
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/abstract/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 纯虚函数与抽象类
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.纯虚函数与抽象类
|
||||
|
||||
@@ -23,7 +25,7 @@ public:
|
||||
|
||||
抽象类只能作为基类来派生新类使用,不能创建抽象类的对象,抽象类的指针和引用->由抽象类派生出来的类的对象!
|
||||
|
||||
> 代码样例:[abstract_base.h](./abstract_base.h)、[pure_virtual.cpp](./pure_virtual.cpp)
|
||||
> 代码样例:[abstract_base.h](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/abstract_base.h)、[pure_virtual.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/pure_virtual.cpp)
|
||||
|
||||
## 2.实现抽象类
|
||||
|
||||
@@ -45,11 +47,11 @@ public:
|
||||
};
|
||||
```
|
||||
|
||||
> 代码样例:[abstract.cpp](./abstract.cpp)
|
||||
> 代码样例:[abstract.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/abstract.cpp)
|
||||
|
||||
## 3.重要点
|
||||
|
||||
- [纯虚函数使一个类变成抽象类](./interesting_facts1.cpp)
|
||||
- [纯虚函数使一个类变成抽象类](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/interesting_facts1.cpp)
|
||||
```cpp
|
||||
// 抽象类至少包含一个纯虚函数
|
||||
class Base{
|
||||
@@ -62,7 +64,7 @@ private:
|
||||
};
|
||||
```
|
||||
|
||||
- [抽象类类型的指针和引用](./interesting_facts2.cpp)
|
||||
- [抽象类类型的指针和引用](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/interesting_facts2.cpp)
|
||||
```cpp
|
||||
class Derived : public Base {
|
||||
public:
|
||||
@@ -81,7 +83,7 @@ int main(void)
|
||||
}
|
||||
```
|
||||
|
||||
- [如果我们不在派生类中覆盖纯虚函数,那么派生类也会变成抽象类](./interesting_facts3.cpp)
|
||||
- [如果我们不在派生类中覆盖纯虚函数,那么派生类也会变成抽象类](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/interesting_facts3.cpp)
|
||||
```cpp
|
||||
// Derived为抽象类
|
||||
class Derived: public Base
|
||||
@@ -91,7 +93,7 @@ public:
|
||||
};
|
||||
```
|
||||
|
||||
- [抽象类可以有构造函数](./interesting_facts4.cpp)
|
||||
- [抽象类可以有构造函数](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/interesting_facts4.cpp)
|
||||
```cpp
|
||||
// 抽象类
|
||||
class Base {
|
||||
@@ -111,7 +113,7 @@ public:
|
||||
};
|
||||
```
|
||||
|
||||
- [构造函数不能是虚函数,而析构函数可以是虚析构函数](./interesting_facts5.cpp)
|
||||
- [构造函数不能是虚函数,而析构函数可以是虚析构函数](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/interesting_facts5.cpp)
|
||||
```cpp
|
||||
// 抽象类
|
||||
class Base {
|
||||
@@ -137,4 +139,4 @@ public:
|
||||
|
||||
抽象类由派生类继承实现!
|
||||
|
||||
> 代码样例:[derived_full.cpp](./derived_full.cpp)
|
||||
> 代码样例:[derived_full.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/abstract/derived_full.cpp)
|
||||
@@ -1,10 +1,12 @@
|
||||
# assert那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/assert/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ assert 断言
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
|
||||
|
||||
@@ -20,7 +22,7 @@ assert 宏的原型定义在 <assert.h>(C)、<cassert>(C++)中。其作
|
||||
void assert(int expression);
|
||||
```
|
||||
|
||||
> 代码样例:[assert.c](./assert.c)
|
||||
> 代码样例:[assert.c](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/assert/assert.c)
|
||||
```c
|
||||
#include <stdio.h>
|
||||
#include <assert.h>
|
||||
@@ -58,4 +60,4 @@ assert: assert.c:13: main: Assertion 'x==7' failed.
|
||||
#define NDEBUG // 加上这行,则 assert 不可用
|
||||
```
|
||||
|
||||
> 样例代码:[ignore_assert.c](./ignore_assert.c)
|
||||
> 样例代码:[ignore_assert.c](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/assert/ignore_assert.c)
|
||||
@@ -1,8 +1,12 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/bit/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 位域
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## Bit field 是什么?
|
||||
|
||||
@@ -108,7 +112,7 @@ struct stuff
|
||||
|
||||
这里 stuff.field1 与 stuff.field2 之间有一个 2 Bits 的空隙,stuff.field3 则存储在下一个 unsigned int 中,该结构现在大小为 3 * 32 = 96 Bits。
|
||||
|
||||
学习代码见:[bit.cpp](bit.cpp)
|
||||
学习代码见:[bit.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/bit/bit.cpp)
|
||||
|
||||
## 位域的初始化和位的重映射
|
||||
|
||||
|
||||
@@ -1,10 +1,12 @@
|
||||
# C实现C++的面向对象特性
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/c-polymorphism/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C 语言实现 C++ 多态
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.C++实现案例
|
||||
|
||||
@@ -12,7 +14,7 @@ C++中的多态:在C++中会维护一张虚函数表,根据赋值兼容规则
|
||||
|
||||
如果一个父类的指针或者引用调用父类的虚函数则该父类的指针会在自己的虚函数表中查找自己的函数地址,如果该父类对象的指针或者引用指向的是子类的对象,而且该子类已经重写了父类的虚函数,则该指针会调用子类的已经重写的虚函数。
|
||||
|
||||
学习案例代码见:[c++_examp.cpp](./c++_examp.cpp)
|
||||
学习案例代码见:[c++_examp.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/c_poly/c++_examp.cpp)
|
||||
|
||||
|
||||
|
||||
@@ -38,4 +40,4 @@ C语言中是没有class类这个概念的,但是有struct结构体,我们
|
||||
|
||||
|
||||
|
||||
学习案例代码见:[c_examp.c](./c_examp.c)
|
||||
学习案例代码见:[c_examp.c](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/c_poly/c_examp.c)
|
||||
@@ -1,8 +1,12 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/const/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ const 常量与修饰
|
||||
|
||||
## 关于作者
|
||||
|
||||
微信公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.const含义
|
||||
|
||||
@@ -34,8 +38,9 @@ void f(const int i){
|
||||
|
||||
+ 可以节省空间,避免不必要的内存分配
|
||||
|
||||
+ const定义常量从汇编的角度来看,只是给出了对应的内存地址,而不是像`#define`一样给出的是立即数。
|
||||
+ const定义的常量在程序运行过程中只有一份拷贝,而`#define`定义的常量在内存中有若干个拷贝。
|
||||
+ 以整型/枚举类型、常量表达式初始化的 const(即常量表达式)在用法上更接近编译期常量:不取地址、仅使用其值时通常被优化成立即数,与 `#define` 类似;取地址或跨编译单元 odr-use 时才会落到内存,且全程序只有一份。
|
||||
+ `#define` 展开为字面量后以立即数形式编入指令,指令本身也占内存,多处使用即多处出现(见 [issue #5](https://github.com/Light-City/CPlusPlusThings/issues/5) 的讨论)。
|
||||
+ 注意:并非所有 const 变量都是常量表达式——只有整数/枚举类型且以常量表达式初始化的才是;其他 const 变量只是 const 限度的变量(如浮点、自定义类型,标准并未规定其可用常量表达式初始化,`constexpr` 才是编译期常量的正确表达)。
|
||||
|
||||
## 3.const对象默认为文件局部变量
|
||||
|
||||
@@ -358,7 +363,7 @@ int main()
|
||||
```
|
||||
> 编译:bazel run basic_content/const/class_const/first_example:main<br>
|
||||
|
||||
此时报错,上面getCount()方法中调用了一个add方法,而add方法并非const修饰,所以运行报错。也就是说const成员函数只能访问const成员函数。
|
||||
此时报错:getCount() 是 const 成员函数,其中的 add() 重载决议只会匹配 const 版本(`int add(int num) const`);把这个 const 版本注释掉后,才会因调用了非 const 的 add() 而报错。即:const 对象只能访问 const 成员函数,非 const 对象可以访问任意成员函数(见 [issue #338](https://github.com/Light-City/CPlusPlusThings/issues/338))。
|
||||
|
||||
当调用改为:
|
||||
|
||||
@@ -410,4 +415,4 @@ static int ap;
|
||||
int Apple::ap=666
|
||||
```
|
||||
|
||||
对于此项,c++11不能进行声明并初始化,也就是上述使用方法。
|
||||
对于此项,c++11不能进行声明并初始化,也就是上述使用方法。
|
||||
@@ -1,10 +1,12 @@
|
||||
# decltype那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/decltype/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ decltype 类型推导
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.基本使用
|
||||
decltype的语法是:
|
||||
@@ -69,7 +71,7 @@ auto multiply(T x, T y)->decltype(x*y)
|
||||
}
|
||||
```
|
||||
|
||||
完整代码见:[decltype.cpp](decltype.cpp)
|
||||
完整代码见:[decltype.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/decltype/decltype.cpp)
|
||||
|
||||
## 2.判别规则
|
||||
|
||||
@@ -135,4 +137,4 @@ decltype(Func(1)) var13=true;//const bool
|
||||
decltype(i++) var14 = i;//int i++返回右值
|
||||
```
|
||||
|
||||
学习参考:https://www.cnblogs.com/QG-whz/p/4952980.html
|
||||
学习参考:https://www.cnblogs.com/QG-whz/p/4952980.html
|
||||
@@ -1,10 +1,12 @@
|
||||
# 从初级到高级的enum那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/enum/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ enum 枚举类型
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
|
||||
## 传统行为
|
||||
@@ -37,7 +39,7 @@ int main()
|
||||
- 会隐式转换为int
|
||||
- 用来表征枚举变量的实际类型不能明确指定,从而无法支持枚举类型的前向声明。
|
||||
|
||||
具体实现见:[tradition_color.cpp](tradition_color.cpp)
|
||||
具体实现见:[tradition_color.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/enum/tradition_color.cpp)
|
||||
|
||||
## 经典做法
|
||||
|
||||
@@ -72,7 +74,7 @@ struct Color1
|
||||
};
|
||||
```
|
||||
|
||||
具体实现见:[classic_practice.cpp](classic_practice.cpp)
|
||||
具体实现见:[classic_practice.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/enum/classic_practice.cpp)
|
||||
|
||||
## C++11 的枚举类
|
||||
|
||||
@@ -110,7 +112,7 @@ enum class Color3:char
|
||||
char c3 = static_cast<char>(Color3::RED);
|
||||
```
|
||||
|
||||
具体实现见:[classic_practice.cpp](classic_practice.cpp)
|
||||
具体实现见:[classic_practice.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/enum/classic_practice.cpp)
|
||||
|
||||
## 类中的枚举类型
|
||||
|
||||
@@ -161,4 +163,4 @@ public:
|
||||
|
||||
枚举常量不会占用对象的存储空间,它们在编译时被全部求值。
|
||||
|
||||
枚举常量的缺点是:它的隐含数据类型是整数,其最大值有限,且不能表示浮点。
|
||||
枚举常量的缺点是:它的隐含数据类型是整数,其最大值有限,且不能表示浮点。
|
||||
@@ -1,16 +1,18 @@
|
||||
# explicit(显式)关键字那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/explicit/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ explicit 显式转换
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
- explicit 修饰构造函数时,可以防止隐式转换和复制初始化
|
||||
- explicit 修饰转换函数时,可以防止隐式转换,但按语境转换除外
|
||||
|
||||
|
||||
代码参见:[.explicit.cpp](./explicit.cpp)
|
||||
代码参见:[.explicit.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/explicit/explicit.cpp)
|
||||
|
||||
参考链接:
|
||||
> https://stackoverflow.com/questions/4600295/what-is-the-meaning-of-operator-bool-const
|
||||
> https://stackoverflow.com/questions/4600295/what-is-the-meaning-of-operator-bool-const
|
||||
20
basic_content/extern/README.md
vendored
20
basic_content/extern/README.md
vendored
@@ -1,10 +1,12 @@
|
||||
# extern "C"
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/extern/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ extern 链接说明
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.C++与C编译区别
|
||||
|
||||
@@ -118,11 +120,11 @@ int add(int x,int y);
|
||||
|
||||
上述案例源代码见:
|
||||
|
||||
- [add.h](extern_c++/add.h)
|
||||
- [add.h](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/extern/extern_c++/add.h)
|
||||
|
||||
- [add.c](extern_c++/add.c)
|
||||
- [add.c](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/extern/extern_c++/add.c)
|
||||
|
||||
- [add.cpp](extern_c++/add.cpp)
|
||||
- [add.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/extern/extern_c++/add.cpp)
|
||||
|
||||
## 2.C中调用C++函数
|
||||
|
||||
@@ -166,11 +168,11 @@ gcc add.c add.o -o main
|
||||
|
||||
上述案例源代码见:
|
||||
|
||||
- [add.h](extern_c/add.h)
|
||||
- [add.h](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/extern/extern_c/add.h)
|
||||
|
||||
- [add.c](extern_c/add.c)
|
||||
- [add.c](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/extern/extern_c/add.c)
|
||||
|
||||
- [add.cpp](extern_c/add.cpp)
|
||||
- [add.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/extern/extern_c/add.cpp)
|
||||
|
||||
综上,总结出使用方法,在C语言的头文件中,对其外部函数只能指定为extern类型,C语言中不支持extern "C"声明,在.c文件中包含了extern "C"时会出现编译语法错误。所以使用extern "C"全部都放在于cpp程序相关文件或其头文件中。
|
||||
|
||||
@@ -209,4 +211,4 @@ extern int add();
|
||||
```
|
||||
|
||||
|
||||
不过与C++调用C接口不同,C++确实是能够调用编译好的C函数,而这里C调用C++,不过是把C++代码当成C代码编译后调用而已。也就是说,C并不能直接调用C++库函数。
|
||||
不过与C++调用C接口不同,C++确实是能够调用编译好的C函数,而这里C调用C++,不过是把C++代码当成C代码编译后调用而已。也就是说,C并不能直接调用C++库函数。
|
||||
@@ -1,10 +1,12 @@
|
||||
# 友元函数与友元类
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/friend/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ friend 友元
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 0.概述
|
||||
|
||||
@@ -35,7 +37,7 @@ friend <类型><友元函数名>(<参数表>);
|
||||
|
||||
注意,友元函数只是一个普通函数,并不是该类的类成员函数,它可以在任何地方调用,友元函数中通过对象名来访问该类的私有或保护成员。
|
||||
|
||||
具体代码见:[friend_func.cpp](friend_func.cpp)
|
||||
具体代码见:[friend_func.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/friend/friend_func.cpp)
|
||||
|
||||
```c++
|
||||
#include <iostream>
|
||||
@@ -74,7 +76,7 @@ friend class <友元类名>;
|
||||
|
||||
类B是类A的友元,那么类B可以直接访问A的私有成员。
|
||||
|
||||
具体代码见:[friend_class.cpp](friend_class.cpp)
|
||||
具体代码见:[friend_class.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/friend/friend_class.cpp)
|
||||
```c++
|
||||
#include <iostream>
|
||||
|
||||
@@ -112,4 +114,4 @@ int main()
|
||||
假如类B是类A的友元,类C继承于类A,那么友元类B是没办法直接访问类C的私有或保护成员。
|
||||
|
||||
- 友元关系没有传递性
|
||||
假如类B是类A的友元,类C是类B的友元,那么友元类C是没办法直接访问类A的私有或保护成员,也就是不存在“友元的友元”这种关系。
|
||||
假如类B是类A的友元,类C是类B的友元,那么友元类C是没办法直接访问类A的私有或保护成员,也就是不存在“友元的友元”这种关系。
|
||||
@@ -1,10 +1,12 @@
|
||||
# inline那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/inline/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ inline 内联函数
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.类中内联
|
||||
|
||||
@@ -131,7 +133,4 @@ int main()
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
|
||||
```
|
||||
@@ -1,10 +1,12 @@
|
||||
# 宏那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/macro/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 宏与条件编译
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.宏中包含特殊符号
|
||||
|
||||
@@ -113,7 +115,7 @@ int main() {
|
||||
}
|
||||
```
|
||||
|
||||
上述代码见:[sig_examp.cpp](sig_examp.cpp)
|
||||
上述代码见:[sig_examp.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/macro/sig_examp.cpp)
|
||||
|
||||
## 2.do{...}while(0)的使用
|
||||
|
||||
@@ -226,7 +228,6 @@ int fc()
|
||||
}
|
||||
```
|
||||
|
||||
上述代码见:[do_while.cpp](do_while.cpp)
|
||||
|
||||
学习文章:<https://www.cnblogs.com/lizhenghn/p/3674430.html>
|
||||
上述代码见:[do_while.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/macro/do_while.cpp)
|
||||
|
||||
学习文章:<https://www.cnblogs.com/lizhenghn/p/3674430.html>
|
||||
@@ -1,14 +1,15 @@
|
||||
# :: 范围解析运算符那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/namespace/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 命名空间
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
- 全局作用域符(::name):用于类型名称(类、类成员、成员函数、变量等)前,表示作用域为全局命名空间
|
||||
- 类作用域符(class::name):用于表示指定类型的作用域范围是具体某个类的
|
||||
- 命名空间作用域符(namespace::name):用于表示指定类型的作用域范围是具体某个命名空间的
|
||||
|
||||
具体代码见:[maohao.cpp](maohao.cpp)
|
||||
|
||||
具体代码见:[maohao.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/maohao/maohao.cpp)
|
||||
@@ -1,10 +1,12 @@
|
||||
# 引用与指针那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/pointer-vs-reference/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 指针与引用
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.引用与指针
|
||||
|
||||
@@ -171,4 +173,4 @@ End of assembler dump.
|
||||
|
||||
C++中引入了引用操作,在对引用的使用加了更多限制条件的情况下,保证了引用使用的安全性和便捷性,还可以保持代码的优雅性。在适合的情况使用适合的操作,引用的使用可以一定程度避免“指针满天飞”的情况,对于提升程序稳定性也有一定的积极意义。最后,指针与引用底层实现都是一样的,不用担心两者的性能差距。
|
||||
|
||||
上述部分参考自:<http://irootlee.com/juicer_pointer_reference/#>
|
||||
上述部分参考自:<http://irootlee.com/juicer_pointer_reference/#>
|
||||
@@ -1,4 +1,6 @@
|
||||
# 类大小计算
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/sizeof/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ sizeof 运算符
|
||||
|
||||
首先来个总结,然后下面给出实际例子,实战!
|
||||
|
||||
@@ -194,11 +196,10 @@ class C : virtual public A, virtual public B
|
||||
int main()
|
||||
{
|
||||
/**
|
||||
* @brief 8 8 16 派生类虚继承多个虚函数,会继承所有虚函数的vptr
|
||||
* @brief GCC: 8 8 16(虚基类指针与虚函数表指针合并);MSVC/Windows: 8 8 32(虚基类指针与虚函数表指针分别存储),结果与编译器相关,见 issue #246
|
||||
*/
|
||||
cout<<sizeof(A)<<" "<<sizeof(B)<<" "<<sizeof(C);
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
```
|
||||
@@ -1,10 +1,12 @@
|
||||
# static那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/static/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ static 静态成员与生存期
|
||||
|
||||
## 关于作者
|
||||
|
||||
微信公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
当与不同类型一起使用时,Static关键字具有不同的含义。我们可以使用static关键字:
|
||||
|
||||
@@ -277,3 +279,21 @@ int main()
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
### 6.static 的内部链接(限定访问范围)
|
||||
|
||||
感谢 [issue #142](https://github.com/Light-City/CPlusPlusThings/issues/142) 指出:static 修饰全局变量/函数时,还起到**限定访问范围**的作用——将其链接性从外部链接(external linkage)改为内部链接(internal linkage),效果类似匿名命名空间:
|
||||
|
||||
- 非 static 的全局变量:其他编译单元可以通过 `extern` 声明访问;
|
||||
- static 全局变量/函数:仅当前编译单元可见,`extern` 声明也无法链接到(上面的 undefined reference 正是这个原因)。
|
||||
|
||||
现代 C++ 中更推荐用**匿名命名空间**表达"仅本文件可见"(对类型同样有效),但理解 static 的这一层含义在阅读旧代码时非常重要。
|
||||
|
||||
```cpp
|
||||
// file1.cpp
|
||||
static int hidden = 42; // 内部链接:其他文件 extern 不可见
|
||||
int visible = 1; // 外部链接:其他文件可 extern 访问
|
||||
|
||||
namespace { // 匿名命名空间:等价且更现代的写法
|
||||
int also_hidden = 7;
|
||||
}
|
||||
```
|
||||
|
||||
@@ -1,10 +1,12 @@
|
||||
# 一文搞懂C和C++中struct
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/struct/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ struct 结构体
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.C中struct
|
||||
|
||||
@@ -52,7 +54,7 @@ int main() {
|
||||
I am Base func
|
||||
```
|
||||
|
||||
完整代码见:[struct_func.c](./struct_func.c)
|
||||
完整代码见:[struct_func.c](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/struct/struct_func.c)
|
||||
|
||||
## 2.C++中struct
|
||||
|
||||
@@ -135,7 +137,7 @@ int main() {
|
||||
}
|
||||
```
|
||||
|
||||
完整代码见:[struct_func.cpp](struct_func.cpp)
|
||||
完整代码见:[struct_func.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/struct/struct_func.cpp)
|
||||
|
||||
> 继承案例
|
||||
|
||||
@@ -167,7 +169,7 @@ int main() {
|
||||
}
|
||||
```
|
||||
|
||||
完整代码见:[ext_struct_func.cpp](./ext_struct_func.cpp)
|
||||
完整代码见:[ext_struct_func.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/struct/ext_struct_func.cpp)
|
||||
|
||||
> 同名函数
|
||||
|
||||
@@ -212,7 +214,7 @@ int main() {
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
完整代码见:[struct_func_func.cpp](./struct_func_func.cpp)
|
||||
完整代码见:[struct_func_func.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/struct/struct_func_func.cpp)
|
||||
|
||||
## 3.总结
|
||||
|
||||
@@ -224,4 +226,4 @@ int main() {
|
||||
| 在C结构体声明中不能使用C++访问修饰符。 | public、protected、private 在C++中可以使用。 |
|
||||
| 在C中定义结构体变量,如果使用了下面定义必须加struct。 | 可以不加struct |
|
||||
| 结构体不能继承(没有这一概念)。 | 可以继承 |
|
||||
| 若结构体的名字与函数名相同,可以正常运行且正常的调用! | 若结构体的名字与函数名相同,使用结构体,只能使用带struct定义! |
|
||||
| 若结构体的名字与函数名相同,可以正常运行且正常的调用! | 若结构体的名字与函数名相同,使用结构体,只能使用带struct定义! |
|
||||
@@ -1,12 +1,14 @@
|
||||
# struct与class区别
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/struct-vs-class/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ struct 与 class 区别
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
关于C与C++中struct内容:见[struct那些事](../struct)
|
||||
关于C与C++中struct内容:见[struct那些事](struct.md)
|
||||
|
||||
总的来说,struct 更适合看成是一个数据结构的实现体,class 更适合看成是一个对象的实现体。
|
||||
|
||||
@@ -16,4 +18,4 @@
|
||||
|
||||
默认的继承访问权限。struct 是 public 的,class 是 private 的。
|
||||
|
||||
struct 作为数据结构的实现体,它默认的数据访问控制是 public 的,而 class 作为对象的实现体,它默认的成员变量访问控制是 private 的。
|
||||
struct 作为数据结构的实现体,它默认的数据访问控制是 public 的,而 class 作为对象的实现体,它默认的成员变量访问控制是 private 的。
|
||||
@@ -1,10 +1,12 @@
|
||||
# this指针那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/this/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ this 指针
|
||||
|
||||
## 关于作者
|
||||
|
||||
微信公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.this指针
|
||||
|
||||
@@ -74,16 +76,16 @@ int main(){
|
||||
|
||||
为了验证this指针是哪一个,现在在`add_age`处添加断点,运行后如下:
|
||||
|
||||

|
||||
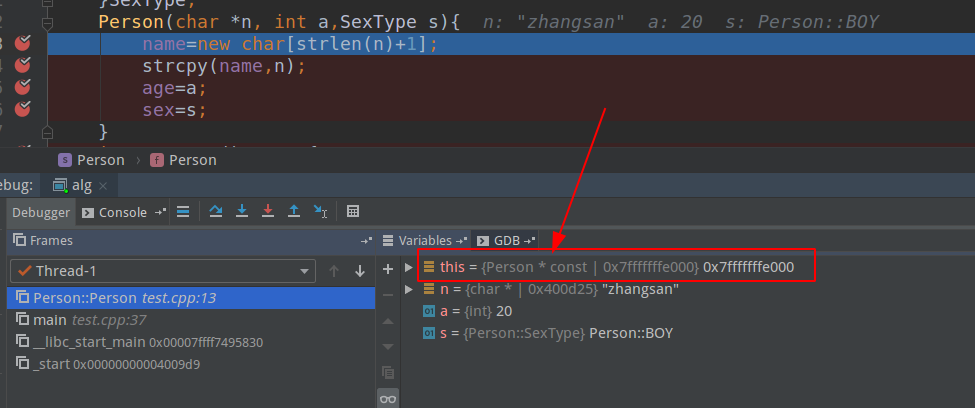
|
||||
|
||||

|
||||
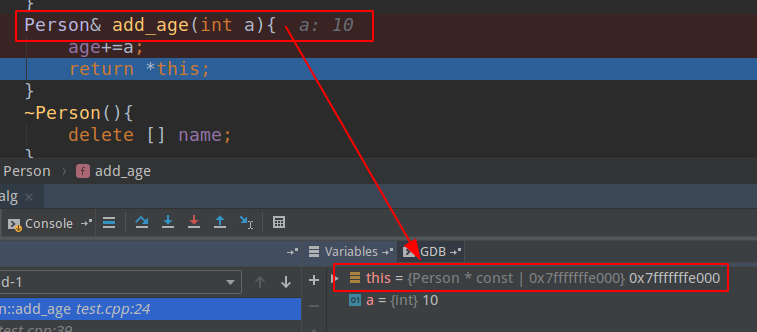
|
||||
|
||||
会发现编译器自动为我们加上`A* const`,而不是`A const *this`!
|
||||
|
||||
紧接着,上述还有个常函数,那么我们在对`get_age`添加断点,如下:
|
||||
|
||||

|
||||
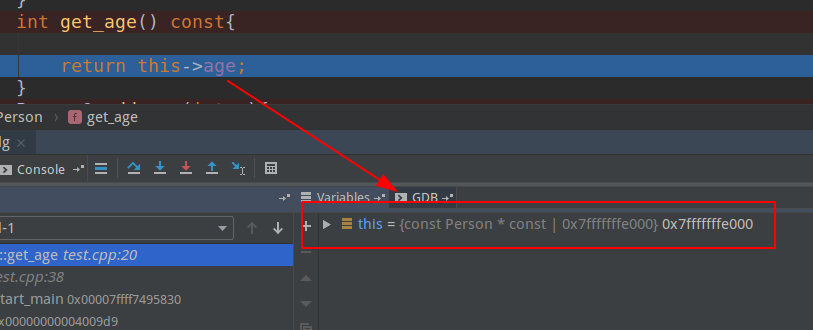
|
||||
|
||||
会发现编译器把上述的this,变为`const A* const`,这个大家也能想到,因为这个函数是const函数,那么针对const函数,它只能访问const变量与const函数,不能修改其他变量的值,所以需要一个this指向不能修改的变量,那就是`const A*`,又由于本身this是`const`指针,所以就为`const A* const`!
|
||||
|
||||
总结:this在成员函数的开始执行前构造,在成员的执行结束后清除。上述的get_age函数会被解析成`get_age(const A * const this)`,`add_age`函数会被解析成`add_age(A* const this,int a)`。在C++中类和结构是只有一个区别的:类的成员默认是private,而结构是public。this是类的指针,如果换成结构,那this就是结构的指针了。
|
||||
总结:this在成员函数的开始执行前构造,在成员的执行结束后清除。上述的get_age函数会被解析成`get_age(const A * const this)`,`add_age`函数会被解析成`add_age(A* const this,int a)`。在C++中类和结构是只有一个区别的:类的成员默认是private,而结构是public。this是类的指针,如果换成结构,那this就是结构的指针了。
|
||||
@@ -1,10 +1,12 @@
|
||||
# UNION那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/union/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ union 联合体
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
联合(union)是一种节省空间的特殊的类,一个 union 可以有多个数据成员,但是在任意时刻只有一个数据成员可以有值。当某个成员被赋值后其他成员变为未定义状态。联合有如下特点:
|
||||
|
||||
@@ -15,4 +17,4 @@
|
||||
- 不能含有虚函数
|
||||
- 匿名 union 在定义所在作用域可直接访问 union 成员
|
||||
- 匿名 union 不能包含 protected 成员或 private 成员
|
||||
- 全局匿名联合必须是静态(static)的
|
||||
- 全局匿名联合必须是静态(static)的
|
||||
@@ -1,9 +1,12 @@
|
||||
# using那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/using/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ using 声明与别名
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 基本使用
|
||||
|
||||
@@ -48,7 +51,7 @@ int main()
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
完整代码见:[using_global.cpp](using_global.cpp)
|
||||
完整代码见:[using_global.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/using/using_global.cpp)
|
||||
## 改变访问性
|
||||
|
||||
```
|
||||
@@ -67,7 +70,7 @@ protected:
|
||||
```
|
||||
|
||||
类Derived私有继承了Base,对于它来说成员变量n和成员函数size都是私有的,如果使用了using语句,可以改变他们的可访问性,如上述例子中,size可以按public的权限访问,n可以按protected的权限访问。
|
||||
完整代码见:[derived_base.cpp](derived_base.cpp)
|
||||
完整代码见:[derived_base.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/using/derived_base.cpp)
|
||||
## 函数重载
|
||||
|
||||
在继承过程中,派生类可以覆盖重载函数的0个或多个实例,一旦定义了一个重载版本,那么其他的重载版本都会变为不可见。
|
||||
@@ -106,7 +109,7 @@ int main()
|
||||
```
|
||||
如上代码中,在派生类中使用using声明语句指定一个名字而不指定形参列表,所以一条基类成员函数的using声明语句就可以把该函数的所有重载实例添加到派生类的作用域中。此时,派生类只需要定义其特有的函数就行了,而无需为继承而来的其他函数重新定义。
|
||||
|
||||
完整代码见:[using_derived.cpp](using_derived.cpp)
|
||||
完整代码见:[using_derived.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/using/using_derived.cpp)
|
||||
## 取代typedef
|
||||
|
||||
C中常用typedef A B这样的语法,将B定义为A类型,也就是给A类型一个别名B
|
||||
@@ -117,4 +120,4 @@ C中常用typedef A B这样的语法,将B定义为A类型,也就是给A类
|
||||
typedef vector<int> V1;
|
||||
using V2 = vector<int>;
|
||||
```
|
||||
完整代码见:[using_typedef.cpp](using_typedef.cpp)
|
||||
完整代码见:[using_typedef.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/using/using_typedef.cpp)
|
||||
@@ -1,24 +1,26 @@
|
||||
# virtual那些事
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/virtual/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ virtual 虚函数
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.虚函数与运行多态
|
||||
|
||||
对应的代码:[emp.cpp](./set1/emp.cpp)
|
||||
对应的代码:[emp.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set1/emp.cpp)
|
||||
|
||||
**虚函数的调用取决于指向或者引用的对象的类型,而不是指针或者引用自身的类型。**
|
||||
|
||||
## 2.vptr与vtable
|
||||
|
||||
见[vptr_vtable那些事](../vptr_vtable)
|
||||
见[vptr_vtable那些事](vptr-vtable.md)
|
||||
|
||||
## 3.虚函数中默认参数
|
||||
|
||||
对应的代码:[default_arg.cpp](./set2/default_arg.cpp)
|
||||
对应的代码:[default_arg.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set2/default_arg.cpp)
|
||||
|
||||
**默认参数是静态绑定的,虚函数是动态绑定的。 默认参数的使用需要看指针或者引用本身的类型,而不是对象的类型**。
|
||||
|
||||
@@ -34,7 +36,7 @@ static成员函数不属于任何类对象或类实例,所以即使给此函
|
||||
|
||||
虚函数依靠vptr和vtable来处理。vptr是一个指针,在类的构造函数中创建生成,并且只能用this指针来访问它,静态成员函数没有this指针,所以无法访问vptr。
|
||||
|
||||
代码学习:[static_error.cpp ](./set3/static_error.cpp )
|
||||
代码学习:[static_error.cpp ](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/static_error.cpp)
|
||||
|
||||
(2)**构造函数可以为虚函数吗?**
|
||||
|
||||
@@ -48,9 +50,9 @@ static成员函数不属于任何类对象或类实例,所以即使给此函
|
||||
|
||||
代码学习:
|
||||
|
||||
- [copy_consrtuct.cpp](./set3/copy_consrtuct.cpp)
|
||||
- [copy_consrtuct.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/copy_consrtuct.cpp)
|
||||
|
||||
- [vir_con.cpp](./set3/vir_con.cpp)
|
||||
- [vir_con.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/vir_con.cpp)
|
||||
|
||||
(3)**析构函数可以为虚函数吗?**
|
||||
|
||||
@@ -58,9 +60,9 @@ static成员函数不属于任何类对象或类实例,所以即使给此函
|
||||
|
||||
代码学习:
|
||||
|
||||
- [full_virde.cpp](./set3/full_virde.cpp)
|
||||
- [full_virde.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/full_virde.cpp)
|
||||
|
||||
- [vir_de.cpp ](./set3/vir_de.cpp)
|
||||
- [vir_de.cpp ](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/vir_de.cpp)
|
||||
|
||||
(4)**虚函数可以为私有函数吗?**
|
||||
|
||||
@@ -69,8 +71,8 @@ static成员函数不属于任何类对象或类实例,所以即使给此函
|
||||
|
||||
代码学习:
|
||||
|
||||
- [virtual_function.cpp](./set3/virtual_function.cpp)
|
||||
- [virtual_function1.cpp](./set3/virtual_function1.cpp)
|
||||
- [virtual_function.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/virtual_function.cpp)
|
||||
- [virtual_function1.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/virtual_function1.cpp)
|
||||
|
||||
(5)**虚函数可以被内联吗?**
|
||||
|
||||
@@ -82,9 +84,9 @@ static成员函数不属于任何类对象或类实例,所以即使给此函
|
||||
|
||||
代码学习:
|
||||
|
||||
- [virtual_inline.cpp](./set3/virtual_inline.cpp)
|
||||
- [virtual_inline.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/virtual_inline.cpp)
|
||||
|
||||
- [inline_virtual.cpp](./set3/inline_virtual.cpp)
|
||||
- [inline_virtual.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set3/inline_virtual.cpp)
|
||||
|
||||
## 5.RTTI与dynamic_cast
|
||||
|
||||
@@ -94,9 +96,9 @@ RTTI(Run-Time Type Identification),通过运行时类型信息程序能够
|
||||
|
||||
代码学习:
|
||||
|
||||
- [rtti.cpp](./set4/rtti.cpp)
|
||||
- [warn_rtti.cpp](./set4/warn_rtti.cpp)
|
||||
- [rtti.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set4/rtti.cpp)
|
||||
- [warn_rtti.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/virtual/set4/warn_rtti.cpp)
|
||||
|
||||
## 6.纯虚函数和抽象类
|
||||
|
||||
见[纯虚函数和抽象类那些事](../abstract)
|
||||
见[纯虚函数和抽象类那些事](abstract.md)
|
||||
@@ -1,8 +1,12 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/volatile/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ volatile 关键字
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
## 1.volatile
|
||||
|
||||
@@ -117,6 +121,5 @@ return a * a;
|
||||
|
||||
代码学习:
|
||||
|
||||
- [noopt_vola.cpp](./noopt_vola.cpp)
|
||||
- [volatile.cpp](./volatile.cpp)
|
||||
|
||||
- [noopt_vola.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/volatile/noopt_vola.cpp)
|
||||
- [volatile.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/basic_content/volatile/volatile.cpp)
|
||||
@@ -1,10 +1,12 @@
|
||||
# 深入浅出C++虚函数的vptr与vtable
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/vptr-vtable/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 虚指针与虚表机制
|
||||
|
||||
## 关于作者:
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||

|
||||
|
||||
|
||||
|
||||
@@ -24,7 +26,7 @@
|
||||
|
||||
开始看代码之前,为了方便大家理解,这里给出调用图:
|
||||
|
||||

|
||||
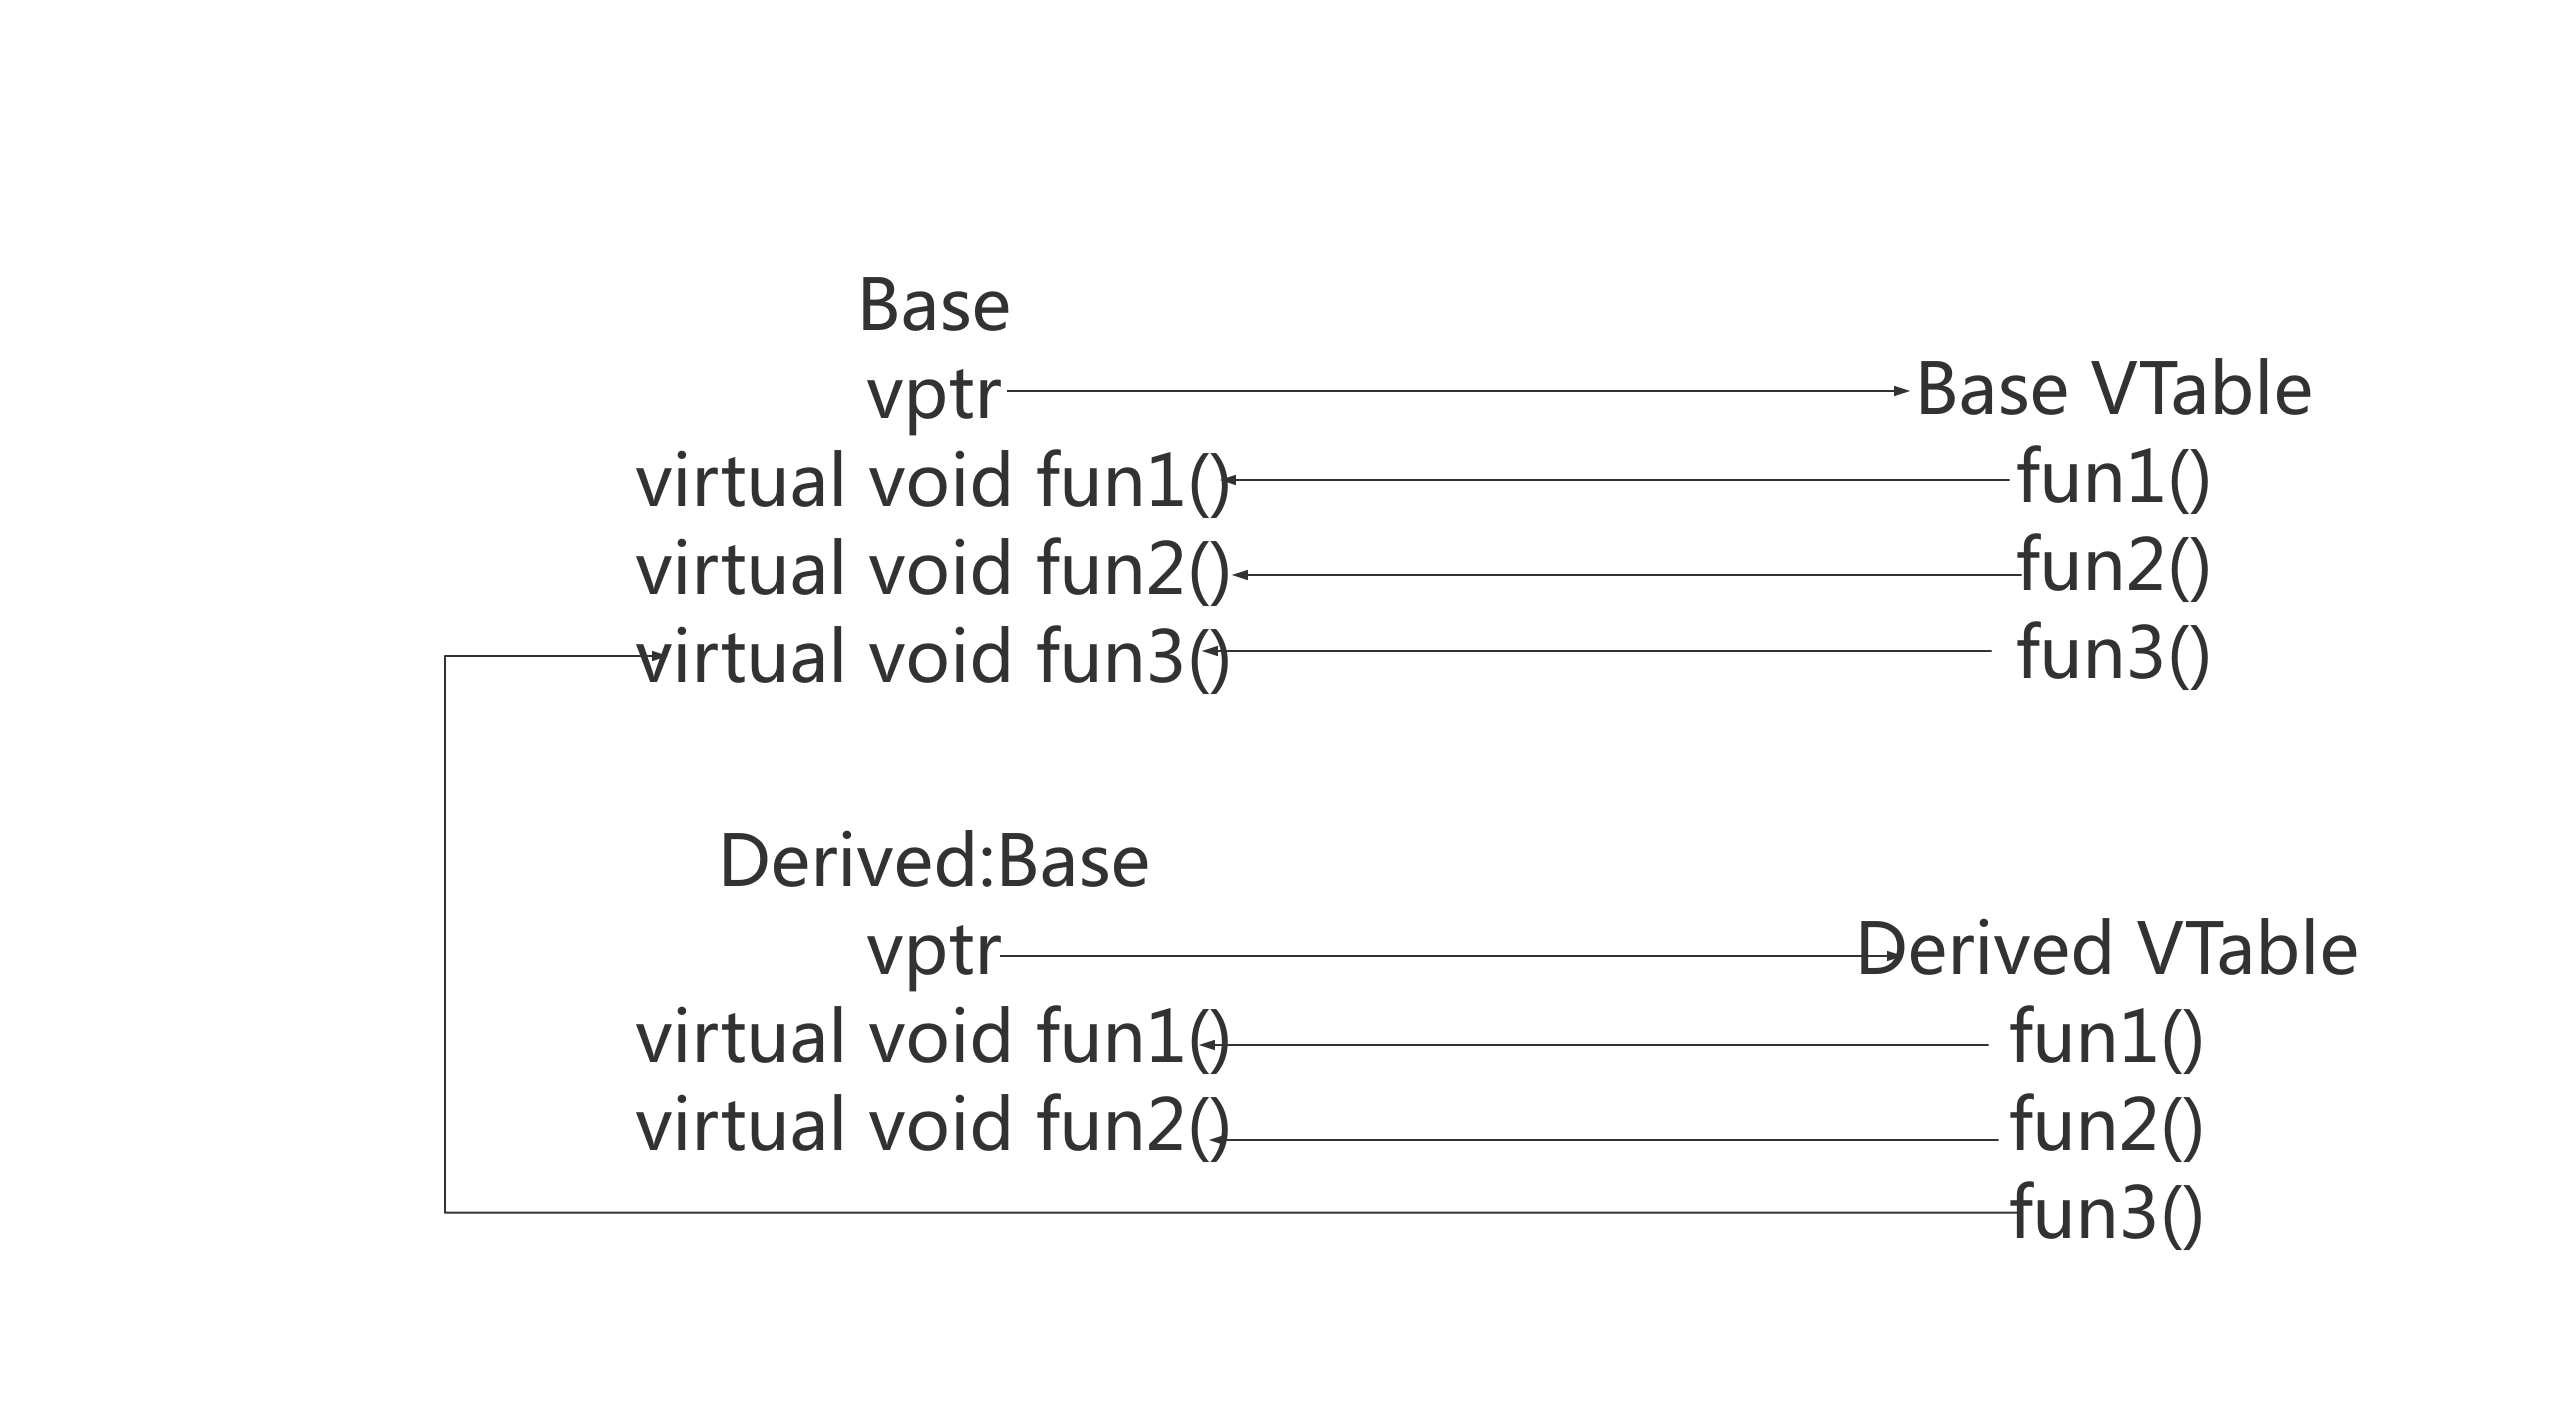
|
||||
|
||||
代码全部遵循标准的注释风格,相信大家看了就会明白,不明白的话,可以留言!
|
||||
|
||||
@@ -215,5 +217,4 @@ Dump of assembler code for function Derived::fun2():
|
||||
0x0000000000400efd <+41>: leaveq
|
||||
0x0000000000400efe <+42>: retq
|
||||
End of assembler dump.
|
||||
```
|
||||
|
||||
```
|
||||
314
codingStyleIdioms/RAII/README.md
Normal file
314
codingStyleIdioms/RAII/README.md
Normal file
@@ -0,0 +1,314 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/raii/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ RAII 资源管理
|
||||
|
||||
## 0.导语
|
||||
|
||||
在C语言中,有三种类型的内存分配:静态、自动和动态。静态变量是嵌入在源文件中的常数,因为它们有已知的大小并且从不改变,所以它们并不那么有趣。自动分配可以被认为是堆栈分配——当一个词法块进入时分配空间,当该块退出时释放空间。它最重要的特征与此直接相关。在C99之前,自动分配的变量需要在编译时知道它们的大小。这意味着任何字符串、列表、映射以及从这些派生的任何结构都必须存在于堆中的动态内存中。
|
||||
|
||||
程序员使用四个基本操作明确地分配和释放动态内存:malloc、realloc、calloc和free。前两个不执行任何初始化,内存可能包含碎片。除了自由,他们都可能失败。在这种情况下,它们返回一个空指针,其访问是未定义的行为;在最好的情况下,你的程序会崩溃。在最坏的情况下,你的程序看起来会工作一段时间,在崩溃前处理垃圾数据。
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
int main() {
|
||||
char *str = (char *) malloc(7);
|
||||
strcpy(str, "toptal");
|
||||
printf("char array = \"%s\" @ %u\n", str, str);
|
||||
|
||||
str = (char *) realloc(str, 11);
|
||||
strcat(str, ".com");
|
||||
printf("char array = \"%s\" @ %u\n", str, str);
|
||||
|
||||
free(str);
|
||||
|
||||
return(0);
|
||||
}
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```cpp
|
||||
char array = "toptal" @ 2762894960
|
||||
char array = "toptal.com" @ 2762894960
|
||||
```
|
||||
|
||||
尽管代码很简单,但它已经包含了一个反模式和一个有问题的决定。在现实生活中,你不应该直接写字节数,而应该使用sizeof函数。类似地,我们将char *数组精确地分配给我们需要的字符串大小的两倍(比字符串长度多一倍,以说明空终止),这是一个相当昂贵的操作。一个更复杂的程序可能会构建一个更大的字符串缓冲区,允许字符串大小增长。
|
||||
|
||||
## 1.RAII的发明:新希望
|
||||
|
||||
至少可以说,所有手动管理都是令人不快的。 在80年代中期,Bjarne Stroustrup为他的全新语言C ++发明了一种新的范例。 他将其称为“资源获取就是初始化”,其基本见解如下:**可以指定对象具有构造函数和析构函数,这些构造函数和析构函数在适当的时候由编译器自动调用,这为管理给定对象的内存提供了更为方便的方法。** 需要,并且该技术对于不是内存的资源也很有用。
|
||||
|
||||
意味着上面的例子在c++中更简洁:
|
||||
|
||||
```cpp
|
||||
int main() {
|
||||
std::string str = std::string ("toptal");
|
||||
std::cout << "string object: " << str << " @ " << &str << "\n";
|
||||
|
||||
str += ".com";
|
||||
std::cout << "string object: " << str << " @ " << &str << "\n";
|
||||
|
||||
return(0);
|
||||
}
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```cpp
|
||||
string object: toptal @ 0x7fffa67b9400
|
||||
string object: toptal.com @ 0x7fffa67b9400
|
||||
```
|
||||
|
||||
在上述例子中,我们没有手动内存管理!构造string对象,调用重载方法,并在函数退出时自动销毁。不幸的是,同样的简单也会导致其他问题。让我们详细地看一个例子:
|
||||
|
||||
```cpp
|
||||
vector<string> read_lines_from_file(string &file_name) {
|
||||
vector<string> lines;
|
||||
string line;
|
||||
|
||||
ifstream file_handle (file_name.c_str());
|
||||
while (file_handle.good() && !file_handle.eof() && file_handle.peek()!=EOF) {
|
||||
getline(file_handle, line);
|
||||
lines.push_back(line);
|
||||
}
|
||||
|
||||
file_handle.close();
|
||||
|
||||
return lines;
|
||||
}
|
||||
|
||||
int main(int argc, char* argv[]) {
|
||||
// get file name from the first argument
|
||||
string file_name (argv[1]);
|
||||
int count = read_lines_from_file(file_name).size();
|
||||
cout << "File " << file_name << " contains " << count << " lines.";
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```cpp
|
||||
File makefile contains 37 lines.
|
||||
```
|
||||
|
||||
这看起来很简单。`vector`被填满、返回和调用。然而,作为关心性能的高效程序员,这方面的一些问题困扰着我们:在return语句中,由于使用了值语义,`vector`在销毁之前不久就被复制到一个新`vector`中。
|
||||
|
||||
> 在现代C ++中,这不再是严格的要求了。 C ++ 11引入了移动语义的概念,其中将原点保留在有效状态(以便仍然可以正确销毁)但未指定状态。 对于编译器而言,返回调用是最容易优化以优化语义移动的情况,因为它知道在进行任何进一步访问之前不久将销毁源。 但是,该示例的目的是说明为什么人们在80年代末和90年代初发明了一大堆垃圾收集的语言,而在那个时候C ++ move语义不可用。
|
||||
|
||||
对于数据量比较大的文件,这可能会变得昂贵。 让我们对其进行优化,只返回一个指针。 语法进行了一些更改,但其他代码相同:
|
||||
|
||||
```cpp
|
||||
vector<string> * read_lines_from_file(string &file_name) {
|
||||
vector<string> * lines;
|
||||
string line;
|
||||
|
||||
ifstream file_handle (file_name.c_str());
|
||||
while (file_handle.good() && !file_handle.eof() && file_handle.peek()!=EOF) {
|
||||
getline(file_handle, line);
|
||||
lines->push_back(line);
|
||||
}
|
||||
|
||||
file_handle.close();
|
||||
|
||||
return lines;
|
||||
}
|
||||
int main(int argc, char* argv[]) {
|
||||
// get file name from the first argument
|
||||
string file_name (argv[1]);
|
||||
int count = read_lines_from_file(file_name).size();
|
||||
cout << "File " << file_name << " contains " << count << " lines.";
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```
|
||||
Segmentation fault (core dumped)
|
||||
```
|
||||
|
||||
程序崩溃!我们只需要将上述的`lines`进行内存分配:
|
||||
|
||||
```cpp
|
||||
vector<string> * lines = new vector<string>;
|
||||
```
|
||||
|
||||
这样就可以运行了!
|
||||
|
||||
不幸的是,尽管这看起来很完美,但它仍然有一个缺陷:它会泄露内存。在C++中,指向堆的指针在不再需要后必须手动删除;否则,一旦最后一个指针超出范围,该内存将变得不可用,并且直到进程结束时操作系统对其进行管理后才会恢复。惯用的现代C++将在这里使用`unique_ptr`,它实现了期望的行为。它删除指针超出范围时指向的对象。然而,这种行为直到C++11才成为语言的一部分。
|
||||
|
||||
在这里,可以直接使用C++11之前的语法,只是把main中改一下即可:
|
||||
|
||||
```cpp
|
||||
vector<string> * read_lines_from_file(string &file_name) {
|
||||
vector<string> * lines = new vector<string>;
|
||||
string line;
|
||||
|
||||
ifstream file_handle (file_name.c_str());
|
||||
while (file_handle.good() && !file_handle.eof() && file_handle.peek()!=EOF) {
|
||||
getline(file_handle, line);
|
||||
lines->push_back(line);
|
||||
}
|
||||
|
||||
file_handle.close();
|
||||
|
||||
return lines;
|
||||
}
|
||||
|
||||
int main(int argc, char* argv[]) {
|
||||
// get file name from the first argument
|
||||
string file_name (argv[1]);
|
||||
vector<string> * file_lines = read_lines_from_file(file_name);
|
||||
int count = file_lines->size();
|
||||
delete file_lines;
|
||||
cout << "File " << file_name << " contains " << count << " lines.";
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
手动去分配内存与释放内存。
|
||||
|
||||
**不幸的是,随着程序扩展到上述范围之外,很快就变得更加难以推理指针应该在何时何地被删除。当一个函数返回指针时,你现在拥有它吗?您应该在完成后自己删除它,还是它属于某个稍后将被一次性释放的数据结构?一方面出错,内存泄漏,另一方面出错,你已经破坏了正在讨论的数据结构和其他可能的数据结构,因为它们试图取消引用现在不再有效的指针。**
|
||||
|
||||
## 2.“使用垃圾收集器,flyboy!”
|
||||
|
||||
垃圾收集器不是一项新技术。 它们由John McCarthy在1959年为Lisp发明。 1980年,随着Smalltalk-80的出现,垃圾收集开始成为主流。 但是,1990年代代表了该技术的真正发芽:在1990年至2000年之间,发布了多种语言,所有语言都使用一种或另一种垃圾回收:Haskell,Python,Lua,Java,JavaScript,Ruby,OCaml 和C#是最著名的。
|
||||
|
||||
什么是垃圾收集? 简而言之,这是一组用于自动执行手动内存管理的技术。 它通常作为具有手动内存管理的语言(例如C和C ++)的库提供,但在需要它的语言中更常用。 最大的优点是程序员根本不需要考虑内存。 都被抽象了。 例如,相当于我们上面的文件读取代码的Python就是这样:
|
||||
|
||||
```python
|
||||
def read_lines_from_file(file_name):
|
||||
lines = []
|
||||
with open(file_name) as fp:
|
||||
for line in fp:
|
||||
lines.append(line)
|
||||
return lines
|
||||
|
||||
if __name__ == '__main__':
|
||||
import sys
|
||||
file_name = sys.argv[1]
|
||||
count = len(read_lines_from_file(file_name))
|
||||
print("File {} contains {} lines.".format(file_name, count))
|
||||
```
|
||||
|
||||
行数组是在第一次分配给它时出现的,并且不复制到调用范围就返回。 由于时间不确定,它会在超出该范围后的某个时间被垃圾收集器清理。 有趣的是,在Python中,用于非内存资源的RAII不是惯用语言。 允许-我们可以简单地编写`fp = open(file_name)`而不是使用with块,然后让GC清理。 但是建议的模式是在可能的情况下使用上下文管理器,以便可以在确定的时间释放它们。
|
||||
|
||||
尽管简化了内存管理,但要付出很大的代价。 在引用计数垃圾回收中,所有变量赋值和作用域出口都会获得少量成本来更新引用。 在标记清除系统中,在GC清除内存的同时,所有程序的执行都以不可预测的时间间隔暂停。 这通常称为世界停止事件。 同时使用这两种系统的Python之类的实现都会受到两种惩罚。 这些问题降低了垃圾收集语言在性能至关重要或需要实时应用程序的情况下的适用性。 即使在以下玩具程序上,也可以看到实际的性能下降:
|
||||
|
||||
```cpp
|
||||
$ make cpp && time ./c++ makefile
|
||||
g++ -o c++ c++.cpp
|
||||
File makefile contains 38 lines.
|
||||
real 0m0.016s
|
||||
user 0m0.000s
|
||||
sys 0m0.015s
|
||||
|
||||
$ time python3 python3.py makefile
|
||||
File makefile contains 38 lines.
|
||||
|
||||
real 0m0.041s
|
||||
user 0m0.015s
|
||||
sys 0m0.015s
|
||||
```
|
||||
|
||||
Python版本的实时时间几乎是C ++版本的三倍。 尽管并非所有这些差异都可以归因于垃圾收集,但它仍然是可观的。
|
||||
|
||||
## 3.所有权:RAII觉醒
|
||||
|
||||
我们知道对象的生存期由其范围决定。 但是,有时我们需要创建一个对象,该对象与创建对象的作用域无关,这是有用的,或者很有用。 在C ++中,运算符new用于创建这样的对象。 为了销毁对象,可以使用运算符delete。 由new操作员创建的对象是动态分配的,即在动态内存(也称为堆或空闲存储)中分配。 因此,由new创建的对象将继续存在,直到使用delete将其明确销毁为止。
|
||||
|
||||
使用new和delete时可能发生的一些错误是:
|
||||
|
||||
- 对象(或内存)泄漏:使用new分配对象,而忘记删除该对象。
|
||||
|
||||
- 过早删除(或悬挂引用):持有指向对象的另一个指针,删除该对象,然而还有其他指针在引用它。
|
||||
|
||||
- 双重删除:尝试两次删除一个对象。
|
||||
|
||||
通常,范围变量是首选。 但是,RAII可以用作new和delete的替代方法,以使对象独立于其范围而存在。 这种技术包括将指针分配到在堆上分配的对象,并将其放在句柄/管理器对象中。 后者具有一个析构函数,将负责销毁该对象。 这将确保该对象可用于任何想要访问它的函数,并且该对象在句柄对象的生存期结束时将被销毁,而无需进行显式清理。
|
||||
|
||||
来自C ++标准库的使用RAII的示例为std :: string和std :: vector。
|
||||
|
||||
考虑这段代码:
|
||||
|
||||
```cpp
|
||||
void fn(const std::string& str)
|
||||
{
|
||||
std::vector<char> vec;
|
||||
for (auto c : str)
|
||||
vec.push_back(c);
|
||||
// do something
|
||||
}
|
||||
```
|
||||
|
||||
当创建`vector`,并将元素推入`vector`时,您不必担心分配和取消分配此类元素内存。 `vector`使用new为其堆上的元素分配空间,并使用delete释放该空间。 作为vector的用户,您无需关心实现细节,并且会相信vector不会泄漏。 在这种情况下,向量是其元素的句柄对象。
|
||||
|
||||
标准库中使用RAII的其他示例是std :: shared_ptr,std :: unique_ptr和std :: lock_guard。
|
||||
|
||||
该技术的另一个名称是SBRM,是范围绑定资源管理的缩写。
|
||||
|
||||
现在,我们将上述读取文件例子,进行修改:
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <vector>
|
||||
#include <cstring>
|
||||
#include <fstream>
|
||||
#include <bits/unique_ptr.h>
|
||||
|
||||
using namespace std;
|
||||
unique_ptr<vector<string>> read_lines_from_file(string &file_name) {
|
||||
unique_ptr<vector<string>> lines(new vector<string>);
|
||||
string line;
|
||||
|
||||
ifstream file_handle (file_name.c_str());
|
||||
while (file_handle.good() && !file_handle.eof() && file_handle.peek()!=EOF) {
|
||||
getline(file_handle, line);
|
||||
lines->push_back(line);
|
||||
}
|
||||
|
||||
file_handle.close();
|
||||
|
||||
return lines;
|
||||
}
|
||||
int main(int argc, char* argv[]) {
|
||||
// get file name from the first argument
|
||||
string file_name (argv[1]);
|
||||
int count = read_lines_from_file(file_name).get()->size();
|
||||
cout << "File " << file_name << " contains " << count << " lines.";
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
## 4.只有在最后,你才意识到RAII的真正力量。
|
||||
|
||||
自从编译器发明以来,手动内存管理是程序员一直在想办法避免的噩梦。 RAII是一种很有前途的模式,但由于没有一些奇怪的解决方法,它根本无法用于堆分配的对象,因此在C ++中会受到影响。 因此,在90年代出现了垃圾收集语言的爆炸式增长,旨在使程序员生活更加愉快,即使以性能为代价。
|
||||
|
||||
最后,RAII总结如下:
|
||||
|
||||
- 资源在析构函数中被释放
|
||||
|
||||
- 该类的实例是堆栈分配的
|
||||
- 资源是在构造函数中获取的。
|
||||
|
||||
RAII代表“资源获取是初始化”。
|
||||
|
||||
常见的例子有:
|
||||
|
||||
- 文件操作
|
||||
|
||||
- 智能指针
|
||||
|
||||
- 互斥量
|
||||
|
||||
## 5.参考文章
|
||||
|
||||
> [1. https://www.toptal.com/software/eliminating-garbage-collector#remote-developer-job](https://www.toptal.com/software/eliminating-garbage-collector#remote-developer-job)
|
||||
|
||||
> [2. https://stackoverflow.com/questions/2321511/what-is-meant-by-resource-acquisition-is-initialization-raii](https://stackoverflow.com/questions/2321511/what-is-meant-by-resource-acquisition-is-initialization-raii)
|
||||
212
codingStyleIdioms/classInitializers/README.md
Normal file
212
codingStyleIdioms/classInitializers/README.md
Normal file
@@ -0,0 +1,212 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/class-initializer-list/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 类初始化列表惯用法
|
||||
|
||||
- const成员的初始化只能在构造函数初始化列表中进行
|
||||
- 引用成员的初始化也只能在构造函数初始化列表中进行
|
||||
- 对象成员(对象成员所对应的类没有默认构造函数)的初始化,也只能在构造函数初始化列表中进行
|
||||
|
||||
## 类之间嵌套
|
||||
|
||||
**第一种: 使用初始化列表。**
|
||||
|
||||
|
||||
```cpp
|
||||
class Animal {
|
||||
public:
|
||||
Animal() {
|
||||
std::cout << "Animal() is called" << std::endl;
|
||||
}
|
||||
|
||||
Animal(const Animal &) {
|
||||
std::cout << "Animal (const Animal &) is called" << std::endl;
|
||||
}
|
||||
|
||||
Animal &operator=(const Animal &) {
|
||||
std::cout << "Animal & operator=(const Animal &) is called" << std::endl;
|
||||
return *this;
|
||||
}
|
||||
|
||||
~Animal() {
|
||||
std::cout << "~Animal() is called" << std::endl;
|
||||
}
|
||||
};
|
||||
|
||||
class Dog {
|
||||
public:
|
||||
Dog(const Animal &animal) : __animal(animal) {
|
||||
std::cout << "Dog(const Animal &animal) is called" << std::endl;
|
||||
}
|
||||
|
||||
~Dog() {
|
||||
std::cout << "~Dog() is called" << std::endl;
|
||||
}
|
||||
|
||||
private:
|
||||
Animal __animal;
|
||||
};
|
||||
|
||||
int main() {
|
||||
Animal animal;
|
||||
std::cout << std::endl;
|
||||
Dog d(animal);
|
||||
std::cout << std::endl;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
运行结果:
|
||||
```cpp
|
||||
Animal() is called
|
||||
|
||||
Animal (const Animal &) is called
|
||||
Dog(const Animal &animal) is called
|
||||
|
||||
~Dog() is called
|
||||
~Animal() is called
|
||||
~Animal() is called
|
||||
```
|
||||
|
||||
依次分析从上到下:
|
||||
|
||||
main函数中`Animal animal;`调用默认构造。
|
||||
|
||||
`Dog d(animal);`等价于:
|
||||
|
||||
```
|
||||
Animal __animal = animal;
|
||||
```
|
||||
实际上就是调用了拷贝构造,因此输出了:
|
||||
```
|
||||
Animal (const Animal &) is called
|
||||
```
|
||||
再然后打印Dog的构造函数里面的输出。
|
||||
|
||||
最后调用析构,程序结束。
|
||||
|
||||
**第二种:构造函数赋值来初始化对象。**
|
||||
|
||||
构造函数修改如下:
|
||||
```cpp
|
||||
Dog(const Animal &animal) {
|
||||
__animal = animal;
|
||||
std::cout << "Dog(const Animal &animal) is called" << std::endl;
|
||||
}
|
||||
```
|
||||
此时输出结果:
|
||||
```
|
||||
Animal() is called
|
||||
|
||||
Animal() is called
|
||||
Animal & operator=(const Animal &) is called
|
||||
Dog(const Animal &animal) is called
|
||||
|
||||
~Dog() is called
|
||||
~Animal() is called
|
||||
~Animal() is called
|
||||
```
|
||||
|
||||
于是得出:
|
||||
|
||||
当调用`Dog d(animal);`时,等价于:
|
||||
|
||||
先定义对象,再进行赋值,因此先调用了默认构造,再调用=操作符重载函数。
|
||||
|
||||
```cpp
|
||||
// 假设之前已经有了animal对象
|
||||
Animal __animal;
|
||||
__animal = animal;
|
||||
```
|
||||
|
||||
> 小结
|
||||
|
||||
通过上述我们得出如下结论:
|
||||
|
||||
- **类中包含其他自定义的class或者struct,采用初始化列表,实际上就是创建对象同时并初始化**
|
||||
- **而采用类中赋值方式,等价于先定义对象,再进行赋值,一般会先调用默认构造,在调用=操作符重载函数。**
|
||||
|
||||
## 无默认构造函数的继承关系中
|
||||
|
||||
现考虑把上述的关系改为继承,并修改Animal与Dog的构造函数,如下代码:
|
||||
|
||||
```cpp
|
||||
class Animal {
|
||||
public:
|
||||
Animal(int age) {
|
||||
std::cout << "Animal(int age) is called" << std::endl;
|
||||
}
|
||||
|
||||
Animal(const Animal & animal) {
|
||||
std::cout << "Animal (const Animal &) is called" << std::endl;
|
||||
}
|
||||
|
||||
Animal &operator=(const Animal & amimal) {
|
||||
std::cout << "Animal & operator=(const Animal &) is called" << std::endl;
|
||||
return *this;
|
||||
}
|
||||
|
||||
~Animal() {
|
||||
std::cout << "~Animal() is called" << std::endl;
|
||||
}
|
||||
};
|
||||
|
||||
class Dog : Animal {
|
||||
public:
|
||||
Dog(int age) : Animal(age) {
|
||||
std::cout << "Dog(int age) is called" << std::endl;
|
||||
}
|
||||
|
||||
~Dog() {
|
||||
std::cout << "~Dog() is called" << std::endl;
|
||||
}
|
||||
|
||||
};
|
||||
```
|
||||
|
||||
上述是通过初始化列表给基类带参构造传递参数,如果不通过初始化列表传递,会发生什么影响?
|
||||
|
||||
去掉初始化列表
|
||||
```
|
||||
Dog(int age) {
|
||||
std::cout << "Dog(int age) is called" << std::endl;
|
||||
}
|
||||
```
|
||||
运行程序:
|
||||
|
||||
```
|
||||
error: no matching function for call to ‘Animal::Animal()’
|
||||
```
|
||||
|
||||
由于在Animal中没有默认构造函数,所以报错,遇到这种问题属于灾难性的,我们应该尽量避免,可以通过初始化列表给基类的构造初始化。
|
||||
|
||||
|
||||
## 类中const数据成员、引用数据成员
|
||||
|
||||
特别是引用数据成员,必须用初始化列表初始化,而不能通过赋值初始化!
|
||||
|
||||
例如:在上述的Animal中添加私有成员,并修改构造函数:
|
||||
```cpp
|
||||
class Animal {
|
||||
public:
|
||||
Animal(int age,std::string name) {
|
||||
std::cout << "Animal(int age) is called" << std::endl;
|
||||
}
|
||||
private:
|
||||
int &age_;
|
||||
const std::string name_;
|
||||
};
|
||||
```
|
||||
|
||||
报下面错误:
|
||||
|
||||
```cpp
|
||||
error: uninitialized reference member in ‘int&’
|
||||
```
|
||||
|
||||
应该改为下面:
|
||||
|
||||
```cpp
|
||||
Animal(int age, std::string name) : age_(age), name_(name) {
|
||||
std::cout << "Animal(int age) is called" << std::endl;
|
||||
}
|
||||
```
|
||||
207
codingStyleIdioms/copy-swap/README.md
Normal file
207
codingStyleIdioms/copy-swap/README.md
Normal file
@@ -0,0 +1,207 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/copy-swap/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ copy-and-swap 惯用法
|
||||
|
||||
> 为什么我们需要复制和交换习惯?
|
||||
|
||||
任何管理资源的类(包装程序,如智能指针)都需要实现big three。尽管拷贝构造函数和析构函数的目标和实现很简单。
|
||||
|
||||
但是复制分配运算符无疑是最细微和最困难的。
|
||||
|
||||
> 应该怎么做?需要避免什么陷阱?
|
||||
|
||||
copy-swap是解决方案,可以很好地协助赋值运算符实现两件事:避免代码重复,并提供强大的**异常保证**。
|
||||
|
||||
>它是如何工作的?
|
||||
|
||||
**从概念上讲,它通过使用拷贝构造函数的功能来创建数据的本地副本,然后使用交换功能获取复制的数据,将旧数据与新数据交换来工作。然后,临时副本将销毁,并随身携带旧数据。我们剩下的是新数据的副本。**
|
||||
|
||||
为了使用copy-swap,我们需要三件事:
|
||||
|
||||
- 一个有效的拷贝构造函数
|
||||
- 一个有效的析构函数(两者都是任何包装程序的基础,因此无论如何都应完整)以及交换功能。
|
||||
|
||||
交换函数是一种不抛异常函数,它交换一个类的两个对象或者成员。我们可能很想使用std :: swap而不是提供我们自己的方法,但这是不可能的。 std :: swap在实现中使用了copy-constructor和copy-assignment运算符,我们最终将尝试根据自身定义赋值运算符!
|
||||
|
||||
(不仅如此,对swap的无条件调用将使用我们的自定义swap运算符,从而跳过了std :: swap会导致的不必要的类构造和破坏。)
|
||||
|
||||
具体例子如下:
|
||||
|
||||
```cpp
|
||||
namespace A {
|
||||
template<typename T>
|
||||
class smart_ptr {
|
||||
public:
|
||||
smart_ptr() noexcept : ptr_(new T()) {
|
||||
|
||||
}
|
||||
|
||||
smart_ptr(const T &ptr) noexcept : ptr_(new T(ptr)) {
|
||||
|
||||
}
|
||||
|
||||
smart_ptr(smart_ptr &rhs) noexcept {
|
||||
ptr_ = rhs.release(); // 释放所有权,此时rhs的ptr_指针为nullptr
|
||||
}
|
||||
|
||||
void swap(smart_ptr &rhs) noexcept { // noexcept == throw() 保证不抛出异常
|
||||
using std::swap;
|
||||
swap(ptr_, rhs.ptr_);
|
||||
}
|
||||
|
||||
T *release() noexcept {
|
||||
T *ptr = ptr_;
|
||||
ptr_ = nullptr;
|
||||
return ptr;
|
||||
}
|
||||
|
||||
T *get() const noexcept {
|
||||
return ptr_;
|
||||
}
|
||||
|
||||
private:
|
||||
T *ptr_;
|
||||
};
|
||||
|
||||
// 提供一个非成员swap函数for ADL(Argument Dependent Lookup)
|
||||
template<typename T>
|
||||
void swap(A::smart_ptr<T> &lhs, A::smart_ptr<T> &rhs) noexcept {
|
||||
lhs.swap(rhs);
|
||||
}
|
||||
}
|
||||
// 注释开启,会引发ADL冲突
|
||||
//namespace std {
|
||||
// // 提供一个非成员swap函数for ADL(Argument Dependent Lookup)
|
||||
// template<typename T>
|
||||
// void swap(A::smart_ptr<T> &lhs, A::smart_ptr<T> &rhs) noexcept {
|
||||
// lhs.swap(rhs);
|
||||
// }
|
||||
//
|
||||
//}
|
||||
|
||||
int main() {
|
||||
|
||||
using std::swap;
|
||||
A::smart_ptr<std::string> s1("hello"), s2("world");
|
||||
// 交换前
|
||||
std::cout << *s1.get() << " " << *s2.get() << std::endl;
|
||||
swap(s1, s2); // 这里swap 能够通过Koenig搜索或者说ADL根据s1与s2的命名空间来查找swap函数
|
||||
// 交换后
|
||||
std::cout << *s1.get() << " " << *s2.get() << std::endl;
|
||||
s1=s2;
|
||||
}
|
||||
```
|
||||
|
||||
现在为了让上述的`s1=s2`完成工作,必须实现赋值运算符。
|
||||
|
||||
> 方法1
|
||||
|
||||
为了避免自赋值,通常采用下面写法 。
|
||||
|
||||
不好!
|
||||
|
||||
不具备异常安全,只具备自我赋值安全性
|
||||
|
||||
```cpp
|
||||
smart_ptr &operator=(const smart_ptr &rhs) {
|
||||
if (*this != rhs) {
|
||||
delete ptr_;
|
||||
ptr_ = new T(rhs.ptr_); // 当new 发生异常,此时ptr_指向的而是一块被删除区域,而不是被赋值对象的区域
|
||||
return *this;
|
||||
}
|
||||
return *this;
|
||||
}
|
||||
```
|
||||
|
||||
> 方法2
|
||||
|
||||
如果new出现异常,ptr_会保持原装! 也可以处理自我赋值! 还是不够好!
|
||||
|
||||
**这样就会导致代码膨胀,于是导致了另一个问题:代码冗余**
|
||||
|
||||
```cpp
|
||||
// 方法2:如果new出现异常,ptr_会保持原装! 也可以处理自我赋值! 还是不够好!
|
||||
smart_ptr &operator=(const smart_ptr &rhs) {
|
||||
T *origin = ptr_;
|
||||
ptr_ = new T(rhs.ptr_);
|
||||
delete origin;
|
||||
return *this;
|
||||
}
|
||||
```
|
||||
|
||||
> 方法3
|
||||
|
||||
copy and swap 很好!
|
||||
|
||||
```cpp
|
||||
smart_ptr &operator=(smart_ptr &rhs) noexcept {
|
||||
smart_ptr tmp(rhs);
|
||||
swap(tmp);
|
||||
return *this;
|
||||
}
|
||||
```
|
||||
|
||||
> 方法4
|
||||
|
||||
改为传值,同方法3!
|
||||
|
||||
```cpp
|
||||
smart_ptr &operator=(smart_ptr rhs) noexcept {
|
||||
swap(rhs);
|
||||
return *this;
|
||||
}
|
||||
```
|
||||
|
||||
> C++11 move
|
||||
|
||||
我们在big three上加上move ctor与move assignment就构成了big five。
|
||||
|
||||
此时再次拓展上述的代码:
|
||||
|
||||
```cpp
|
||||
// move ctor
|
||||
smart_ptr(smart_ptr &&rhs) noexcept {
|
||||
std::cout << "move ctor" << std::endl;
|
||||
ptr_ = rhs.ptr_;
|
||||
if (ptr_)
|
||||
rhs.ptr_ = nullptr;
|
||||
}
|
||||
|
||||
// move assignment
|
||||
smart_ptr &operator=(smart_ptr &&rhs) noexcept {
|
||||
std::cout << "move assignment" << std::endl;
|
||||
smart_ptr tmp(rhs);
|
||||
swap(rhs);
|
||||
return *this;
|
||||
}
|
||||
```
|
||||
|
||||
**实际上,我们比那个不需要多写代码move assignment,copy-and-swap 技巧 和 move-and-swap 技巧是共享同一个函数的。**当copy构造为上述的方法4时,**对于C++ 11,编译器会依据参数是左值还是右值在拷贝构造函数和移动构造函数间进行选择:**
|
||||
|
||||
```cpp
|
||||
smart_ptr &operator=(smart_ptr rhs) noexcept {
|
||||
swap(rhs);
|
||||
return *this;
|
||||
}
|
||||
```
|
||||
|
||||
所以当这个同上述写的
|
||||
|
||||
```cpp
|
||||
smart_ptr &operator=(smart_ptr &&rhs) noexcept{}
|
||||
```
|
||||
|
||||
同时存在,就会出现error: ambiguous overload for ‘operator=’ 。
|
||||
|
||||
调用处如下:
|
||||
|
||||
```cpp
|
||||
A::smart_ptr<std::string> s1("hello"), s2("world");
|
||||
A::smart_ptr<std::string> s3 = s1;
|
||||
A::smart_ptr<std::string> s4 = std::move(s1);
|
||||
```
|
||||
|
||||
- 如果是 s3 = s1,这样就会调用拷贝构造函数来初始化other(因为s1是左值),赋值操作符会与新创建的对象交换数据,深度拷贝。这就是copy and swap 惯用法的定义:构造一个副本,与副本交换数据,并让副本在作用域内自动销毁。
|
||||
- 如果是s4 = std::move(s1),这样就会调用移动构造函数来初始化rhs(因为std::move(s1)是右值),所以这里没有深度拷贝,只有高效的数据转移。
|
||||
|
||||
因此也可以称呼它为“统一赋值操作符”,因为它合并了"拷贝赋值"与"移动赋值"。
|
||||
73
codingStyleIdioms/enumclass/README.md
Normal file
73
codingStyleIdioms/enumclass/README.md
Normal file
@@ -0,0 +1,73 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/enum-class/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ enum class 强类型枚举
|
||||
|
||||
在Effective modern C++中Item 10: Prefer scoped enums to unscoped enum,调到要用有范围的enum class代替无范围的enum。
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
enum Shape {circle,retangle};
|
||||
auto circle = 10; // error
|
||||
```
|
||||
|
||||
上述错误是因为两个circle在同一范围。
|
||||
对于enum等价于:
|
||||
```cpp
|
||||
#define circle 0
|
||||
#define retangle 1
|
||||
```
|
||||
因此后面再去定义circle就会出错。
|
||||
|
||||
所以不管枚举名是否一样,里面的成员只要有一致的,就会出问题。
|
||||
例如:
|
||||
```cpp
|
||||
enum A {a,b};
|
||||
enum B {c,a};
|
||||
```
|
||||
a出现两次,在enum B的a处报错。
|
||||
|
||||
根据前面我们知道,enum名在范围方面没有什么作用,因此我们想到了namespace,如下例子:
|
||||
```cpp
|
||||
// 在创建枚举时,将它们放在名称空间中,以便可以使用有意义的名称访问它们:
|
||||
namespace EntityType {
|
||||
enum Enum {
|
||||
Ground = 0,
|
||||
Human,
|
||||
Aerial,
|
||||
Total
|
||||
};
|
||||
}
|
||||
|
||||
void foo(EntityType::Enum entityType)
|
||||
{
|
||||
if (entityType == EntityType::Ground) {
|
||||
/*code*/
|
||||
}
|
||||
}
|
||||
```
|
||||
将命名空间起的有意思点,就可以达到想要的效果。
|
||||
|
||||
但是不断的使用命名空间,势必太繁琐,而且如果我不想使用namespace,要达到这样的效果,便会变得不安全,也没有约束。
|
||||
|
||||
因此在c++11后,引入enum class。
|
||||
|
||||
enum class 解决了为enum成员定义类型、类型安全、约束等问题。
|
||||
回到上述例子:
|
||||
```cpp
|
||||
// enum class
|
||||
enum class EntityType {
|
||||
Ground = 0,
|
||||
Human,
|
||||
Aerial,
|
||||
Total
|
||||
};
|
||||
|
||||
void foo(EntityType entityType)
|
||||
{
|
||||
if (entityType == EntityType::Ground) {
|
||||
/*code*/
|
||||
}
|
||||
}
|
||||
```
|
||||
这便是这一节要阐述的惯用法:enum class。
|
||||
59
codingStyleIdioms/pImpl/README.md
Normal file
59
codingStyleIdioms/pImpl/README.md
Normal file
@@ -0,0 +1,59 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/pimpl/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ Pimpl 惯用法
|
||||
|
||||
“指向实现的指针”或“pImpl”是一种 C++ 编程技巧,它将类的实现细节从对象表示中移除,放到一个分离的类中,并以一个不透明的指针进行访问。
|
||||
|
||||
使用pImpl惯用法的原因如下:
|
||||
|
||||
考虑如下例子:
|
||||
|
||||
```cpp
|
||||
class X
|
||||
{
|
||||
private:
|
||||
C c;
|
||||
D d;
|
||||
} ;
|
||||
```
|
||||
|
||||
变成pImpl就是下面这样子
|
||||
|
||||
```cpp
|
||||
class X
|
||||
{
|
||||
private:
|
||||
struct XImpl;
|
||||
XImpl* pImpl;
|
||||
};
|
||||
```
|
||||
|
||||
CPP定义:
|
||||
|
||||
```cpp
|
||||
struct X::XImpl
|
||||
{
|
||||
C c;
|
||||
D d;
|
||||
};
|
||||
```
|
||||
|
||||
- 二进制兼容性
|
||||
|
||||
开发库时,可以在不破坏与客户端的二进制兼容性的情况下向XImpl添加/修改字段(这将导致崩溃!)。 由于在向Ximpl类添加新字段时X类的二进制布局不会更改,因此可以安全地在次要版本更新中向库添加新功能。
|
||||
|
||||
当然,您也可以在不破坏二进制兼容性的情况下向X / XImpl添加新的公共/私有非虚拟方法,但这与标准的标头/实现技术相当。
|
||||
|
||||
- 数据隐藏
|
||||
|
||||
如果您正在开发一个库,尤其是专有库,则可能不希望公开用于实现库公共接口的其他库/实现技术。 要么是由于知识产权问题,要么是因为您认为用户可能会被诱使对实现进行危险的假设,或者只是通过使用可怕的转换技巧来破坏封装。 PIMPL解决/缓解了这一难题。
|
||||
|
||||
- 编译时间
|
||||
|
||||
编译时间减少了,因为当您向XImpl类添加/删除字段和/或方法时(仅映射到标准技术中添加私有字段/方法的情况),仅需要重建X的源(实现)文件。 实际上,这是一种常见的操作。
|
||||
|
||||
使用标准的标头/实现技术(没有PIMPL),当您向X添加新字段时,曾经重新分配X(在堆栈或堆上)的每个客户端都需要重新编译,因为它必须调整分配的大小 。 好吧,每个从未分配X的客户端也都需要重新编译,但这只是开销(客户端上的结果代码是相同的)。
|
||||
|
||||
|
||||
|
||||
> https://stackoverflow.com/questions/8972588/is-the-pimpl-idiom-really-used-in-practices
|
||||
252
concurrency/Threading_In_CPlusPlus/README.md
Normal file
252
concurrency/Threading_In_CPlusPlus/README.md
Normal file
@@ -0,0 +1,252 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/threading-in-cpp/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 多线程入门
|
||||
|
||||
[TOC]
|
||||
|
||||
本文中的所有代码见《C++那些事》仓库。
|
||||
|
||||
> https://github.com/Light-City/CPlusPlusThings
|
||||
|
||||
## 1.理解线程与进程
|
||||
|
||||
线程是调度的基本单位 进程是资源分配的基本单位。可以把一个程序理解为进程,进程又包含多个线程。
|
||||
|
||||
例如:浏览器是个进程,而每开一个tab就是一个线程。
|
||||
|
||||
两者简单区别:
|
||||
|
||||
- **地址空间和其它资源**:进程间相互独立,同一进程的各线程间共享。某进程内的线程在其它进程不可见。
|
||||
- **通信**: 进程间通信IPC,线程间可以直接读写进程数据段(如全局变量)来进行通信——需要进程同步和互斥手段的辅助,以保证数据的一致性。
|
||||
- **调度和切换**:线程上下文切换比进程上下文切换要快得多。
|
||||
- 在**多线程OS**中,进程不是一个可执行的实体。
|
||||
|
||||
至于IPC通信与线程通信后面会新开一篇文章。
|
||||
|
||||
## 2.五种创建线程的方式
|
||||
|
||||
- 函数指针
|
||||
- Lambda函数吧
|
||||
- Functor(仿函数)
|
||||
- 非静态成员函数
|
||||
- 静态成员函数
|
||||
|
||||
### 2.1 函数指针
|
||||
|
||||
```cpp
|
||||
// 1.函数指针
|
||||
void fun(int x) {
|
||||
while (x-- > 0) {
|
||||
cout << x << endl;
|
||||
}
|
||||
}
|
||||
// 调用
|
||||
std::thread t1(fun, 10);
|
||||
t1.join();
|
||||
```
|
||||
|
||||
### 2.2 Lambda函数
|
||||
|
||||
```cpp
|
||||
// 注意:如果我们创建多线程 并不会保证哪一个先开始
|
||||
int main() {
|
||||
// 2.Lambda函数
|
||||
auto fun = [](int x) {
|
||||
while (x-- > 0) {
|
||||
cout << x << endl;
|
||||
}
|
||||
};
|
||||
// std::1.thread t1(fun, 10);
|
||||
// 也可以写成下面:
|
||||
std::thread t1_1([](int x) {
|
||||
while (x-- > 0) {
|
||||
cout << x << endl;
|
||||
}
|
||||
}, 11);
|
||||
// std::1.thread t2(fun, 10);
|
||||
// t1.join();
|
||||
t1_1.join();
|
||||
// t2.join();
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
### 2.3 仿函数
|
||||
|
||||
```cpp
|
||||
// 3.functor (Funciton Object)
|
||||
class Base {
|
||||
public:
|
||||
void operator()(int x) {
|
||||
while (x-- > 0) {
|
||||
cout << x << endl;
|
||||
}
|
||||
}
|
||||
};
|
||||
// 调用
|
||||
thread t(Base(), 10);
|
||||
t.join();
|
||||
```
|
||||
|
||||
### 2.4 非静态成员函数
|
||||
|
||||
```cpp
|
||||
// 4.Non-static member function
|
||||
class Base {
|
||||
public:
|
||||
void fun(int x) {
|
||||
while (x-- > 0) {
|
||||
cout << x << endl;
|
||||
}
|
||||
}
|
||||
};
|
||||
// 调用
|
||||
thread t(&Base::fun,&b, 10);
|
||||
t.join();
|
||||
```
|
||||
|
||||
### 2.5 静态成员函数
|
||||
|
||||
```cpp
|
||||
// 4.Non-static member function
|
||||
class Base {
|
||||
public:
|
||||
static void fun(int x) {
|
||||
while (x-- > 0) {
|
||||
cout << x << endl;
|
||||
}
|
||||
}
|
||||
};
|
||||
// 调用
|
||||
thread t(&Base::fun, 10);
|
||||
t.join();
|
||||
```
|
||||
|
||||
## 3.join与detach
|
||||
|
||||
### 3.1 join
|
||||
|
||||
- 一旦线程开始,我们要想等待线程完成,需要在该对象上调用join()
|
||||
- 双重join将导致程序终止
|
||||
- 在join之前我们应该检查显示是否可以被join,通过使用joinable()
|
||||
|
||||
```cpp
|
||||
void run(int count) {
|
||||
while (count-- > 0) {
|
||||
cout << count << endl;
|
||||
}
|
||||
std::this_thread::sleep_for(chrono::seconds(3));
|
||||
}
|
||||
|
||||
int main() {
|
||||
thread t1(run, 10);
|
||||
cout << "main()" << endl;
|
||||
t1.join();
|
||||
if (t1.joinable()) {
|
||||
t1.join();
|
||||
}
|
||||
cout << "main() after" << endl;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
### 3.2 detach
|
||||
|
||||
- 这用于从父线程分离新创建的线程
|
||||
- 在分离线程之前,请务必检查它是否可以joinable,否则可能会导致两次分离,并且双重detach()将导致程序终止
|
||||
- 如果我们有分离的线程并且main函数正在返回,那么分离的线程执行将被挂起
|
||||
|
||||
```cpp
|
||||
void run(int count) {
|
||||
while (count-- > 0) {
|
||||
cout << count << endl;
|
||||
}
|
||||
std::this_thread::sleep_for(chrono::seconds(3));
|
||||
}
|
||||
|
||||
int main() {
|
||||
thread t1(run, 10);
|
||||
cout << "main()" << endl;
|
||||
t1.detach();
|
||||
if(t1.joinable())
|
||||
t1.detach();
|
||||
cout << "main() after" << endl;
|
||||
return 0;
|
||||
|
||||
```
|
||||
|
||||
## 4.临界区与互斥量
|
||||
|
||||
### 4.1 什么是临界区(Critical Sections)?
|
||||
|
||||
临界段是一段代码,如果要使程序正确运行,一次只能由一个线程执行。如果两个线程(或进程)同时执行临界区内的代码,则程序可能不再具有正确的行为。
|
||||
|
||||
### 4.2 只是增加一个变量是临界区吗?
|
||||
|
||||
可能是吧。
|
||||
|
||||
增加变量(i ++)的过程分三个步骤:
|
||||
|
||||
- 将内存内容复制到CPU寄存器。 load
|
||||
- 在CPU中增加该值。 increment
|
||||
- 将新值存储在内存中。 store
|
||||
|
||||
如果只能通过一个线程访问该内存位置(例如下面的变量i),则不会出现争用情况,也没有与i关联的临界区。 但是sum变量是一个全局变量,可以通过两个线程进行访问。 两个线程可能会尝试同时增加变量。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <mutex>
|
||||
#include <thread>
|
||||
|
||||
using namespace std;
|
||||
|
||||
int sum = 0; //shared
|
||||
|
||||
mutex m;
|
||||
|
||||
void *countgold() {
|
||||
int i; //local to each thread
|
||||
for (i = 0; i < 10000000; i++) {
|
||||
sum += 1;
|
||||
}
|
||||
return NULL;
|
||||
}
|
||||
|
||||
int main() {
|
||||
thread t1(countgold);
|
||||
thread t2(countgold);
|
||||
|
||||
//Wait for both threads to finish
|
||||
t1.join();
|
||||
t2.join();
|
||||
|
||||
cout << "sum = " << sum << endl;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
上面代码的典型输出是sum总和为20000000。由于存在竞争条件,每次运行程序都会打印不同的总和。 该代码不会阻止两个线程同时读写总和。 例如,两个线程都将sum的当前值复制到运行每个线程的CPU中(让我们选择123)。 两个线程都将一个递增到自己的副本。 两个线程都写回该值(124)。 如果线程在不同时间访问了总和,则计数将为125。
|
||||
|
||||
### 4.3 如何确保一次只有一个线程可以访问全局变量?
|
||||
|
||||
如果一个线程当前处于临界区,我们希望另一个线程等待,直到第一个线程完成。为此,我们可以使用**互斥锁(**互斥的缩写)。
|
||||
|
||||
互斥锁形象比喻:
|
||||
|
||||
|
||||
|
||||
一个防止他人进入的简单方法,就是门口加一把锁。先到的人锁上门,后到的人看到上锁,就在门口排队,等锁打开再进去。这就叫["互斥锁"](http://zh.wikipedia.org/wiki/互斥锁)(Mutual exclusion,缩写 Mutex),防止多个线程同时读写某一块内存区域。
|
||||
|
||||
```cpp
|
||||
m.lock();
|
||||
sum += 1;
|
||||
m.unlock();
|
||||
```
|
||||
|
||||
上述代码就可以正常输出:`sum = 20000000`。
|
||||
|
||||
## 参考资料
|
||||
|
||||
> http://www.ruanyifeng.com/blog/2013/04/processes_and_threads.html?utm_source=com.ideashower.readitlater.pro&utm_medium=social&utm_oi=35626384621568
|
||||
|
||||
> https://www.youtube.com/watch?v=eZ8yKZo-PGw&list=PLk6CEY9XxSIAeK-EAh3hB4fgNvYkYmghp&index=4
|
||||
9
concurrency/concurrency_v1/README.md
Normal file
9
concurrency/concurrency_v1/README.md
Normal file
@@ -0,0 +1,9 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/cpp-concurrency-in-action/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ Concurrency in Action 导读
|
||||
|
||||
- [第一章](https://github.com/Light-City/CPlusPlusThings/tree/master/concurrency/concurrency_v1/chapter1)
|
||||
|
||||
- [第二章](https://github.com/Light-City/CPlusPlusThings/tree/master/concurrency/concurrency_v1/chapter2)
|
||||
|
||||
学习资料(第二版中文笔记):[https://downdemo.gitbook.io/cpp-concurrency-in-action-2ed/](https://downdemo.gitbook.io/cpp-concurrency-in-action-2ed/)
|
||||
@@ -1,8 +1,10 @@
|
||||
# C++新特性
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/modern-cpp/cpp11/cpp11/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++11 新特性概览
|
||||
|
||||
## 1.C++11新特性
|
||||
|
||||
- [Variadic Templates](./variadic)
|
||||
- [Variadic Templates](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/variadic)
|
||||
|
||||
- Spaces in Template Expressions
|
||||
|
||||
@@ -11,17 +13,17 @@
|
||||
vector<list<int>> // before c++ 11 error error: ‘>>’ should be ‘> >’ within a nested template argument list,c++11后可以正常通过
|
||||
```
|
||||
|
||||
- [nullptr and nullptr_t](./nullptr.cpp)
|
||||
- [nullptr and nullptr_t](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/nullptr.cpp)
|
||||
|
||||
- [Automatic Type Deduction with auto](./auto.cpp)
|
||||
- [Automatic Type Deduction with auto](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/auto.cpp)
|
||||
|
||||
- [Uniform Initialization ](./uniform_initialization.cpp)
|
||||
- [Uniform Initialization ](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/uniform_initialization.cpp)
|
||||
|
||||
- [initializer_list](./initializer.cpp)
|
||||
- [initializer_list](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/initializer.cpp)
|
||||
|
||||
- [explicit for ctors taking more than one argument](./explicit.cpp)
|
||||
- [explicit for ctors taking more than one argument](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/explicit.cpp)
|
||||
|
||||
- [range-based for statement](./auto.cpp)
|
||||
- [range-based for statement](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/auto.cpp)
|
||||
|
||||
```cpp
|
||||
for(decl:col) {
|
||||
@@ -29,33 +31,33 @@
|
||||
}
|
||||
```
|
||||
|
||||
- [=default,=delete](./default_delete.cpp)
|
||||
- [=default,=delete](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/default_delete.cpp)
|
||||
|
||||
如果你自行定义了一个ctor,那么编译器就不会给你一个default ctor
|
||||
如果强制加上=default,就可以重新获得并使用default ctor.
|
||||
|
||||
- Alias(化名)Template(template typedef)
|
||||
|
||||
- [alias.cpp](./alias.cpp)
|
||||
- [template_template.cpp](./template_template.cpp)
|
||||
- [alias.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/alias.cpp)
|
||||
- [template_template.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/template_template.cpp)
|
||||
|
||||
- [template template parameter](./template_template.cpp)
|
||||
- [template template parameter](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/template_template.cpp)
|
||||
|
||||
- [type alias](./type_alias.cpp)
|
||||
- [type alias](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/type_alias.cpp)
|
||||
|
||||
- [noexcept](./noexcept.cpp)
|
||||
- [noexcept](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/noexcept.cpp)
|
||||
|
||||
- [override](./override.cpp)
|
||||
- [override](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/override.cpp)
|
||||
|
||||
- [final](./final.cpp)
|
||||
- [final](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/final.cpp)
|
||||
|
||||
- [decltype](./decltype.cpp)
|
||||
- [decltype](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/decltype.cpp)
|
||||
|
||||
- [lambda](./lambda.cpp)
|
||||
- [lambda](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/lambda.cpp)
|
||||
|
||||
- [Rvalue reference](./rvalue.cpp)
|
||||
- [Rvalue reference](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/rvalue.cpp)
|
||||
|
||||
- [move aware class](./move.cpp)
|
||||
- [move aware class](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/move.cpp)
|
||||
|
||||
- 容器-结构与分类
|
||||
|
||||
@@ -63,8 +65,8 @@
|
||||
- (2) 关联式容器包括:set/multiset,map/multimap
|
||||
- (3) 无序容器(C++2.0新引入,更换原先hash_xxx为unordered_xxx)包括:unordered_map/unordered_multimap,unordered_set/unordered_multiset
|
||||
|
||||
- [Hash Function](./hash.cpp)
|
||||
- [Hash Function](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/hash.cpp)
|
||||
|
||||
- [tuple](./tuple.cpp)
|
||||
- [tuple](https://github.com/Light-City/CPlusPlusThings/tree/master/cpp2.0/cpp11/tuple.cpp)
|
||||
|
||||
学习资料:https://www.bilibili.com/video/av51863195?from=search&seid=3610634846288253061
|
||||
@@ -1,4 +1,6 @@
|
||||
## C++设计模式之单例模式
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/design-patterns/singleton-pattern/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ 单例模式
|
||||
|
||||
## 0.导语
|
||||
|
||||
@@ -325,4 +327,4 @@ public:
|
||||
|
||||
> https://www.cnblogs.com/liyuan989/p/4264889.html
|
||||
|
||||
> https://segmentfault.com/a/1190000015950693
|
||||
> https://segmentfault.com/a/1190000015950693
|
||||
58
design_pattern/singleton/singleton_default.hpp
Normal file
58
design_pattern/singleton/singleton_default.hpp
Normal file
@@ -0,0 +1,58 @@
|
||||
/**
|
||||
* @file singleton_default.hpp
|
||||
* @brief 可复用的线程安全单例模板基类(CRTP)
|
||||
* 受 issue #303 启发:https://github.com/Light-City/CPlusPlusThings/issues/303
|
||||
* 参考 boost::container::singleton_default 的思路。
|
||||
*
|
||||
* 用法:
|
||||
* class MyConfig : public SingletonDefault<MyConfig> {
|
||||
* friend class SingletonDefault<MyConfig>;
|
||||
* private:
|
||||
* MyConfig() = default; // 构造私有,交由基类创建
|
||||
* public:
|
||||
* int value = 42;
|
||||
* };
|
||||
* MyConfig::instance().value = 1;
|
||||
*
|
||||
* 编译:g++ -std=c++11 main.cpp
|
||||
* @author 光城
|
||||
* @version v1
|
||||
* @date 2026-10
|
||||
*/
|
||||
|
||||
#pragma once
|
||||
|
||||
#include <mutex>
|
||||
|
||||
template <class T>
|
||||
class SingletonDefault {
|
||||
public:
|
||||
SingletonDefault(const SingletonDefault&) = delete;
|
||||
SingletonDefault& operator=(const SingletonDefault&) = delete;
|
||||
|
||||
static T& instance() {
|
||||
// C++11 起,局部静态变量的初始化由标准保证线程安全("magic statics")
|
||||
static T inst;
|
||||
return inst;
|
||||
}
|
||||
|
||||
protected:
|
||||
SingletonDefault() = default;
|
||||
~SingletonDefault() = default;
|
||||
};
|
||||
|
||||
/**
|
||||
* 若需要 C++03 或对 magic statics 不放心的环境,可用 call_once 版本:
|
||||
*
|
||||
* template <class T>
|
||||
* class SingletonDefaultOnce {
|
||||
* public:
|
||||
* static T& instance() {
|
||||
* std::call_once(once_, [] { inst_.reset(new T); });
|
||||
* return *inst_;
|
||||
* }
|
||||
* private:
|
||||
* static std::once_flag once_;
|
||||
* static std::unique_ptr<T> inst_;
|
||||
* };
|
||||
*/
|
||||
100
extension/some_problem/README.md
Normal file
100
extension/some_problem/README.md
Normal file
@@ -0,0 +1,100 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-tools/cpp-string-to-int/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# C++ string 转 int
|
||||
|
||||
个人公众号:
|
||||
|
||||

|
||||
|
||||
首先提出解决方案:
|
||||
|
||||
- atoi
|
||||
- strtol
|
||||
- stoi
|
||||
|
||||
这几个有什么不同呢?下面测试对比。
|
||||
|
||||
> C语言风格函数
|
||||
|
||||
atoi与strtol对比:
|
||||
|
||||
```cpp
|
||||
string str = "16s";
|
||||
int a = atoi(str.c_str());
|
||||
int b = strtol(str.c_str(), nullptr, 10);
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```
|
||||
atoi的结果为:16
|
||||
strtol的结果为:16
|
||||
```
|
||||
|
||||
这两个函数都是从字符串开始寻找数字或者正负号或者小数点,遇到非法字符终止。
|
||||
|
||||
所以到上述s字符就不输出了,提前结束,也就是说当你的字符串不是数字的时候,或者小数点等非数字,不会报异常!直接输出0.
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
string str = "asdsa";
|
||||
int a = atoi(str.c_str());
|
||||
int b = strtol(str.c_str(), nullptr, 10);
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```
|
||||
0
|
||||
0
|
||||
```
|
||||
|
||||
strtol相比与atoi来说,支持多种进制转换,例如8进制等
|
||||
|
||||
例如:
|
||||
|
||||
```
|
||||
int b = strtol(str.c_str(), nullptr, 8);
|
||||
```
|
||||
|
||||
> C++风格
|
||||
|
||||
在C++中可以使用stoi来转int,这个函数相比于前两个一个最大特点是:异常!
|
||||
|
||||
我们知道C++相比于C语言多了异常,这也是这个函数在C++中具有的最显著功能。
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
string str1 = "asq,";
|
||||
// int c = stoi(str1); // 报异常
|
||||
string str2 = "12312";
|
||||
int c = stoi(str2); // ok
|
||||
cout << c << endl;
|
||||
```
|
||||
|
||||
异常如下:
|
||||
|
||||
```
|
||||
terminate called after throwing an instance of 'std::invalid_argument'
|
||||
what(): stoi
|
||||
```
|
||||
|
||||
> 自定义
|
||||
|
||||
也就是自己写呗,如下:
|
||||
|
||||
```cpp
|
||||
int stringToInt(const string &s) {
|
||||
int v;
|
||||
stringstream ss;
|
||||
ss << s;
|
||||
ss >> v;
|
||||
return v;
|
||||
}
|
||||
int main() {
|
||||
int i = stringToInt("2.3");
|
||||
cout<<i<<endl;
|
||||
}
|
||||
```
|
||||
29
learn_class/modern_cpp_30/README.md
Normal file
29
learn_class/modern_cpp_30/README.md
Normal file
@@ -0,0 +1,29 @@
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/cpp-courses/modern-cpp-30-geektime/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
# 极客时间《现代 C++ 实战 30 讲》
|
||||
|
||||
- [堆、栈、RAII:C++里该如何管理资源?](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/RAII)
|
||||
- [堆](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/RAII/heap.cpp)
|
||||
- [栈](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/RAII/stack.cpp)
|
||||
- [RAII](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/RAII/RAII.cpp)
|
||||
- [自己动手,实现C++的智能指针](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/smart_ptr)
|
||||
- [auto_ptr、scope_ptr](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/smart_ptr/auto_scope.cpp)
|
||||
- [unique_ptr](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/smart_ptr/unique_ptr.cpp)
|
||||
- [shared_ptr](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/smart_ptr/shared_ptr.cpp)
|
||||
- [右值和移动究竟解决了什么问题?](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/reference)
|
||||
- [左值与右值](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/reference/reference.cpp)
|
||||
- [延长声明周期](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/reference/lifetime.cpp)
|
||||
- [引用折叠](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/reference/collapses.cpp)
|
||||
- [完美转发](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/reference/forward.cpp)
|
||||
- [不要返回本地变量的引用](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/reference/don'treturnReference.cpp)
|
||||
- [容器1](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/container1)
|
||||
- [容器2](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/container2)
|
||||
- [异常](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/exception)
|
||||
- [字面量、静态断言和成员函数说明符](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/literalAssert)
|
||||
- [是不是应该返回对象?](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/obj)
|
||||
- [编译期多态:泛型编程和模板入门](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/compilerpoly)
|
||||
- [译期能做些什么?一个完整的计算世界](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/compilercompute)
|
||||
- [SFINAE:不是错误的替换失败是怎么回事?](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/SFINAE)
|
||||
- [constexpr:一个常态的世界](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/constexpr)
|
||||
- [函数对象和lambda:进入函数式编程](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/functionLambda)
|
||||
- [内存模型和atomic:理解并发的复杂性](https://github.com/Light-City/CPlusPlusThings/tree/master/learn_class/modern_cpp_30/memorymodel_atomic)
|
||||
@@ -1,41 +1,62 @@
|
||||
# 10日c++实战狂练
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/practical-exercises/10-day-cpp-crash-course/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
- [x] [day1](day1)
|
||||
# C++ 十日速成练习
|
||||
|
||||
- [x] [day1](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day1)
|
||||
|
||||
基本c++语法
|
||||
|
||||
- [x] [day2](day2)
|
||||
- [x] [day2](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day2)
|
||||
|
||||
递归、结构体、枚举、静态变量等
|
||||
|
||||
- [x] [day3](day3)
|
||||
- [x] [day3](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day3)
|
||||
|
||||
函数
|
||||
|
||||
- [x] [day4](day4)
|
||||
- [x] [day4](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day4)
|
||||
|
||||
函数深入
|
||||
|
||||
- [x] [day5](day5)
|
||||
- [x] [day5](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day5)
|
||||
|
||||
继承多态
|
||||
|
||||
- [x] [day6](day6)
|
||||
- [x] [day6](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day6)
|
||||
|
||||
虚函数、抽象类
|
||||
|
||||
- [x] [day7](day7)
|
||||
- [x] [day7](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day7)
|
||||
|
||||
运算符重载
|
||||
|
||||
- [x] [day8](day8)
|
||||
- [x] [day8](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day8)
|
||||
|
||||
模板与STL
|
||||
|
||||
- [x] [day9](day9)
|
||||
- [x] [day9](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day9)
|
||||
|
||||
异常
|
||||
|
||||
- [x] [day10](day10)
|
||||
- [x] [day10](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/10_day_practice/day10)
|
||||
|
||||
文件与流
|
||||
文件与流
|
||||
|
||||
## 每日题目说明(回应 [issue #136](https://github.com/Light-City/CPlusPlusThings/issues/136))
|
||||
|
||||
题目即每天的**文件名 + 文件内注释**,这里给出汇总清单,练习时先看题目名,自己写一遍,再对照仓库实现:
|
||||
|
||||
| Day | 主题 | 题目(对应仓库文件) |
|
||||
| --- | --- | --- |
|
||||
| 1 | 基本语法 | 注释对齐(annotate)、打印输出(print)、闰年判断(runnian)、union 初探(union) |
|
||||
| 2 | 递归/结构体/枚举 | 汉诺塔(hanoi)、幂运算(pow)、递归基础(rec1)、简单计算器(compute)、枚举应用(enum) |
|
||||
| 3 | 函数 | 函数重载、默认参数、值/引用/指针传参对比 |
|
||||
| 4 | 函数深入 | 函数指针、回调、可变参数、内联函数 |
|
||||
| 5 | 类与对象 | 构造/析构(ctor_dtor)、继承访问控制(inherit_access)、运算符重载(rule)、组合关系(rela)、虚函数初探(virtual) |
|
||||
| 6 | 继承多态 | 虚函数、抽象类、纯虚函数、多态综合案例 |
|
||||
| 7 | 运算符重载 | 算术/关系/下标/圆括号重载、强制转换运算符 |
|
||||
| 8 | 模板与 STL | 类模板(class_template)、函数模板(func)、STL 容器入门(stl) |
|
||||
| 9 | 异常 | try/catch、自定义异常、异常安全 |
|
||||
| 10 | 文件与流 | 文件读写、流的格式化 |
|
||||
|
||||
> 建议:每道题先自己从零写,写不出来再看实现;写完了对比差距,收获最大(参考 [issue #180](https://github.com/Light-City/CPlusPlusThings/issues/180) 的讨论)。
|
||||
|
||||
@@ -1,26 +1,27 @@
|
||||
## 重点实战练习
|
||||
> 本文档由 [C++那些事网站](https://light-city.github.io/stories_things/practical-exercises/key-cpp-exercises/) 同步生成,网站版本含多语言与更新排版。
|
||||
|
||||
├── [中括号重载.cpp](bracket_overloading.cpp)
|
||||
├── [时钟++运算符重载.cpp](clock.cpp)
|
||||
├── [运算符重载之强制转换.cpp](operator_cast.cpp)
|
||||
└── [重载圆括号的时钟.cpp](operator_circle.cpp)
|
||||
# C++ 重点实战练习
|
||||
|
||||
├── [函数模板.cpp](func_temp.cpp)
|
||||
├── [中括号重载.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/bracket_overloading.cpp)
|
||||
├── [时钟++运算符重载.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/clock.cpp)
|
||||
├── [运算符重载之强制转换.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/operator_cast.cpp)
|
||||
└── [重载圆括号的时钟.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/operator_circle.cpp)
|
||||
|
||||
├── [动态数组.cpp](array.cpp)
|
||||
├── [函数模板.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/func_temp.cpp)
|
||||
|
||||
├── [字典插入与查找.cpp](map_insert_look.cpp)
|
||||
├── [动态数组.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/array.cpp)
|
||||
|
||||
├── [异常捕获.cpp](try.cpp)
|
||||
├── [字典插入与查找.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/map_insert_look.cpp)
|
||||
|
||||
├── [类模板之栈.cpp](stack.cpp)
|
||||
├── [异常捕获.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/try.cpp)
|
||||
|
||||
├── [类模板特化之数组.cpp](array_template.cpp)
|
||||
├── [类模板之栈.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/stack.cpp)
|
||||
|
||||
├── [继承与封装.cpp](override.cpp)
|
||||
├── [类模板特化之数组.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/array_template.cpp)
|
||||
|
||||
├── [读写文件综合题.cpp](read_file.cpp)
|
||||
├── [输入输出运算符重载.cpp](io_operator_overload.cpp)
|
||||
├── [输入输出重载.cpp](io_operator.cpp)
|
||||
├── [输出格式.cpp](output.cpp)
|
||||
├── [继承与封装.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/override.cpp)
|
||||
|
||||
├── [读写文件综合题.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/read_file.cpp)
|
||||
├── [输入输出运算符重载.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/io_operator_overload.cpp)
|
||||
├── [输入输出重载.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/io_operator.cpp)
|
||||
├── [输出格式.cpp](https://github.com/Light-City/CPlusPlusThings/tree/master/practical_exercises/key_exercises/output.cpp)
|
||||
59
site_extras/about.md
Normal file
59
site_extras/about.md
Normal file
@@ -0,0 +1,59 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/about/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# 联系作者
|
||||
|
||||
我是开源社区的积极参与者,为[CPlusPlusThings](https://github.com/Light-City/CPlusPlusThings)、[Apache Arrow](https://github.com/apache/arrow)和[DuckDB](https://github.com/duckdb/duckdb)等项目做出了贡献。我热衷于促进开源计划的发展并支持协作生态系统。
|
||||
|
||||
我是一名全栈工程师。
|
||||
|
||||
我❤️后端工程师。
|
||||
|
||||
🖖 我主要将精力放在使用 C/Go/C++ 进行后端开发上。
|
||||
|
||||
我喜欢在以下平台写文章:
|
||||
|
||||
- [Medium](https://light-city.medium.com/)
|
||||
- [WeChat](https://mp.weixin.qq.com/s/5_Ms8bGbA-PWj5EwmTBaQA)
|
||||
- [ZhiHu](https://www.zhihu.com/people/francis-52-23/posts)
|
||||
- [BiliBili](https://space.bilibili.com/367439608?spm_id_from=333.337.0.0)
|
||||
|
||||
现在专注于数据库相关的工作,欢迎与我交流!
|
||||
|
||||
- 微信
|
||||
|
||||
搜索:gcxzhang
|
||||
|
||||
- 微信公众号
|
||||
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/xq.jpg" height="200" width="200"><br>
|
||||
知识星球
|
||||
</th>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/wechat.jpg" height="200" width="200"><br>
|
||||
微信公众号
|
||||
</th>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
- 赞赏我
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/alipay.jpg" height="200" width="200"><br>
|
||||
支付宝
|
||||
</th>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/wechat.png" height="200" width="200"><br>
|
||||
微信
|
||||
</th>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
- 邮箱: 455954986@qq.com
|
||||
146
site_extras/cplusplus-things-overview.md
Normal file
146
site_extras/cplusplus-things-overview.md
Normal file
@@ -0,0 +1,146 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cplusplus-things-overview/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# 项目概要
|
||||
|
||||
## 1. 项目概述
|
||||
|
||||
- 中文名:[**C++那些事**](https://github.com/Light-City/CPlusPlusThings)
|
||||
- 英文名:[**Stories About C Plus Plus or CPlusPlusThings**](https://github.com/Light-City/CPlusPlusThings)
|
||||
|
||||
**C++ 那些事** 是一个面向 C++ 初学者和进阶开发者的开源学习项目。该项目旨在帮助学习者从 C++ 的基础入门到高级进阶,涵盖从语法基础、面向对象编程、模板编程、STL 使用,到多线程并发、内存管理、性能优化等高级主题。此外,项目还深入分析了一些经典的开源库和框架的源码,帮助开发者更好地理解 C++ 在实际项目中的应用。
|
||||
|
||||
## 2. 项目目标
|
||||
|
||||
- **入门到进阶**:为初学者提供一个系统化的学习路径,帮助他们从零基础逐步掌握 C++ 的核心概念和高级特性。
|
||||
- **面试准备**:为求职者提供常见 C++ 面试题的解析和实战演练,帮助他们在面试中脱颖而出。
|
||||
- **源码分析**:通过分析经典开源项目的源码,帮助开发者深入理解 C++ 的设计模式和实现原理。
|
||||
- **多线程与并发**:深入探讨 C++ 中的多线程编程和并发控制,帮助开发者编写高效、安全的并发程序。
|
||||
- **性能优化**:介绍 C++ 中的性能优化技巧,帮助开发者编写高效的代码。
|
||||
|
||||
## 3. 项目内容
|
||||
|
||||
**C++ 那些事** 项目内容丰富,涵盖了 C++ 的各个方面,主要包括以下几个模块:
|
||||
|
||||
- **基础进阶**
|
||||
|
||||
- **关键字与特性**:如 `const`、`static`、`this`、`inline`、`sizeof`、`virtual`、`volatile`、`explicit`、`friend`、`using`、`::`、`enum`、`decltype` 等关键字的详细解析。
|
||||
- **函数与指针**:函数指针、纯虚函数和抽象类、`vptr_vtable` 等。
|
||||
- **数据结构**:`struct`、`union`、位域、引用与指针的区别等。
|
||||
- **C 实现 C++ 多态**:通过 C 语言实现 C++ 的多态特性。
|
||||
- **宏与断言**:宏的定义与使用、`assert` 的使用场景。
|
||||
|
||||
- **实战系列**
|
||||
|
||||
- **10 日狂练**:通过 10 天的密集练习,快速提升 C++ 编程能力。
|
||||
- **重点实战练习**:针对 C++ 中的重点难点进行实战演练,巩固所学知识。
|
||||
|
||||
- **STL 源码剖析**
|
||||
|
||||
- **容器**:`array`、`deque`、`queue`、`stack`、`list`、`vector`、`rb_tree`、`set`、`multiset`、`map`、`multimap`、`hashtable`、`unordered_map` 等容器的源码分析。
|
||||
- **迭代器与特性**:`iterator`、`traits`、`typename` 等。
|
||||
- **EBO 优化**:STL 设计中的空基类优化(EBO)技术。
|
||||
|
||||
- **C++2.0 新特性**
|
||||
|
||||
- **C++11 新特性**:如自动类型推导、Lambda 表达式、右值引用、智能指针等;另见站内 [C++11 专题](modern-cpp/cpp11/index.md)。
|
||||
- **C++17 / C++20**:[C++17 专题](modern-cpp/cpp17/index.md)、[C++20 专题](modern-cpp/cpp20/index.md)。
|
||||
|
||||
- **拓展专题**
|
||||
|
||||
- **语言机制深入**:mutable、const 全家桶、ABI、尾递归等(见导航「基础进阶 → 语言机制深入」)。
|
||||
- **内存与调试**、**性能测评**、**项目实战**、**阅读与技巧**:独立导航栏目,含 AddressSanitizer、Benchmark、pybind11、gRPC 等实战文。
|
||||
|
||||
- **设计模式**
|
||||
|
||||
- **常见设计模式**:如单例模式、工厂模式、观察者模式等在 C++ 中的应用。
|
||||
|
||||
- **并发编程**
|
||||
|
||||
- **多线程与多进程**:`std::thread`、`std::async`、`std::mutex`、`std::condition_variable` 等多线程编程技术。
|
||||
- **C++ Concurrency in Action**:深入探讨 C++ 中的并发编程模型与实践。
|
||||
|
||||
- **C++ 惯用法**
|
||||
|
||||
- **编程风格与惯用法**:探讨 C++ 中的常见编程风格与惯用法,帮助开发者写出更优雅的代码。
|
||||
|
||||
- **学习课程**
|
||||
|
||||
- **极客时间《现代 C++ 实战 30 讲》**:推荐学习资源,帮助开发者系统学习现代 C++。
|
||||
|
||||
- **工具篇**
|
||||
|
||||
- **调试与输出工具**:如 `dbg-macro`、`rr` 等调试工具的使用。
|
||||
- **容器快捷输出工具**:简化容器输出的工具。
|
||||
- **观察编译过程**:通过工具观察 C++ 代码的编译过程变化。
|
||||
|
||||
## 4. 项目特色
|
||||
|
||||
- **系统化学习路径**:从基础到进阶,内容循序渐进,适合不同层次的学习者。
|
||||
- **理论与实践结合**:不仅有理论知识的讲解,还有大量的代码示例和实战项目。
|
||||
- **源码深度分析**:通过分析经典开源项目的源码,帮助开发者深入理解 C++ 的设计与实现。
|
||||
- **多线程与并发**:深入探讨 C++ 中的并发编程,帮助开发者编写高效、安全的并发程序。
|
||||
- **面试导向**:提供常见面试题的解析,帮助求职者更好地准备面试。
|
||||
|
||||
## 5. 项目资源
|
||||
|
||||
- **在线学习网站**:[C++那些事](https://light-city.github.io/stories_things/)
|
||||
- **微信公众号**:[光城](https://mp.weixin.qq.com/s/5_Ms8bGbA-PWj5EwmTBaQA)
|
||||
- **B站视频**:[未来的光城](https://www.bilibili.com/video/BV1Rv4y1H7LB/?vd_source=bb6532dcd5b1d6b26125da900adb618e),项目内容同步至 B站,以视频形式展示,方便学习者观看。
|
||||
|
||||
## 6. 参与方式
|
||||
|
||||
[**C++那些事**](https://github.com/Light-City/CPlusPlusThings)是一个开源项目,欢迎各位开发者参与贡献。你可以通过以下方式参与:
|
||||
|
||||
- **Star 和 Fork**:如果你觉得项目对你有帮助,欢迎在 GitHub 上 Star 和 Fork 项目。
|
||||
- **提交 PR**:如果你有好的内容或改进建议,欢迎提交 Pull Request。
|
||||
- **反馈与建议**:如果你在使用过程中遇到问题或有任何建议,欢迎在项目的 Issue 区提出。
|
||||
|
||||
## 7. 项目未来规划
|
||||
|
||||
- **扩展更多高级主题**:如 C++20 新特性、元编程、编译期计算等。
|
||||
- **增加更多实战项目**:通过更多的实战项目,帮助开发者将所学知识应用到实际开发中。
|
||||
- **社区建设**:建立更活跃的社区,鼓励开发者之间的交流与分享。
|
||||
|
||||
## 8. 结语
|
||||
|
||||
[**C++那些事**](https://github.com/Light-City/CPlusPlusThings)是一个致力于帮助 C++ 学习者从入门到进阶的开源项目。无论你是初学者还是有一定经验的开发者,都可以在这里找到适合自己的学习资源。希望通过这个项目,能够帮助更多的人掌握 C++,并在实际开发中运用自如。
|
||||
|
||||
欢迎各位开发者 Star、Fork、PR,共同推动 C++ 社区的发展!
|
||||
|
||||
## 9. 关于作者
|
||||
|
||||
- **微信**:搜索 `gcxzhang`
|
||||
|
||||
- **微信公众号**
|
||||
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/xq.jpg" height="200" width="200"><br>
|
||||
知识星球
|
||||
</th>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/wechat.jpg" height="200" width="200"><br>
|
||||
微信公众号
|
||||
</th>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
- **赞赏支持**
|
||||
|
||||
<table>
|
||||
<tbody>
|
||||
<tr>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/alipay.jpg" height="200" width="200"><br>
|
||||
支付宝
|
||||
</th>
|
||||
<th align="center" style="height=200 width="200">
|
||||
<img src="assets/images/wechat.png" height="200" width="200"><br>
|
||||
微信
|
||||
</th>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
121
site_extras/cpp-benchmarks-cpp-sso-benchmark.md
Normal file
121
site_extras/cpp-benchmarks-cpp-sso-benchmark.md
Normal file
@@ -0,0 +1,121 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-benchmarks/cpp-sso-benchmark/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ string SSO 性能测试
|
||||
|
||||
今天想问大家两个问题:
|
||||
|
||||
**1.下面代码性能上有没有区别?**
|
||||
|
||||
```cpp
|
||||
std::string s1("hello world hel");
|
||||
std::string s2("hello world helo");
|
||||
```
|
||||
|
||||
**2.sizeof(std::string)是多少?**
|
||||
|
||||
下面,我们来一起探索这两个问题。
|
||||
|
||||
由于这两个答案在g++(libstdc++)与clang(libc++)上的结果不一样,所以这里会分别进行分析。
|
||||
|
||||
## 1.g++(libstdc++)
|
||||
|
||||
g++的源码我们以g++-10为例,详细代码可以戳这个github地址,这里列出比较核心的代码。
|
||||
|
||||
> https://github.com/gcc-mirror/gcc/blob/devel/omp/gcc-10/libstdc%2B%2B-v3/include/bits/basic_string.h#L171
|
||||
|
||||
```cpp
|
||||
template<typename _CharT, typename _Traits, typename _Alloc>
|
||||
class basic_string {
|
||||
private:
|
||||
struct _Alloc_hider : allocator_type {
|
||||
pointer _M_p; // The actual data.
|
||||
};
|
||||
enum { __min_cap = 15 / sizeof(value_type) };
|
||||
_Alloc_hider _M_dataplus; // 8 bytes
|
||||
size_type __size_; // 8 bytes
|
||||
|
||||
union {
|
||||
_CharT _M_local_buf[_S_local_capacity + 1]; // 16 bytes
|
||||
size_type _M_allocated_capacity; // 8 bytes
|
||||
}; // 16 bytes
|
||||
}; // 32 bytes
|
||||
```
|
||||
|
||||
在上面代码中注释部分详细的列出了string占据的字节(注意:这里的value_type以char来计算,也就是sizeof(value_type) = 1)。
|
||||
|
||||
sizeof(string) = 8 + 8 + 16 = 32。
|
||||
|
||||
其中8字节ptr,8字节size,16字节union。
|
||||
|
||||
性能层面,这里实现了SSO,本地buffer会存储最多15个字符,当超过15字符便会分配在heap上,这里我写了一个benchmark来对比性能。
|
||||
|
||||
- 短字符串测试内容为:"hello world hel",总共15个字符。
|
||||
- 长字符串测试内容为:"hello world helo",总共为16个字符。
|
||||
|
||||
```
|
||||
std::string s1("hello world hel");
|
||||
std::string s2("hello world helo");
|
||||
```
|
||||
|
||||
可以看到性能差距非常大,仅仅一个字符会导致std::string性能差别这么大!
|
||||
|
||||
这里本质还是前面的SSO local buffer。
|
||||
|
||||
性能测试:https://quick-bench.com/q/s7pvDB_SwQyDCcZk50odAaYIzMc
|
||||
|
||||

|
||||
|
||||
## 2.clang++(libc++)
|
||||
|
||||
同理,我们以llvm-14为例,如果想要看完整代码戳下面的github地址即可,这里摘取出核心代码。
|
||||
|
||||
> https://github.com/llvm/llvm-project/blob/release/14.x/libcxx/include/string#L765
|
||||
|
||||
```cpp
|
||||
template<class _CharT, class _Traits, class _Allocator>
|
||||
class basic_string {
|
||||
private:
|
||||
struct __long {
|
||||
size_type __cap_; // 8 bytes
|
||||
size_type __size_; // 8 bytes
|
||||
pointer __data_; // 8 bytes
|
||||
};
|
||||
|
||||
enum {__min_cap = (sizeof(__long) - 1)/sizeof(value_type) > 2 ?
|
||||
(sizeof(__long) - 1)/sizeof(value_type) : 2};
|
||||
|
||||
struct __short {
|
||||
union {
|
||||
unsigned char __size_; // 1 bytes
|
||||
value_type __lx; // 1 bytes
|
||||
}; // 1 bytes
|
||||
value_type __data_[__min_cap]; // 23 bytes
|
||||
}; // 24 bytes
|
||||
|
||||
union __ulx {
|
||||
__long __lx; // 24 bytes
|
||||
__short __lxx; // 24 bytes
|
||||
}; // 24 bytes
|
||||
}
|
||||
```
|
||||
|
||||
在上面代码中注释部分详细的列出了string占据的字节(注意:这里的value_type以char来计算,也就是sizeof(value_type) = 1)。
|
||||
|
||||
sizeof(string) = union的大小,这个union是24字节,所以等于24。
|
||||
|
||||
而SSO,本地buffer存储的字符不超过22,当超过22个字符便会分配在heap上。
|
||||
|
||||
所以当我们使用与gcc同样的测试代码应用在clang上,我们便得到了不太一样的结果,即:long字符串的性能与short字符串的性能拆别不大。原因就是gcc的测试case都是在22个字符以内,都是短字符。
|
||||
|
||||
性能测试:https://quick-bench.com/q/nmLMqQZ31cmWBbbIFr2nHN2JL1k
|
||||
|
||||

|
||||
|
||||
当我们测试真正的长短字符串时,性能便会发生明显变化,趋势与gcc保持一致。
|
||||
|
||||
- 短字符串测试内容为:"hello world hello worl",总共22个字符。
|
||||
- 长字符串测试内容为:"hello world hello world",总共为23个字符。
|
||||
|
||||
性能测试:https://quick-bench.com/q/ujtMrtotEi6RrpfMDJ1UcSLFIJE
|
||||
|
||||

|
||||
27
site_extras/cpp-benchmarks-memcpy-vs-std-copy.md
Normal file
27
site_extras/cpp-benchmarks-memcpy-vs-std-copy.md
Normal file
@@ -0,0 +1,27 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-benchmarks/memcpy-vs-std-copy/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# memcpy 与 std::copy 性能对比
|
||||
|
||||
最近在做性能优化时,发现有一些代码用了std::copy,还有一些用了memcpy,两者在功能上其实类似,那么它们对性能影响是怎样的呢?
|
||||
|
||||
于是本篇文章将会探讨这两者的一些使用场景。
|
||||
|
||||
## memcpy:理论上有一些性能优势
|
||||
|
||||
从理论上讲,`memcpy`可能具有轻微的性能优势,原因在于其不同于`std::copy`的要求。`memcpy`在处理数据拷贝时可以忽略数据重叠的可能性,而`std::copy`需要处理一些不同的情况(底层memmove)。然而,这种性能差异在实际应用中往往难以察觉,特别是对于小规模的数据拷贝操作。
|
||||
|
||||
值得注意的是,`memcpy`只能用于处理C风格的POD结构,因此在处理非POD类型时并不是一个可行的选择。
|
||||
|
||||
这里使用quick-bench做了一个测评,可以看到性能并无太大差别。
|
||||
|
||||
> https://quick-bench.com/q/QER6YyI5f33kmqNqV7_Zdw8P5AE
|
||||
|
||||

|
||||
|
||||
## 如何选择?
|
||||
|
||||
在实际项目中,如何选择`memcpy`还是`std::copy`取决于具体的需求。如果处理的是POD类型,而且希望保持灵活性,那么选择`std::copy`是更为明智的选择。对于大多数应用场景,`std::copy`提供了更通用、更安全的数据拷贝方式。
|
||||
|
||||
然而,在追求极致性能的情况下,可以考虑使用`memcpy`,尤其是在处理大规模数据时。但在做出选择时,务必结合实际应用场景,并借助性能分析工具进行详细测试和优化。
|
||||
|
||||
总的来说,`memcpy`和`std::copy`都有各自的优势和劣势,我们需要根据项目的具体要求,在性能和灵活性之间做出权衡。在实践中,通常选择更安全和通用的`std::copy`是一个更可靠的选择。
|
||||
121
site_extras/cpp-benchmarks-polymorphism-crtp-variant-virtual.md
Normal file
121
site_extras/cpp-benchmarks-polymorphism-crtp-variant-virtual.md
Normal file
@@ -0,0 +1,121 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-benchmarks/polymorphism-crtp-variant-virtual/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 多态:虚函数、CRTP 与 variant
|
||||
|
||||
## C++多态性能测试:CRTP vs std::variant vs virtual
|
||||
|
||||
多态是面向对象编程的一个重要概念,它使得单一接口能够代表不同的类型。C++提供了几种实现多态性的方式,本文将会讨论三种场景的多态:
|
||||
|
||||
1. **虚函数**:在C++中实现多态性的传统方式是使用虚函数。这涉及使用基类和派生类来实现特定的实现。
|
||||
2. **std::variant**:在C++17中引入的std::variant,它实现了一种无需继承的多态性。
|
||||
3. **CRTP(Curiously Recurring Template Pattern)**:CRTP是一种比较特殊的技术,它通过模板的奇特递归模式实现多态性。
|
||||
|
||||
测试的组合场景如下:
|
||||
|
||||
- 单纯crtp
|
||||
- crtp + std::variant
|
||||
- virtual
|
||||
- std::variant + std::visit
|
||||
- std::variant + std::get_if
|
||||
- std::variant + std::holds_alternative
|
||||
|
||||
使用的编译器:
|
||||
|
||||
- gcc 13.2
|
||||
- clang17.0
|
||||
|
||||
完整测试代码已放置**星球**,这里贴一下关键代码
|
||||
|
||||
```cpp
|
||||
class Shape {
|
||||
public:
|
||||
virtual ~Shape() = default;
|
||||
virtual double area() const = 0;
|
||||
};
|
||||
|
||||
class Circle : public Shape
|
||||
class Rectangle : public Shape
|
||||
|
||||
|
||||
|
||||
// virtual
|
||||
static void BM_VirtualFunction(benchmark::State& state) {
|
||||
std::vector<std::unique_ptr<Shape>> shapes;
|
||||
shapes.reserve(1000);
|
||||
|
||||
for (int i = 0; i < 1000; ++i) {
|
||||
if (i % 2 == 0) {
|
||||
shapes.emplace_back(std::make_unique<Circle>(5.0));
|
||||
} else {
|
||||
shapes.emplace_back(std::make_unique<Rectangle>(4.0, 6.0));
|
||||
}
|
||||
}
|
||||
|
||||
for (auto _ : state) {
|
||||
double totalArea = 0.0;
|
||||
for (const auto& shape : shapes) {
|
||||
totalArea += shape->area();
|
||||
}
|
||||
benchmark::DoNotOptimize(totalArea);
|
||||
}
|
||||
}
|
||||
BENCHMARK(BM_VirtualFunction);
|
||||
|
||||
static void BM_VariantVisit(benchmark::State& state) {
|
||||
std::vector<std::variant<Circle, Rectangle>> shapes;
|
||||
shapes.reserve(1000);
|
||||
|
||||
for (int i = 0; i < 1000; ++i) {
|
||||
if (i % 2 == 0) {
|
||||
shapes.emplace_back(Circle(5.0));
|
||||
} else {
|
||||
shapes.emplace_back(Rectangle(4.0, 6.0));
|
||||
}
|
||||
}
|
||||
|
||||
for (auto _ : state) {
|
||||
double totalArea = 0.0;
|
||||
for (const auto& s : shapes) {
|
||||
totalArea += std::visit([](const auto& shape) { return shape.area(); }, s);
|
||||
}
|
||||
benchmark::DoNotOptimize(totalArea);
|
||||
}
|
||||
}
|
||||
static void BM_CRTPVariant(benchmark::State& state) {
|
||||
std::vector<ShapeVariant> shapes;
|
||||
shapes.reserve(1000);
|
||||
|
||||
for (int i = 0; i < 1000; ++i) {
|
||||
if (i % 2 == 0) {
|
||||
shapes.emplace_back(crtp_light::Circle(5.0));
|
||||
} else {
|
||||
shapes.emplace_back(crtp_light::Rectangle(4.0, 6.0));
|
||||
}
|
||||
}
|
||||
|
||||
for (auto _ : state) {
|
||||
double totalArea = 0.0;
|
||||
for (const auto& s : shapes) {
|
||||
totalArea += std::visit([](const auto& shape) { return shape.area(); }, s);
|
||||
}
|
||||
benchmark::DoNotOptimize(totalArea);
|
||||
}
|
||||
}
|
||||
BENCHMARK(BM_CRTPVariant);
|
||||
|
||||
// ...
|
||||
```
|
||||
|
||||
测试结果1:gcc编译,可以看到virtual与std::variant性能差别不大,但是与crtp差别非常大。
|
||||
|
||||

|
||||
|
||||
测试结果2:clang编译,总体趋势类似gcc编译,只有crtp + std::variant性能明显回退,这个可能也是由于这里用了std::visit导致。
|
||||
|
||||

|
||||
|
||||
在A Tour of C++书中提到:
|
||||
|
||||
> This is basically equivalent to a virtual function call, but potentially faster. As with all claims of performance, this ‘‘potentially faster’’ should be verified by measurements when performance is critical. For most uses, the difference in performance is insignificant.
|
||||
|
||||
与本次测试基本符合。
|
||||
97
site_extras/cpp-concurrency-cpp-deadlock-debugging.md
Normal file
97
site_extras/cpp-concurrency-cpp-deadlock-debugging.md
Normal file
@@ -0,0 +1,97 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/cpp-deadlock-debugging/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 死锁排查
|
||||
|
||||
## C++如何排查并发编程死锁问题?
|
||||
|
||||
最近在Apache arrow里面写一个支持并行的算子:nested loop join,然后既然涉及到并行,这里就会遇到大家常说的死锁问题,假设你碰到了死锁问题,如何调试与定位呢?
|
||||
|
||||
那这便是本篇目标,帮助你快速掌握并发编程:死锁检测与死锁调试问题,非常的干,好了进行正文。
|
||||
|
||||
## 1.引入
|
||||
|
||||
为了更好的讲解死锁,我们用一个程序来引入。
|
||||
|
||||
```cpp
|
||||
std::mutex gMutex;
|
||||
|
||||
int t2() {
|
||||
std::lock_guard<std::mutex> m(gMutex);
|
||||
return 0;
|
||||
}
|
||||
|
||||
int t1() {
|
||||
std::lock_guard<std::mutex> l(gMutex);
|
||||
return t2();
|
||||
}
|
||||
```
|
||||
|
||||
相信看这个程序,大家都会觉得有问题,死锁了!问题出在`t1()`函数和`t2()`函数中都对全局的互斥锁`gMutex`进行了加锁操作,但是`t1()`函数在加锁后调用了`t2()`函数,而`t2()`函数内部又试图再次对`gMutex`进行加锁。
|
||||
|
||||
t1锁已经加上了,但还没释放,t2又去加锁,两个人都在等待谁先释放,进入了死循环,实际在项目中代码并不会如这里这么简单,非常的复杂,例如:我在Apache arrow中写的代码是这样:
|
||||
|
||||
```cpp
|
||||
Status OnBuildSideFinished(size_t thread_index) {
|
||||
std::lock_guard<std::mutex> guard(probe_side_mutex_);
|
||||
// do something
|
||||
accumulate_build_ready_ = true;
|
||||
return scheduler_->StartTaskGroup(thread_index,task_group_probe_,queued_batches_to_probe_.batch_count());
|
||||
}
|
||||
```
|
||||
|
||||
你看这个代码比上面的场景就复杂多了,嵌套了至少5层堆栈,剩余代码还没贴出来,但是这两个本质都是一个死锁模型。
|
||||
|
||||
## 2.调试
|
||||
|
||||
讲解了死锁模型之后,碰到这种问题,如何定位呢?
|
||||
|
||||
这里可以采用两种办法,第一种直接运行程序,然后gdb上去。
|
||||
|
||||
例如:
|
||||
|
||||
```
|
||||
./a.out
|
||||
```
|
||||
|
||||
然后找到进程号后:
|
||||
|
||||
```
|
||||
gdb -p xxx
|
||||
```
|
||||
|
||||
此时我们可以得到及格正在等待的线程。
|
||||
|
||||
```cpp
|
||||
(gdb) info threads
|
||||
Id Target Id Frame
|
||||
* 1 Thread 0x7ffff7fe2740 (LWP 32301) "a.out" 0x00007ffff7bc8017 in pthread_join () from /lib64/libpthread.so.0
|
||||
2 Thread 0x7ffff6fd0700 (LWP 32305) "a.out" 0x00007ffff7bcd54d in __lll_lock_wait () from /lib64/libpthread.so.0
|
||||
```
|
||||
|
||||
然后去看`__lll_lock_wait`的堆栈,例如这里我看了2号线程,然后查看堆栈得到t1与t2的行号,直接可以定位到哪里出了问题,非常的直观!
|
||||
|
||||
|
||||
|
||||
除了这种方式之外,还可以直接gdb上去运行程序,此时会卡死,然后ctrl + c杀掉之后也是可以跟上面一样的内容。
|
||||
|
||||
例如:
|
||||
|
||||
```
|
||||
(gdb) r
|
||||
Starting program: /home/light/a.out
|
||||
Missing separate debuginfos, use: debuginfo-install glibc-2.17-326.el7_9.x86_64
|
||||
[Thread debugging using libthread_db enabled]
|
||||
Using host libthread_db library "/lib64/libthread_db.so.1".
|
||||
Hello World!
|
||||
[New Thread 0x7ffff6fd0700 (LWP 32305)]
|
||||
^C
|
||||
Thread 1 "a.out" received signal SIGINT, Interrupt.
|
||||
0x00007ffff7bc8017 in pthread_join () from /lib64/libpthread.so.0
|
||||
Missing separate debuginfos, use: debuginfo-install libgcc-4.8.5-44.el7.x86_64 libstdc++-4.8.5-44.el7.x86_64
|
||||
(gdb) info threads
|
||||
Id Target Id Frame
|
||||
* 1 Thread 0x7ffff7fe2740 (LWP 32301) "a.out" 0x00007ffff7bc8017 in pthread_join () from /lib64/libpthread.so.0
|
||||
2 Thread 0x7ffff6fd0700 (LWP 32305) "a.out" 0x00007ffff7bcd54d in __lll_lock_wait () from /lib64/libpthread.so.0
|
||||
```
|
||||
|
||||
好了,本节就讲这么多,感兴趣的欢迎转发这篇硬核文章!于此同时,推荐一下自己的**线程池项目**,个人用视频讲解了这个项目,同时配上docker一键部署(这一期的视频,后面打算给大家录制一下),感兴趣的联系我即可。
|
||||
174
site_extras/cpp-concurrency-cpp-simd.md
Normal file
174
site_extras/cpp-concurrency-cpp-simd.md
Normal file
@@ -0,0 +1,174 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/cpp-simd/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ SIMD 向量化
|
||||
|
||||
最近在看相关向量化的内容,看起来有点头大,借此机会,学习一下高性能SIMD编程。
|
||||
|
||||
SIMD全称single-instruction multiple-data,单指令多数据。
|
||||
|
||||
在传统的计算机架构中,CPU一次只能处理一个数据元素。但是,许多任务涉及对大量数据执行相同的操作,例如对数组中的所有元素进行加法、乘法或逻辑操作等。SIMD编程通过向CPU提供专门的指令集,使得CPU能够同时对多个数据元素执行相同的操作。
|
||||
|
||||
这种处理方式特别适合涉及向量、矩阵、图像、音频和视频等数据的计算。
|
||||
|
||||
目前比较常用的有SSE、SSE2、AVX128、AVX256、AVX512。
|
||||
|
||||
本节,将简单学习一下AVX512的一些操作,操作比较多,这里只是引入一些。
|
||||
|
||||
## 1.术语
|
||||
|
||||
首先第一个问题便是,simd编程的代码跟平时写的代码长相不大一样,各种下划线以及命名,完全看不懂,如何理解呢?
|
||||
|
||||
诸如:
|
||||
|
||||
- _mm512_set1_ps
|
||||
|
||||
Broadcast single-precision (32-bit) floating-point value a to all elements of dst.
|
||||
|
||||
- _mm512_set1_epi32
|
||||
|
||||
Broadcast 32-bit integer a to all elements of dst.
|
||||
|
||||
于是,找到了下面这个表格:
|
||||
|
||||
| Abbreviation | Full Name | C/C++ Equivalent |
|
||||
| ------------ | ------------------------------ | ---------------- |
|
||||
| ps | packed single-precision | float |
|
||||
| ph | packed half-precision | None* |
|
||||
| pd | packed double-precision | double |
|
||||
| pch | packed half-precision complex | None* |
|
||||
| pi8 | packed 8-bit integer | int8_t |
|
||||
| pi16 | packed 16-bit integer | int16_t |
|
||||
| pi32 | packed 32-bit integer | int32_t |
|
||||
| epi8 | extended packed 8-bit integer | int8_t |
|
||||
| epi16 | extended packed 16-bit integer | int16_t |
|
||||
| epi32 | extended packed 32-bit integer | int32_t |
|
||||
| epi64 | extended packed 64-bit integer | int64_t |
|
||||
| epi64x | extended packed 64-bit integer | int64_t |
|
||||
|
||||
> https://stackoverflow.com/questions/70911872/what-are-the-names-and-meanings-of-the-intrinsic-vector-element-types-like-epi6
|
||||
|
||||
再比如:
|
||||
|
||||
_mm512_mask_load_ps
|
||||
|
||||
_mm512_mask_loadu_ps
|
||||
|
||||
u表示unordered,表示加载无序,当使用 `_mm512_mask_loadu_ps` 函数加载内存中的数据时,不会执行对内存地址的任何对齐要求。而_mm512_mask_load_ps要求满足 64 字节对齐要求。
|
||||
|
||||
这样对照着学习,非常快的便可以知道每个接口的含义了。
|
||||
|
||||
相关API可以看看Interl Intrinsics Guide。
|
||||
|
||||
> https://www.intel.com/content/www/us/en/docs/intrinsics-guide/index.html
|
||||
|
||||
## 2.实际例子
|
||||
|
||||
### 2.1 求最小值
|
||||
|
||||
对于512位,我们可以存储16个32位float。
|
||||
|
||||
```cpp
|
||||
static inline rf_512 load(float* ptr) { return _mm512_loadu_ps(ptr); }
|
||||
float a[width] = {1.0, 2.0, 3.0, 22.0, 5.0, 17.0, 9.0, 8.0,
|
||||
9.0, 10.0, 11.0, 12.0, 13.0, 14.0, 15.0, 16.0};
|
||||
float b[width] = {3.3, 6.2, 5.3, 4.4, 5.5, 6.6, 7.7, 8.8,
|
||||
9.9, 10.10, 21.11, 12.12, 13.13, 14.14, 15.0, 16.16};
|
||||
rf_512 data = minimum(load(a), load(b));
|
||||
```
|
||||
|
||||
于是我们可以快速得到:
|
||||
|
||||
```cpp
|
||||
1 2 3 4.4 5 6.6 7.7 8 9 10 11 12 13 14 15 16
|
||||
```
|
||||
|
||||
## 2.2 快速打乱数据顺序
|
||||
|
||||
对于输入数据是
|
||||
|
||||
```
|
||||
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16
|
||||
```
|
||||
|
||||
我们可以快速得到:
|
||||
|
||||
```cpp
|
||||
16.16 2 14.14 13.13 5 6 7 8 9 10 11 12 13 14 15 16
|
||||
```
|
||||
|
||||
对应实现:
|
||||
|
||||
```cpp
|
||||
static inline rf_512 permutexvar(ri_512 idx, rf_512 src) {
|
||||
return _mm512_permutexvar_ps(idx, src);
|
||||
}
|
||||
/*
|
||||
raw data: 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16
|
||||
shuffle data: 16.16 2 14.14 13.13 5 6 7 8 9 10 11 12 13 14 15 16
|
||||
*/
|
||||
void print_permutexvar_mask() {
|
||||
float a[width] = {1.0, 2.0, 3.0, 4.0, 5.0, 6.0, 7.0, 8.0,
|
||||
9.0, 10.0, 11.0, 12.0, 13.0, 14.0, 15.0, 16.0};
|
||||
float b[width] = {1.1, 2.2, 3.3, 4.4, 5.5, 6.6, 7.7, 8.8,
|
||||
9.9, 10.10, 11.11, 12.12, 13.13, 14.14, 15.0, 16.16};
|
||||
mask_type mask = make_bit_mask<1, 0, 1, 1, 0>();
|
||||
int idx_array[width] = {15, 14, 13, 12, 11, 10, 9, 8, 7, 6, 5, 4, 3, 2, 1, 0};
|
||||
ri_512 idx = _mm512_loadu_si512((__m512i*)idx_array);
|
||||
rf_512 result = permutexvar_mask(load(a), mask, idx, load(b));
|
||||
float result_arr[width];
|
||||
store(result, result_arr);
|
||||
std::cout << "raw data: ";
|
||||
for (int i = 0; i < width; i++) {
|
||||
std::cout << a[i] << " ";
|
||||
}
|
||||
std::cout << std::endl;
|
||||
|
||||
std::cout << "shuffle data: ";
|
||||
for (int i = 0; i < width; i++) {
|
||||
std::cout << result_arr[i] << " ";
|
||||
}
|
||||
std::cout << std::endl;
|
||||
}
|
||||
```
|
||||
|
||||
### 2.3 旋转
|
||||
|
||||
对于一个数组:
|
||||
|
||||
```
|
||||
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16
|
||||
```
|
||||
|
||||
我们可以旋转得到:
|
||||
|
||||
```
|
||||
4 5 6 7 8 9 10 11 12 13 14 15 16 1 2 3
|
||||
```
|
||||
|
||||
or
|
||||
|
||||
```
|
||||
14 15 16 1 2 3 4 5 6 7 8 9 10 11 12 13
|
||||
```
|
||||
|
||||
也就是rotate down or rotate up。
|
||||
|
||||
在这里,我们可以这样实现:
|
||||
|
||||
```cpp
|
||||
rf_512 rotateGeneral(float* arr, int s) {
|
||||
int idx_array[width];
|
||||
for (int i = 0; i < width; i++) {
|
||||
idx_array[i] = (i + s) % width;
|
||||
}
|
||||
ri_512 idx = _mm512_loadu_si512((__m512i*)idx_array);
|
||||
rf_512 result = permutexvar(idx, load(arr));
|
||||
return result;
|
||||
}
|
||||
```
|
||||
|
||||
等等,还有其他的例子,可以发现通过使用simd,我们可以实现一些非常有趣的算法,加速对数组,批量数据的处理。
|
||||
|
||||
后面会继续学习simd,一起加油吧~
|
||||
|
||||
注:本节的完整示例已在星球更新,谢谢~
|
||||
145
site_extras/cpp-concurrency-cpp17-parallel-stl.md
Normal file
145
site_extras/cpp-concurrency-cpp17-parallel-stl.md
Normal file
@@ -0,0 +1,145 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/cpp17-parallel-stl/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++17 并行 STL
|
||||
|
||||
## 1.各个编译器支持进度
|
||||
|
||||
不同编译器对并行算法库的支持,如下:
|
||||
|
||||
> https://en.cppreference.com/w/cpp/compiler_support/17#C.2B.2B17_library_features
|
||||
|
||||
可以看到gcc9之后就支持了,clang目前支持还不完全,自己也本地测了一下确实不支持。
|
||||
|
||||

|
||||
|
||||
其支持的算法包括:
|
||||
|
||||

|
||||
|
||||
> https://en.cppreference.com/w/cpp/experimental/parallelism
|
||||
|
||||
## 2.并行算法库要求
|
||||
|
||||
gcc9以后便可以使用并行算法库了,我们可以看一下下面的gcc-9文档。
|
||||
|
||||
> https://gcc.gnu.org/gcc-9/changes.html
|
||||
|
||||
其中,提到一个非常重要的信息:**需要tbb支持**。
|
||||
|
||||

|
||||
|
||||
TBB是由英特尔(Intel)公司开发的一个用于并行编程的 C++ 库。TBB 旨在简化多核处理器上的并行软件开发,提供了一套抽象和模型,使程序员能够更容易地实现并行算法。
|
||||
|
||||
1.C++17当中使用并行算法库的前提必须得安装tbb,那如果不安装tbb会怎样呢?
|
||||
|
||||
我自己实测就是可以编译与运行,只是没有任何加速,跟原来非并行跑出来的结果是一样的。
|
||||
|
||||
2.TBB如何安装呢?
|
||||
|
||||
一个是官方的tbb,叫做oneTBB。
|
||||
|
||||
> https://github.com/oneapi-src/oneTBB
|
||||
|
||||
另一个是其他人写的tbb,叫做tbb。
|
||||
|
||||
> https://github.com/wjakob/tbb
|
||||
|
||||
区别在于添加了基于 CMake 的构建系统。
|
||||
|
||||
现在官方也是支持cmake ,所以建议去使用官方的吧。
|
||||
|
||||
编译也是非常简单:
|
||||
|
||||
```
|
||||
mkdir build && cmake ..
|
||||
make -j8
|
||||
make install
|
||||
```
|
||||
|
||||
## 3.如何使用
|
||||
|
||||
相比于传统的STL使用又有哪些改变呢?
|
||||
|
||||
**1.接口层面**
|
||||
|
||||
其实比较简单,例如 sort原来是:
|
||||
|
||||
```cpp
|
||||
std::sort(begin, end, comp);
|
||||
```
|
||||
|
||||
现在变为:
|
||||
|
||||
```
|
||||
std::sort(exe_policy, begin, end, comp);
|
||||
```
|
||||
|
||||
只需要添加执行策略(execution policy),有三个选项:
|
||||
|
||||
1. **`std::execution::seq`(顺序执行):**
|
||||
- 这是默认的执行策略,也就是说,如果你没有明确指定执行策略,算法将使用顺序执行。
|
||||
- 算法将按照顺序依次处理元素,不涉及并行处理。
|
||||
2. **`std::execution::par`(并行执行):**
|
||||
- 使用这个执行策略将启用并行执行。算法会尝试以并行的方式处理元素,充分利用多核处理器。
|
||||
3. **`std::execution::par_unseq`(并行和向量化执行):**
|
||||
- 这个执行策略允许算法在并行的同时进行向量化(vectorization),这意味着可以利用 SIMD(Single Instruction, Multiple Data)指令集进行并行向量化操作。
|
||||
- 与 `std::execution::par` 不同,`par_unseq` 在能够并行处理的同时还允许矢量化处理,从而更充分地利用硬件的并行和向量化能力。
|
||||
|
||||
**2.头文件层面**
|
||||
|
||||
必须要引入:
|
||||
|
||||
```cpp
|
||||
#include <algorithm>
|
||||
#include <execution>
|
||||
```
|
||||
|
||||
如果有tbb的操作,可以引入tbb的头文件,例如:设置线程数。
|
||||
|
||||
**3.编译层面**
|
||||
|
||||
编译时需要指定链接信息,例如:
|
||||
|
||||
```cpp
|
||||
g++ -O3 -std=c++17 -Wall -Wextra -pedantic -I/usr/local/include/tbb -L /usr/local/lib/ -o main.out main.cc -ltbb
|
||||
```
|
||||
|
||||
## 4.性能测试
|
||||
|
||||
最近在做sort相关的工作,想看看merge与sort的性能,所以写了个benchmark,逻辑如下:
|
||||
|
||||
- 串行sort vs 并行sort(par策略)
|
||||
|
||||
- 串行merge vs 并行merge(par策略)
|
||||
|
||||
数据范围:
|
||||
|
||||
```cpp
|
||||
BENCHMARK(BM_ParallelSort)->Arg(16384)->Arg(16384000)->Arg(163840000);
|
||||
```
|
||||
|
||||
下面的测试结果将采用tbb默认线程调度策略。
|
||||
|
||||
**对比组1:并行Sort/串行Sort详细数据与加速比**
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
**对比组2:并行Merge/串行Merge详细数据与加速比**
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
tbb文档:
|
||||
|
||||
> https://oneapi-src.github.io/oneTBB/index.html
|
||||
|
||||
如果要设置线程数,可以这样操作:
|
||||
|
||||
```cpp
|
||||
#include <tbb/tbb.h>
|
||||
|
||||
tbb::task_scheduler_init init(16);
|
||||
```
|
||||
54
site_extras/cpp-concurrency-false-sharing-cache-line.md
Normal file
54
site_extras/cpp-concurrency-false-sharing-cache-line.md
Normal file
@@ -0,0 +1,54 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/false-sharing-cache-line/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ False Sharing 与缓存行
|
||||
|
||||
最近看到一段代码,手动做的对齐,于是研究一下不对齐又会带来什么影响?
|
||||
|
||||
```cpp
|
||||
template <typename T>
|
||||
class AtomicWithPadding {
|
||||
private:
|
||||
static constexpr int kCacheLineSize = 64;
|
||||
uint8_t padding_before[kCacheLineSize];
|
||||
|
||||
public:
|
||||
std::atomic<T> value;
|
||||
|
||||
private:
|
||||
uint8_t padding_after[kCacheLineSize];
|
||||
};
|
||||
```
|
||||
|
||||
这里便引出了大家面试的必考点:
|
||||
|
||||
- Cache line
|
||||
|
||||
于是有下面几个面试问题,你能答上来?
|
||||
|
||||
- 什么是cache line?
|
||||
- 什么是MESI协议?
|
||||
- 什么是False sharing?
|
||||
- C++里面如何保证避免False sharing?
|
||||
- 避免False sharing可以带来什么好处?
|
||||
- 你知道C++17之后提供了哪两个变量解决这个问题?
|
||||
|
||||
于是,找了个性能测试,大概实现是:
|
||||
|
||||
- 定义4个变量,a、b、c、d,多线程进行共享
|
||||
- 另外是对这四个变量对齐,然后开n个线程去调度。
|
||||
|
||||
下面是benchmark:
|
||||
|
||||
```cpp
|
||||
------------------------------------------------------------------
|
||||
Benchmark Time CPU Iterations
|
||||
------------------------------------------------------------------
|
||||
singleThread 4.05 ms 4.04 ms 133
|
||||
directSharing/real_time 8.78 ms 0.069 ms 77
|
||||
falseSharing/real_time 8.81 ms 0.083 ms 74
|
||||
noSharing/real_time 1.16 ms 0.071 ms 578
|
||||
```
|
||||
|
||||
可以看到noSharing得到了非常好的效果!缓存命中率大大提高,当然这里用perf分析一下是更好的,可以看看L1 cache miss。
|
||||
|
||||
以上答案在知识星球已更新,欢迎一起探讨,留言区交流,谢谢~
|
||||
137
site_extras/cpp-concurrency-gdb-multi-thread-debug.md
Normal file
137
site_extras/cpp-concurrency-gdb-multi-thread-debug.md
Normal file
@@ -0,0 +1,137 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/gdb-multi-thread-debug/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# GDB 多线程 All-Stop 调试
|
||||
|
||||
当我们使用gdb调试多线程程序时,线程可以在任何时间执行,当我们想尝试调试某一个线程的时候(例如:next),会导致切换到其他线程,不符合我们在当前线程切到下一行的预期。
|
||||
|
||||
```cpp
|
||||
Thread 2 "arrow-compute-n" hit Breakpoint 1, arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5ba840, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
399 size_t thread_index = thread_indexer_();
|
||||
(gdb) n
|
||||
[Switching to Thread 0x7ffff2c08700 (LWP 29121)]
|
||||
|
||||
Thread 3 "arrow-compute-n" hit Breakpoint 1, arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5bb060, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
399 size_t thread_index = thread_indexer_();
|
||||
```
|
||||
|
||||
此时我们需要怎么做呢?
|
||||
|
||||
那便是今天要引入的调度器锁定(scheduler-locking)。GDB 无法锁步执行所有线程。由于线程调度取决于你调试目标的操作系统(而不是由 GDB 控制),因此在当前线程完成单步操作时,其他线程可能执行多个语句。此外,一般来说,当程序停止时,其他线程停在语句的中间,而不是在清晰的语句边界处停止。甚至在继续或单步执行后,你可能会发现你的程序停在另一个线程中。每当其他线程在第一个线程完成你请求的操作之前遇到断点、信号或异常时,就会发生这种情况。
|
||||
|
||||
而通过gdb提供的scheduler-locking可以帮助你锁定调度器以仅允许单个线程运行来修改 GDB 的默认行为。
|
||||
|
||||
默认情况下scheduler-locking值等于replay
|
||||
|
||||
```
|
||||
(gdb) show scheduler-locking
|
||||
Mode for locking scheduler during execution is "replay".
|
||||
```
|
||||
|
||||
在回放模式下的行为类似于on,在记录模式下或正常执行期间的行为类似于关闭。这是默认模式。
|
||||
|
||||
- on
|
||||
|
||||
例如执行`t 2`会切换到线程2上面,此时设置on会只在当前线程进行调试。
|
||||
|
||||
- off
|
||||
|
||||
与on相反,没有锁定,任何线程随时都可以运行。
|
||||
|
||||
- step
|
||||
|
||||
在单步执行时的行为类似于打开,否则类似于关闭。当你step时,除了当前线程之外的线程永远不会有机会运行,而当你使用像`continue`、`until`或`finish`这样的命令时,它们完全可以运行。
|
||||
|
||||
例如:next、step这种会在你想要的进程内进行调试,其他线程hang住;contine之类的会让所有的线程运行。
|
||||
|
||||
## 示例
|
||||
|
||||
可以看到当设置step时,continue会在线程之间切换。
|
||||
|
||||
```
|
||||
(gdb) info threads
|
||||
Id Target Id Frame
|
||||
1 Thread 0x7ffff7e88780 (LWP 31464) "arrow-compute-n" 0x00007ffff37e3de2 in pthread_cond_timedwait@@GLIBC_2.3.2 () from /lib64/libpthread.so.0
|
||||
2 Thread 0x7ffff3409700 (LWP 31494) "arrow-compute-n" arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5bb060, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
* 3 Thread 0x7ffff2c08700 (LWP 31495) "arrow-compute-n" arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5bb060, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
(gdb) c
|
||||
Continuing.
|
||||
[Switching to Thread 0x7ffff3409700 (LWP 31494)]
|
||||
|
||||
Thread 2 "arrow-compute-n" hit Breakpoint 1, arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5bb060, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
399 size_t thread_index = thread_indexer_();
|
||||
(gdb) info threads
|
||||
Id Target Id Frame
|
||||
1 Thread 0x7ffff7e88780 (LWP 31464) "arrow-compute-n" 0x00007ffff37e3de2 in pthread_cond_timedwait@@GLIBC_2.3.2 () from /lib64/libpthread.so.0
|
||||
* 2 Thread 0x7ffff3409700 (LWP 31494) "arrow-compute-n" arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5bb060, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
3 Thread 0x7ffff2c08700 (LWP 31495) "arrow-compute-n" 0x00007ffff605a372 in arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5bb060, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
```
|
||||
|
||||
然后再continue会进入到下一个断点:
|
||||
|
||||
```cpp
|
||||
(gdb) info threads
|
||||
Id Target Id Frame
|
||||
1 Thread 0x7ffff7e88780 (LWP 31464) "arrow-compute-n" 0x00007ffff37e3a35 in pthread_cond_wait@@GLIBC_2.3.2 () from /lib64/libpthread.so.0
|
||||
2 Thread 0x7ffff3409700 (LWP 31494) "arrow-compute-n" 0x00007ffff5781b50 in arrow::compute::NestedLoopJoinNode::OnBuildSideBatch(unsigned long, arrow::compute::ExecBatch)@plt ()
|
||||
from /code/arrow/cpp/build/debug/libarrow.so.200
|
||||
* 3 Thread 0x7ffff2c08700 (LWP 31495) "arrow-compute-n" 0x00007ffff5781b50 in arrow::compute::NestedLoopJoinNode::OnBuildSideBatch(unsigned long, arrow::compute::ExecBatch)@plt ()
|
||||
from /code/arrow/cpp/build/debug/libarrow.so.200
|
||||
(gdb) c
|
||||
Continuing.
|
||||
[Switching to Thread 0x7ffff3409700 (LWP 31494)]
|
||||
|
||||
Thread 2 "arrow-compute-n" hit Breakpoint 3, 0x00007ffff5781b50 in arrow::compute::NestedLoopJoinNode::OnBuildSideBatch(unsigned long, arrow::compute::ExecBatch)@plt ()
|
||||
from /code/arrow/cpp/build/debug/libarrow.so.200
|
||||
(gdb) info threads
|
||||
Id Target Id Frame
|
||||
1 Thread 0x7ffff7e88780 (LWP 31464) "arrow-compute-n" 0x00007ffff37e3a35 in pthread_cond_wait@@GLIBC_2.3.2 () from /lib64/libpthread.so.0
|
||||
* 2 Thread 0x7ffff3409700 (LWP 31494) "arrow-compute-n" 0x00007ffff5781b50 in arrow::compute::NestedLoopJoinNode::OnBuildSideBatch(unsigned long, arrow::compute::ExecBatch)@plt ()
|
||||
from /code/arrow/cpp/build/debug/libarrow.so.200
|
||||
3 Thread 0x7ffff2c08700 (LWP 31495) "arrow-compute-n" 0x00007ffff5781b56 in arrow::compute::NestedLoopJoinNode::OnBuildSideBatch(unsigned long, arrow::compute::ExecBatch)@plt ()
|
||||
from /code/arrow/cpp/build/debug/libarrow.so.200
|
||||
```
|
||||
|
||||
可以看到线程之间切换,如果是想在线程内,可以直接next,例如:
|
||||
|
||||
```cpp
|
||||
(gdb) t 2
|
||||
[Switching to thread 2 (Thread 0x7ffff3409700 (LWP 32396))]
|
||||
#0 0x00007ffff605ae0d in arrow::compute::NestedLoopJoinNode::OnBuildSideBatch (this=0x5bbf90, thread_index=1, batch=...) at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:487
|
||||
487 if (!batch.length) {
|
||||
(gdb) n
|
||||
490 std::lock_guard<std::mutex> guard(build_side_mutex_);
|
||||
(gdb) n
|
||||
491 build_accumulator_.InsertBatch(std::move(batch));
|
||||
```
|
||||
|
||||
如果是执行print操作,引起了函数调用,会停止,输出不了我们符合预期的结果。
|
||||
|
||||
```cpp
|
||||
(gdb) p batch.ToString()
|
||||
[Switching to Thread 0x7ffff2c08700 (LWP 32397)]
|
||||
|
||||
Thread 3 "arrow-compute-n" hit Breakpoint 1, arrow::compute::NestedLoopJoinNode::InputReceived (this=0x5bbf90, input=0x5ba840, batch=...)
|
||||
at /code/arrow/cpp/src/arrow/compute/exec/nested_loop_node.cc:399
|
||||
399 size_t thread_index = thread_indexer_();
|
||||
The program stopped in another thread while making a function call from GDB.
|
||||
Evaluation of the expression containing the function
|
||||
(arrow::compute::ExecBatch::ToString() const) will be abandoned.
|
||||
When the function is done executing, GDB will silently stop.
|
||||
```
|
||||
|
||||
我们此时可以设置on,此时便可以进行print了!
|
||||
|
||||
```
|
||||
(gdb) set scheduler-locking on
|
||||
(gdb) p batch.ToString()
|
||||
$2 = "ExecBatch\n # Rows: 2\n 0: Array[null,4]\n 1: Array[true,false]\n"
|
||||
```
|
||||
|
||||
> https://sourceware.org/gdb/current/onlinedocs/gdb.html/All_002dStop-Mode.html
|
||||
77
site_extras/cpp-concurrency-helgrind-concurrency-check.md
Normal file
77
site_extras/cpp-concurrency-helgrind-concurrency-check.md
Normal file
@@ -0,0 +1,77 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/helgrind-concurrency-check/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# Helgrind 并发错误检测
|
||||
|
||||
## C++那些事之helgrind并发编程检测
|
||||
|
||||
通常我们在写多线程程序的时候很容易遇到两个问题:
|
||||
|
||||
- 死锁了,不知道什么原因导致
|
||||
- 数据不一致,多个线程锁用错了
|
||||
|
||||
那么有没有工具来检测这两种场景呢
|
||||
|
||||
答案是有的,我们可以使用valgrind的helgrind工具检测这两个问题,为了使本文讲解的更加丝滑,引出了几个例子。
|
||||
|
||||
**注:完整示例及修复示例已更新至星球。**
|
||||
|
||||
## 死锁
|
||||
|
||||
假设有两个线程互相持有对方的锁,此时我们可以模拟出死锁,例如:
|
||||
|
||||
```cpp
|
||||
void thread_func1() {
|
||||
std::lock_guard<std::mutex> lock1(mutex1);
|
||||
std::this_thread::sleep_for(std::chrono::milliseconds(100));
|
||||
std::lock_guard<std::mutex> lock2(mutex2);
|
||||
}
|
||||
|
||||
void thread_func2() {
|
||||
std::lock_guard<std::mutex> lock2(mutex2);
|
||||
std::this_thread::sleep_for(std::chrono::milliseconds(100));
|
||||
std::lock_guard<std::mutex> lock1(mutex1);
|
||||
}
|
||||
```
|
||||
|
||||
helgrind使用的方法如下:
|
||||
|
||||
```
|
||||
valgrind --tool=helgrind ./a.out
|
||||
```
|
||||
|
||||
此时我们可以看到死锁的位置,例如这个示例中指出了两个线程在对应位置发生了死锁
|
||||
|
||||
```
|
||||
thread_func2() (deadlock.cc:18)
|
||||
thread_func1() (deadlock.cc:12)
|
||||
```
|
||||
|
||||

|
||||
|
||||
## 数据竞争
|
||||
|
||||
假设有一个共享变量,我们在多线程对它增加10w次,这个结果是多少呢?
|
||||
|
||||
很明显这里产生了多线程竞争全局变量的问题,最终的结果不一致,使用helgrind检测方法同上。
|
||||
|
||||
```cpp
|
||||
int shared_var = 0;
|
||||
|
||||
void increment() {
|
||||
for (int i = 0; i < 100000; ++i) {
|
||||
++shared_var;
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
此时,我们可以看到data race的行数是哪一行,然后去解决问题。
|
||||
|
||||

|
||||
|
||||
最后,留几个问题吧:
|
||||
|
||||
1.上面这两个有问题的代码,如何修复?
|
||||
|
||||
2.除了上面工具,还有其他办法?
|
||||
|
||||
> 本节完
|
||||
265
site_extras/cpp-concurrency-libev-event-loop.md
Normal file
265
site_extras/cpp-concurrency-libev-event-loop.md
Normal file
@@ -0,0 +1,265 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/libev-event-loop/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# libev 事件循环原理
|
||||
|
||||
大纲
|
||||
|
||||
[TOC]
|
||||
|
||||
`libev` 是一个跨平台的高效事件通知库,主要用于多路复用事件机制(例如 `select`、`poll`、`epoll` 等)的实现。它的设计目标是提供简单、快速的事件循环机制,特别适合需要高并发和低延迟的场景,如高性能 Web 服务器、网络代理和其他 IO 密集型应用。它的代码量非常少,并且使用在一些生产环境中,非常推荐阅读,本节来讲讲其中的实现原理与使用。
|
||||
|
||||
## 1.基本框架
|
||||
|
||||
libev 的核心是事件循环(event loop),它是应用程序与操作系统之间的接口,用于监听和分发不同类型的事件。libev 的架构非常简洁,主要包含以下几个部分:
|
||||
|
||||
### 1.1 事件句柄(ev_watcher)
|
||||
|
||||
libev 通过事件句柄(watcher)来管理和监听各种事件。每种事件类型(如 IO 事件、定时器事件等)都有一个对应的 watcher 类型。常见的事件句柄包括:
|
||||
|
||||
- **ev_io**:用于监听文件描述符的可读/可写事件。
|
||||
- **ev_timer**:用于定时器事件,支持一次性定时器和重复定时器。
|
||||
- **ev_signal**:用于捕捉信号事件(如 `SIGINT`、`SIGTERM` 等)。
|
||||
|
||||
像上面都可以称之为ev_watcher的子类:
|
||||
|
||||
```cpp
|
||||
typedef struct ev_watcher
|
||||
{
|
||||
int active;
|
||||
int pending;
|
||||
int priority;
|
||||
void *data;
|
||||
void (*cb)(struct ev_loop *loop, struct ev_watcher *w, int revents);
|
||||
} ev_watcher;
|
||||
```
|
||||
|
||||
实际使用时,会涉及到两个关键函数,例如:注册一个可读的标准输入事件
|
||||
|
||||
```cpp
|
||||
ev_io stdin_watcher;
|
||||
ev_io_init(&stdin_watcher, stdin_cb, /*STDIN_FILENO*/ 0, EV_READ);
|
||||
ev_io_start(loop, &stdin_watcher);
|
||||
```
|
||||
|
||||
ev_io_init是一个宏,最后展开就是下面代码,主要是对watcher进行初始化,例如:设置callback、fd、events等。
|
||||
|
||||
```cpp
|
||||
do
|
||||
{
|
||||
do
|
||||
{
|
||||
((ev_watcher *)(void *)((&stdin_watcher)))->active = ((ev_watcher *)(void *)((&stdin_watcher)))->pending = 0;
|
||||
((ev_watcher *)(void *)(((&stdin_watcher))))->priority = (0);
|
||||
((((&stdin_watcher)))->cb = ((stdin_cb)), memmove(&((ev_watcher *)(((&stdin_watcher))))->cb, &(((&stdin_watcher)))->cb, sizeof((((&stdin_watcher)))->cb)));
|
||||
} while (0);
|
||||
do
|
||||
{
|
||||
((&stdin_watcher))->fd = ((0));
|
||||
((&stdin_watcher))->events = ((EV_READ)) | EV__IOFDSET;
|
||||
} while (0);
|
||||
} while (0);
|
||||
```
|
||||
|
||||
ev_io_start主要是修改anfs与fdchanges数组。
|
||||
|
||||
- 对于已经active的watcher直接返回
|
||||
- 如果还不活跃,则设置active与priority
|
||||
- 使用头插法插入到anfds对应fd的链表中,并将当前watcher设置为head
|
||||
|
||||
```cpp
|
||||
wlist_add(&((loop)->anfds)[fd].head, (WL)w);
|
||||
|
||||
static __inline__ void
|
||||
wlist_add(WL *head, WL elem)
|
||||
{
|
||||
elem->next = *head;
|
||||
*head = elem;
|
||||
}
|
||||
```
|
||||
|
||||
- 将fd插入到fdchanges数组末尾
|
||||
|
||||
```cpp
|
||||
++((loop)->fdchangecnt);
|
||||
((loop)->fdchanges)[((loop)->fdchangecnt) - 1] = fd;
|
||||
```
|
||||
|
||||
- 设置标记
|
||||
|
||||
```cpp
|
||||
w->events &= ~EV__IOFDSET;
|
||||
```
|
||||
|
||||
### 1.2 IO多路复用
|
||||
|
||||
在libev中支持epoll、poll、select等,其中在loop中有2个回调函数:
|
||||
|
||||
```cpp
|
||||
void (*backend_modify)(struct ev_loop *loop, int fd, int oev, int nev);
|
||||
void (*backend_poll)(struct ev_loop *loop, ev_tstamp timeout);
|
||||
```
|
||||
|
||||
我们以epool为例,backend_modify就是epoll_modify,backend_poll就是epoll_poll。
|
||||
|
||||
epoll_modify就是大家通常使用的epoll_ctl,当事件发生变化使用EPOLL_CTL_MOD,否则使用EPOLL_CTL_ADD。
|
||||
|
||||
```cpp
|
||||
epoll_ctl (backend_fd, oev && oldmask != nev ? EPOLL_CTL_MOD : EPOLL_CTL_ADD, fd, &ev)
|
||||
```
|
||||
|
||||
epoll_poll执行逻辑如下:
|
||||
|
||||
- epoll_wait获取就绪事件列表(loop->epoll_events)
|
||||
- 对于就绪事件,执行fd_event放入loop的pendings对应优先级的数组中。
|
||||
|
||||
```cpp
|
||||
static __inline__ void
|
||||
fd_event(struct ev_loop *loop, int fd, int revents)
|
||||
{
|
||||
ANFD *anfd = ((loop)->anfds) + fd;
|
||||
if (__builtin_expect((!!(!anfd->reify)), (1)))
|
||||
fd_event_nocheck(loop, fd, revents);
|
||||
}
|
||||
|
||||
static __inline__ void
|
||||
fd_event_nocheck(struct ev_loop *loop, int fd, int revents)
|
||||
{
|
||||
ANFD *anfd = ((loop)->anfds) + fd;
|
||||
ev_io *w;
|
||||
for (w = (ev_io *)anfd->head; w; w = (ev_io *)((WL)w)->next)
|
||||
{
|
||||
int ev = w->events & revents;
|
||||
if (ev)
|
||||
ev_feed_event(loop, (W)w, ev);
|
||||
}
|
||||
}
|
||||
|
||||
// 省略部分代码
|
||||
void __attribute__((__noinline__))
|
||||
ev_feed_event(struct ev_loop *loop, void *w, int revents)
|
||||
{
|
||||
w_->pending = ++((loop)->pendingcnt)[pri];
|
||||
((loop)->pendings)[pri][w_->pending - 1].w = w_;
|
||||
((loop)->pendings)[pri][w_->pending - 1].events = revents;
|
||||
}
|
||||
```
|
||||
|
||||
### 1.3 Timer
|
||||
|
||||
Timer内部实现采用了二叉堆与四叉堆,这里之所用四叉堆,是因为四叉堆的缓存效率更高,其实现如下:
|
||||
|
||||
```cpp
|
||||
#define DHEAP 4
|
||||
#define HEAP0 (DHEAP - 1) /* index of first element in heap */
|
||||
#define HPARENT(k) ((((k) - HEAP0 - 1) / DHEAP) + HEAP0)
|
||||
#define UPHEAP_DONE(p,k) ((p) == (k))
|
||||
```
|
||||
|
||||
注意上面使用了HEAP0作为第一个元素,即offset,堆内部的实现便是upheap、downheap,比较简单就不赘述。其结构为:
|
||||
|
||||
```cpp
|
||||
typedef ev_watcher_time *WT;
|
||||
|
||||
typedef struct
|
||||
{
|
||||
ev_tstamp at;
|
||||
WT w;
|
||||
} ANHE;
|
||||
```
|
||||
|
||||
heap的排序是按照at来比较,at为定时器到期时间,堆排序则按照at的值由小到大排序。
|
||||
|
||||
### 1.4 事件循环(ev_loop)
|
||||
|
||||
通常使用如下:
|
||||
|
||||
```cpp
|
||||
struct ev_loop *loop = EV_DEFAULT;
|
||||
ev_run(loop, 0);
|
||||
```
|
||||
|
||||
EV_DEFAULT会调用ev_default_loop函数,初始化一个ev_loop结构,里面主要是通过loop_init初始化loop结构,比如:选择epoll还是poll、select。
|
||||
|
||||
最核心的点:epoll_init发生在上面loop创建时。
|
||||
|
||||
ev_run比较复杂,主要做几件事:
|
||||
|
||||
- fd_reify
|
||||
|
||||
遍历前面提到的fdchanges数组,根据fd从anfds中取出链表,遍历所有事件链表,得到所有事件,判断当前最新的事件与之前老的事件(events)是否一致,不一致调用epoll_modify(或者第一次添加事件)。
|
||||
|
||||
```cpp
|
||||
typedef struct
|
||||
{
|
||||
WL head; // 事件链表
|
||||
unsigned char events; // 前面事件
|
||||
// other
|
||||
} ANFD;
|
||||
```
|
||||
|
||||
- backend_poll
|
||||
|
||||
见前面backend_poll的实现,会获取就绪事件并把事件放入pendings数组里面,即放到对应的优先级队列的最后。
|
||||
|
||||
- timer_reify,事件未过期不做处理,过期了执行下面逻辑:
|
||||
|
||||
- 没有设置repeat的timer
|
||||
- 调用ev_timer_stop清除
|
||||
|
||||
- 设置repeat的timer
|
||||
|
||||
例如:`ev_timer_init(&timer_watcher, timer_cb, 2.0, 3.0);``
|
||||
|
||||
``ev_timer` 的 `at` 设置为当前时间加上 2 秒(即定时器将在 2 秒后触发),并且 `repeat` 设置为 3 秒,那么定时器将首先在 2 秒后触发,然后每隔 3 秒触发一次。
|
||||
|
||||
```cpp
|
||||
if (w->repeat)
|
||||
{
|
||||
// 更新下次触发时间
|
||||
((WT)(w))->at += w->repeat;
|
||||
// 过期了
|
||||
if (((WT)(w))->at < ((loop)->mn_now))
|
||||
((WT)(w))->at = ((loop)->mn_now); // 设置当前时间
|
||||
// 设置堆顶元素为前面w->at
|
||||
(((loop)->timers)[HEAP0]).at = (((loop)->timers)[HEAP0]).w->at;
|
||||
// 调整堆
|
||||
downheap(((loop)->timers), ((loop)->timercnt), HEAP0);
|
||||
}
|
||||
```
|
||||
|
||||
- Invoke_cb
|
||||
|
||||
Invoke_cb默认是ev_invoke_pending,从对应优先队列中取出事件,调用callback函数进行事件处理。
|
||||
|
||||
```cpp
|
||||
ANPENDING *p = ((loop)->pendings)[((loop)->pendingpri)] + --((loop)->pendingcnt)[((loop)->pendingpri)];
|
||||
(p->w)->cb(loop, (p->w), (p->events));
|
||||
```
|
||||
|
||||
## 2.如何使用?
|
||||
|
||||
```cpp
|
||||
git clone git@github.com:enki/libev.git
|
||||
./configure
|
||||
make && make install
|
||||
```
|
||||
|
||||
项目编译:
|
||||
|
||||
```
|
||||
gcc main.c -lev
|
||||
```
|
||||
|
||||
## 3.课后作业
|
||||
|
||||
最后,留一个课后题目,你是否可以使用libev写一个这样的例子?
|
||||
|
||||
当我们输入数据的时候,stdio事件返回ready,如果输入超时,则返回timeout,演示效果:
|
||||
|
||||
```cpp
|
||||
[light@i-7dwsk0ty libev]$ ./a.out
|
||||
timeout
|
||||
[light@i-7dwsk0ty libev]$ ./a.out
|
||||
21
|
||||
stdin ready
|
||||
```
|
||||
156
site_extras/cpp-concurrency-std-thread-internals.md
Normal file
156
site_extras/cpp-concurrency-std-thread-internals.md
Normal file
@@ -0,0 +1,156 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/std-thread-internals/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ std::thread 内核实现
|
||||
|
||||
## 深度揭秘std::thread
|
||||
|
||||
当我们在写一个lambda时,传给thread,线程创建与task调用是在何时触发?
|
||||
|
||||
```cpp
|
||||
auto t = std::thread([this] {
|
||||
// do something
|
||||
});
|
||||
```
|
||||
|
||||
这这个线程中传递了一个lambda,那么本节所要解决的问题是:这个lambda何时触发?是在构造的时候?还是在某处调用时?
|
||||
|
||||
来,让我们一起进入源码时代。
|
||||
|
||||
## 1._M_make_routine
|
||||
|
||||
本节所分析的代码分别如下:
|
||||
|
||||
1) 头文件
|
||||
|
||||
> https://github.com/gcc-mirror/gcc/blob/releases/gcc-4.9/libstdc%2B%2B-v3/include/std/thread
|
||||
|
||||
2. 实现文件
|
||||
|
||||
> https://github.com/gcc-mirror/gcc/blob/releases/gcc-4.9/libstdc%2B%2B-v3/src/c%2B%2B11/thread.cc
|
||||
|
||||
3. posix头文件
|
||||
|
||||
> https://github.com/gcc-mirror/gcc/blob/releases/gcc-4.9/libgcc/gthr-posix.h
|
||||
|
||||
上面的代码会调用下面这个构造函数:
|
||||
|
||||
```cpp
|
||||
template<typename _Callable, typename... _Args>
|
||||
explicit
|
||||
thread(_Callable&& __f, _Args&&... __args)
|
||||
{
|
||||
_M_start_thread(_M_make_routine(std::__bind_simple(
|
||||
std::forward<_Callable>(__f),
|
||||
std::forward<_Args>(__args)...)));
|
||||
}
|
||||
```
|
||||
|
||||
`__f`为我们传入的lambda,这里通过bind将lambda与参数绑定在一起,随后传给`_M_make_routine`,便构造出`_Impl`。
|
||||
|
||||
```cpp
|
||||
template<typename _Callable>
|
||||
shared_ptr<_Impl<_Callable>>
|
||||
_M_make_routine(_Callable&& __f)
|
||||
{
|
||||
// Create and allocate full data structure, not base.
|
||||
return std::make_shared<_Impl<_Callable>>(std::forward<_Callable>(__f));
|
||||
}
|
||||
```
|
||||
|
||||
而`_Impl`里面存的是刚才bind的返回结果`_M_func`。
|
||||
|
||||
```cpp
|
||||
template<typename _Callable>
|
||||
struct _Impl : public _Impl_base
|
||||
{
|
||||
_Callable _M_func;
|
||||
|
||||
_Impl(_Callable&& __f) : _M_func(std::forward<_Callable>(__f))
|
||||
{ }
|
||||
|
||||
void
|
||||
_M_run() { _M_func(); }
|
||||
};
|
||||
```
|
||||
|
||||
随后`_M_make_routine`创建好的`shared_ptr<_Impl<_Callable>>`传递给`_M_start_thread`。
|
||||
|
||||
## 2._M_start_thread
|
||||
|
||||
`_M_start_thread`会调用`__gthread_create`,在这里会传递`execute_native_thread_routine`。
|
||||
|
||||
```cpp
|
||||
void
|
||||
thread::_M_start_thread(__shared_base_type __b)
|
||||
{
|
||||
if (!__gthread_active_p())
|
||||
#if __EXCEPTIONS
|
||||
throw system_error(make_error_code(errc::operation_not_permitted),
|
||||
"Enable multithreading to use std::thread");
|
||||
#else
|
||||
__throw_system_error(int(errc::operation_not_permitted));
|
||||
#endif
|
||||
|
||||
__b->_M_this_ptr = __b;
|
||||
int __e = __gthread_create(&_M_id._M_thread,
|
||||
&execute_native_thread_routine, __b.get());
|
||||
if (__e)
|
||||
{
|
||||
__b->_M_this_ptr.reset();
|
||||
__throw_system_error(__e);
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
关键点1:`execute_native_thread_routine`
|
||||
|
||||
在下面代码中给出了几个信息:
|
||||
|
||||
第一:为何要extern "C"
|
||||
|
||||
第二:调用了`_M_run()`
|
||||
|
||||
```cpp
|
||||
extern "C"
|
||||
{
|
||||
static void*
|
||||
execute_native_thread_routine(void* __p)
|
||||
{
|
||||
thread::_Impl_base* __t = static_cast<thread::_Impl_base*>(__p);
|
||||
thread::__shared_base_type __local;
|
||||
__local.swap(__t->_M_this_ptr);
|
||||
|
||||
__try
|
||||
{
|
||||
__t->_M_run();
|
||||
}
|
||||
__catch(const __cxxabiv1::__forced_unwind&)
|
||||
{
|
||||
__throw_exception_again;
|
||||
}
|
||||
__catch(...)
|
||||
{
|
||||
std::terminate();
|
||||
}
|
||||
|
||||
return 0;
|
||||
}
|
||||
} // extern "C"
|
||||
```
|
||||
|
||||
关键点2:`__gthread_create`
|
||||
|
||||
调用了pthread_create
|
||||
|
||||
```cpp
|
||||
static inline int
|
||||
__gthread_create (__gthread_t *__threadid, void *(*__func) (void*),
|
||||
void *__args)
|
||||
{
|
||||
return __gthrw_(pthread_create) (__threadid, NULL, __func, __args);
|
||||
}
|
||||
```
|
||||
|
||||
好了,我们来梳理一下上面的流程,当我们构造std::thread时,传入了自定义的callback(lambda)执行我们的业务逻辑,std::thread构造函数会发起pthread_create的调用,同时把execute_native_thread_routine以C语言风格传递给pthread_create,在执行pthread_create会执行execute_native_thread_routine,那么里面的`_M_run()`便会执行,这便是对应我们的lambda函数调用。
|
||||
|
||||
本节对线程的调用有了更近一步的认识,你学到了吗,欢迎分享。
|
||||
742
site_extras/cpp-concurrency-std-thread-jthread-guide.md
Normal file
742
site_extras/cpp-concurrency-std-thread-jthread-guide.md
Normal file
@@ -0,0 +1,742 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-concurrency/std-thread-jthread-guide/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ std::thread 与 jthread
|
||||
|
||||
## 全面解析thread 与 jthread
|
||||
|
||||
## 1.准备工作
|
||||
|
||||
本文的内容基于gcc-13的源码进行展开,讲详细讲解C++11 std::thread的使用与内核实现、讲解如何使用pthread + thread混用,讲解C++20 jthread的用法与内核实现。
|
||||
|
||||
如果说你是一个多线程开发的小白/大神,本篇文章都非常的适合学习,既会包含基础的理论知识,还会包含丰富的实践与内核代码揭秘。
|
||||
|
||||
源码剖析版本:gcc-13
|
||||
|
||||
> https://github.com/gcc-mirror/gcc/tree/releases/gcc-13
|
||||
|
||||
大纲如下:
|
||||
|
||||
[TOC]
|
||||
|
||||
## 2.C++11的thread
|
||||
|
||||
### 2.1 基本使用
|
||||
|
||||
创建一个thread,然后传入自己的执行函数,参数等。
|
||||
|
||||
这里的result可以使用atomic 也可以使用promise。
|
||||
|
||||
基本使用中一般需要注意t.join,让主线程等待子线程,它会阻塞当前线程,直到调用 join() 的线程执行完成。
|
||||
|
||||
```cpp
|
||||
std::atomic<int> result(0);
|
||||
|
||||
void threadFunction(int a, int b) {
|
||||
result = a + b;
|
||||
std::cout << "Child thread finished its work.\n";
|
||||
}
|
||||
|
||||
int main() {
|
||||
int a = 5;
|
||||
int b = 7;
|
||||
|
||||
std::thread t(threadFunction, a, b);
|
||||
|
||||
t.join();
|
||||
std::cout << "Result computed by the child thread: " << result << std::endl;
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
如果你没有在线程上指定 join() 或 dettach() ,则会导致运行时错误,因为主/当前线程将完成其执行,而创建的其他线程仍将运行。
|
||||
|
||||
示例:去掉上面的t.join(),你的程序将会崩溃。
|
||||
|
||||
```
|
||||
Result computed by the child thread: 0
|
||||
Child thread finished its work.
|
||||
terminate called without an active exception
|
||||
[1] 52814 abort ./a.out
|
||||
```
|
||||
|
||||
### 2.2 STL实现
|
||||
|
||||
大家可以去看std_thread.h文件,来跟我一起阅读内核实现。
|
||||
|
||||
代码路径:gcc/libstdc++-v3/include/bits/std_thread.h
|
||||
|
||||
#### 2.2.1 与pthread关联
|
||||
|
||||
首先它是一个类thread,然后有一个比较重要的类型,像我的Linux系统上面这个宏是打开的,默认一般是`__gthread_t`,而这个通常是一个pthread_t。
|
||||
|
||||
```cpp
|
||||
#ifdef _GLIBCXX_HAS_GTHREADS
|
||||
using native_handle_type = __gthread_t;
|
||||
#else
|
||||
using native_handle_type = int;
|
||||
#endif
|
||||
```
|
||||
|
||||
即:
|
||||
|
||||
```
|
||||
typedef pthread_t __gthread_t;
|
||||
```
|
||||
|
||||
所以我们可以得到第一个结论:底层实现基于linux的pthread实现。
|
||||
|
||||
#### 2.2.2 内部id
|
||||
|
||||
thread类,有一个私有成员叫做`_M_id`。
|
||||
|
||||
```cpp
|
||||
private:
|
||||
id _M_id;
|
||||
```
|
||||
|
||||
其类型是哪部的一个类,再往里面深入就是native_handle_type。
|
||||
|
||||
```cpp
|
||||
class id
|
||||
{
|
||||
native_handle_type _M_thread;
|
||||
|
||||
public:
|
||||
id() noexcept : _M_thread() { }
|
||||
|
||||
explicit
|
||||
id(native_handle_type __id) : _M_thread(__id) { }
|
||||
|
||||
}
|
||||
```
|
||||
|
||||
那再结合上面的内容,可以得到:
|
||||
|
||||
```cpp
|
||||
private:
|
||||
pthread_t _M_id;
|
||||
```
|
||||
|
||||
是不是很熟悉,我们得到了第二个知识点:thread内部维护了一个id,在linux上默认是pthread_t。
|
||||
|
||||
#### 2.2.3 是否可连接
|
||||
|
||||
如果一个线程处于 "joinable" 状态,那么在它执行完成之前,程序可以调用 `join()` 函数来等待该线程的执行完成。
|
||||
|
||||
joinable判断依据是:
|
||||
|
||||
```cpp
|
||||
_M_id != id()
|
||||
```
|
||||
|
||||
基于前面的内容,我们可以推导出:
|
||||
|
||||
```cpp
|
||||
pthread_t _M_id;
|
||||
pthread_t null_thread = pthread_t();
|
||||
_M_id != null_thread;
|
||||
```
|
||||
|
||||
即:joinable判断依据是当前线程是否不等于默认的线程id(0)。
|
||||
|
||||
join方法非常的重要,我们通常需要使用它,那它的实现原理简单来说就是如下:
|
||||
|
||||
- 是否可joinable
|
||||
- 是,调用pthread_join(这里的gthread实际上会调用到pthread的接口)
|
||||
- 否或者上面join有错误,跑出异常EINVAL或者join错误。
|
||||
- 设置为不可joinable,即:设置内部的线程id为0
|
||||
|
||||
```cpp
|
||||
thread::join()
|
||||
{
|
||||
int __e = EINVAL;
|
||||
|
||||
if (_M_id != id()) // 是否可joinable
|
||||
__e = __gthread_join(_M_id._M_thread, 0);
|
||||
|
||||
if (__e)
|
||||
__throw_system_error(__e);
|
||||
|
||||
_M_id = id(); // _M_id = pthread_t(),设置为0
|
||||
}
|
||||
```
|
||||
|
||||
在join之后,如果我们再join,此时便会抛出上面EINVAL异常,即:无效参数。
|
||||
|
||||
```
|
||||
terminate called after throwing an instance of 'std::system_error'
|
||||
what(): Invalid argument
|
||||
```
|
||||
|
||||
#### 2.2.4 分离
|
||||
|
||||
跟join类似,不过相反,告诉程序你不再关心该线程的执行了,实现逻辑除了调用接口不一样,其他地方都一致,不赘述了。
|
||||
|
||||
detach重使用的是pthread_detach。
|
||||
|
||||
```cpp
|
||||
void
|
||||
thread::detach()
|
||||
{
|
||||
int __e = EINVAL;
|
||||
|
||||
if (_M_id != id())
|
||||
__e = __gthread_detach(_M_id._M_thread);
|
||||
|
||||
if (__e)
|
||||
__throw_system_error(__e);
|
||||
|
||||
_M_id = id();
|
||||
}
|
||||
```
|
||||
|
||||
#### 2.2.5 构造与析构
|
||||
|
||||
##### 2.2.5.1 构造
|
||||
|
||||
使用:
|
||||
|
||||
```
|
||||
thread t1;
|
||||
```
|
||||
|
||||
默认构造内核代码:
|
||||
|
||||
```cpp
|
||||
thread() noexcept = default;
|
||||
```
|
||||
|
||||
带参数的构造使用:
|
||||
|
||||
```cpp
|
||||
std::thread t2(threadFunction, a, b);
|
||||
```
|
||||
|
||||
带参数构造内核代码:
|
||||
|
||||
```cpp
|
||||
template <typename _Callable, typename... _Args,
|
||||
typename = _Require<__not_same<_Callable>>>
|
||||
explicit thread(_Callable &&__f, _Args &&...__args) {}
|
||||
```
|
||||
|
||||
内部实现是:
|
||||
|
||||
```cpp
|
||||
_M_start_thread(_State_ptr(new _State_impl<_Wrapper>(
|
||||
std::forward<_Callable>(__f), std::forward<_Args>(__args)...)),
|
||||
_M_thread_deps_never_run);
|
||||
```
|
||||
|
||||
可以看到核心函数是`_M_start_thread`,这里面的代码简化为:
|
||||
|
||||
```cpp
|
||||
const int err = __gthread_create(&_M_id._M_thread,
|
||||
&execute_native_thread_routine,
|
||||
state.get());
|
||||
if (err)
|
||||
__throw_system_error(err);
|
||||
```
|
||||
|
||||
而`__gthread_create`可以理解为是pthread_create,那么是不是非常的清楚了?
|
||||
|
||||
注意到这里有一个细节就是传递给pthread_create的参数重func是execute_native_thread_routine,上面转化为pthread_create为:
|
||||
|
||||
```cpp
|
||||
pthread_create (&_M_id._M_thread, NULL, &execute_native_thread_routine, state.get());
|
||||
```
|
||||
|
||||
而execute_native_thread_routine是一个extern "C" 包裹的函数,使 C++ 中的函数名称具有 C 链接。
|
||||
|
||||
所以上面构造函数逻辑非常清晰了,就是调用pthread_create初始化内部线程id,那么这里有一个疑问,**用户传递的函数与参数怎么处理呢?**
|
||||
|
||||
这就引入了State,细心的朋友注意到上面pthread_create的最后一个参数是通常的函数参数:`state.get()`,函数是execute_native_thread_routine。
|
||||
|
||||
```cpp
|
||||
static void*
|
||||
execute_native_thread_routine(void* __p)
|
||||
{
|
||||
thread::_State_ptr __t{ static_cast<thread::_State*>(__p) };
|
||||
__t->_M_run();
|
||||
return nullptr;
|
||||
}
|
||||
```
|
||||
|
||||
`_State`是一个接口,其实现是`_State_impl`,可以看到参数与函数是转发到了这里面,然后通过`_M_run`去执行用户传递的函数,执行的时候是调用`_Callable`的operator(),在前面我们知道创建的时候是带了`_Wrapper`,所以`_Callable`等于`_Wrapper`,而`__Wrapper`又是一个`_Call_wrapper`别名,会将用户的函数与参数传递进去。
|
||||
|
||||
```cpp
|
||||
using _Wrapper = _Call_wrapper<_Callable, _Args...>;
|
||||
|
||||
struct _State
|
||||
{
|
||||
virtual ~_State();
|
||||
virtual void _M_run() = 0;
|
||||
};
|
||||
using _State_ptr = unique_ptr<_State>;
|
||||
|
||||
|
||||
template <typename _Callable>
|
||||
struct _State_impl : public _State
|
||||
{
|
||||
_Callable _M_func;
|
||||
|
||||
template <typename... _Args>
|
||||
_State_impl(_Args &&...__args)
|
||||
: _M_func(std::forward<_Args>(__args)...)
|
||||
{
|
||||
}
|
||||
|
||||
void
|
||||
_M_run() { _M_func(); }
|
||||
};
|
||||
```
|
||||
|
||||
所以到这里,我们可以看一下
|
||||
|
||||
```cpp
|
||||
template <typename... _Tp>
|
||||
using _Call_wrapper = _Invoker<tuple<typename decay<_Tp>::type...>>;
|
||||
```
|
||||
|
||||
相当于将上面_Call_wrapper的所有参数去掉引用和修饰之后作为tuple传递进去,即:
|
||||
|
||||
```cpp
|
||||
_Invoker<tuple<_Callable, Arg1, Arg2, ...>
|
||||
```
|
||||
|
||||
然后最终传递给`std::__invoke`。
|
||||
|
||||
所以,假设我写了这么一行代码:
|
||||
|
||||
```cpp
|
||||
_Call_wrapper<decltype(&add), int, int> invoker(&add, 3, 4);
|
||||
```
|
||||
|
||||
它会通过invoke帮你调用add函数。
|
||||
|
||||
```cpp
|
||||
invoke(_Fn&& __f, _Args&&... __args)
|
||||
```
|
||||
|
||||
当然上面调用的是其内部的`__invoke`,两者没有什么区别,一个是对外的接口,一个是对内的。
|
||||
|
||||
经过上面的讲解,我们可以小结一下:
|
||||
|
||||
- 带参数的构造函数会创建tid,通过pthread_create
|
||||
- 传递给pthread_create的函数是一个包裹的函数,内部使用State去驱动
|
||||
- 用户通过将函数、参数传递给thread,最终调用这个函数是通过`std::__invoke`来驱动起来。
|
||||
|
||||
##### 2.2.5.2 拷贝与移动
|
||||
|
||||
thead禁止了拷贝构造、拷贝赋值,只支持移动构造与移动赋值。
|
||||
|
||||
```cpp
|
||||
thread(const thread &) = delete;
|
||||
thread &operator=(const thread &) = delete;
|
||||
```
|
||||
|
||||
移动构造
|
||||
|
||||
```cpp
|
||||
thread(thread &&__t) noexcept
|
||||
{
|
||||
swap(__t);
|
||||
}
|
||||
|
||||
void
|
||||
swap(thread &__t) noexcept
|
||||
{
|
||||
std::swap(_M_id, __t._M_id);
|
||||
}
|
||||
```
|
||||
|
||||
移动赋值
|
||||
|
||||
```cpp
|
||||
thread &operator=(thread &&__t) noexcept
|
||||
{
|
||||
if (joinable())
|
||||
std::__terminate();
|
||||
swap(__t);
|
||||
return *this;
|
||||
}
|
||||
```
|
||||
|
||||
##### 2.2.5.3 析构
|
||||
|
||||
析构的原则是你创建的线程资源得消费/释放掉,而一个线程如果是可joinable,那么它被pthread_create了,但是还没有被使用,此时会直接terminate。
|
||||
|
||||
```cpp
|
||||
~thread()
|
||||
{
|
||||
if (joinable())
|
||||
std::__terminate();
|
||||
}
|
||||
```
|
||||
|
||||
#### 2.2.6 其他成员
|
||||
|
||||
例如:获取线程内部的线程id、线程的id内部的`_M_thread`。
|
||||
|
||||
```cpp
|
||||
id
|
||||
get_id() const noexcept
|
||||
{ return _M_id; }
|
||||
|
||||
native_handle_type
|
||||
native_handle()
|
||||
{ return _M_id._M_thread; }
|
||||
```
|
||||
|
||||
#### 2.2.7 面试考点
|
||||
|
||||
**1.构造与析构**
|
||||
|
||||
所以这里有一个提问:下面代码有什么问题吗?
|
||||
|
||||
```cpp
|
||||
// test1.cc
|
||||
int main() {
|
||||
thread t1;
|
||||
}
|
||||
|
||||
// test2.cc
|
||||
int main() {
|
||||
std::thread t2(threadFunction, a, b);
|
||||
}
|
||||
```
|
||||
|
||||
其答案是:test1正常运行,test2 crash!
|
||||
|
||||
原因是:thread的默认构造函数不做任何事情,而带参数的构造函数里面会调用`__gthread_create`(即:pthread_create)创建线程,即初始化了内部的`_M_id._M_thread`,在析构的时候会判断joinable,此时的`_M_id`与id()是不相等的,即:joinable = true,直接std::__terminate()此时crash了。
|
||||
|
||||
**2.移动赋值**
|
||||
|
||||
假设现在有下面两个函数f1、f2,这两个函数可以正常运行吗?为什么?
|
||||
|
||||
```cpp
|
||||
void f1() {
|
||||
std::thread t1(tfunc);
|
||||
std::thread t2;
|
||||
t2 = std::move(t1);
|
||||
t2.join();
|
||||
}
|
||||
void f2() {
|
||||
std::thread t1(tfunc);
|
||||
std::thread t2(tfunc);
|
||||
t2 = std::move(t1);
|
||||
t2.join();
|
||||
}
|
||||
```
|
||||
|
||||
其答案是:f1正常运行,f2 crash!
|
||||
|
||||
原因是:`f1`中t2使用了默认构造函数(不做任何事情),所以`t2`本身是非joinable的,可以安全使用移动赋值。但是,`f2`的t2是可joinable的(因此构造函数中初始化了tid),而移动赋值时会判断是否joinable,如果joinable,那么直接terminate,这其实比较好理解,因为t2本身的线程被创建了,还没有消费使用,就给swap出去了,那如何修复这个问题呢?
|
||||
|
||||
其实很简单:在前面加个join即可:
|
||||
|
||||
```cpp
|
||||
t2.join(); // 新加的
|
||||
t2 = std::move(t1);
|
||||
t2.join();
|
||||
```
|
||||
|
||||
可能有些人觉得t2搞了两次join难道没问题吗,因此此时第二次的t2实际上已经是t1了,所以可以看作是:
|
||||
|
||||
```cpp
|
||||
t2.join();
|
||||
t1.join();
|
||||
```
|
||||
|
||||
|
||||
|
||||
## 3.C++20的jthread
|
||||
|
||||
自C++20之后引入了`std::jthread`,它可以自动join启动的线程,并发出中断信号。
|
||||
|
||||
### 3.1 基本使用
|
||||
|
||||
如果我们使用前面的thread,下出下面这个代码会core掉,因为在析构函数中会去判断是否joinable,此时会terminate。
|
||||
|
||||
```cpp
|
||||
std::thread t{ [] {std::cout << "hello std::thread" << std::endl; } };
|
||||
|
||||
std::cout << "t.joinable(): " << t.joinable() << std::endl;
|
||||
```
|
||||
|
||||
如果使用了C++20的jthread,便不会有这个问题,例如:
|
||||
|
||||
```cpp
|
||||
std::jthread tj{ [] {std::cout << "hello std::jthread" << std::endl; } };
|
||||
|
||||
std::cout << "tj.joinable(): " << tj.joinable() << std::endl;
|
||||
```
|
||||
|
||||
此时你会发现可以正常运行!
|
||||
|
||||
### 3.2 STL实现
|
||||
|
||||
jthread是在thread里面,其实现基于前面的thread,源码位置:gcc/libstdc++-v3/include/std/thread
|
||||
|
||||
到底有什么秘密呢?我们一起来揭秘。
|
||||
|
||||
#### 3.2.1 与thread关联
|
||||
|
||||
jthread与thread息息相关,可以说基于thread实现,其中最核心的成员就是thread类型,而内部的id与native_handle_type类型均使用了thread内部的。
|
||||
|
||||
```cpp
|
||||
using id = thread::id;
|
||||
using native_handle_type = thread::native_handle_type;
|
||||
|
||||
thread _M_thread;
|
||||
```
|
||||
|
||||
#### 3.2.2 stop_token与stop_source
|
||||
|
||||
jthread内部使用了 std::stop_token 增强控制。std::stop_token 是一种向线程执行发送停止请求的机制。 它作为请求运行,如果在线程执行中正确处理,则允许其被终止。
|
||||
|
||||
内部使用了std::stop_source成员来维护。
|
||||
|
||||
```cpp
|
||||
stop_source _M_stop_source;
|
||||
```
|
||||
|
||||
下面我们一起来看看STL的实现。
|
||||
|
||||
**1.stop_source**
|
||||
|
||||
首先stop_source内部会维护一个state,叫做:
|
||||
|
||||
```cpp
|
||||
stop_token::_Stop_state_ref _M_state;
|
||||
```
|
||||
|
||||
这个里面便是:
|
||||
|
||||
```
|
||||
_Stop_state_t* _M_ptr
|
||||
```
|
||||
|
||||
因为一个stop_source可以被不同的线程所持有,所以它可以是共享的,因此内部是通过一个引用来做的,所以你可能会在源码里面看到`_Stop_state_ref`,它来负责管理整个state的生命周期,所有权问题。其共享的实现是通过底层的`_Stop_state_t`实现,内部有两个成员非常重要:
|
||||
|
||||
```cpp
|
||||
using value_type = uint32_t;
|
||||
std::atomic<value_type> _M_owners{1};
|
||||
std::atomic<value_type> _M_value{_S_ssrc_counter_inc};
|
||||
```
|
||||
|
||||
一个是`_M_owners`,管理所有权的;`_M_value`负责管理什么时候停止。
|
||||
|
||||
我们平时用的三个接口分别是:
|
||||
|
||||
- stop_possible
|
||||
- stop_requested
|
||||
- request_stop
|
||||
|
||||
底层便会给`_M_value`设置上对应的bit
|
||||
|
||||
```cpp
|
||||
static constexpr value_type _S_stop_requested_bit = 1;
|
||||
static constexpr value_type _S_locked_bit = 2;
|
||||
static constexpr value_type _S_ssrc_counter_inc = 4;
|
||||
```
|
||||
|
||||
当用户请求停止:request_stop,此时会设置上`_S_stop_requested_bit`,如果用户调用了stop_requested,那么也是去查看内部的`_M_value`是否设置上`_S_stop_requested_bit`。
|
||||
|
||||
`_S_locked_bit`与stop_possible接口有关,如果已经发出了停止请求或者仍然存在可以发出停止请求,那么stop_possible会返回true。
|
||||
|
||||
另外一个是`_S_ssrc_counter_inc`,这个是默认值,在stop_source的构造/拷贝构造时会给value加上`_S_ssrc_counter_inc`。
|
||||
|
||||
**2.stop_token**
|
||||
|
||||
像上面讲到的`_Stop_state_ref`所有内容基本都在stop_token里面,它的内部也是维护了一个state,叫做:
|
||||
|
||||
```
|
||||
_Stop_state_ref _M_state;
|
||||
```
|
||||
|
||||
实现细节与上面一致,就不赘述了。那么它与stop_source的区别是什么呢?
|
||||
|
||||
这里引用cppreference的解释:stop_token 类提供了检查是否已为其关联的 std::stop_source 对象发出或可以发出停止请求的方法。 它本质上是相关停止状态的线程安全“视图”。
|
||||
|
||||
> https://en.cppreference.com/w/cpp/thread/stop_token
|
||||
|
||||
**3.stop_callback**
|
||||
|
||||
stop_callback与stop_token的关系是stop_callback会注册到stop_token里面,stop_token内部会维持一个双向链表结构来对callback进行删除与新增,插入callback采用的是头插法。
|
||||
|
||||
callback触发时机有两块:
|
||||
|
||||
- 在request_stop时触发
|
||||
|
||||
callback提前注册到stop_token里面,那么在执行一段时间,用户发起请求,此时会触发callback。
|
||||
|
||||
```cpp
|
||||
auto onStop = []() {
|
||||
std::cout << "Timer has stopped." << std::endl;
|
||||
};
|
||||
|
||||
// Register the onStop callback with stop_callback
|
||||
std::stop_callback callback(source.get_token(), onStop);
|
||||
// do something for example: sleep
|
||||
|
||||
// stop
|
||||
source.request_stop(); // invoke callback
|
||||
```
|
||||
|
||||
- 注册时立即触发
|
||||
|
||||
stop_token已经要求停止,此时callback在注册时会立即触发,因为线程已经执行完了,此时应该执行回调。
|
||||
|
||||
```cpp
|
||||
thread.request_stop();
|
||||
std::stop_callback callback(stopToken, []() {
|
||||
std::cout << "Callback executed" << std::endl;
|
||||
}); // invoke callback
|
||||
```
|
||||
|
||||
具体STL中的实现是`_M_register_callback`会调用`__cb->_M_run()`,此时会调用callback函数。
|
||||
|
||||
#### 3.2.3 构造与析构
|
||||
|
||||
##### 3.2.3.1 构造
|
||||
|
||||
- 默认构造
|
||||
|
||||
默认构造会初始化一个空的stopstate,内部tid不做维护,行为跟thread一致。
|
||||
|
||||
```cpp
|
||||
jthread() noexcept
|
||||
: _M_stop_source{nostopstate}
|
||||
{ }
|
||||
```
|
||||
|
||||
- 带参数构造
|
||||
|
||||
初始化`_M_thread`,它是通过`_S_create`然后调用`_S_create_pmf`创建一个thread,然后给`_M_thread`,这样内部的thread变被构造好了。
|
||||
|
||||
```cpp
|
||||
template<typename _Callable, typename... _Args,
|
||||
typename = enable_if_t<!is_same_v<remove_cvref_t<_Callable>,
|
||||
jthread>>>
|
||||
explicit
|
||||
jthread(_Callable&& __f, _Args&&... __args)
|
||||
: _M_thread{_S_create(_M_stop_source, std::forward<_Callable>(__f),
|
||||
std::forward<_Args>(__args)...)}
|
||||
{ }
|
||||
```
|
||||
|
||||
##### 3.2.3.2 拷贝与移动
|
||||
|
||||
拷贝构造与拷贝赋值被禁用掉了,行为跟thread一致!
|
||||
|
||||
```
|
||||
jthread(const jthread&) = delete;
|
||||
jthread& operator=(const jthread&) = delete;
|
||||
```
|
||||
|
||||
移动构造默认,移动赋值使用swap。
|
||||
|
||||
```cpp
|
||||
jthread(jthread&&) noexcept = default;
|
||||
|
||||
jthread&
|
||||
operator=(jthread&& __other) noexcept
|
||||
{
|
||||
std::jthread(std::move(__other)).swap(*this);
|
||||
return *this;
|
||||
}
|
||||
|
||||
void
|
||||
swap(jthread& __other) noexcept
|
||||
{
|
||||
std::swap(_M_stop_source, __other._M_stop_source);
|
||||
std::swap(_M_thread, __other._M_thread);
|
||||
}
|
||||
```
|
||||
|
||||
##### 3.2.3.3 析构
|
||||
|
||||
析构决定了jthread在一开始的行为,为何我们不用手动join,是因为在析构的时候,它会去判断是否可join,如果joinable,那么用户没有join过,析构函数帮你调用一下join,同时会在之前检查request_stop。
|
||||
|
||||
```cpp
|
||||
~jthread()
|
||||
{
|
||||
if (joinable())
|
||||
{
|
||||
request_stop();
|
||||
join();
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
##### 3.2.3.4 其他成员
|
||||
|
||||
其他成员基本上是在thread上进行操作,然后对外暴露了一个接口,例如:
|
||||
|
||||
```cpp
|
||||
[[nodiscard]] bool
|
||||
joinable() const noexcept
|
||||
{
|
||||
return _M_thread.joinable();
|
||||
}
|
||||
|
||||
join()
|
||||
{
|
||||
_M_thread.join();
|
||||
}
|
||||
|
||||
void
|
||||
detach()
|
||||
{
|
||||
_M_thread.detach();
|
||||
}
|
||||
|
||||
[[nodiscard]] id
|
||||
get_id() const noexcept
|
||||
{
|
||||
return _M_thread.get_id();
|
||||
}
|
||||
|
||||
[[nodiscard]] native_handle_type
|
||||
native_handle()
|
||||
{
|
||||
return _M_thread.native_handle();
|
||||
}
|
||||
|
||||
[[nodiscard]] static unsigned
|
||||
hardware_concurrency() noexcept
|
||||
{
|
||||
return thread::hardware_concurrency();
|
||||
}
|
||||
```
|
||||
|
||||
剩下一些是对stop_source的操作:
|
||||
|
||||
```cpp
|
||||
[[nodiscard]] stop_source
|
||||
get_stop_source() noexcept
|
||||
{
|
||||
return _M_stop_source;
|
||||
}
|
||||
|
||||
[[nodiscard]] stop_token
|
||||
get_stop_token() const noexcept
|
||||
{
|
||||
return _M_stop_source.get_token();
|
||||
}
|
||||
|
||||
bool request_stop() noexcept
|
||||
{
|
||||
return _M_stop_source.request_stop();
|
||||
}
|
||||
```
|
||||
|
||||
### 3.3 示例
|
||||
|
||||
cppreference中这个例子非常不错,在示例中用户工作函数传递了stop_source作为参数,在内部可以通过判断stop_requested(),如果停止了,我们可以做一些释放资源的操作,还是非常有用的。
|
||||
|
||||
触发的条件就是主线程执行了request_stop。
|
||||
|
||||
> https://en.cppreference.com/w/cpp/thread/stop_source
|
||||
98
site_extras/cpp-guides-cpp-string-split-methods.md
Normal file
98
site_extras/cpp-guides-cpp-string-split-methods.md
Normal file
@@ -0,0 +1,98 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-guides/cpp-string-split-methods/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 字符串六种分割方法
|
||||
|
||||
通常我们在开发的时候会对一个长字符串依据分隔符进行分割,从而得到我们想要的字符串,大家都说C++字符串分割并没有那么方便,今天来总结一下5种方法分割字符串。
|
||||
|
||||
包含了从C++11到C++20的写法,以及C风格。
|
||||
|
||||
为了方便后续文章的讲解,我们先定义一个函数原型:
|
||||
|
||||
- 参数:两个字符串,一个表示原字符串,另一个表示分隔符
|
||||
|
||||
- 返回值:字符串数组
|
||||
|
||||
注:懒人版,可以从星球获取完整代码。
|
||||
|
||||
## 1.find分割
|
||||
|
||||
第一种方法便是大家常用的先找到分割符的位置,然后划分字符串,添加到数组中,于是有了下面的代码。
|
||||
|
||||
```cpp
|
||||
nt start = 0;
|
||||
int end = s.find(delim);
|
||||
std::vector<std::string> result;
|
||||
while (end != std::string::npos) {
|
||||
result.push_back(s.substr(start, end - start));
|
||||
start = end + delim.size();
|
||||
end = s.find(delim, start);
|
||||
}
|
||||
|
||||
result.push_back(s.substr(start, end - start));
|
||||
```
|
||||
|
||||
这种办法是否还能进行优化呢?
|
||||
|
||||
答案是肯定的,为了使得代码看起来更加优雅,我们可以每次删除前面已经输出的子串,然后find逻辑一致。
|
||||
|
||||
```cpp
|
||||
while (end != std::string::npos) {
|
||||
result.push_back(s.substr(0, end));
|
||||
s.erase(0, end + delim.size());
|
||||
end = s.find(delim);
|
||||
}
|
||||
```
|
||||
|
||||
## 2.C++20 Ranges与Views分割
|
||||
|
||||
C++20中我们可以使用 `std::ranges::views::split()` 创建一个分隔符的视图,然后使用transform,将每个子视图转换为 `std::string`。
|
||||
|
||||
```cpp
|
||||
auto split_transform_view = s | std::ranges::views::split(delim) |
|
||||
std::ranges::views::transform([](auto&& str) {
|
||||
return std::string(str.begin(), str.end());
|
||||
});
|
||||
```
|
||||
|
||||
是不是很简单,可能一些人没看懂,诶关系去看之前的C++20文章吧。
|
||||
|
||||
## 3.正则分割
|
||||
|
||||
使用 `std::regex` 对象构造分隔符模式,使用`std::sregex_token_iterator` 遍历由正则表达式模式分隔的子字符串,-1表示提取不匹配的字符串,即除了分割符的字符串。
|
||||
|
||||
```cpp
|
||||
std::regex r(delim);
|
||||
return {std::sregex_token_iterator(s.begin(), s.end(), r, -1),
|
||||
std::sregex_token_iterator()};
|
||||
```
|
||||
|
||||
## 4.istringstream分割
|
||||
|
||||
getline每次只能传递一个分隔符,于是分隔之后,需要继续跳过后续的分隔符。
|
||||
|
||||
```cpp
|
||||
std::istringstream ss(s);
|
||||
while (std::getline(ss, token, *(it = delim.begin()))) {
|
||||
result.push_back(token);
|
||||
it++;
|
||||
|
||||
while (it != delim.end() && ss.peek() == *(it)) {
|
||||
it++;
|
||||
ss.get();
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## 5.C风格的strtok分割
|
||||
|
||||
使用 `strtok()` 将字符串分割成标记,然后while循环依次提取即可。
|
||||
|
||||
```cpp
|
||||
token = strtok((char*)s.c_str(), delim.c_str());
|
||||
while (token != NULL) {
|
||||
result.push_back(token);
|
||||
token = strtok(NULL, delim.c_str());
|
||||
}
|
||||
```
|
||||
|
||||
以上便是常用的几种方法,你还有其他方法吗?欢迎留言区见,本节懒人版可以从星球获取完整代码。
|
||||
148
site_extras/cpp-guides-cpython-extension-notes.md
Normal file
148
site_extras/cpp-guides-cpython-extension-notes.md
Normal file
@@ -0,0 +1,148 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-guides/cpython-extension-notes/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# CPython 扩展开发笔记
|
||||
|
||||
本篇文章将会围绕最近给Apache提的一个feature为背景,展开讲讲CPython遇到的问题,以及尝试自己从0写一个库出来,代码也已经放星球了,感兴趣的同学可以去下载学习。
|
||||
|
||||
## 0.背景
|
||||
|
||||
最近在给apache arrow提的一个feature因为C++接口的变动引发其他语言的接口变动,一些测试也跟着需要修复。
|
||||
|
||||
像PyArrow熟悉的人应该一点也不陌生,这次接口变动也需要修改这个库,因为是在一个仓库里的,不然ci过不了。而PyArrow的实现是通过CPython实现的,之前也没特别学习CPython,改出了一堆问题,其中遇到两个问题比较重要,这里记录一下。
|
||||
|
||||
**问题1:初始化函数里面不支持其他类的默认构造。**
|
||||
|
||||
示例:
|
||||
|
||||
```
|
||||
def __init__(self, mode="only_valid", filter=Expression._scalar(True)):
|
||||
pass
|
||||
```
|
||||
|
||||
报错:
|
||||
|
||||
```
|
||||
TypeError: descriptor '_scalar' for 'pyarrow._compute.Expression' objects doesn't apply to a 'bool' object
|
||||
```
|
||||
|
||||
可以看到没识别出来,实际情况是Expression._scalar(True)合法的,我们看里面的实现:
|
||||
|
||||
```python
|
||||
@staticmethod
|
||||
def _scalar(value):
|
||||
cdef:
|
||||
Scalar scalar
|
||||
|
||||
if isinstance(value, Scalar):
|
||||
scalar = value
|
||||
else:
|
||||
scalar = lib.scalar(value)
|
||||
|
||||
return Expression.wrap(CMakeScalarExpression(scalar.unwrap()))
|
||||
```
|
||||
|
||||
可以看到,里面支持正常的bool类型,我怀疑这是cpython的限制,于是改为下面这种方式就可以了:
|
||||
|
||||
```python
|
||||
def __init__(self, mode="only_valid", filter=None):
|
||||
if filter is None:
|
||||
filter = Expression._scalar(True)
|
||||
```
|
||||
|
||||
**问题2:定义顺序**
|
||||
|
||||
当我使用后面创建的`_true`,每次传递进去的默认值是空,这个比较好理解,因为最后编译好了会翻译为一个`xxx.cpp`文件,根据C++规则前面读到的自然就是空了。
|
||||
|
||||
```python
|
||||
def __init__(self, mode="only_valid", filter=_true):
|
||||
pass
|
||||
|
||||
|
||||
cdef CExpression _true = CMakeScalarExpression(
|
||||
<shared_ptr[CScalar]> make_shared[CBooleanScalar](True)
|
||||
)
|
||||
```
|
||||
|
||||
好了,基于以上背景,我自己也想写一个例子出来,例如:使用C++写一个类,封装sort和sum,然后使用Python调用。
|
||||
|
||||
## 1.CPython完整例子
|
||||
|
||||
1. 创建一个.h文件
|
||||
|
||||
```cpp
|
||||
void sort(std::vector<int>& nums) {
|
||||
std::sort(nums.begin(), nums.end());
|
||||
}
|
||||
int sum(std::vector<int>& nums) {
|
||||
int sum = 0;
|
||||
for (int num : nums) {
|
||||
sum += num;
|
||||
}
|
||||
return sum;
|
||||
}
|
||||
```
|
||||
|
||||
2) 创建foo.pyx
|
||||
|
||||
重要点:上面vector需要:
|
||||
|
||||
```
|
||||
from libcpp.vector cimport vector
|
||||
```
|
||||
|
||||
然后去定义一个class,调用C++的接口。
|
||||
|
||||
```
|
||||
cdef class PyFoo:
|
||||
cdef Foo* f
|
||||
|
||||
def __cinit__(self):
|
||||
self.f = new Foo()
|
||||
|
||||
def __dealloc__(self):
|
||||
del self.f
|
||||
|
||||
def sort(self, nums):
|
||||
cdef vector[int] c_nums = nums
|
||||
self.f.sort(c_nums)
|
||||
|
||||
def sum(self, nums):
|
||||
cdef vector[int] c_nums = nums
|
||||
return self.f.sum(c_nums)
|
||||
```
|
||||
|
||||
3. 创建setup.py文件
|
||||
|
||||
```python
|
||||
ext = Extension('Foo', sources=["foo.pyx"], language="c++", include_dirs=[numpy.get_include()])
|
||||
|
||||
setup(name="Foo", ext_modules = cythonize([ext]))
|
||||
```
|
||||
|
||||
4. 运行
|
||||
|
||||
```
|
||||
python3 setup.py build_ext --inplace
|
||||
```
|
||||
|
||||
最后,可以写一个测试脚本去使用自己写的python接口。
|
||||
|
||||
```python
|
||||
import Foo
|
||||
|
||||
f = Foo.PyFoo()
|
||||
nums = [3, 1, 4, 1, 5, 9, 2, 6, 5, 3, 5]
|
||||
f.sort(nums)
|
||||
print("Sorted nums:", nums)
|
||||
print("Sum of nums:", f.sum(nums))
|
||||
```
|
||||
|
||||
CPython在一些项目中使用挺多的,学习起来吧~
|
||||
|
||||
运行:
|
||||
|
||||
```
|
||||
➜ cpython_examples python3 test.py
|
||||
Sorted nums: [3, 1, 4, 1, 5, 9, 2, 6, 5, 3, 5]
|
||||
Sum of nums: 44
|
||||
```
|
||||
271
site_extras/cpp-guides-curl-cpp-notes.md
Normal file
271
site_extras/cpp-guides-curl-cpp-notes.md
Normal file
@@ -0,0 +1,271 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-guides/curl-cpp-notes/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# libcurl C++ 开发备忘
|
||||
|
||||
代码风格统一有助于团队协作与代码review,业界用的比较多的是google的风格,本节来点不一样的,看看咱们平时用的比较多的工具curl团队的代码规范是什么样子的。
|
||||
|
||||
curl简单说一下,它在命令行或脚本中传输数据非常有用,大家也肯定用过,其源码实现可以在github上查看
|
||||
|
||||
> https://github.com/curl/curl
|
||||
|
||||
下面我们来从几个方面看看curl的C语言开发规范。
|
||||
|
||||
[TOC]
|
||||
|
||||
## 命名
|
||||
|
||||
新的函数和变量名称应该是逻辑的、可理解的,并且根据它们的用途进行命名。
|
||||
|
||||
文件局部函数应该被声明为静态的,建议是小写字母名称。
|
||||
|
||||
## 缩进
|
||||
|
||||
只使用空格进行缩进,不使用制表符。每个新的开放大括号使用两个空格。
|
||||
|
||||
```
|
||||
if(something_is_true) {
|
||||
while(second_statement == fine) {
|
||||
moo();
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
## 注释
|
||||
|
||||
由于编写的是 C89 代码,不允许使用 **//** 注释。它们直到 C99 标准才被引入。只使用 **/\* 注释 \*/**。
|
||||
|
||||
```
|
||||
/* 这是一个注释 */
|
||||
```
|
||||
|
||||
## 长行
|
||||
|
||||
curl 中的源代码永远不应该超过 79 列,即使在现代大屏幕和高分辨率屏幕时代,仍然有两个原因要保持这一点:
|
||||
|
||||
1. 较窄的列比较宽的列更容易阅读。有一个原因是报纸几十年甚至几个世纪来一直使用列。
|
||||
2. 较窄的列允许开发人员更容易地在不同的窗口中并排显示多个代码片段。它允许在同一个屏幕上并排显示两个或三个源代码窗口 - 以及多个终端和调试窗口。
|
||||
|
||||
## 大括号
|
||||
|
||||
在 if/while/do/for 表达式中,我们将开放大括号写在与关键字同一行,然后将闭合大括号设置在与初始关键字相同缩进级别的同一行。就像这样:
|
||||
|
||||
```
|
||||
if(age < 40) {
|
||||
/* 显然是年轻人 */
|
||||
}
|
||||
```
|
||||
|
||||
如果它们只包含一个一行语句,则可以省略大括号:
|
||||
|
||||
```
|
||||
if(!x)
|
||||
continue;
|
||||
```
|
||||
|
||||
对于函数,开放大括号应该写在单独的一行上:
|
||||
|
||||
```
|
||||
int main(int argc, char **argv)
|
||||
{
|
||||
return 1;
|
||||
}
|
||||
```
|
||||
|
||||
## 'else' 在下一行
|
||||
|
||||
在使用大括号添加 **else** 子句到条件表达式时,我们将其添加到关闭大括号后的新行。就像这样:
|
||||
|
||||
```
|
||||
if(age < 40) {
|
||||
/* 显然是年轻人 */
|
||||
}
|
||||
else {
|
||||
/* 可能是脾气暴躁的 */
|
||||
}
|
||||
```
|
||||
|
||||
## 括号前不加空格
|
||||
|
||||
在使用 if/while/do/for 表达式时,关键字与开放括号之间不应有空格。就像这样:
|
||||
|
||||
```
|
||||
while(1) {
|
||||
/* 永远循环 */
|
||||
}
|
||||
```
|
||||
|
||||
## 使用布尔条件
|
||||
|
||||
在 if/while 条件中,我们更喜欢测试条件值,如布尔值与 TRUE 或 FALSE、指针与 NULL 或 != NULL 以及整数与零或非零,而不是:
|
||||
|
||||
```
|
||||
result = do_something();
|
||||
if(!result) {
|
||||
/* 出现了问题 */
|
||||
return result;
|
||||
}
|
||||
```
|
||||
|
||||
## 条件中不要赋值
|
||||
|
||||
为了增加可读性并减少条件的复杂性,避免在 if/while 条件中进行变量赋值。不赞成这种风格:
|
||||
|
||||
```
|
||||
if((ptr = malloc(100)) == NULL)
|
||||
return NULL;
|
||||
```
|
||||
|
||||
而是鼓励更清晰地表达:
|
||||
|
||||
```
|
||||
ptr = malloc(100);
|
||||
if(!ptr)
|
||||
return NULL;
|
||||
```
|
||||
|
||||
## 新块在新行上
|
||||
|
||||
永远不会在同一行上写多个语句,即使是短的 if() 条件也不例外。
|
||||
|
||||
```
|
||||
if(a)
|
||||
return TRUE;
|
||||
else if(b)
|
||||
return FALSE;
|
||||
```
|
||||
|
||||
永远不要这样:
|
||||
|
||||
```
|
||||
if(a) return TRUE;
|
||||
else if(b) return FALSE;
|
||||
```
|
||||
|
||||
## 运算符周围加空格
|
||||
|
||||
请在 C 表达式中运算符的两侧使用空格。后缀 **(), [], ->, ., ++, --** 和一元 **+, -, !, ~, &** 操作符除外,它们不应该有空格。
|
||||
|
||||
示例:
|
||||
|
||||
```
|
||||
bla = func();
|
||||
who = name[0];
|
||||
age += 1;
|
||||
true = !false;
|
||||
size += -2 + 3 *
|
||||
|
||||
(a + b);
|
||||
ptr->member = a++;
|
||||
struct.field = b--;
|
||||
ptr = &address;
|
||||
contents = *pointer;
|
||||
complement = ~bits;
|
||||
empty = (!*string) ? TRUE : FALSE;
|
||||
```
|
||||
|
||||
## 返回值不加括号
|
||||
|
||||
在 'return' 语句中不加额外的括号:
|
||||
|
||||
```
|
||||
int works(void)
|
||||
{
|
||||
return TRUE;
|
||||
}
|
||||
```
|
||||
|
||||
## sizeof 参数加括号
|
||||
|
||||
在代码中使用 sizeof 运算符时,我们更喜欢在其参数周围加上括号:
|
||||
|
||||
```
|
||||
int size = sizeof(int);
|
||||
```
|
||||
|
||||
## 列对齐
|
||||
|
||||
一些语句不能在单行上完成,因为行太长、语句太难读,或者是由于上述其他风格指南。在这种情况下,语句跨越多行。
|
||||
|
||||
如果一个连续行是表达式或子表达式的一部分,那么你应该在适当的列上对齐,以便能够清楚地知道它是语句的哪一部分。运算符不应该起始于连续行。在其他情况下,遵循 2 个空格的缩进指南。以下是来自 libcurl 的一些示例:
|
||||
|
||||
```
|
||||
if(Curl_pipeline_wanted(handle->multi, CURLPIPE_HTTP1) &&
|
||||
(handle->set.httpversion != CURL_HTTP_VERSION_1_0) &&
|
||||
(handle->set.httpreq == HTTPREQ_GET ||
|
||||
handle->set.httpreq == HTTPREQ_HEAD))
|
||||
/* 没有要求 HTTP/1.0 并且是 GET 或 HEAD 请求 */
|
||||
return TRUE;
|
||||
```
|
||||
|
||||
如果没有括号,使用默认缩进:
|
||||
|
||||
```
|
||||
data->set.http_disable_hostname_check_before_authentication =
|
||||
(0 != va_arg(param, long)) ? TRUE : FALSE;
|
||||
```
|
||||
|
||||
函数调用时使用开放括号:
|
||||
|
||||
```
|
||||
if(option) {
|
||||
result = parse_login_details(option, strlen(option),
|
||||
(userp ? &user : NULL),
|
||||
(passwdp ? &passwd : NULL),
|
||||
NULL);
|
||||
}
|
||||
```
|
||||
|
||||
与 "current open" 括号对齐:
|
||||
|
||||
```
|
||||
DEBUGF(infof(data, "Curl_pp_readresp_ %d bytes of trailing "
|
||||
"server response left\n",
|
||||
(int)clipamount));
|
||||
```
|
||||
|
||||
## 平台相关代码
|
||||
|
||||
使用 **#ifdef HAVE_FEATURE** 进行条件代码。我们避免在 #ifdef 行中检查特定操作系统或硬件。HAVE_FEATURE 应该由 configure 脚本为类 Unix 系统生成,并且它们在其他系统的 `config-[system].h` 文件中硬编码。
|
||||
|
||||
我们还鼓励在 libcurl 构建时,使用可能为空或定义为常量的宏/函数,以使代码无缝。就像这个例子,其中 **magic()** 函数根据构建时的条件不同而工作:
|
||||
|
||||
```
|
||||
#ifdef HAVE_MAGIC
|
||||
void magic(int a)
|
||||
{
|
||||
return a + 2;
|
||||
}
|
||||
#else
|
||||
#define magic(x) 1
|
||||
#endif
|
||||
|
||||
int content = magic(3);
|
||||
```
|
||||
|
||||
## 不要 typedef 结构体
|
||||
|
||||
尽管可以使用结构体,但不要对其进行 typedef。使用 `struct name` 的方式来标识它们:
|
||||
|
||||
```
|
||||
struct something {
|
||||
void *valid;
|
||||
size_t way_to_write;
|
||||
};
|
||||
struct something instance;
|
||||
```
|
||||
|
||||
**不要这样**:
|
||||
|
||||
```
|
||||
typedef struct {
|
||||
void *wrong;
|
||||
size_t way_to_write;
|
||||
} something;
|
||||
something instance;
|
||||
```
|
||||
|
||||
本文翻译自:https://curl.se/dev/code-style.html
|
||||
|
||||
|
||||
!!! note "说明"
|
||||
本文为开发备忘,建议结合官方 libcurl 文档与具体项目错误码排查。
|
||||
100
site_extras/cpp-guides-how-to-read-open-source-cpp.md
Normal file
100
site_extras/cpp-guides-how-to-read-open-source-cpp.md
Normal file
@@ -0,0 +1,100 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-guides/how-to-read-open-source-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# 如何阅读开源 C++ 代码
|
||||
|
||||
## 如何秒懂阅读开源项目代码?
|
||||
|
||||
在实际项目或开源代码中,特别是C代码比较喜欢用宏,那么造成了一个很大问题:阅读代码非常的困难,调试也是另外一个问题,那么给你一个项目带有大量的宏,如何快速理解?
|
||||
|
||||
通常我们在面试的时候会遇到一个非常重要的知识点:gcc编译过程,大家可能对答如流,那么为了区分候选人的水平,引申出:你知道gcc哪些编译参数,各自参数有什么用?预处理阶段会发生什么?一般你会在这个阶段做些什么,对你有何帮助?
|
||||
|
||||
本节就一个开源项目为例,如何快速秒懂代码!
|
||||
|
||||
下面是一段libev的代码,其中有若干个宏,比如:
|
||||
|
||||
- EV_FREQUENT_CHECK
|
||||
- assert
|
||||
- `EV_P_`
|
||||
- ANHE_w
|
||||
- ANHE_at_cache
|
||||
|
||||
```cpp
|
||||
void noinline
|
||||
ev_timer_start (EV_P_ ev_timer *w) EV_THROW
|
||||
{
|
||||
if (expect_false (ev_is_active (w)))
|
||||
return;
|
||||
|
||||
ev_at (w) += mn_now;
|
||||
|
||||
assert (("libev: ev_timer_start called with negative timer repeat value", w->repeat >= 0.));
|
||||
|
||||
EV_FREQUENT_CHECK;
|
||||
|
||||
++timercnt;
|
||||
ev_start (EV_A_ (W)w, timercnt + HEAP0 - 1);
|
||||
array_needsize (ANHE, timers, timermax, ev_active (w) + 1, EMPTY2);
|
||||
ANHE_w (timers [ev_active (w)]) = (WT)w;
|
||||
ANHE_at_cache (timers [ev_active (w)]);
|
||||
upheap (timers, ev_active (w));
|
||||
|
||||
EV_FREQUENT_CHECK;
|
||||
|
||||
/*assert (("libev: internal timer heap corruption", timers [ev_active (w)] == (WT)w));*/
|
||||
}
|
||||
```
|
||||
|
||||
看起来是不是一愣一愣的,这段代码引出几个问题:
|
||||
|
||||
- 函数参数是几个?
|
||||
- 函数类型是?
|
||||
- 代码中ev_at是啥玩意?
|
||||
|
||||
为了秒懂代码,我们需要使用`-E`来得到预处理阶段宏展开之后的代码,方便我们理解与阅读。
|
||||
|
||||
展开之后,我们会得到:
|
||||
|
||||
```cpp
|
||||
void __attribute__ ((__noinline__))
|
||||
ev_timer_start (struct ev_loop *loop, ev_timer *w)
|
||||
{
|
||||
if (__builtin_expect ((!!((0 + ((ev_watcher *)(void *)(w))->active))),(0)))
|
||||
return;
|
||||
|
||||
((WT)(w))->at += ((loop)->mn_now);
|
||||
|
||||
|
||||
# 3881 "ev.c" 3 4
|
||||
((
|
||||
# 3881 "ev.c"
|
||||
("libev: ev_timer_start called with negative timer repeat value", w->repeat >= 0.)
|
||||
# 3881 "ev.c" 3 4
|
||||
) ? (void) (0) : __assert_fail (
|
||||
# 388libev: ev_timer_start called with negative timer repeat value\", w->repeat >= 0.)"
|
||||
# 3881 "ev.c" 3 4
|
||||
, "ev.c", 3881, __PRETTY_FUNCTION__))
|
||||
# 3881 "ev.c"
|
||||
;
|
||||
|
||||
do { } while (0);
|
||||
|
||||
++((loop)->timercnt);
|
||||
ev_start (loop, (W)w, ((loop)->timercnt) + (4 - 1) - 1);
|
||||
if (__builtin_expect ((!!((((W)(w))->active + 1) > (((loop)->timermax)))),(0))) { int __attribute__ ((__unused__)) ocur_ = (((loop)->timermax)); (((loop)->timers)) = (ANHE *)array_realloc (sizeof (ANHE), (((loop)->timers)), &(((loop)->timermax)), (((W)(w))->active + 1)); ; };
|
||||
(((loop)->timers) [((W)(w))->active]).w = (WT)w;
|
||||
(((loop)->timers) [((W)(w))->active]).at = (((loop)->timers) [((W)(w))->active]).w->at;
|
||||
upheap (((loop)->timers), ((W)(w))->active);
|
||||
|
||||
do { } while (0);
|
||||
|
||||
|
||||
}
|
||||
```
|
||||
|
||||
此时我们去理解代码,基本上没啥障碍了,但是还是不够清晰明了,为了突出你与其他候选人之间的差异,我提出几个问题:
|
||||
|
||||
- 上面显示了很多行数,可以去掉吗,怎么解决?
|
||||
- 上面assert这种系统宏非常的简单好理解,不需要我们展开它,你知道怎么做?
|
||||
- 在上面这二步展开中可能会出现问题,你知道发生了什么,如何解决?
|
||||
|
||||
好了,本节就先聊这么多,下一节继续分享,欢迎留言区探讨上面的答案!
|
||||
45
site_extras/cpp-guides-interesting-cpp-code-snippet.md
Normal file
45
site_extras/cpp-guides-interesting-cpp-code-snippet.md
Normal file
@@ -0,0 +1,45 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-guides/interesting-cpp-code-snippet/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# 一段有趣的 C++ 代码
|
||||
|
||||
## 0.导语
|
||||
|
||||
目标:如何获取参数lambda或者functor的参数个数呢?
|
||||
|
||||
本节将从模版 + `::*` + decay + decltype来实现!
|
||||
|
||||
## 1.实现
|
||||
|
||||
最终效果:
|
||||
|
||||
```cpp
|
||||
auto c1 = [](int x, double y) { return x * y; };
|
||||
std::cout << argument_count<decltype(c1)>::value << std::endl;
|
||||
MyClass f;
|
||||
std::cout << argument_count<decltype(f)>::value << std::endl;
|
||||
```
|
||||
|
||||
输出:2
|
||||
|
||||
我们思考一下这个问题,需要直到这几个点:
|
||||
|
||||
- 如何定位到functor与lambda的位置?
|
||||
- 如何获取到这个函数签名的参数数量?
|
||||
|
||||
对于第一个问题,我们可以使用`::*`便可以指向成员声明,对于functor与lambda都是`&std::decay<F>::type::operator())`。简单来说都是获取operator()这个声明的地址。
|
||||
|
||||
这里使用decay来移除cv限定符,以上述MyClass为例,到这里先通过`std::decay<F>::type`获取到MyClass类型,随后获取对应operator()的地址,然后传递给argument_count_impl。
|
||||
|
||||
```cpp
|
||||
template <typename F>
|
||||
using argument_count = decltype(argument_count_impl(&std::decay<F>::type::operator()));
|
||||
```
|
||||
|
||||
argument_count_impl的实现也比较简单,使用R (F::*)(A...)签名获取到对应的函数,这里使用了可变参数模版,`::*`,sizeof是用来获取参数数量,integral_constant则表示这个编译器常量类型为int,值为sizeof...(A)。
|
||||
|
||||
```cpp
|
||||
template <typename F, typename R, typename... A>
|
||||
static std::integral_constant<int, sizeof...(A)> argument_count_impl(R (F::*)(A...));
|
||||
```
|
||||
|
||||
基于此,便实现了获取Lambda or Functor参数个数的功能~
|
||||
148
site_extras/cpp-guides-print-1-to-100-without-loop.md
Normal file
148
site_extras/cpp-guides-print-1-to-100-without-loop.md
Normal file
@@ -0,0 +1,148 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-guides/print-1-to-100-without-loop/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 无循环打印 1-100
|
||||
|
||||
给大家设定一个条件:不使用循环,请打印出1-100个数字。
|
||||
|
||||
如果使用循环很简单了,那么你能想到多少种方法呢?
|
||||
|
||||
今天来给大家用一些C++的骚操作来写出这种代码,欢迎留言与转发~
|
||||
|
||||
这道题目其实非常简单,但却涵盖了很多面试考点,其中包括:
|
||||
|
||||
- 模版特化、便特化,如何编写递归模版
|
||||
- CRTP
|
||||
- std::copy、std::iota、std::transform如何使用,各自算法实现
|
||||
- 类静态变量
|
||||
- 等等
|
||||
|
||||
## 1.递归
|
||||
|
||||
1-100可以拆为`5*5*4`,用三个函数去打印它,函数a cout一次,然后变量加1,函数b层层嵌套a重复5次,函数c层层嵌套b重复5次,最后在main函数中对c层层嵌套4次。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
int a(int n) {
|
||||
std::cout << n++ << std::endl;
|
||||
return n;
|
||||
}
|
||||
|
||||
int b(int n) { return a(a(a(a(a(n))))); }
|
||||
|
||||
int c(int n) { return b(b(b(b(b(n))))); }
|
||||
|
||||
int main() {
|
||||
c(c(c(c(1))));
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
## 2.模版重载
|
||||
|
||||
使用模版与特化来处理,当迭代100时只输出100,否则输出I,并且+1递归处理。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
template <int I>
|
||||
struct JustPrint : public JustPrint<I + 1> {
|
||||
JustPrint() : JustPrint<I + 1>() { std::cout << I << " "; }
|
||||
};
|
||||
|
||||
template <>
|
||||
struct JustPrint<100> {
|
||||
JustPrint<100>() { std::cout << 1 << " "; }
|
||||
};
|
||||
|
||||
int main() { JustPrint<1> j; }
|
||||
```
|
||||
|
||||
## 3.CRTP
|
||||
|
||||
方式3基于方式2,将其改造为crtp编程风格,是不是有点看不懂了,嘿嘿。
|
||||
|
||||
下面struct可以被替换为class,这里我用类来描述。其实就是两个类,第一个类Print为父类,打印每次的I,并调用子类,子类PrintDerived即成Print,并将自己传递给父类,子类是一个重载类,控制递归终止。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
template <typename Derived, int I>
|
||||
struct Print {
|
||||
Print() {
|
||||
std::cout << I << " ";
|
||||
Derived::next();
|
||||
}
|
||||
};
|
||||
|
||||
template <int I>
|
||||
struct PrintDerived : public Print<PrintDerived<I>, I> {
|
||||
static void next() { PrintDerived<I + 1>(); }
|
||||
};
|
||||
template <>
|
||||
struct PrintDerived<100> : public Print<PrintDerived<100>, 100> {
|
||||
static void next() {}
|
||||
};
|
||||
|
||||
int main() {
|
||||
PrintDerived<1> j;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
## 4.类静态变量
|
||||
|
||||
创建一个Test数组,元素为100个,静态变量每次累加。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
using namespace std;
|
||||
|
||||
class Test {
|
||||
static int i;
|
||||
|
||||
public:
|
||||
Test() { cout << ++i << endl; }
|
||||
};
|
||||
int Test::i;
|
||||
int main() {
|
||||
Test a[100];
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
## 5.使用算法库
|
||||
|
||||
使用`std::for_each`简单粗暴。
|
||||
|
||||
```cpp
|
||||
int main() {
|
||||
std::vector<int> l(100);
|
||||
std::iota(l.begin(), l.end(), 1);
|
||||
std::for_each(l.begin(), l.end(), [](int& n) { std::cout << n << std::endl; });
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
## 6.C++20 ranges
|
||||
|
||||
使用C++20的std::views,在std::copy时打印。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <iterator>
|
||||
#include <ranges>
|
||||
int main() {
|
||||
auto numbers = std::views::iota(1, 100 + 1);
|
||||
std::copy(numbers.begin(), numbers.end(), std::ostream_iterator<int>(std::cout, "\n"));
|
||||
}
|
||||
```
|
||||
|
||||
这个方式继续改造,还有一种实现,使用std::transform。
|
||||
|
||||
```cpp
|
||||
auto range = std::views::transform(std::ranges::iota_view{1, 101}, [](const auto& x) {
|
||||
std::cout << x << std::endl;
|
||||
return x;
|
||||
});
|
||||
std::vector<int> a(range.begin(), range.end());
|
||||
```
|
||||
147
site_extras/cpp-idioms-avoid-default-constructor.md
Normal file
147
site_extras/cpp-idioms-avoid-default-constructor.md
Normal file
@@ -0,0 +1,147 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/avoid-default-constructor/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 避免默认构造函数
|
||||
|
||||
在 C++ 中,有一些容器通过 `resize()` 方法调整大小时,默认构造函数会被调用,这可能并不是我们想要的行为。本文将介绍如何使用自定义分配器来控制这一过程,避免默认构造的调用。
|
||||
|
||||
示例1:
|
||||
|
||||
```cpp
|
||||
// [0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
|
||||
vec.resize(5);
|
||||
vec.resize(10);
|
||||
```
|
||||
|
||||
你知道此时输出什么吗?
|
||||
|
||||
答案是:
|
||||
|
||||
```
|
||||
[0, 1, 2, 3, 4]
|
||||
[0, 1, 2, 3, 4, 0, 0, 0, 0, 0]
|
||||
```
|
||||
|
||||
这里需要明白几点内容:
|
||||
|
||||
**第一:为何resize回去之后的数据变为了0,发生了什么?**
|
||||
|
||||
**第二:如果我想要原来的数据,怎么做?即我想要输出结果是:**
|
||||
|
||||
```cpp
|
||||
[0, 1, 2, 3, 4]
|
||||
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
|
||||
```
|
||||
|
||||
**第三:如果vector的成员没有默认构造函数会发生什么?**
|
||||
|
||||
**第四:resize有什么限制?**
|
||||
|
||||
那么本节就来研究一下这个强大的功能,如何让resize避免调用默认构造。
|
||||
|
||||
注:篇幅有限,懒人版本节所有代码更新于星球。
|
||||
|
||||
## 1.resize剖析
|
||||
|
||||
为了让本文更加丝滑,我使用了下面示例,禁止Foo的构造,然后vector上面resize它。
|
||||
|
||||
```cpp
|
||||
class Foo {
|
||||
public:
|
||||
Foo() = delete;
|
||||
|
||||
private:
|
||||
int a;
|
||||
};
|
||||
|
||||
std::vector<Foo> f;
|
||||
f.resize(10);
|
||||
```
|
||||
|
||||
此时会编译错误,我们可以看到一堆报错信息。
|
||||
|
||||
第一个问题:可以看到调用栈到了`__uninitialized_default_n`,此时会去检查当前类型是否是平凡类型,这便是resize的第一个限制!
|
||||
|
||||
```cpp
|
||||
required from '_ForwardIterator std::__uninitialized_default_n(_ForwardIterator, _Size) [with _ForwardIterator = Foo*; _Size = long unsigned int]'
|
||||
710 | return __uninitialized_default_n_1<__is_trivial(_ValueType)
|
||||
| ~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~~
|
||||
711 | && __can_fill>::
|
||||
```
|
||||
|
||||
第二个问题:由于我们禁止了默认构造,那么分配器在原地址placement new 一个默认对象的时候失败了,此时便报错,这便是第二个限制!
|
||||
|
||||
```cpp
|
||||
gcc/14.1.0_1/include/c++/14/bits/stl_construct.h:119:7: error: use of deleted function 'Foo::Foo()'
|
||||
119 | ::new((void*)__p) _Tp(std::forward<_Args>(__args)...);
|
||||
| ^~~~~~~~~~~~~~~~~~~
|
||||
```
|
||||
|
||||
那么说到这里了,便可以进入正文了,可以看到resize的时候会去使用分配器去分配内存,当传递的大小大于size(此时假设在capacity内,即地址有效),那么此时会使用分配器placement new一个默认构造函数的对象。
|
||||
|
||||
gcc的源码实现可以放在这里给大家看一下,很简单吧?就是调用construct。
|
||||
|
||||
```cpp
|
||||
__try
|
||||
{
|
||||
typedef __gnu_cxx::__alloc_traits<_Allocator> __traits;
|
||||
for (; __n > 0; --__n, (void)++__cur)
|
||||
__traits::construct(__alloc, std::__addressof(*__cur));
|
||||
return __cur;
|
||||
}
|
||||
__catch(...)
|
||||
{
|
||||
std::_Destroy(__first, __cur, __alloc);
|
||||
__throw_exception_again;
|
||||
}
|
||||
```
|
||||
|
||||
好了,resize原理讲明白了,我们来讲讲一开始的问题。
|
||||
|
||||
## 2.避免调用默认构造
|
||||
|
||||
如何避免调用默认构造呢?
|
||||
|
||||
那其实很简单了,就是屏蔽调gcc默认的construct,怎么屏蔽了?
|
||||
|
||||
这里便用到了vector的第二个参数:分配器!
|
||||
|
||||
## 3.分配器
|
||||
|
||||
为了解决这个问题,我们可以使用自定义分配器。自定义分配器可以控制对象的构造行为,允许我们选择在调用 `resize` 时是否使用默认构造。以下是一个简单的自定义分配器实现,只贴了核心代码。
|
||||
|
||||
```cpp
|
||||
template <class T>
|
||||
class no_init_alloc {
|
||||
public:
|
||||
using value_type = T;
|
||||
// Override construct method to do nothing
|
||||
template <class U>
|
||||
void construct(U* p) {
|
||||
// Do nothing, memory is not initialized
|
||||
}
|
||||
};
|
||||
```
|
||||
|
||||
我们只需要在construct不做任何事情即可,此时便可以使用它,即:
|
||||
|
||||
```cpp
|
||||
std::vector<Foo, no_init_alloc<Foo>> std_vec;
|
||||
```
|
||||
|
||||
此时便可以得到:
|
||||
|
||||
```cpp
|
||||
[0, 1, 2, 3, 4]
|
||||
[0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
|
||||
```
|
||||
|
||||
而不是:
|
||||
|
||||
```
|
||||
[0, 1, 2, 3, 4]
|
||||
[0, 1, 2, 3, 4, 0, 0, 0, 0, 0]
|
||||
```
|
||||
|
||||
好了,你学会了吗?
|
||||
|
||||
> 本节完
|
||||
@@ -0,0 +1,35 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/class-template-over-function-template/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 类模板优于函数模板
|
||||
|
||||
https://stackoverflow.com/questions/5688355/partial-specialisation-of-member-function-with-non-type-parameter
|
||||
|
||||
最近看到一个很有意思的模版问题,看看大家对函数模版与类模版的基础掌握的如何,对于下面这个例子会出现什么问题?
|
||||
|
||||
你一般使用什么方法进行修复?
|
||||
|
||||
```cpp
|
||||
template <typename T, int R>
|
||||
struct foo {
|
||||
foo(const T& v) : value_(v) {}
|
||||
|
||||
void bar() {
|
||||
std::cout << "Generic" << std::endl;
|
||||
for (int i = 0; i < R; ++i) std::cout << value_ << std::endl;
|
||||
}
|
||||
|
||||
T value_;
|
||||
};
|
||||
|
||||
template <>
|
||||
void foo<float, 3>::bar() {
|
||||
std::cout << "Float" << std::endl;
|
||||
for (int i = 0; i < 3; ++i) std::cout << value_ << std::endl;
|
||||
}
|
||||
|
||||
template <int R>
|
||||
void foo<double, R>::bar() {
|
||||
std::cout << "Double" << std::endl;
|
||||
for (int i = 0; i < R; ++i) std::cout << value_ << std::endl;
|
||||
}
|
||||
```
|
||||
97
site_extras/cpp-idioms-dependency-injection-cpp.md
Normal file
97
site_extras/cpp-idioms-dependency-injection-cpp.md
Normal file
@@ -0,0 +1,97 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/dependency-injection-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 依赖注入
|
||||
|
||||
最近星球里面有个小伙伴让更新一下依赖注入,于是写出了这篇文章,来从实际的例子讲解,本文会讲解一些原理与实现,完整的实现代码懒人版放在星球中,我们开始正文。
|
||||
|
||||
大纲:
|
||||
|
||||
- 直接依赖
|
||||
- 接口依赖注入
|
||||
- 模版依赖注入
|
||||
|
||||
依赖注入是一种常用的设计模式,通常会采用接口/模版的方式提高代码的可测性与维护性,下面我们来举个例子。
|
||||
|
||||
假设有一个用户服务类UserService,需要通过HTTP客户端与远程服务器进行通信,在这种情况下我们可能会写出如下三种实现。
|
||||
|
||||
## 1.直接依赖
|
||||
|
||||
UserService内部直接依赖HttpClient,例如:
|
||||
|
||||
```cpp
|
||||
class HttpClient {
|
||||
public:
|
||||
std::string Get(const std::string& url);
|
||||
void Post(const std::string& url, const std::string& data);
|
||||
};
|
||||
|
||||
class UserService {
|
||||
private:
|
||||
HttpClient m_httpClient;
|
||||
};
|
||||
```
|
||||
|
||||
UserService内部通常会有一些方法去操作m_httpClient,这种方式简单粗暴,但是UserService与具体的HttpClient相耦合,导致难以替换依赖对象,也难以进行单元测试。
|
||||
|
||||
于是引出了后面两个方法。
|
||||
|
||||
## 2.接口依赖注入
|
||||
|
||||
我们的目标是期望测试的时候很方便的测试,而不需要创建一个具体的类,可以由用户mock出一个类去测试,那么我们可以想到接口,将HttpClient抽出来,得到:
|
||||
|
||||
```cpp
|
||||
struct IHttpClient {
|
||||
virtual std::string Get(const std::string& url) = 0;
|
||||
virtual void Post(const std::string& url, const std::string& data) = 0;
|
||||
virtual ~IHttpClient() = default;
|
||||
};
|
||||
class UserService {
|
||||
private:
|
||||
std::unique_ptr<IHttpClient> m_httpClient;
|
||||
};
|
||||
|
||||
```
|
||||
|
||||
那么在测试的时候便可以mock出一个client进行测试,例如:
|
||||
|
||||
```cc
|
||||
class MockHttpClient : public IHttpClient {
|
||||
public:
|
||||
MOCK_METHOD(std::string, Get, (const std::string& url), (override));
|
||||
MOCK_METHOD(void, Post, (const std::string& url, const std::string& data), (override));
|
||||
};
|
||||
|
||||
auto mockHttpClient = std::make_unique<MockHttpClient>();
|
||||
UserService userService(std::move(mockHttpClient));
|
||||
```
|
||||
|
||||
经过以上改造,我们可以做到:
|
||||
|
||||
- 在 .cc 文件中隐藏实现细节
|
||||
- 针对抽象接口工作
|
||||
- 在对象构造期间注入依赖项
|
||||
|
||||
## 3.模版依赖注入
|
||||
|
||||
模板依赖注入通过C++模板技术,将依赖对象作为模板参数传递给`UserService`。在实例化模板时,指定具体的HTTP客户端实现。这种方法在编译时解决依赖问题,无需虚函数调用,提高了性能。同时,也使得`UserService`类可以灵活地与不同的HTTP客户端实现进行集成,并且易于进行单元测试。
|
||||
|
||||
```cpp
|
||||
template <typename THttpClient>
|
||||
class UserService {
|
||||
private:
|
||||
THttpClient m_httpClient;
|
||||
};
|
||||
```
|
||||
|
||||
在这种情况下比较好测试,例如:
|
||||
|
||||
```cpp
|
||||
UserService<MockHttpClient> userService;
|
||||
```
|
||||
|
||||
这种方式有如下好处:
|
||||
|
||||
- 在模板实例化期间注入依赖项
|
||||
- 无需虚拟调用(注意 THttpClient 不是接口,因此可以在编译时解析调用)
|
||||
|
||||
以上便是本节要讲的所有内容,本节完整代码放于星球,欢迎订阅下载!
|
||||
11
site_extras/cpp-idioms-header-only-vs-implementation.md
Normal file
11
site_extras/cpp-idioms-header-only-vs-implementation.md
Normal file
@@ -0,0 +1,11 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/header-only-vs-implementation/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ Header-Only 与实现分离
|
||||
|
||||
最近看到一些小伙伴问到了几个比较有趣的问题,这里总结一下,这些都是实际面试中出现过的问题,看看你知道多少,考察一下底子。
|
||||
|
||||
**面试问题1:你通常编写代码的风格是什么?Header-Only?还是声明与实现分离?**
|
||||
|
||||
**面试问题2:C++里面是否所有的函数可以分离实现与声明?为什么?**
|
||||
|
||||
**面试问题3:模版的声明与实现分离有哪些方法?请举例说明各自优缺点,适用场景?**
|
||||
75
site_extras/cpp-idioms-lazy-evaluation-cpp.md
Normal file
75
site_extras/cpp-idioms-lazy-evaluation-cpp.md
Normal file
@@ -0,0 +1,75 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/lazy-evaluation-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 延迟计算惯用法
|
||||
|
||||
---
|
||||
|
||||
在软件开发中,延迟计算(**lazy evaluation or call-by-need**)是一种强大的技术,它允许我们推迟表达式的计算,直到真正需要的时候才执行。
|
||||
|
||||
这种技术在处理大规模数据集或需要动态计算的情况下特别有用。
|
||||
|
||||
### 1.什么是延迟计算?
|
||||
|
||||
延迟计算是指推迟表达式的计算,直到它们真正需要的时候才执行。这种技术的优点在于可以提高程序的效率和性能,尤其是在处理大规模数据集或需要动态计算的情况下。
|
||||
|
||||
延迟计算的实现通常通过延迟函数调用或延迟表达式求值来实现。这意味着表达式的计算被推迟到它们被使用的时候,而不是在定义它们的时候就立即执行。
|
||||
|
||||
### 2.几种实现方法
|
||||
|
||||
在 C++ 中,我们有多种方法来实现延迟计算。下面是一些常见的方法:
|
||||
|
||||
1. **Lambda 表达式**:Lambda 表达式可以用来表示一个匿名函数,可以在需要的地方进行延迟计算。
|
||||
|
||||
```cpp
|
||||
auto delayedCalculation = []() {
|
||||
std::cout << "延迟计算" << std::endl;
|
||||
return 42;
|
||||
};
|
||||
```
|
||||
|
||||
2. **std::function**:`std::function` 可以用于封装函数,使得函数的执行可以延迟到后面的某个时刻。
|
||||
|
||||
```cpp
|
||||
std::function<int()> delayedCalculation = []() {
|
||||
std::cout << "延迟计算" << std::endl;
|
||||
return 42;
|
||||
};
|
||||
```
|
||||
|
||||
3. **std::bind**:`std::bind` 可以用于绑定函数和参数,并生成一个可调用对象,延迟执行函数调用。
|
||||
|
||||
```cpp
|
||||
auto delayedCall = std::bind(delayedCalculation, 42);
|
||||
```
|
||||
|
||||
4. **函数指针**:通过指向函数的指针,可以在需要的时候调用相应的函数,实现延迟计算。
|
||||
|
||||
```cpp
|
||||
void delayedCalculation() {
|
||||
std::cout << "延迟计算" << std::endl;
|
||||
}
|
||||
|
||||
void (*funcPtr)() = &delayedCalculation;
|
||||
(*funcPtr)();
|
||||
```
|
||||
|
||||
5. **惰性求值**:惰性求值是一种延迟计算的范式,它延迟表达式的求值直到它真正需要的时候。
|
||||
|
||||
```cpp
|
||||
auto it = std::begin(vec);
|
||||
std::cout << "第一个元素:" << *it << std::endl;
|
||||
```
|
||||
|
||||
6. **生成器**:生成器是一种用于延迟生成序列的技术,允许按需生成序列中的元素,而不是一次性生成所有元素。
|
||||
|
||||
```cpp
|
||||
std::vector<int> generateSequence(int n) {
|
||||
std::vector<int> result;
|
||||
for (int i = 0; i < n; ++i) {
|
||||
result.push_back(i);
|
||||
}
|
||||
return result;
|
||||
}
|
||||
```
|
||||
|
||||
除此之外,还有哪些实现呢?欢迎与我一起探讨。
|
||||
134
site_extras/cpp-idioms-lookup-table-idiom.md
Normal file
134
site_extras/cpp-idioms-lookup-table-idiom.md
Normal file
@@ -0,0 +1,134 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/lookup-table-idiom/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 查表法惯用法
|
||||
|
||||
```cpp
|
||||
#include <benchmark/benchmark.h>
|
||||
#include <cmath>
|
||||
#include <random>
|
||||
|
||||
|
||||
const int HLL_COUNT = 16;
|
||||
|
||||
|
||||
static float harmonic_mean_table(const uint64_t* data) {
|
||||
static const float harmonic_tables[16] = {
|
||||
1.0f / static_cast<float>(1L << 0),
|
||||
1.0f / static_cast<float>(1L << 1),
|
||||
1.0f / static_cast<float>(1L << 2),
|
||||
1.0f / static_cast<float>(1L << 3),
|
||||
1.0f / static_cast<float>(1L << 4),
|
||||
1.0f / static_cast<float>(1L << 5),
|
||||
1.0f / static_cast<float>(1L << 6),
|
||||
1.0f / static_cast<float>(1L << 7),
|
||||
1.0f / static_cast<float>(1L << 8),
|
||||
1.0f / static_cast<float>(1L << 9),
|
||||
1.0f / static_cast<float>(1L << 10),
|
||||
1.0f / static_cast<float>(1L << 11),
|
||||
1.0f / static_cast<float>(1L << 12),
|
||||
1.0f / static_cast<float>(1L << 13),
|
||||
1.0f / static_cast<float>(1L << 14),
|
||||
1.0f / static_cast<float>(1L << 15),
|
||||
};
|
||||
|
||||
float harmonic_mean = 0.0f;
|
||||
for (int i = 0; i < HLL_COUNT; ++i) {
|
||||
harmonic_mean += harmonic_tables[data[i]];
|
||||
}
|
||||
|
||||
return harmonic_mean;
|
||||
}
|
||||
|
||||
static float harmonic_mean_calc(const uint64_t* data) {
|
||||
float harmonic_mean = 0.0f;
|
||||
for (int i = 0; i < HLL_COUNT; ++i) {
|
||||
harmonic_mean += powf(2.0f, -data[i]);
|
||||
}
|
||||
|
||||
return harmonic_mean;
|
||||
}
|
||||
|
||||
|
||||
uint64_t global_data[HLL_COUNT];
|
||||
|
||||
static void CustomArguments(benchmark::internal::Benchmark* b) {
|
||||
std::random_device rd;
|
||||
std::mt19937 gen(rd());
|
||||
std::uniform_int_distribution<uint64_t> dis(0, HLL_COUNT - 1);
|
||||
|
||||
for (int i = 0; i < HLL_COUNT; ++i) {
|
||||
global_data[i] = dis(gen);
|
||||
}
|
||||
}
|
||||
|
||||
static void BM_HarmonicMeanTable(benchmark::State& state) {
|
||||
for (auto _ : state) {
|
||||
benchmark::DoNotOptimize(harmonic_mean_table(global_data));
|
||||
}
|
||||
}
|
||||
BENCHMARK(BM_HarmonicMeanTable)->Apply(CustomArguments);
|
||||
|
||||
|
||||
static void BM_HarmonicMeanCalc(benchmark::State& state) {
|
||||
for (auto _ : state) {
|
||||
benchmark::DoNotOptimize(harmonic_mean_calc(global_data));
|
||||
}
|
||||
}
|
||||
BENCHMARK(BM_HarmonicMeanCalc)->Apply(CustomArguments);
|
||||
```
|
||||
|
||||
https://quick-bench.com/q/KtYyI4wutSurcnCrEezhRrH3Oks
|
||||
|
||||
> https://github.com/StarRocks/starrocks/pull/16351
|
||||
|
||||
## std::inplace_merge vs std::merge
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <vector>
|
||||
#include <algorithm>
|
||||
#include <numeric>
|
||||
#include <benchmark/benchmark.h>
|
||||
|
||||
|
||||
std::vector<int> generateTestData(int size) {
|
||||
std::vector<int> vec(size);
|
||||
|
||||
for (int i = 0; i < size / 2; ++i) {
|
||||
vec[i] = 2 * i + 1;
|
||||
}
|
||||
|
||||
for (int i = size / 2; i < size; ++i) {
|
||||
vec[i] = 2 * (i - size / 2) + 2;
|
||||
}
|
||||
|
||||
return vec;
|
||||
}
|
||||
|
||||
static void BM_Merge(benchmark::State& state) {
|
||||
state.PauseTiming();
|
||||
std::vector<int> vec = generateTestData(state.range(0) * 2);
|
||||
std::vector<int> result(state.range(0) * 2);
|
||||
state.ResumeTiming();
|
||||
for (auto _ : state) {
|
||||
std::merge(vec.begin(), vec.begin() + state.range(0), vec.begin() + state.range(0), vec.end(), result.begin());
|
||||
}
|
||||
}
|
||||
BENCHMARK(BM_Merge)->Range(8, 8 << 10);
|
||||
|
||||
static void BM_InplaceMerge(benchmark::State& state) {
|
||||
state.PauseTiming();
|
||||
std::vector<int> vec = generateTestData(state.range(0) * 2);
|
||||
std::vector<int>::iterator middle = vec.begin() + state.range(0);
|
||||
state.ResumeTiming();
|
||||
|
||||
for (auto _ : state) {
|
||||
std::inplace_merge(vec.begin(), middle, vec.end());
|
||||
}
|
||||
}
|
||||
BENCHMARK(BM_InplaceMerge)->Range(8, 8 << 10);
|
||||
```
|
||||
|
||||
https://quick-bench.com/q/u1WQpxF-KxrvW2s4mrnPkC6ZvLw
|
||||
|
||||
> https://github.com/StarRocks/starrocks/pull/14609
|
||||
101
site_extras/cpp-idioms-member-pointer-type-info.md
Normal file
101
site_extras/cpp-idioms-member-pointer-type-info.md
Normal file
@@ -0,0 +1,101 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/member-pointer-type-info/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 成员指针与类型信息
|
||||
|
||||
`::*`,估计99%的人都没用过,甚至没见过,可以留言区打出来!本节将会从0讲解语法,并使用一个项目中的实际例子来实战该用法。
|
||||
|
||||
[TOC]
|
||||
|
||||
## 1.什么是`::*`
|
||||
|
||||
`C::*` 是 C++ 中的**成员指针**语法,表示指向某个类 `C` 成员的指针。这个语法用于指向类的成员变量或成员函数。与普通指针不同,成员指针不是指向某个对象的具体内存地址,而是指向类中成员的**位置**,并且需要与类的对象实例一起使用。
|
||||
|
||||
### 1.1 语法
|
||||
|
||||
- `T C::*` 是一个指向类 `C` 中类型为 `T` 的成员变量的指针。
|
||||
- `R (C::*)(Args...)` 是一个指向类 `C` 中返回类型为 `R`,参数列表为 `Args...` 的成员函数的指针。
|
||||
|
||||
### 1.2 成员变量指针
|
||||
|
||||
成员变量指针指向某个类的成员变量,使用 `T C::*` 这种形式。
|
||||
|
||||
例如:下面示例中定义了一个成员指针 `ptr`,它指向 `MyClass` 类的 `x` 成员。`obj.*ptr` 通过成员指针访问对象的成员变量。
|
||||
|
||||
```cpp
|
||||
struct MyClass {
|
||||
int x;
|
||||
double y;
|
||||
};
|
||||
|
||||
int MyClass::*ptr = &MyClass::x;
|
||||
|
||||
MyClass obj;
|
||||
obj.x = 10;
|
||||
std::cout << "obj.x = " << obj.*ptr << std::endl;
|
||||
```
|
||||
|
||||
### 1.3 成员函数指针
|
||||
|
||||
成员函数指针指向类的成员函数,使用 `R (C::*)(Args...)` 这种形式。
|
||||
|
||||
示例:通过 `obj.*funcPtr()` 调用成员函数。
|
||||
|
||||
```cpp
|
||||
void (MyClass::*funcPtr)() const = &MyClass::print;
|
||||
MyClass obj;
|
||||
(obj.*funcPtr)();
|
||||
```
|
||||
|
||||
## 3.有什么用?
|
||||
|
||||
假设你有一个 ORM 框架,需要从成员指针中获取字段类型,生成对应列的类型,可以这样写:
|
||||
|
||||
```cpp
|
||||
struct User {
|
||||
std::string username;
|
||||
int user_id;
|
||||
};
|
||||
|
||||
// 自动生成数据库列的定义
|
||||
template <typename T, typename C>
|
||||
void generate_sql_column(T C::*member_ptr, const std::string& column_name) {
|
||||
if constexpr (std::is_same_v<T, std::string>) {
|
||||
std::cout << column_name << " VARCHAR(255)" << std::endl;
|
||||
} else if constexpr (std::is_integral_v<T>) {
|
||||
std::cout << column_name << " INT" << std::endl;
|
||||
}
|
||||
}
|
||||
|
||||
int main() {
|
||||
// 假设我们想自动为 User 类生成 SQL 表结构
|
||||
generate_sql_column(&User::username, "username");
|
||||
generate_sql_column(&User::user_id, "user_id");
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
## 4.实际项目衍生实用工具!
|
||||
|
||||
在实际项目中,我们可以使用`C::*`提取出对象与成员类型,怎么实现呢?
|
||||
|
||||
答案是:模版 + `C::*`
|
||||
|
||||
如下示例,我们便可以通过`value_type_from_member_pointer`与`class_type_from_member_pointer`来提取出对应的成员类型与类类型,非常方便的工具。
|
||||
|
||||
```cpp
|
||||
template <typename T, typename C>
|
||||
struct from_member_pointer_helper<T C::*> {
|
||||
using value_type = T;
|
||||
using class_type = C;
|
||||
};
|
||||
|
||||
template <auto Ptr>
|
||||
struct from_member_pointer : from_member_pointer_helper<typename std::remove_cvref_t<decltype(Ptr)>> {};
|
||||
|
||||
template <auto Ptr>
|
||||
using value_type_from_member_pointer = from_member_pointer<Ptr>::value_type;
|
||||
|
||||
template <auto Ptr>
|
||||
using class_type_from_member_pointer = from_member_pointer<Ptr>::class_type;
|
||||
```
|
||||
228
site_extras/cpp-idioms-mixin-idiom.md
Normal file
228
site_extras/cpp-idioms-mixin-idiom.md
Normal file
@@ -0,0 +1,228 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/mixin-idiom/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ Mixin 惯用法
|
||||
|
||||
大家好,我是光城,今天给大家分享C++那些事里面的一个惯用法:mixin
|
||||
|
||||
混合(Mixins)是Lisp中的一个概念。混合是类的一部分,意味着它旨在与其他类或混合组合在一起。
|
||||
常规独立类(例如Person)与混合的区别在于,混合模拟了一些小功能片段(例如打印或显示),并不用于独立使用。相反,它应该与需要此功能的其他类(例如Person)组合在一起。
|
||||
|
||||
因此,混合的目的是允许类似于多重继承的东西。
|
||||
|
||||
在C++汇总mixin的基本写法如下:
|
||||
|
||||
```cpp
|
||||
template <class Super>
|
||||
class Mixin : public Super {
|
||||
. /* mixin body */
|
||||
};
|
||||
```
|
||||
|
||||
或者
|
||||
|
||||
```cpp
|
||||
template<typename... Super>
|
||||
class Mixin : public Super... {
|
||||
public:
|
||||
Mixin() : Super...() {}
|
||||
// ...
|
||||
};
|
||||
```
|
||||
|
||||
**注:本节的所有示例代码可从星球获取。**
|
||||
|
||||
## 示例1:缩放与旋转
|
||||
|
||||
假设我们要对一个长方形/正方形进行缩放、旋转、添加边框等,这些操作都会影响其宽度与高度,我们可以使用mixin来实现。
|
||||
|
||||
首先,我们可以定义好正常形与长方形作为mixin的基类。
|
||||
|
||||
```cpp
|
||||
// 正方形类
|
||||
class Square : public Shape {
|
||||
public:
|
||||
Square(int sideLength) : sideLength(sideLength) {}
|
||||
int GetWidth() const override { return sideLength; }
|
||||
int GetHeight() const override { return sideLength; }
|
||||
private:
|
||||
int sideLength;
|
||||
};
|
||||
|
||||
// 长方形类
|
||||
class Rectangle : public Shape {
|
||||
public:
|
||||
Rectangle(int width, int height) : width(width), height(height) {}
|
||||
int GetWidth() const override { return width; }
|
||||
int GetHeight() const override { return height; }
|
||||
private:
|
||||
int width;
|
||||
int height;
|
||||
};
|
||||
```
|
||||
|
||||
随后使用mixin子类去拓展功能,例如:一个缩放的mixin我们可以自定义一个类,它的宽度与高度等于scale乘以对应的宽高。
|
||||
|
||||
```cpp
|
||||
// 缩放的Mixin
|
||||
template <class Base, int ScaleX, int ScaleY>
|
||||
class Scale : public Base {
|
||||
public:
|
||||
int GetScaledWidth() const { return Base::GetWidth() * ScaleX; }
|
||||
int GetScaledHeight() const { return Base::GetHeight() * ScaleY; }
|
||||
};
|
||||
|
||||
```
|
||||
|
||||
像这种场景非常适合使用mixin。
|
||||
|
||||
使用的时候:
|
||||
|
||||
```cpp
|
||||
using ModifiedShape = Border<RotateBy90<Scale<Square, 2, 1>>, 10>;
|
||||
```
|
||||
|
||||
## 示例2:redo与undo
|
||||
|
||||
完整示例模拟一个redo与undo操作,我们便可以在数据之间来回的切换。`Redoable<Undoable<Number>> `,在这里我们可以将这些类混合到一起使用了。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
using namespace std;
|
||||
|
||||
struct Number {
|
||||
typedef int value_type;
|
||||
int n;
|
||||
void set(int v) {
|
||||
n = v;
|
||||
}
|
||||
int get() const {
|
||||
return n;
|
||||
}
|
||||
};
|
||||
|
||||
template <typename BASE, typename T = typename BASE::value_type>
|
||||
struct Undoable : public BASE {
|
||||
typedef T value_type;
|
||||
T before;
|
||||
void set(T v) {
|
||||
before = BASE::get();
|
||||
BASE::set(v);
|
||||
}
|
||||
void undo() {
|
||||
BASE::set(before);
|
||||
}
|
||||
};
|
||||
|
||||
template <typename BASE, typename T = typename BASE::value_type>
|
||||
struct Redoable : public BASE {
|
||||
typedef T value_type;
|
||||
T after;
|
||||
void set(T v) {
|
||||
after = v;
|
||||
BASE::set(v);
|
||||
}
|
||||
void redo() {
|
||||
BASE::set(after);
|
||||
}
|
||||
};
|
||||
|
||||
typedef Redoable<Undoable<Number>> ReUndoableNumber;
|
||||
|
||||
int main() {
|
||||
ReUndoableNumber mynum;
|
||||
mynum.set(42);
|
||||
mynum.set(84);
|
||||
cout << mynum.get() << '\n'; // Output: 84
|
||||
mynum.undo();
|
||||
cout << mynum.get() << '\n'; // Output: 42
|
||||
mynum.redo();
|
||||
cout << mynum.get() << '\n'; // Output: back to 84
|
||||
}
|
||||
```
|
||||
|
||||
## 示例3:重复打印
|
||||
|
||||
再举一个拼积木的例子:重复打印。
|
||||
|
||||
首先,有一个类,我们可以print这个人的名字。
|
||||
|
||||
```cpp
|
||||
class Name
|
||||
{
|
||||
public:
|
||||
Name(std::string firstName, std::string lastName)
|
||||
: firstName_(std::move(firstName))
|
||||
, lastName_(std::move(lastName)) {}
|
||||
|
||||
void print() const
|
||||
{
|
||||
std::cout << lastName_ << ", " << firstName_ << '\n';
|
||||
}
|
||||
|
||||
private:
|
||||
std::string firstName_;
|
||||
std::string lastName_;
|
||||
};
|
||||
```
|
||||
|
||||
那如果我想重复打印呢?
|
||||
|
||||
我们可以这样玩,使用mixin,将Name类传递进去。
|
||||
|
||||
```cpp
|
||||
template<typename Printable>
|
||||
struct RepeatPrint : Printable
|
||||
{
|
||||
explicit RepeatPrint(Printable const& printable) : Printable(printable) {}
|
||||
void repeat(unsigned int n) const
|
||||
{
|
||||
while (n-- > 0)
|
||||
{
|
||||
this->print();
|
||||
}
|
||||
}
|
||||
};
|
||||
|
||||
template<typename Printable>
|
||||
RepeatPrint<Printable> repeatPrint(Printable const& printable)
|
||||
{
|
||||
return RepeatPrint<Printable>(printable);
|
||||
}
|
||||
```
|
||||
|
||||
使用:
|
||||
|
||||
```
|
||||
Name ned("Eddard", "Stark");
|
||||
repeatPrint(ned).repeat(10);
|
||||
```
|
||||
|
||||
此时,便得到重复n次的打印结果。
|
||||
|
||||
那么mixin比较适合什么场景呢?
|
||||
|
||||
- 保持原来的类不变,
|
||||
- 客户端代码不直接使用原始类,它需要将其包装到 mixin 中才能使用增强功能,
|
||||
|
||||
## 标准库
|
||||
|
||||
在标准库当中有一个使用mixin技术:std::nested_exception。
|
||||
|
||||
std::nested_exception 是一个多态 mixin 类,它可以捕获并存储当前异常,从而可以在彼此之间嵌套任意类型的异常。
|
||||
|
||||
```cpp
|
||||
template <typename _Except>
|
||||
struct _Nested_exception : public _Except, public nested_exception
|
||||
{}
|
||||
```
|
||||
|
||||
在源码中我们可以看到使用了nested_exception作为mixin的基类。
|
||||
|
||||
## 参考
|
||||
|
||||
> https://cedanet.com.au/ceda/Xc++/$mixin/mixins-in-straight-c++.php
|
||||
>
|
||||
> https://www.fluentcpp.com/2017/12/12/mixin-classes-yang-crtp/
|
||||
>
|
||||
> https://stackoverflow.com/questions/18773367/what-are-mixins-as-a-concept
|
||||
51
site_extras/cpp-idioms-trigraphs-cpp.md
Normal file
51
site_extras/cpp-idioms-trigraphs-cpp.md
Normal file
@@ -0,0 +1,51 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-idioms/trigraphs-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 三字母词
|
||||
|
||||
## C++那些事之删除三字母
|
||||
|
||||
C++17 之前,Trigraph 是用 ISO/IEC 646 等小字符代码编写程序的功能,在 C89 中引入。 ISO/IEC 646 缺少 C 中使用的以下字符,因此`??`请使用以下字符进行转义:
|
||||
|
||||
| 三字母内容 | 替换的内容 |
|
||||
| ---------- | ---------- |
|
||||
| `??=` | `#` |
|
||||
| `??(` | `[` |
|
||||
| `??)` | `]` |
|
||||
| `??<` | `{` |
|
||||
| `??>` | `}` |
|
||||
| `??/` | `\` |
|
||||
| `??!` | `|` |
|
||||
| `??-` | `~` |
|
||||
| `??'` | `^` |
|
||||
|
||||
`\?`它被转义以防止被三字母表替换。
|
||||
|
||||
C++17三字母被删除,`??=`等不再被替换。
|
||||
|
||||
## 示例
|
||||
|
||||
C++17之前:
|
||||
|
||||
```cpp
|
||||
std::cout << "??=" << std::endl;
|
||||
std::cout << "??(" << std::endl;
|
||||
std::cout << "?\?(" << std::endl;
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```
|
||||
#
|
||||
[
|
||||
??(
|
||||
```
|
||||
|
||||
C++17及之后:
|
||||
|
||||
```
|
||||
??=
|
||||
??(
|
||||
??(
|
||||
```
|
||||
|
||||
现在可能由于Unicode等字符编码已经普遍存在,不再需要三字母组,而gcc等编译器默认禁用三字母组。
|
||||
233
site_extras/cpp-memory-debug-address-sanitizer-asan.md
Normal file
233
site_extras/cpp-memory-debug-address-sanitizer-asan.md
Normal file
@@ -0,0 +1,233 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-memory-debug/address-sanitizer-asan/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# AddressSanitizer 内存检测
|
||||
|
||||
C和C++是非常不安全且容易出错的编程语言,Address Sanitizer是由Google开发的一种工具,用于检测内存访问错误,如使用后释放(use-after-free)和内存泄漏。它已集成到GCC版本>= 4.8中,可用于C和C++代码。Address Sanitizer使用运行时插桩来跟踪内存分配,这意味着您必须使用AddressSanitizer构建代码,以充分利用其功能。
|
||||
|
||||
- [Use after free](https://github.com/google/sanitizers/wiki/AddressSanitizerExampleUseAfterFree) (dangling pointer dereference)
|
||||
- [Heap buffer overflow](https://github.com/google/sanitizers/wiki/AddressSanitizerExampleHeapOutOfBounds)
|
||||
- [Stack buffer overflow](https://github.com/google/sanitizers/wiki/AddressSanitizerExampleStackOutOfBounds)
|
||||
- [Global buffer overflow](https://github.com/google/sanitizers/wiki/AddressSanitizerExampleGlobalOutOfBounds)
|
||||
- [Use after return](https://github.com/google/sanitizers/wiki/AddressSanitizerExampleUseAfterReturn)
|
||||
- [Use after scope](https://github.com/google/sanitizers/wiki/AddressSanitizerExampleUseAfterScope)
|
||||
- [Initialization order bugs](https://github.com/google/sanitizers/wiki/AddressSanitizerInitializationOrderFiasco)
|
||||
- [Memory leaks](https://github.com/google/sanitizers/wiki/AddressSanitizerLeakSanitizer)
|
||||
|
||||
本文将会以上面8种场景来介绍内存检测工具**AddressSanitizer**。
|
||||
|
||||
## 1.Use after free
|
||||
|
||||
以下面代码为例。首先,通过`new`关键字分配了一个整数的内存空间,并将其地址赋给指针 `ptr`。然后,使用 `delete` 关键字释放了这块内存。但是,在释放后,程序仍然尝试通过指针 `ptr` 访问已经释放的内存,并将值 10 赋给该内存位置,这就是使用后释放错误。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
int main() {
|
||||
int* ptr = new int;
|
||||
delete ptr;
|
||||
*ptr = 10; // Use after free
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
在编译时添加下面选项。
|
||||
|
||||
```
|
||||
-fsanitize=address
|
||||
```
|
||||
|
||||
运行生成的bin文件,得到如下结果。
|
||||
|
||||

|
||||
|
||||
## 2.heap buffer overflow
|
||||
|
||||
首先,通过 `new` 关键字在堆上分配了一个包含两个整数的数组,并将数组的起始地址赋给指针 `arr`。然后,程序试图将值 10 存储在数组的第三个位置(索引为 2),这超出了数组的有效范围,导致堆缓冲区溢出错误。
|
||||
|
||||
```
|
||||
#include <iostream>
|
||||
|
||||
int main() {
|
||||
int* arr = new int[2];
|
||||
arr[2] = 10; // Heap buffer overflow
|
||||
delete[] arr;
|
||||
return 0;
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
同上面用法:
|
||||
|
||||
```
|
||||
g++-13 heap_buffer_overflow.cc -Wall -g -fsanitize=address
|
||||
```
|
||||
|
||||
然后:
|
||||
|
||||
```
|
||||
./a.out
|
||||
```
|
||||
|
||||
得到下面检测结果。
|
||||
|
||||

|
||||
|
||||
## 3.stack buffer overflow
|
||||
|
||||
在 `vulnerableFunction` 函数中,定义了一个包含 8 个字符的字符数组 `buffer`。然后,使用 `std::cin` 从标准输入读取数据存储到 `buffer` 中,但没有限制输入的大小。如果输入的字符数超过了 `buffer` 的大小,就会发生栈缓冲区溢出错误。
|
||||
|
||||
```cpp
|
||||
void vulnerableFunction() {
|
||||
char buffer[8];
|
||||
std::cin >> buffer; // Stack buffer overflow
|
||||
std::cout << "You entered: " << buffer << std::endl;
|
||||
}
|
||||
```
|
||||
|
||||
用法同上。
|
||||
|
||||

|
||||
|
||||
## 4.global buffer overflow
|
||||
|
||||
全局缓冲区(`buffer` 数组)在程序的全局范围内定义,而没有受到足够的输入大小限制。如果输入的字符数超过了缓冲区的大小,就会发生全局缓冲区溢出错误。与栈缓冲区溢出类似,全局缓冲区溢出可能导致程序的不稳定性和安全性问题。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
char buffer[8];
|
||||
|
||||
int main() {
|
||||
std::cin >> buffer; // 全局缓冲区溢出错误
|
||||
std::cout << "You entered: " << buffer << std::endl;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
用法同上,得到:
|
||||
|
||||

|
||||
|
||||
## 5.use after return
|
||||
|
||||
在函数 `f` 中,局部变量 `i` 的地址被返回,但在 `main` 函数中,尝试通过返回的指针访问已经被销毁的局部变量。当出现这种场景是,可以对bin文件进行检测,设置`ASAN_OPTIONS=detect_stack_use_after_return=1`。
|
||||
|
||||
```
|
||||
g++-13 stack_use_after_return.cc -Wall -g -fsanitize=address
|
||||
ASAN_OPTIONS=detect_stack_use_after_return=1 ./a.out
|
||||
```
|
||||
|
||||
代码:
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
int *f() {
|
||||
int i = 42;
|
||||
int *p = &i;
|
||||
return p;
|
||||
}
|
||||
|
||||
int main() { return *f(); }
|
||||
|
||||
```
|
||||
|
||||
我们便会得到:
|
||||
|
||||

|
||||
|
||||
## 6.use after scope
|
||||
|
||||
将局部变量 `x` 的地址赋给指针 `p`,然而,在超出该内部作用域后,尝试通过指针 `p` 访问已经超出范围的局部变量 `x`,导致范围外使用错误。这也是未定义行为。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
int main() {
|
||||
int* p = 0;
|
||||
{
|
||||
int x = 0;
|
||||
p = &x;
|
||||
}
|
||||
*p = 5;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
编译与运行:
|
||||
|
||||
```
|
||||
g++-13 stack_use_after_scope.cc -Wall -g -fsanitize=address
|
||||
ASAN_OPTIONS=detect_stack_use_after_scope=0 ./a.out
|
||||
```
|
||||
|
||||
实测clang++可以,g++无法检测。
|
||||
|
||||

|
||||
|
||||
## 7.Initialization order bugs
|
||||
|
||||
在两个不同的源文件中,存在全局变量 `a` 的初始化,但初始化的顺序不确定。在 `init_order_b.cc` 文件中,尝试使用变量 `a` 的值,但由于初始化顺序不一致,可能导致未定义的行为。
|
||||
|
||||
代码如下:
|
||||
|
||||
```cpp
|
||||
// init_order_a.cc
|
||||
int duplicate(int n) { return n * 2; }
|
||||
auto a = duplicate(2);
|
||||
|
||||
// init_order_b.cc
|
||||
#include <iostream>
|
||||
|
||||
extern int a;
|
||||
auto b = a;
|
||||
|
||||
int main() {
|
||||
std::cout << b << std::endl;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
当我们编写这样的代码时,其结果是不确定的,可能是4也可能是0,取决于初始化的顺序。
|
||||
|
||||
例如:
|
||||
|
||||
```
|
||||
clang++ init_order_a.cc init_order_b.cc -Wall -g -fsanitize=address
|
||||
```
|
||||
|
||||
这样输出是4,而先编译b,后编译a,得到0。
|
||||
|
||||
```
|
||||
clang++ init_order_b.cc init_order_a.cc -Wall -g -fsanitize=address
|
||||
```
|
||||
|
||||
当出现这种问题时,我们可以使用AddressSanitizer检测初始化顺序。
|
||||
|
||||
```cpp
|
||||
ASAN_OPTIONS=check_initialization_order=true ./a.out
|
||||
```
|
||||
|
||||

|
||||
|
||||
## 8.memory leak
|
||||
|
||||
通过 `new` 关键字动态分配了一个整数的内存,但在程序结束前未使用 `delete` 关键字释放这块内存,导致内存泄漏。
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
int main() {
|
||||
int* ptr = new int;
|
||||
// Missing delete ptr; // Memory leak
|
||||
return 0;
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
设置`ASAN_OPTIONS=detect_leaks=1`。
|
||||
|
||||
```
|
||||
ASAN_OPTIONS=detect_leaks=1 ./a.out
|
||||
```
|
||||
|
||||

|
||||
133
site_extras/cpp-memory-debug-cpp-memory-leak-detection.md
Normal file
133
site_extras/cpp-memory-debug-cpp-memory-leak-detection.md
Normal file
@@ -0,0 +1,133 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-memory-debug/cpp-memory-leak-detection/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 内存泄漏检测
|
||||
|
||||
## C++那些事之如何检测内存
|
||||
|
||||
我们在编写C/C++代码时,内存问题无处不在,无论是工作还是面试,都离不开内存的话题。
|
||||
|
||||
今天使用一个例子来Step by Step的上手valgrind检测C++内存。
|
||||
|
||||
模拟三个问题:
|
||||
|
||||
- 释放内存问题检测
|
||||
- 写溢出检测
|
||||
- 读溢出检测
|
||||
|
||||
你将会学习到:
|
||||
|
||||
- 如果检测这三个问题
|
||||
- 如果使用gdb + valgrind一起调试
|
||||
|
||||
欢迎一起讨论。
|
||||
|
||||
## 1.示例引入
|
||||
|
||||
大家看一下下面这个代码,我们会发现有很多问题:
|
||||
|
||||
- strcpy不安全,究竟多大的内存大小,可能会越界
|
||||
- print时msg访问越界
|
||||
- 析构函数没有释放内存
|
||||
|
||||
是不是像极了自己曾经写的代码,哈哈。
|
||||
|
||||
本节就来检测出这些问题。
|
||||
|
||||
```cpp
|
||||
class Message {
|
||||
private:
|
||||
char *msg;
|
||||
|
||||
public:
|
||||
Message(const char *text) {
|
||||
msg = new char[3];
|
||||
std::strcpy(msg, text);
|
||||
}
|
||||
|
||||
void printOutOfRange() {
|
||||
std::cout << msg[5] << std::endl;
|
||||
}
|
||||
|
||||
~Message() {
|
||||
|
||||
}
|
||||
};
|
||||
|
||||
int main() {
|
||||
Message message("hello");
|
||||
message.printOutOfRange();
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
## 2.valgrind
|
||||
|
||||
valgrind安装:
|
||||
|
||||
```
|
||||
brew install valgrind // mac
|
||||
sudo apt-get install install // ubuntu
|
||||
```
|
||||
|
||||
更多系统的安装参考官方地址:
|
||||
|
||||
> https://valgrind.org/downloads/
|
||||
|
||||
## 3.使用
|
||||
|
||||
首先编译时,建议使用debug,-g,这样的话可以检测到代码哪一行有问题。
|
||||
|
||||
```
|
||||
g++ val_test.cc -g
|
||||
```
|
||||
|
||||
然后我们执行:
|
||||
|
||||
```
|
||||
valgrind --leak-check=full ./a.out
|
||||
```
|
||||
|
||||
我们便得到了valgrind给我们的信息:
|
||||
|
||||

|
||||
|
||||
此时,在上面我们可以看到几个问题:
|
||||
|
||||
- Invalid write
|
||||
|
||||
发生在val_test.cc::11
|
||||
|
||||
- Invalid read
|
||||
|
||||
发生在val_test.cc:10
|
||||
|
||||
- 内存泄漏
|
||||
|
||||
1 allocs, 0 frees,3 bytes allocated.
|
||||
|
||||
这些信息可以快速让我们定位到哪一行代码有问题。
|
||||
|
||||
## 4.gdb调试
|
||||
|
||||
当我们给它加上`--vgdb-error=0`后,我们便可以很方便的调试代码了,一边调试,一边看哪里有问题。
|
||||
|
||||
```cpp
|
||||
valgrind --leak-check=full --vgdb-error=0 ./a.out
|
||||
```
|
||||
|
||||

|
||||
|
||||
随后,我们gdb上去
|
||||
|
||||
```cpp
|
||||
gdb -q a.out
|
||||
```
|
||||
|
||||
把上面的target那一行粘贴到 gdb里面,然后continue,我们便可以看到对应行的代码以及valgrind会继续输出的信息。
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
本节带大家实战内存问题,如果对你有帮助欢迎转发。
|
||||
19
site_extras/cpp-memory-debug-valgrind-massif-memory.md
Normal file
19
site_extras/cpp-memory-debug-valgrind-massif-memory.md
Normal file
@@ -0,0 +1,19 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-memory-debug/valgrind-massif-memory/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# Valgrind Massif 内存分析
|
||||
|
||||
gpstart -a --wrapper=valgrind --wrapper-args=" --tool=massif --time-unit=B --detailed-freq=1 --massif-out-file=/tmp/massif.out.%p"
|
||||
|
||||

|
||||
|
||||
```
|
||||
ms_print xxx.out | more
|
||||
```
|
||||
|
||||
https://valgrind.org/docs/manual/ms-manual.html
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
valgrind -v --tool=massif --time-unit=B --detailed-freq=1 --massif-out-file=./massif.out ./a.out
|
||||
7
site_extras/cpp-projects-cpp-fnonce-implementation.md
Normal file
7
site_extras/cpp-projects-cpp-fnonce-implementation.md
Normal file
@@ -0,0 +1,7 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/cpp-fnonce-implementation/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# 手撕 C++ FnOnce
|
||||
|
||||
## 《C++那些事》手撕C++版本的Fn、FnOnce、FnMut
|
||||
|
||||
## 1.目标
|
||||
182
site_extras/cpp-projects-cpp-grpc-demo.md
Normal file
182
site_extras/cpp-projects-cpp-grpc-demo.md
Normal file
@@ -0,0 +1,182 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/cpp-grpc-demo/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ gRPC 小项目
|
||||
|
||||
## C++那些事之grpc小Demo
|
||||
|
||||
github上比较火的rpc有grpc、brpc,腾讯内部比较牛逼的trpc等等,这些rpc支持不同的语言、不同平台。今天来聊聊如何使用grpc,从一个简单的demo入手,整个项目使用CMake构建,一个非常标准的rpc项目管理,所有代码已更新至星球,获取方式见最后的二维码。
|
||||
|
||||
## 1.Step by Step 环境
|
||||
|
||||
如果你的电脑是mac,不好意思,暂时用不了最新版本的grpc,最新版本的grpc用了abseil,编译会有问题,官方暂时未解决,如果大家知道如何解决,可以留言,我这边目前未找到解决方法。
|
||||
|
||||
所以,建议安装低版本的grpc在你的mac上,或者在linux直接安装,linux上可以使用最新版本grpc,一次安装没有任何问题。
|
||||
|
||||
安装方式:
|
||||
|
||||
```
|
||||
git clone -b v1.57.0 git@github.com:grpc/grpc.git
|
||||
```
|
||||
|
||||
然后初始化submodule
|
||||
|
||||
```cpp
|
||||
git submodule update --init
|
||||
```
|
||||
|
||||
cmake编译安装:
|
||||
|
||||
```cpp
|
||||
cd cmake
|
||||
mkdir build
|
||||
cd build
|
||||
cmake -DgRPC_INSTALL=ON -DgRPC_BUILD_TESTS=OFF -DCMAKE_INSTALL_PREFIX=/usr/local/grpc ../..
|
||||
|
||||
make -j8
|
||||
make -j8 install // root 权限
|
||||
```
|
||||
|
||||
大家可以修改上面的安装目录,注意install时需要root权限。
|
||||
|
||||
安装完之后,将你的bin目录配置到path,例如:
|
||||
|
||||
```
|
||||
export PATH=/usr/local/grpc/bin:$PATH
|
||||
```
|
||||
|
||||
## 2.反转字符串Demo
|
||||
|
||||
环境搞定了之后,我们便可以上手搞事了。
|
||||
|
||||
### 2.1 协议
|
||||
|
||||
第一件事是确定rpc协议:
|
||||
|
||||
```cpp
|
||||
syntax = "proto3";
|
||||
|
||||
package stringreverse;
|
||||
|
||||
service StringReverse {
|
||||
rpc sendRequest (StringRequest) returns (StringReply) {}
|
||||
}
|
||||
|
||||
message StringRequest {
|
||||
string original = 1;
|
||||
}
|
||||
|
||||
message StringReply {
|
||||
string reversed = 1;
|
||||
}
|
||||
```
|
||||
|
||||
非常简单的协议,请求一个字符串,返回一个字符串。
|
||||
|
||||
### 2.2 客户端
|
||||
|
||||
构造rpc请求字符串,然后调用sendRequest接口发送出去即可。
|
||||
|
||||
```cpp
|
||||
std::string str = "hello world grpc!";
|
||||
std::cout << "Original string: " << str << std::endl;
|
||||
StringRequest request;
|
||||
StringReply reply;
|
||||
ClientContext context;
|
||||
request.set_original(str);
|
||||
Status status = stub->sendRequest(&context, request, &reply);
|
||||
if (status.ok()) {
|
||||
std::cout << "Reversed string: " << reply.reversed() << std::endl;
|
||||
}
|
||||
// do something
|
||||
```
|
||||
|
||||
### 2.3 服务端
|
||||
|
||||
通过继承Service实现反转字符串逻辑。
|
||||
|
||||
```cpp
|
||||
class ReverseServiceImplementation final : public StringReverse::Service {
|
||||
Status sendRequest(ServerContext* context, const StringRequest* request,
|
||||
StringReply* reply) override {
|
||||
// 反转逻辑
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
最后注册service即可:
|
||||
|
||||
```cpp
|
||||
builder.RegisterService(&service);
|
||||
std::unique_ptr<Server> server(builder.BuildAndStart());
|
||||
std::cout << "Server listening on port: " << server_address << std::endl;
|
||||
```
|
||||
|
||||
## 3.运行
|
||||
|
||||
创建编译目录:
|
||||
|
||||
```
|
||||
mkdir build
|
||||
cmake ..
|
||||
# 输出
|
||||
-- The C compiler identification is GNU 10.2.1
|
||||
-- The CXX compiler identification is GNU 10.2.1
|
||||
-- Detecting C compiler ABI info
|
||||
-- Detecting C compiler ABI info - done
|
||||
-- Check for working C compiler: /opt/rh/devtoolset-10/root/usr/bin/cc - skipped
|
||||
-- Detecting C compile features
|
||||
-- Detecting C compile features - done
|
||||
-- Detecting CXX compiler ABI info
|
||||
-- Detecting CXX compiler ABI info - done
|
||||
-- Check for working CXX compiler: /opt/rh/devtoolset-10/root/usr/bin/c++ - skipped
|
||||
-- Detecting CXX compile features
|
||||
-- Detecting CXX compile features - done
|
||||
-- Looking for pthread.h
|
||||
-- Looking for pthread.h - found
|
||||
-- Performing Test CMAKE_HAVE_LIBC_PTHREAD
|
||||
-- Performing Test CMAKE_HAVE_LIBC_PTHREAD - Failed
|
||||
-- Looking for pthread_create in pthreads
|
||||
-- Looking for pthread_create in pthreads - not found
|
||||
-- Looking for pthread_create in pthread
|
||||
-- Looking for pthread_create in pthread - found
|
||||
-- Found Threads: TRUE
|
||||
-- Found Protobuf: /usr/local/grpc/bin/protoc-23.4.0 (found version "23.4.0")
|
||||
-- Using protobuf
|
||||
-- Using gRPC 1.57.0
|
||||
-- Configuring done
|
||||
-- Generating done
|
||||
-- Build files have been written to: /code/stringreverse/build
|
||||
```
|
||||
|
||||
make编译:
|
||||
|
||||
```
|
||||
[ 10%] Generating stringreverse.pb.cc, stringreverse.pb.h, stringreverse.grpc.pb.cc, stringreverse.grpc.pb.h
|
||||
Scanning dependencies of target server
|
||||
[ 20%] Building CXX object CMakeFiles/server.dir/server.cc.o
|
||||
[ 30%] Building CXX object CMakeFiles/server.dir/stringreverse.pb.cc.o
|
||||
[ 40%] Building CXX object CMakeFiles/server.dir/stringreverse.grpc.pb.cc.o
|
||||
[ 50%] Linking CXX executable server
|
||||
[ 50%] Built target server
|
||||
Scanning dependencies of target client
|
||||
[ 60%] Building CXX object CMakeFiles/client.dir/client.cc.o
|
||||
[ 70%] Building CXX object CMakeFiles/client.dir/stringreverse.pb.cc.o
|
||||
[ 80%] Building CXX object CMakeFiles/client.dir/stringreverse.grpc.pb.cc.o
|
||||
[ 90%] Linking CXX executable client
|
||||
[100%] Built target client
|
||||
```
|
||||
|
||||
运行server:
|
||||
|
||||
```
|
||||
[light@i-i339drlk build]$ ./server
|
||||
Server listening on port: 0.0.0.0:5000
|
||||
```
|
||||
|
||||
运行client:
|
||||
|
||||
```cpp
|
||||
[light@i-i339drlk build]$ ./client
|
||||
Original string: hello world grpc!
|
||||
Reversed string: !cprg dlrow olleh
|
||||
```
|
||||
83
site_extras/cpp-projects-cpp-ipc-practice.md
Normal file
83
site_extras/cpp-projects-cpp-ipc-practice.md
Normal file
@@ -0,0 +1,83 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/cpp-ipc-practice/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 进程间通信实战
|
||||
|
||||
进程间通信是一个非常重要的话题,特别是像一些大型项目都有它的影子,例如:PostgreSQL使用了管道完成copy的进程间通信,那么本节也将基于这个主题,使用C++去搭建一个进程间通过管道通信的demo出来,本节将会结合前面几节讲的内容,给出一个比较完整的实战例子出来:
|
||||
|
||||
- mutex
|
||||
- condition_variable
|
||||
- thread
|
||||
|
||||
注:本节的完整代码会放在星球中。
|
||||
|
||||
首先一个很简单的管道用法为:
|
||||
|
||||
- 创建一个管道
|
||||
|
||||
它会creating a pipe, forking, and invoking the shell.
|
||||
|
||||
```cpp
|
||||
// FILE *popen(const char *command, const char *type);
|
||||
pipe = popen(command.c_str(), "w");
|
||||
```
|
||||
|
||||
- 关闭一个管道
|
||||
|
||||
```cpp
|
||||
// int pclose(FILE *stream);
|
||||
pclose(pipe);
|
||||
```
|
||||
|
||||
接下来我们就只需要往里面写与读了,原理也很简单,例如:
|
||||
|
||||
此时便会把data写入到前面创建的管道中。
|
||||
|
||||
```cpp
|
||||
// size_t fwrite( const void* buffer, size_t size, size_t count, FILE* stream );
|
||||
size_t written = fwrite(data.c_str(), sizeof(char), data.size(), pipe);
|
||||
```
|
||||
|
||||
如果从管道中读取,我们可以使用fread或者fgets,`fgets` 会在读取到换行符或达到缓冲区大小时停止,而 `fread` 会尽可能多地读取数据,直到达到指定的字节数或遇到文件结尾。同理,上面的fwrite可以替换为fputs。
|
||||
|
||||
现在,一个管道的基本使用介绍完了,如何写一个完整的demo?
|
||||
|
||||
很简单,我们只需要创建两个线程,一个读,一个写,然后写线程往pipe里面写数据,读线程从pipe里面读即可。
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
std::thread writer_thread(write_to_pipe);
|
||||
std::thread reader_thread(read_from_pipe);
|
||||
|
||||
writer_thread.join();
|
||||
reader_thread.join();
|
||||
```
|
||||
|
||||
写线程需要做的事情就是调用fwrite丢数据即可
|
||||
|
||||
```cpp
|
||||
ProcessWriter writer("cat > /tmp/pipe");
|
||||
|
||||
// 写入数据
|
||||
std::string message = "Hello pipe!\n";
|
||||
if (!writer.write(message)) {
|
||||
std::cerr << "Failed to write data to pipe" << std::endl;
|
||||
}
|
||||
```
|
||||
|
||||
同理,读线程取数据:
|
||||
|
||||
```cpp
|
||||
ProcessReader reader("/tmp/pipe");
|
||||
// 读取数据
|
||||
std::string message;
|
||||
while (reader.read(message)) {
|
||||
// do something
|
||||
}
|
||||
```
|
||||
|
||||
最后的效果就是:
|
||||
|
||||
```cpp
|
||||
Read from pipe: Hello pipe!
|
||||
```
|
||||
70
site_extras/cpp-projects-cpp-short-url-demo.md
Normal file
70
site_extras/cpp-projects-cpp-short-url-demo.md
Normal file
@@ -0,0 +1,70 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/cpp-short-url-demo/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 短链接服务 Demo
|
||||
|
||||
真实的短链接相对来说比较复杂,例如:hash算法、放号系统等等。
|
||||
|
||||
今天只是从小项目角度模拟一个短链接实现。
|
||||
|
||||
如何通过短短的几十行代码快速实现一个?其中涉及的几个关键点:
|
||||
|
||||
- 如何将长链接缩短
|
||||
- 如何存储映射关系
|
||||
|
||||
映射关系就不用说了,整一个map持久化内存,如果涉及到数据库,需要通过数据库的jdbc/odbc等接口访问写入库当中。
|
||||
|
||||
长链接缩短这里采用随机算法+固定长度思路来实现。
|
||||
|
||||
## 1.随机
|
||||
|
||||
通过uniform_int_distribution,生成一个`[a, b]`区间的随机数,这里随机从下列字符串中每次取一个字符,最后拼接起来就是短链接。
|
||||
|
||||
```cpp
|
||||
string characters{
|
||||
"abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ0123456789"};
|
||||
```
|
||||
|
||||
包含:
|
||||
|
||||
- 数字
|
||||
- 小写字母
|
||||
- 大写字母
|
||||
|
||||
```cpp
|
||||
uniform_int_distribution<int> distribution(0, characters.size() - 1);
|
||||
string code;
|
||||
for (int i = 0; i < length; ++i)
|
||||
code += characters[distribution(generator)];
|
||||
```
|
||||
|
||||
## 2.存储
|
||||
|
||||
每次将其存储到map中即可,例如:
|
||||
|
||||
```cpp
|
||||
if (links.count(originalLink)) {
|
||||
return links[originalLink];
|
||||
}
|
||||
|
||||
shortCode = generateRandomCode(len);
|
||||
string shortenedLink = base_url + shortCode;
|
||||
links[shortenedLink] = originalLink;
|
||||
```
|
||||
|
||||
这里保留了基本url,例如:
|
||||
|
||||
```cpp
|
||||
string baseUrl = "https://www.google.com.hk/search";
|
||||
LinkShortener shortener(baseUrl);
|
||||
|
||||
string originalLink = "https://www.google.com.hk/search?q=asdsad&oq=asdsad&aqs=chrome.0.69i59j69i57j69i59l2.634j0j4&sourceid=chrome&ie=UTF-8";
|
||||
string shortenedLink = shortener.shortenLink(originalLink, 8);
|
||||
```
|
||||
|
||||
最后便可以将这个url缩短为:
|
||||
|
||||
```
|
||||
https://www.google.com.hk/searchtXuOlOSt
|
||||
```
|
||||
|
||||
是不是很简单,本节的测试与完整代码已在星球更新,欢迎加入一起学习成长~
|
||||
134
site_extras/cpp-projects-cpp17-sqlite-folder-size.md
Normal file
134
site_extras/cpp-projects-cpp17-sqlite-folder-size.md
Normal file
@@ -0,0 +1,134 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/cpp17-sqlite-folder-size/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++17 与 SQLite 统计目录大小
|
||||
|
||||
## 项目实战:使用 C++17 和 SQLite 实现文件夹大小计算与存储
|
||||
|
||||
[TOC]
|
||||
|
||||
本节将会围绕一个项目背景展开:假设业务中需要定时检查某些文件夹大小,并做一下持久化操作,C++如何去完成这一个项目呢?
|
||||
|
||||
本节带你通过一个小项目,使用 C++17 和 SQLite 实现一个文件夹大小计算与存储的系统,帮助你更好地管理你的文件系统。
|
||||
|
||||
### 项目目标
|
||||
|
||||
我们将实现以下功能:
|
||||
1. **递归计算指定目录及其子目录的大小**。
|
||||
2. **将计算结果保存到 SQLite 数据库**,方便后续查询和分析。
|
||||
3. **可扩展性强**:你可以轻松修改项目,添加多线程支持、优化性能,或将结果存储到其他数据库中。
|
||||
|
||||
**注:懒人版,完整代码已更新星球。**
|
||||
|
||||
### 项目实现步骤
|
||||
|
||||
#### 1. 环境
|
||||
|
||||
首先,你需要确保开发环境中已经安装了以下工具:
|
||||
- **支持C++17 编译器**:如 g++,通过以下命令可以检查版本:
|
||||
|
||||
```bash
|
||||
g++ --version
|
||||
```
|
||||
确保 g++ 支持 C++17 标准。
|
||||
|
||||
- **SQLite3**:数据库操作我们会使用 SQLite,你可以通过包管理器来安装它:
|
||||
```bash
|
||||
sudo apt-get install sqlite3 libsqlite3-dev
|
||||
```
|
||||
安装完后,SQLite 数据库的开发库 `libsqlite3-dev` 可以确保我们在 C++ 中能正常使用 SQLite。
|
||||
|
||||
#### 2. 创建项目结构
|
||||
|
||||
我们将把代码分为多个模块,保持清晰的架构:
|
||||
- `folder_size.h` / `folder_size.cpp`:负责递归计算目录及其子目录大小。
|
||||
- `database.h` / `database.cpp`:封装 SQLite 数据库操作逻辑。
|
||||
- `main.cpp`:主程序入口,负责整体流程的控制。
|
||||
|
||||
项目的目录结构如下:
|
||||
```
|
||||
project/
|
||||
│── folder_size.h
|
||||
│── folder_size.cpp
|
||||
│── database.h
|
||||
│── database.cpp
|
||||
└── main.cpp
|
||||
```
|
||||
|
||||
#### 3. 代码实现
|
||||
|
||||
接下来,我们将一步步实现每个模块。
|
||||
|
||||
##### 3.1 目录计算模块
|
||||
|
||||
C++17 提供了`std::filesystem` 库来递归遍历目录并计算大小。因此其核心实现如下:
|
||||
|
||||
```cpp
|
||||
uintmax_t total_size = 0;
|
||||
for (const auto& entry : fs::recursive_directory_iterator(dir_path)) {
|
||||
if (fs::is_regular_file(entry.path())) {
|
||||
total_size += fs::file_size(entry.path());
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
如果要计算根目录 再计算一次即可。
|
||||
|
||||
##### 3.2 SQLite数据库操作
|
||||
|
||||
引入:
|
||||
|
||||
```
|
||||
#include <sqlite3.h>
|
||||
```
|
||||
|
||||
使用:
|
||||
|
||||
```cpp
|
||||
sqlite3_close(db_); // 关闭
|
||||
|
||||
// 插入
|
||||
for (const auto& [folder, size] : folder_sizes) {
|
||||
const std::string insert_sql =
|
||||
"INSERT OR REPLACE INTO FolderSizes (Folder, Size) "
|
||||
"VALUES ('" + folder + "', " + std::to_string(size) + ");";
|
||||
if (!ExecuteSQL(insert_sql)) {
|
||||
return false;
|
||||
}
|
||||
}
|
||||
|
||||
// 执行
|
||||
sqlite3_exec
|
||||
```
|
||||
|
||||
#### 4. 编译与运行
|
||||
|
||||
编译项目非常简单:
|
||||
|
||||
```bash
|
||||
mkdir build
|
||||
cmake ../
|
||||
make -j8
|
||||
```
|
||||
|
||||
然后,运行程序,计算目录大小并存储到数据库:
|
||||
|
||||
```bash
|
||||
./folder_size_calculator
|
||||
```
|
||||
|
||||
程序将会递归计算指定目录的大小,并将结果保存到 `folder_sizes.db` 数据库中。
|
||||
|
||||
#### 5. 查询数据库
|
||||
|
||||
最后,你可以通过
|
||||
|
||||
SQLite 命令行工具查询数据库中的内容:
|
||||
|
||||
```bash
|
||||
sqlite3 folder_sizes.db
|
||||
sqlite> SELECT * FROM FolderSizes;
|
||||
```
|
||||
|
||||
这将显示所有已保存的目录及其对应的大小。
|
||||
|
||||
> 本节完
|
||||
109
site_extras/cpp-projects-google-benchmark-cpp.md
Normal file
109
site_extras/cpp-projects-google-benchmark-cpp.md
Normal file
@@ -0,0 +1,109 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/google-benchmark-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# Google Benchmark 性能测试
|
||||
|
||||
## 《C++那些事》之开启你的BenchMark测试
|
||||
|
||||
## 0.导语
|
||||
|
||||
本节目标:完成一个BenchMark小项目!
|
||||
|
||||
在平时开发中,如何测试自己的接口性能呢?C++里面如何快速搭建一个BenchMark测试框架呢?
|
||||
|
||||
本节将Step By Step开启BenchMark入门的第一课。
|
||||
|
||||
## 1.项目结构
|
||||
|
||||
我们以vector与list插入为例,来讲解BenchMark项目。
|
||||
|
||||
这次项目是基于Bazel来管理的,如果还不知道如何配置相关环境的,请参考之前的视频课程/文档资料。
|
||||
|
||||
创建一个项目结构为:
|
||||
|
||||
```
|
||||
```
|
||||
|
||||
BenchMark采用google的开源项目:
|
||||
|
||||
```cpp
|
||||
https://github.com/google/benchmark.git
|
||||
```
|
||||
|
||||
像以前大家使用第三方库,需要自己源码编译一波,生成so库,然后链接,太麻烦了!这里直接使用bazel管理,只需要在WORKSPACE里面,添加依赖的git项目,例如这里采用google benchmark的v1.7.1版本。
|
||||
|
||||
```cpp
|
||||
git_repository(
|
||||
name = "google_benchmark",
|
||||
remote = "https://github.com/google/benchmark.git",
|
||||
tag = "v1.7.1",
|
||||
)
|
||||
```
|
||||
|
||||
随后,我们需要实现主逻辑,创建一个src目录,里面添加一个BUILD文件:目的在于编译过会cpp文件,注意:这里依赖了benchmark库,使用方法为@**前面配置的name**//:benchmark
|
||||
|
||||
```cpp
|
||||
cc_binary(
|
||||
name = "vector_list",
|
||||
srcs = ["vector_list.cc"],
|
||||
deps = [
|
||||
"@google_benchmark//:benchmark",
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
这样的话,在cc文件中便可以使用了:
|
||||
|
||||
```cpp
|
||||
#include <benchmark/benchmark.h>
|
||||
```
|
||||
|
||||
### 2.Demo环节
|
||||
|
||||
编写两个插入函数,非常简单,框架如下所示,里面有一些需要说明的,如下:
|
||||
|
||||
- state为benchmark的运行时状态信息
|
||||
- 例如:休眠控制、入参数控制等
|
||||
- state.range(0)便是获取第0个参数
|
||||
- DoNotOptimize表示不做编译器优化
|
||||
|
||||
```cpp
|
||||
// 测试 std::vector 的插入速度
|
||||
static void BM_vectorInsert(benchmark::State& state) {
|
||||
for (auto _ : state) {
|
||||
std::vector<int> v;
|
||||
for (size_t i = 0; i < state.range(0); ++i) {
|
||||
v.insert(v.begin() + i, i);
|
||||
}
|
||||
benchmark::DoNotOptimize(v);
|
||||
}
|
||||
}
|
||||
|
||||
// 测试 std::list 的插入速度
|
||||
static void BM_listInsert(benchmark::State& state) {
|
||||
for (auto _ : state) {
|
||||
std::list<int> l;
|
||||
for (size_t i = 0; i < state.range(0); ++i) {
|
||||
l.insert(l.begin(), i);
|
||||
}
|
||||
benchmark::DoNotOptimize(l);
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
主入口调用:
|
||||
|
||||
- Range(8, 8 << 10) 表示从8开始,每次乘以8,直到8192,这个对应上面的state.range(0),会把这个数作为参数传递进去
|
||||
- BENCHMARK_MAIN表示使用google benchmark的main函数,我们知道每个可执行文件都有一个main,那这个文件可以执行的原因就在于,这个宏展开后就是main函数,你学会了吗?
|
||||
|
||||
```cpp
|
||||
// 定义基准测试
|
||||
BENCHMARK(BM_vectorInsert)->Range(8, 8<<10);
|
||||
BENCHMARK(BM_listInsert)->Range(8, 8<<10);
|
||||
|
||||
// 运行基准测试
|
||||
BENCHMARK_MAIN();
|
||||
```
|
||||
|
||||
## 3.总结
|
||||
|
||||
本节Step by Step带大家学习google benchmark,并将其应用到我们自己的项目中,你可以在里面做很多有趣的事情,本节源码放入知识星球当中供大家学习,欢迎加入一起交流~
|
||||
37
site_extras/cpp-projects-modern-cpp-http-server.md
Normal file
37
site_extras/cpp-projects-modern-cpp-http-server.md
Normal file
@@ -0,0 +1,37 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/modern-cpp-http-server/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++20 协程 HTTP 服务器
|
||||
|
||||
## 现代 C++ HTTP 服务器
|
||||
|
||||
最近星球小伙伴总是问我有没有网络相关的项目,于是写了一个基于现代C++ + CMake管理的完整项目。
|
||||
|
||||
该项目具备以下特性:
|
||||
|
||||
- 大量现代C++特性
|
||||
- C++20相关
|
||||
- cortouine
|
||||
- concept
|
||||
- std::format
|
||||
- std::span
|
||||
- C++17相关
|
||||
- if语句初始化
|
||||
- 结构化绑定
|
||||
- optional
|
||||
- 高效的事件驱动机制
|
||||
- 使用 `epoll` 实现事件循环,管理大量的客户端连接。`epoll` 是 Linux 平台上处理高并发 I/O 的高效工具,它可以同时监听多个文件描述符的事件,从而有效地减少系统调用开销,提高 I/O 操作的并发性。
|
||||
- 服务器在主事件循环中通过非阻塞 `epoll_wait` 监听连接事件,避免了传统阻塞 I/O 带来的性能瓶颈。
|
||||
- 协程与异步编程
|
||||
- 采用 C++20 协程简化异步任务的实现,提供了类似同步代码的写法,使代码逻辑更加清晰。项目中通过 `co_await` 异步读取和写入客户端数据,减少了线程上下文切换的开销。
|
||||
- 实现了 `SocketAwaiter` 和 `AsyncSocketOperation` 两个类,用于封装套接字的异步读写操作,使得编写异步处理代码变得更加简洁和自然。
|
||||
- 文件 I/O 操作的异步处理
|
||||
- 服务器支持异步读取 HTML 文件内容,通过 `std::async` 实现异步文件读取,避免阻塞主线程,从而更快地响应客户端请求。
|
||||
- 在处理请求时,异步读取所需的文件并缓存到内存,减少了 I/O 操作对性能的影响。
|
||||
- 非阻塞套接字操作
|
||||
- 使用 `fcntl` 将套接字设置为非阻塞模式,保证 `accept` 和 `read/write` 操作不会阻塞服务器的主线程。这在高并发场景下尤为重要,可以显著提高服务器的并发处理能力。
|
||||
|
||||
项目效果:
|
||||
|
||||
|
||||
|
||||
学习方式:有详细的文档+代码,可以单独购买加下方微信或者加入星球即可。
|
||||
180
site_extras/cpp-projects-protobuf-zerocopy-cpp.md
Normal file
180
site_extras/cpp-projects-protobuf-zerocopy-cpp.md
Normal file
@@ -0,0 +1,180 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/protobuf-zerocopy-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# Protobuf ZeroCopy 序列化
|
||||
|
||||
## 1.ZeroCopyStream
|
||||
|
||||
protobuf在io接口上有一个叫做ZeroCopyStream,对于IO的接口设计,pb提供了相关序列化与反序列化接口,如:
|
||||
|
||||
```cpp
|
||||
// Read a protocol buffer from the given zero-copy input stream. If
|
||||
// successful, the entire input will be consumed.
|
||||
bool ParseFromZeroCopyStream(io::ZeroCopyInputStream* input);
|
||||
|
||||
// Write the message to the given zero-copy output stream. All required
|
||||
// fields must be set.
|
||||
bool SerializeToZeroCopyStream(io::ZeroCopyOutputStream* output) const;
|
||||
```
|
||||
|
||||
ZeroCopyStream设计的初衷是最小化buffer的拷贝次数,即省略掉stream内部数据拷贝到用户buffer。因此,stream可以返回一个缓冲区,该缓冲区实际上直接指向要存储字节的最终数据结构,并且调用者可以直接与该缓冲区交互,从而消除了中间复制操作。
|
||||
|
||||
例如:经典的IO stream:
|
||||
|
||||
```cpp
|
||||
char buffer[[]BUFFER_SIZE];
|
||||
input->Read(buffer, BUFFER_SIZE);
|
||||
DoSomething(buffer, BUFFER_SIZE);
|
||||
```
|
||||
|
||||
然后,stream基本上只是调用memcpy()将数据从pb复制到用户buffer中。如果使用ZeroCopyInputStream,我们只需要:
|
||||
|
||||
```cpp
|
||||
const void* buffer;
|
||||
int size;
|
||||
input->Next(&buffer, &size);
|
||||
DoSomething(buffer, size);
|
||||
```
|
||||
|
||||
这里不执行拷贝,调用者最终直接从buffer中读取。
|
||||
|
||||
ZeroCopyStream提供了两个基类:ZeroCopyOutputStream/ZeroCopyInputStream。
|
||||
|
||||
以InputStream为例,通常我们可以通过继承的方式自定义自己的ZerCopyStream,需要实现下面四个接口。
|
||||
|
||||
```cpp
|
||||
// implements ZeroCopyInputStream ----------------------------------
|
||||
bool Next(const void** data, int* size);
|
||||
void BackUp(int count);
|
||||
bool Skip(int count);
|
||||
int64 ByteCount() const;
|
||||
```
|
||||
|
||||
一些rpc框架基本都自定义自己的Stream,例如:sofa-pbrpc
|
||||
|
||||
> https://github.com/baidu/sofa-pbrpc/blob/master/src/sofa/pbrpc/buffer.h
|
||||
|
||||
## 2.Demo
|
||||
|
||||
定义一个pb协议,例如:授权验证:
|
||||
|
||||
```cpp
|
||||
syntax = "proto3";
|
||||
|
||||
message BasicAuth {
|
||||
string username = 1;
|
||||
string password = 2;
|
||||
}
|
||||
```
|
||||
|
||||
随后编写序列化与反序列化:
|
||||
|
||||
- 序列化
|
||||
|
||||
```cpp
|
||||
BasicAuth auth_message;
|
||||
auth_message.set_username("user123");
|
||||
auth_message.set_password("password");
|
||||
|
||||
StringOutputStream output_stream(&buf);
|
||||
|
||||
auth_message.SerializeToZeroCopyStream(&output_stream);
|
||||
```
|
||||
|
||||
- 反序列化
|
||||
|
||||
```cpp
|
||||
ArrayInputStream input_stream(buf.data(), buf.size());
|
||||
BasicAuth auth_message;
|
||||
if (!auth_message.ParseFromZeroCopyStream(&input_stream)) {
|
||||
std::cerr << "Failed to parse data." << std::endl;
|
||||
}
|
||||
|
||||
std::cout << "Username: " << auth_message.username() << std::endl;
|
||||
std::cout << "Password: " << auth_message.password() << std::endl;
|
||||
```
|
||||
|
||||
随后我们便可以调用它:
|
||||
|
||||
```cpp
|
||||
int main() {
|
||||
std::string buf;
|
||||
buf.reserve(512);
|
||||
ser(buf);
|
||||
deser(buf);
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```cpp
|
||||
Username: user123
|
||||
Password: password
|
||||
```
|
||||
|
||||
本节完,以上完整代码见知识星球,欢迎与我共同探讨rpc相关内容。
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
```
|
||||
(gdb) p *dsr
|
||||
$8 = {typeInfo = {datumlen = 4, typid = 1082, align = 105 'i', byval = true}, datumStreamVersion = DatumStreamVersion_Original, nth = -1,
|
||||
logical_row_count = 16382, datump = 0x3840470 "\277\377\377\377\231\002", physical_datum_index = -1, physical_datum_count = 0,
|
||||
datum_beginp = 0x3840470 "\277\377\377\377\231\002", datum_afterp = 0x38503dc "", has_null = true, buffer_beginp = 0x383fc60 "",
|
||||
null_bitmap = {buffer = 0x383fc70 "", byteBit = 0 '\000', bytePointer = 0x383fc70 "", bitCount = 16382, bitPosition = -1,
|
||||
readBitOnCount = 58981488}, null_bitmap_beginp = 0x0, rle_can_have_compression = false, rle_compress_beginp = 0x0, rle_repeatcountsp = 0x0,
|
||||
delta_beginp = 0x0, delta_deltasp = 0x0, delta_datum_p = 0, rle_norepeats_null_bitmap_count = 0, rle_compress_bitmap_count = 0,
|
||||
rle_repeatcounts_count = 0, rle_repeatcounts_size = 0, delta_item = false, delta_bitmap_count = 0, deltas_count = 0, deltas_size = 0,
|
||||
rle_block_was_compressed = false, rle_compress_bitmap = {buffer = 0x0, byteBit = 0 '\000', bytePointer = 0x0, bitCount = 0, bitPosition = 0,
|
||||
readBitOnCount = 0}, rle_repeatcounts_index = 0, rle_in_repeated_item = false, rle_repeated_item_count = 0,
|
||||
rle_total_repeat_items_read = 0, delta_block_was_compressed = false, delta_bitmap = {buffer = 0x0, byteBit = 0 '\000',
|
||||
bytePointer = 0xff6c00454244 <error: Cannot access memory at address 0xff6c00454244>, bitCount = 0, bitPosition = 0,
|
||||
readBitOnCount = 13651600}, eyecatcher = "\000\000\000", physical_data_size = 0, maxDataBlockSize = 13652112,
|
||||
errdetailCallback = 0x35daeb0, errdetailArg = 0x34c4e18, errcontextCallback = 0x34c4e18, errcontextArg = 0x383fc60, memctxt = 0x1077c}
|
||||
```
|
||||
157
site_extras/cpp-projects-pybind11-python-cpp.md
Normal file
157
site_extras/cpp-projects-pybind11-python-cpp.md
Normal file
@@ -0,0 +1,157 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/pybind11-python-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# pybind11 加速 Python
|
||||
|
||||
通常像一些耗时的操作,我们期望在C++中去实现,然后使用Python去调用对应的接口,或者因为底层库的原因,需要支持对外的Python API,那么我们通常需要支持在Python中访问C++,如何实现呢?
|
||||
|
||||
方法比较多,本节以pybind11为例,引入一个完整的项目工程模版,如果你后续有这种需求,可以基于模版去修改。
|
||||
|
||||
注:(懒人版)本节的所有代码也都放在星球里面。
|
||||
|
||||
## 1.宏展开
|
||||
|
||||
假设:我们以比较耗时的排序为例,如果我们想在C++中写一个排序,然后在Python中去使用它,怎么去写呢?
|
||||
|
||||
C++程序是比较简单的,对外暴露一个接口里面做排序即可,例如:
|
||||
|
||||
```cpp
|
||||
std::vector<int> sort_vector(const std::vector<int>& input) {
|
||||
std::vector<int> result = input;
|
||||
std::sort(result.begin(), result.end());
|
||||
return result;
|
||||
}
|
||||
```
|
||||
|
||||
那么问题来了,对于Pybind11来说,如何使用这个接口呢?
|
||||
|
||||
使用pybind11的宏即可定义一个模块,例如:
|
||||
|
||||
```cpp
|
||||
PYBIND11_MODULE(sort_module, m) {
|
||||
m.doc() = "pybind11 example plugin"; // Optional module docstring
|
||||
|
||||
m.def("sort_vector", &sort_vector, "A function that sorts a list of integers");
|
||||
}
|
||||
```
|
||||
|
||||
宏展开之后是:PyInit_sort_module
|
||||
|
||||
当我们在python当中import xxx库的时候,Python 解释器会去加载一个 C/C++ 编写的扩展模块时自动调用的入口函数,而这个入口函数就是下面的PyInit_sort_module:
|
||||
|
||||
```cpp
|
||||
static ::pybind11::module_::module_def pybind11_module_def_sort_module [[maybe_unused]];
|
||||
|
||||
[[maybe_unused]] static void pybind11_init_sort_module(::pybind11::module_ &);
|
||||
|
||||
extern "C" [[maybe_unused]] __attribute__((visibility("default"))) PyObject *PyInit_sort_module();
|
||||
|
||||
extern "C" __attribute__((visibility("default"))) PyObject *PyInit_sort_module() {
|
||||
{
|
||||
const char *compiled_ver = "3" "." "11";
|
||||
const char *runtime_ver = Py_GetVersion();
|
||||
size_t len = std::strlen(compiled_ver);
|
||||
|
||||
if (std::strncmp(runtime_ver, compiled_ver, len) != 0 || (runtime_ver[len] >= '0' && runtime_ver[len] <= '9')) {
|
||||
PyErr_Format(PyExc_ImportError,
|
||||
"Python version mismatch: module was compiled for Python %s, "
|
||||
"but the interpreter version is incompatible: %s.",
|
||||
compiled_ver, runtime_ver);
|
||||
return nullptr;
|
||||
}
|
||||
}
|
||||
|
||||
pybind11::detail::get_internals();
|
||||
auto m = ::pybind11::module_::create_extension_module("sort_module", nullptr, &pybind11_module_def_sort_module);
|
||||
|
||||
try {
|
||||
pybind11_init_sort_module(m);
|
||||
return m.ptr();
|
||||
} catch (pybind11::error_already_set & e) {
|
||||
pybind11::raise_from(e, PyExc_ImportError, "initialization failed");
|
||||
return nullptr;
|
||||
} catch (const std::exception &e) {
|
||||
::pybind11::set_error(PyExc_ImportError, e.what());
|
||||
return nullptr;
|
||||
}
|
||||
}
|
||||
|
||||
void pybind11_init_sort_module(::pybind11::module_ & m) {
|
||||
m.doc() = "pybind11 example plugin";
|
||||
|
||||
m.def("sort_vector", &sort_vector, "A function that sorts a list of integers");
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
所以,如果我们不去使用这个宏,在import库的时候会报错:
|
||||
|
||||
```python
|
||||
>>> import sort_module
|
||||
Traceback (most recent call last):
|
||||
File "<stdin>", line 1, in <module>
|
||||
ImportError: dynamic module does not define module export function (PyInit_sort_module)
|
||||
```
|
||||
|
||||
## 2.CMake + pybind11
|
||||
|
||||
pybind11在C++中的使用如下:
|
||||
|
||||
- 头文件
|
||||
|
||||
```cpp
|
||||
#include <pybind11/pybind11.h>
|
||||
#include <pybind11/stl.h>
|
||||
```
|
||||
|
||||
- 宏
|
||||
|
||||
```
|
||||
PYBIND11_MODULE(sort_module, m) {
|
||||
// 你的实现
|
||||
}
|
||||
```
|
||||
|
||||
那么如何在cmake中下载并链接pybind11呢?
|
||||
|
||||
只需要使用FetchContent模块即可,例如:
|
||||
|
||||
```cpp
|
||||
FetchContent_Declare(
|
||||
pybind11
|
||||
URL https://github.com/pybind/pybind11/archive/v2.12.0.tar.gz
|
||||
)
|
||||
```
|
||||
|
||||
然后在CMakeLists中加入你的模块即可:
|
||||
|
||||
```cpp
|
||||
pybind11_add_module(sort_module sort_module.cc)
|
||||
```
|
||||
|
||||
cmake将会帮你下载pybingd11,同时编译好。
|
||||
|
||||
## 3.使用
|
||||
|
||||
上面会生成一个so,install到python的site-packages目录,然后import的时候便会识别,如下演示我们自定义的模块:
|
||||
|
||||
```python
|
||||
import sort_module
|
||||
|
||||
def test_sort():
|
||||
input_list = [5, 2, 3, 1, 4]
|
||||
sorted_list = sort_module.sort_vector(input_list)
|
||||
print(f"Original list: {input_list}")
|
||||
print(f"Sorted list: {sorted_list}")
|
||||
|
||||
if __name__ == "__main__":
|
||||
test_sort()
|
||||
|
||||
```
|
||||
|
||||
运行:
|
||||
|
||||
```
|
||||
(base) ➜ build python ../test.py
|
||||
Original list: [5, 2, 3, 1, 4]
|
||||
Sorted list: [1, 2, 3, 4, 5]
|
||||
```
|
||||
75
site_extras/cpp-projects-stack-calculator-design.md
Normal file
75
site_extras/cpp-projects-stack-calculator-design.md
Normal file
@@ -0,0 +1,75 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-projects/stack-calculator-design/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 栈式计算器设计
|
||||
|
||||
写一个栈计算器,设计如下:
|
||||
|
||||
- 支持 `+`、`-`、`*`、`/`运算
|
||||
- 支持后缀输入
|
||||
|
||||
例如:
|
||||
```
|
||||
2 3 +
|
||||
```
|
||||
输出:
|
||||
```
|
||||
5
|
||||
```
|
||||
如何实现呢?
|
||||
|
||||
其中最关键两个问题:
|
||||
|
||||
1.如何分词
|
||||
|
||||
2.如何实现栈
|
||||
|
||||
## 1.如何分词
|
||||
|
||||
首先定义好输入是一个字符串,空格风格,我们便可以使用istringstream分割每一个token了,基本框架为:
|
||||
|
||||
```cpp
|
||||
std::istringstream iss(expression);
|
||||
std::string token;
|
||||
while (iss >> token) {
|
||||
}
|
||||
```
|
||||
|
||||
## 2.如何实现栈
|
||||
|
||||
对于计算器来说,最核心就是入栈、出栈。
|
||||
|
||||
- 碰到数字入栈
|
||||
- 碰到操作符出栈计算
|
||||
|
||||
我们便可以写出框架:
|
||||
|
||||
```cpp
|
||||
if (isNumber(token)) {
|
||||
pushNumber(token);
|
||||
} else if (isOperator(token)) {
|
||||
popAndCal(token);
|
||||
} else {
|
||||
throw std::runtime_error("Invalid token in expression.");
|
||||
}
|
||||
```
|
||||
|
||||
popAndCal是计算的核心,如:
|
||||
|
||||
```cpp
|
||||
void popAndCal(const std::string& token) {
|
||||
if (operandStack.size() < 2) {
|
||||
throw std::runtime_error("Invalid expression.");
|
||||
} else {
|
||||
double operand2 = operandStack.top();
|
||||
operandStack.pop();
|
||||
double operand1 = operandStack.top();
|
||||
operandStack.pop();
|
||||
double result = performOperation(operand1, operand2, token);
|
||||
operandStack.push(result);
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
那么我们在栈中变存储了我们想要的结果,最后返回top即可。
|
||||
|
||||
是不是很简单,欢迎与我一起探讨。
|
||||
116
site_extras/cpp-things-cpp-const-family.md
Normal file
116
site_extras/cpp-things-cpp-const-family.md
Normal file
@@ -0,0 +1,116 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-const-family/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ const 全家桶
|
||||
|
||||
大纲
|
||||
|
||||
- const
|
||||
- constexpr
|
||||
- C++20
|
||||
- consteval
|
||||
- constinit
|
||||
|
||||
**注:本文所有代码示例已放星球。**
|
||||
|
||||
## 1.const
|
||||
|
||||
`const` 是我们在学习 C++/C 时最早接触的关键字之一,通常作为 `cv-qualifier` 使用,表示对象不可变。它并不保证 **编译时评估**,具体何时评估由编译器决定。例如:
|
||||
|
||||
```cpp
|
||||
const int a = 1; // 编译时
|
||||
const auto x = getdata(); // 运行时
|
||||
```
|
||||
|
||||
const有时可以用于编译时常量表达式,但是有一些例外,例如:
|
||||
|
||||
```cpp
|
||||
const double count_1 = 3.3;
|
||||
std::array<double, static_cast<int>(count_1)> moreDoubles1 {1.1, 2.2, 3.3};
|
||||
```
|
||||
|
||||
此时便会报错:the value of 'count_1' is not usable in a constant expression
|
||||
|
||||
但是这样是正常的:
|
||||
|
||||
```cpp
|
||||
const int count = 3;
|
||||
std::array<double, count> doubles {1.1, 2.2, 3.3};
|
||||
```
|
||||
|
||||
本质在于编译时表达式求值,于是C++11引入了constexpr。
|
||||
|
||||
## 2.constexpr
|
||||
|
||||
constexpr 可以用来指定变量的值可以出现在常量表达式,此时只需要将前面例子的const变为constexpr,便可以正常运行。
|
||||
|
||||
```cpp
|
||||
constexpr double count_2 = 3.3;
|
||||
std::array<double, static_cast<int>(count_2)> moreDoubles2 {1.1, 2.2, 3.3};
|
||||
```
|
||||
|
||||
`constexpr` 并不一定只能在编译时执行。它的本质含义是 **可以** 在编译时计算,但如果在运行时使用 `constexpr` 变量或函数,它也可以在运行时执行。
|
||||
|
||||
例如:result1与result2完全不一样,result1是编译时计算,但是result2是运行时计算的,抛个疑问:**你知道为什么吗?**
|
||||
|
||||
所以并不是指定了constexpr的函数它就一定是编译时计算的。
|
||||
|
||||
```cpp
|
||||
constexpr int compileTimeSum(int a, int b) {
|
||||
return a + b;
|
||||
}
|
||||
|
||||
int main() {
|
||||
constexpr int result1 = compileTimeSum(3, 5);
|
||||
int x = 10;
|
||||
int result2 = compileTimeSum(x, 20);
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
那么谁能保证呢?于是C++20来了。
|
||||
|
||||
## 3.C++20
|
||||
|
||||
### 3.1 consteval
|
||||
|
||||
consteval解决了上面的问题,它只能用于函数,并强制所有调用在编译时进行。如果我们此时将上面的constexpr改为consteval,此时result2会发生什么呢?
|
||||
|
||||
那便是报错:call to consteval function '**compileTimeSum(x, 20)**' is not a constant expression
|
||||
|
||||
```cpp
|
||||
consteval int compileTimeSum(int a, int b) {
|
||||
return a + b;
|
||||
}
|
||||
|
||||
int main() {
|
||||
constexpr int result1 = compileTimeSum(3, 5);
|
||||
int x = 10;
|
||||
int result2 = compileTimeSum(x, 20);
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
如果使用了consteval使用在变量上,也会报错:**error:** a variable cannot be declared '**consteval**'。
|
||||
|
||||
> https://en.cppreference.com/w/cpp/language/consteval
|
||||
|
||||
### 3.2 constinit
|
||||
|
||||
constinit可以强制静态或线程局部变量进行常量初始化。
|
||||
|
||||
- 不能与 constexpr、consteval 一起使用
|
||||
- 一个非类型说明符,作用是assert
|
||||
- 保证变量是静态初始化
|
||||
- 只能用于 static 或者 thread_local
|
||||
|
||||
例如:下面会编译报错:error: 'constinit' can only be applied to a variable with static or thread storage duration
|
||||
|
||||
```cpp
|
||||
constinit int a = 100;
|
||||
int main() {
|
||||
++a;
|
||||
constinit auto b = 100; // error
|
||||
// b has thread storage duration
|
||||
constinit thread_local auto b = 100;
|
||||
}
|
||||
```
|
||||
78
site_extras/cpp-things-cpp-dereference-operator.md
Normal file
78
site_extras/cpp-things-cpp-dereference-operator.md
Normal file
@@ -0,0 +1,78 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-dereference-operator/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 解引用运算符 *
|
||||
|
||||
## 0.导语
|
||||
|
||||
通常我们在操作指针时,会使用到`*`,例如:
|
||||
|
||||
```cpp
|
||||
int a = 1;
|
||||
int *ptr = a;
|
||||
std::cout << *ptr << std::endl;
|
||||
```
|
||||
|
||||
除此之外,还有什么用途?
|
||||
|
||||
答案是肯定的,例如,在C++中还有下面三类:
|
||||
|
||||
- `::*`
|
||||
- `.*`
|
||||
- `->*`
|
||||
|
||||
那么你知道这三个分别表示什么吗?
|
||||
|
||||
## 1.::*
|
||||
|
||||
`::*`被称之为**Pointer to member declarator**,指向成员声明符的指针。
|
||||
|
||||
举个例子吧:
|
||||
|
||||
下面这个例子你如何区w_的地址呢?
|
||||
|
||||
如果你写成`double * d = &w_`; 它便是无效的,因为不知道`w_`在哪里哦,所以需要指向成员声明符的指针,这样便可以进行绑定,有了这个指针之后,便可以访问成员了,继续讲后面两个。
|
||||
|
||||
```cpp
|
||||
class Rectangle {
|
||||
public:
|
||||
double w_, h_;
|
||||
|
||||
Rectangle(double w, double h) : w_(w), h_(h) {}
|
||||
double area() { return w_ * h_; }
|
||||
};
|
||||
|
||||
int main() {
|
||||
Rectangle r{2.1, 3.2};
|
||||
double Rectangle::* w = &Rectangle::w_;
|
||||
r.*w = 2.2;
|
||||
std::cout << r.w_ << std::endl;
|
||||
};
|
||||
```
|
||||
|
||||
## 2..*
|
||||
|
||||
`.*`被称为pointer to member of object,这个比较好理解,就是访问**对象**成员的指针,指向成员的指针允许你引用类对象的非静态成员。不能使用指向成员的指针指向静态类成员,因为静态成员的地址与任何特定对象都没有关联。
|
||||
|
||||
所以看上面的例子中有了这一行代码,修改成员w的值为2.2。
|
||||
|
||||
```cpp
|
||||
r.*w = 2.2;
|
||||
```
|
||||
|
||||
## 3.->*
|
||||
|
||||
`->*`被称为pointer to member of pointer,这个就更好理解了,跟.*类似,不过操作的是**指针对象**成员的地址,
|
||||
|
||||
所以对应的例子变为:
|
||||
|
||||
```cpp
|
||||
Rectangle r{2.1, 3.2}, *pr;
|
||||
pr = &r;
|
||||
std::cout << pr->*w << std::endl;
|
||||
```
|
||||
|
||||
更加详细的请阅读cppreference.com。
|
||||
|
||||
> https://en.cppreference.com/w/cpp/language/pointer#Pointers_to_members
|
||||
|
||||
你学会了吗?本节完~
|
||||
83
site_extras/cpp-things-cpp-iv-initialization.md
Normal file
83
site_extras/cpp-things-cpp-iv-initialization.md
Normal file
@@ -0,0 +1,83 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-iv-initialization/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 初始化与赋值
|
||||
|
||||
## C++ iv
|
||||
|
||||
```cpp
|
||||
int* p = nullptr;
|
||||
std::shared_ptr<int> s(p); // 计数器1
|
||||
std::shared_ptr<int> s2(s); // 计数器2
|
||||
assert(s.use_count() == 2);
|
||||
```
|
||||
|
||||
这段代码会引发几个疑问:
|
||||
|
||||
- 为何nullptr原始指针构造出来的智能指针计数器不是0?
|
||||
- delete nullptr是否是安全的?
|
||||
|
||||
### 1.空的shared_ptr语义
|
||||
|
||||
我们直接看shared_ptr源码,所谓**空**指的是:
|
||||
|
||||
- 从默认构造一个shared_ptr
|
||||
- 从nullptr_t构造一个shared_ptr
|
||||
|
||||
这两种情况才是空,而对于从原始指针构造的shared_ptr,它占有那个指针的所有权,不管它是否为空。
|
||||
|
||||
分别对应下面三个构造。
|
||||
|
||||
```cpp
|
||||
private:
|
||||
element_type* __ptr_;
|
||||
__shared_weak_count* __cntrl_;
|
||||
|
||||
public:
|
||||
_LIBCPP_HIDE_FROM_ABI
|
||||
_LIBCPP_CONSTEXPR shared_ptr() _NOEXCEPT
|
||||
: __ptr_(nullptr),
|
||||
__cntrl_(nullptr)
|
||||
{ }
|
||||
|
||||
_LIBCPP_HIDE_FROM_ABI
|
||||
_LIBCPP_CONSTEXPR shared_ptr(nullptr_t) _NOEXCEPT
|
||||
: __ptr_(nullptr),
|
||||
__cntrl_(nullptr)
|
||||
{ }
|
||||
shared_ptr(_Yp* __p, _Dp __d)
|
||||
: __ptr_(__p)
|
||||
{}
|
||||
```
|
||||
|
||||
在上面原始指针式nullptr情况下,删除delete nullptr会发生什么?删除两次又回发生什么?
|
||||
|
||||
### 2.delete nullptr
|
||||
|
||||
假设有下面的代码,运行之后会crush?会正常运行?
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
int main() {
|
||||
int *p = nullptr;
|
||||
delete p;
|
||||
std::cout << "delete once" << std::endl;
|
||||
delete p;
|
||||
std::cout << "delete twice" << std::endl;
|
||||
|
||||
}
|
||||
```
|
||||
|
||||
答案是:正常输出。
|
||||
|
||||
具体原因参考cppreference:
|
||||
|
||||
If *expression* evaluates to a null pointer value, no destructors are called, and the deallocation function may or may not be called (it's unspecified), but the default deallocation functions are guaranteed to do nothing when passed a null pointer.
|
||||
|
||||
> https://en.cppreference.com/w/cpp/language/delete
|
||||
|
||||
如果表达式的计算结果为空指针值,则不会调用析构函数,也可能调用或不调用释放函数(未指定),但默认的释放函数保证在传递空指针时不做任何事情。
|
||||
|
||||
|
||||
!!! note "阅读提示"
|
||||
本文讨论 C++ 中**初始化**(initialization)与**赋值**(assignment)的区别,可参见 [类初始化列表](../cpp-idioms/class-initializer-list.md)。
|
||||
147
site_extras/cpp-things-cpp-multiple-return-values.md
Normal file
147
site_extras/cpp-things-cpp-multiple-return-values.md
Normal file
@@ -0,0 +1,147 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-multiple-return-values/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 多返回值写法
|
||||
|
||||
[TOC]
|
||||
|
||||
今天再提出一个比较经典的面试题:函数如何返回多个结果?你能想到几种办法?
|
||||
|
||||
其实这道题目考察的知识点非常的多,涉及到:
|
||||
|
||||
- 指针
|
||||
- 引用
|
||||
- lambda
|
||||
- functional
|
||||
- tie
|
||||
- tuple
|
||||
- struct bingding
|
||||
- template deduce
|
||||
- 等等
|
||||
|
||||
本篇文章将会给大家用不同的方法来解答这道题目,首先我们转化一下这个题目,使用`a / b`来模拟(下面不考虑被除数为0的场景),返回商与余数。简单来说转化为一个函数返回商与余数有多少种办法?
|
||||
|
||||
下面进入正文,注:本节的所有代码已首发于星球,感兴趣戳下方二维码即可。
|
||||
|
||||
## 1. 指针与引用
|
||||
|
||||
对接口进行更改,添加两个变量,使用指针与引用。
|
||||
|
||||
```cpp
|
||||
void divideWithReferences(int dividend, int divisor, int& quotient, int& remainder) {
|
||||
quotient = dividend / divisor;
|
||||
remainder = dividend % divisor;
|
||||
}
|
||||
|
||||
void divideWithPointers(int dividend, int divisor, int* quotient, int* remainder) {
|
||||
if (quotient) *quotient = dividend / divisor;
|
||||
if (remainder) *remainder = dividend % divisor;
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
使用这种方式的缺点也明显可见,当返回值不止两个,接口就非常的长。此外,如果面试官要求你不允许更改函数接口,那么这个办法用不了了。
|
||||
|
||||
## 2. Tuple + Tie
|
||||
|
||||
Tuple和tie的组合为函数返回多个值提供了一种简洁的方式。通过使用`std::tie`,我们可以将tuple中的元素解包到不同的变量中,提高代码的清晰度。
|
||||
|
||||
这种方法算是标准答案之一,比较简单清晰,如果返回值是两个pair也可以。
|
||||
|
||||
```cpp
|
||||
std::tuple<int, int> divide(int dividend, int divisor) {
|
||||
return std::make_tuple(dividend / divisor, dividend % divisor);
|
||||
}
|
||||
|
||||
|
||||
std::tie(quotient, remainder) = divide(14, 3);
|
||||
std::cout << quotient << ", " << remainder << std::endl;
|
||||
```
|
||||
|
||||
## 3. Struct Binding
|
||||
|
||||
对上面进行改造,C++17引入的结构化绑定进一步简化了多值返回的代码。使用auto和结构化绑定,使得代码更加直观易懂。
|
||||
|
||||
如果面试官要你进一步的对上面的方法进行改造,那么可以变为下面这个代码示例,使用结构化绑定使代码更加优雅。
|
||||
|
||||
```cpp
|
||||
auto divide(int dividend, int divisor) {
|
||||
struct result {
|
||||
int quotient;
|
||||
int remainder;
|
||||
};
|
||||
return result{dividend / divisor, dividend % divisor};
|
||||
}
|
||||
auto [quotient, remainder] = divide(14, 3);
|
||||
```
|
||||
|
||||
## 4. 函数 Callback
|
||||
|
||||
在日常项目中,特别是一些开源项目,callback是一种常用的手段,通过传递处理返回值的callback,让用户自定义处理,这样便实现了返回多个值,实现更加灵活的代码结构。这对于异步编程和事件处理等场景非常有用。
|
||||
|
||||
```cpp
|
||||
void divide(int dividend, int divisor, std::function<void(int, int)> callback) {
|
||||
callback(dividend / divisor, dividend % divisor);
|
||||
}
|
||||
```
|
||||
|
||||
## 5. 自定义 Out
|
||||
|
||||
自定义out是一种通过结构体包装的方式,将输出参数作为结构体的成员。这种方式提高了代码的可读性,尤其适用于需要返回多个值的函数。
|
||||
|
||||
```cpp
|
||||
template <class T>
|
||||
struct out {
|
||||
std::function<void(T)> target;
|
||||
|
||||
out(T* t)
|
||||
: target([t](T&& in) {
|
||||
if (t) *t = std::move(in);
|
||||
}) {}
|
||||
|
||||
template <class... Args>
|
||||
void emplace(Args&&... args) {
|
||||
target(T(std::forward<Args>(args)...));
|
||||
}
|
||||
|
||||
template <class X>
|
||||
void operator=(X&& x) {
|
||||
emplace(std::forward<X>(x));
|
||||
}
|
||||
|
||||
template <class... Args>
|
||||
void operator()(Args&&... args) {
|
||||
emplace(std::forward<Args>(args)...);
|
||||
}
|
||||
};
|
||||
|
||||
void divide(int dividend, int divisor, out<int>& quotient_out, out<int>& remainder_out) {
|
||||
quotient_out.emplace(dividend / divisor);
|
||||
remainder_out.emplace(dividend % divisor);
|
||||
}
|
||||
```
|
||||
|
||||
## 6. 模版推导
|
||||
|
||||
C++的模版推导为开发者提供了更为灵活和简洁的代码编写方式。通过模版推导,我们可以处理不同类型的数据而无需显式指定类型。
|
||||
|
||||
```cpp
|
||||
template <typename T1, typename T2>
|
||||
struct many {
|
||||
T1 quotient;
|
||||
T2 remainder;
|
||||
};
|
||||
|
||||
template <class T1, class T2>
|
||||
many(T1, T2) -> many<T1, T2>;
|
||||
|
||||
many<int, int> divide(int dividend, int divisor) {
|
||||
return many{
|
||||
dividend / divisor,
|
||||
dividend % divisor,
|
||||
};
|
||||
}
|
||||
|
||||
auto [quotient, remainder] = divide(14, 3);
|
||||
```
|
||||
|
||||
总体而言,C++提供了多种方式来实现多值返回,每种方式都有其适用的场景。选择合适的方式取决于具体的需求,开发者可以根据代码结构和可读性来灵活使用这些特性。
|
||||
75
site_extras/cpp-things-cpp-mutable-keyword.md
Normal file
75
site_extras/cpp-things-cpp-mutable-keyword.md
Normal file
@@ -0,0 +1,75 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-mutable-keyword/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ mutable 关键字
|
||||
|
||||
### 深入探讨 C++ 中的 `mutable` 关键字
|
||||
|
||||
在 C++ 中,`mutable` 关键字经常被认为是“穿透”常量(`const`)限制的工具。在某些情况下,虽然我们希望对一个对象施加常量保护,但还是需要对该对象的某些数据成员进行修改。本文将详细探讨 `mutable` 的使用场景和背后的设计哲学,并讨论其如何在 C++ 中解决特定的编程需求。
|
||||
|
||||
#### 1. `mutable` 关键字的基本用途
|
||||
|
||||
我们知道,当一个成员函数被 `const` 修饰时,该成员函数保证不会修改对象的状态。然而,在实际编程中,有时我们希望修改一个数据成员,但仍然希望将成员函数标记为 `const`。这就是 `mutable` 关键字的作用:
|
||||
|
||||
```cpp
|
||||
class Foo
|
||||
{
|
||||
private:
|
||||
mutable bool done_;
|
||||
public:
|
||||
void doSomething() const {
|
||||
// 在 const 成员函数中修改 mutable 成员
|
||||
done_ = true;
|
||||
}
|
||||
};
|
||||
```
|
||||
|
||||
在上面的例子中,`doSomething()` 被声明为 `const`,表明它不会改变对象的状态。然而,`done_` 被标记为 `mutable`,这意味着即使在 `const` 方法中,我们仍然可以修改 `done_`。这种设计使得我们可以在保持函数接口语义不变的情况下,管理某些需要修改的数据。
|
||||
|
||||
#### 2. 逻辑常量性 vs. 位常量性
|
||||
|
||||
C++ 中的常量性可以分为两类:**逻辑常量性** 和 **位常量性**。逻辑常量性指的是对象的状态在外部看来没有发生变化,而位常量性指的是对象在内存中的位数据保持不变。`mutable` 关键字允许我们定义逻辑常量性,即即使对象的某些内部数据变化了,但在逻辑上对象的状态并未发生可见变化。
|
||||
|
||||
比如在一个线程安全的类中,我们可能会使用 `boost::mutex` 来保护数据访问。为了在 `const` 方法中获取锁,我们可以将 `mutex` 声明为 `mutable`:
|
||||
|
||||
```cpp
|
||||
class ThreadSafeClass {
|
||||
private:
|
||||
mutable std::mutex mtx_;
|
||||
int data_;
|
||||
public:
|
||||
int getData() const {
|
||||
std::lock_guard<std::mutex> lock(mtx_);
|
||||
return data_;
|
||||
}
|
||||
};
|
||||
```
|
||||
|
||||
在上述例子中,虽然 `getData` 方法被声明为 `const`,但我们需要锁来保护数据访问的线程安全性。因此,我们将 `mtx_` 声明为 `mutable`,以允许在 `const` 方法中对其进行修改。这种情况下,我们说类的逻辑状态没有改变,只是为确保线程安全而进行的修改。
|
||||
|
||||
#### 3. 在 Lambda 表达式中的 `mutable`
|
||||
|
||||
从 C++11 开始,`mutable` 也可以用于 lambda 表达式,以允许修改按值捕获的变量。默认情况下,lambda 中按值捕获的变量是不可变的。如果需要在 lambda 中修改捕获的变量,可以使用 `mutable`:
|
||||
|
||||
```cpp
|
||||
int x = 0;
|
||||
auto f1 = [=]() mutable { x = 42; }; // OK: 可以修改捕获的 x
|
||||
auto f2 = [=]() { x = 42; }; // Error: 按值捕获的变量不能被修改
|
||||
```
|
||||
|
||||
这种情况下,`mutable` 允许我们在函数体内修改捕获的变量,而不会影响到外部变量的值。
|
||||
|
||||
#### 4. 避免使用 `const_cast`
|
||||
|
||||
没有 `mutable` 关键字的情况下,我们可能需要使用 `const_cast` 来处理这些特殊情况。`const_cast` 可以去掉对象的常量性,但它也有缺点:`const_cast` 可以完全移除常量性保护,让我们对对象进行任意的修改和方法调用,这会导致代码的可读性和安全性下降。
|
||||
|
||||
相比之下,`mutable` 关键字提供了一种更细粒度的控制方式。通过 `mutable`,我们可以在特定的数据成员上设置“例外”,允许在 `const` 方法中修改,而不必将整个对象的常量性去掉。因此,`mutable` 能够更安全地处理这些特例。
|
||||
|
||||
#### 5. 使用 `mutable` 的设计哲学
|
||||
|
||||
`mutable` 关键字的设计哲学在于保持接口的**逻辑常量性**。在大多数情况下,我们希望编写 const-correct 的代码,这意味着对象的状态在没有显式修改的情况下不会变化。`mutable` 允许我们在某些内部实现上做出让步,比如缓存、引用计数、调试信息等,而不会打破这种接口设计的一致性。
|
||||
|
||||
设计一个接口时,我们应该明确何时以及为什么需要修改一个对象的状态。`mutable` 关键字能让代码在逻辑层面保持不变,同时又提供了修改特定数据成员的能力。这需要设计者深思熟虑,确保 `mutable` 的使用不会破坏对象的常量性概念,只有在确实需要的情况下使用。
|
||||
|
||||
### 6.参考资料
|
||||
|
||||
> https://stackoverflow.com/questions/105014/does-the-mutable-keyword-have-any-purpose-other-than-allowing-a-data-member-to
|
||||
96
site_extras/cpp-things-cpp-restrict-optimization.md
Normal file
96
site_extras/cpp-things-cpp-restrict-optimization.md
Normal file
@@ -0,0 +1,96 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-restrict-optimization/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ restrict 与编译优化
|
||||
|
||||
## restrict性能优化
|
||||
|
||||
```cpp
|
||||
#include <vector>
|
||||
#include <memory>
|
||||
#include <benchmark/benchmark.h>
|
||||
|
||||
#define LEN 1<<20
|
||||
using AggregateDataPtr = char *;
|
||||
|
||||
struct AvgState {
|
||||
uint64_t numerator{0};
|
||||
uint64_t denominator{0};
|
||||
|
||||
double divide() { return numerator / denominator; }
|
||||
};
|
||||
|
||||
class Column {
|
||||
public:
|
||||
std::vector<uint64_t> & data() {return data_; }
|
||||
|
||||
private:
|
||||
std::vector<uint64_t> data_;
|
||||
};
|
||||
|
||||
template <class Derived>
|
||||
class IAggregate {
|
||||
public:
|
||||
void addBatch(size_t batch_size, AggregateDataPtr state, Column *args) __attribute__((noinline)) {
|
||||
for (size_t i = 0; i < batch_size; ++i) {
|
||||
static_cast<const Derived *>(this)->add(state, args, i);
|
||||
}
|
||||
}
|
||||
|
||||
void addBatchWithoutOpt(size_t batch_size, AggregateDataPtr state, Column *args) __attribute__((noinline)) {
|
||||
for (size_t i = 0; i < batch_size; ++i) {
|
||||
static_cast<const Derived *>(this)->addWithoutOpt(state, args, i);
|
||||
}
|
||||
}
|
||||
};
|
||||
|
||||
class AvgAggregator final : public IAggregate<AvgAggregator> {
|
||||
public:
|
||||
static AvgState& data(AggregateDataPtr __restrict place) { return *reinterpret_cast<AvgState *>(place); }
|
||||
static AvgState& data_without_opt(AggregateDataPtr place) { return *reinterpret_cast<AvgState *>(place); }
|
||||
|
||||
void add(AggregateDataPtr __restrict state, Column * args, uint64_t row_num) const {
|
||||
data(state).numerator += args[0].data()[row_num];
|
||||
++(data(state).denominator);
|
||||
}
|
||||
|
||||
void addWithoutOpt(AggregateDataPtr state, Column * args, uint64_t row_num) const {
|
||||
data_without_opt(state).numerator += args[0].data()[row_num];
|
||||
++(data_without_opt(state).denominator);
|
||||
}
|
||||
};
|
||||
|
||||
static void BM_loop_with_optimize(benchmark::State& state) {
|
||||
AvgAggregator avgAggregator;
|
||||
Column column;
|
||||
for (size_t i = 0 ; i < LEN; i++) {
|
||||
column.data().push_back(i);
|
||||
}
|
||||
Column arg0[] = {column};
|
||||
// Code inside this loop is measured repeatedly
|
||||
for(auto _ : state) {
|
||||
auto avgState = std::make_unique<AvgState>();
|
||||
avgAggregator.addBatch(LEN, reinterpret_cast<AggregateDataPtr>(avgState.get()), arg0);
|
||||
}
|
||||
}
|
||||
|
||||
static void BM_loop_without_optimize(benchmark::State& state) {
|
||||
AvgAggregator avgAggregator;
|
||||
Column column;
|
||||
for (size_t i = 0 ; i < LEN; i++) {
|
||||
column.data().push_back(i);
|
||||
}
|
||||
Column arg0[] = {column};
|
||||
// Code inside this loop is measured repeatedly
|
||||
for(auto _ : state) {
|
||||
auto avgState = std::make_unique<AvgState>();
|
||||
avgAggregator.addBatchWithoutOpt(LEN, reinterpret_cast<AggregateDataPtr>(avgState.get()), arg0);
|
||||
}
|
||||
}
|
||||
|
||||
BENCHMARK(BM_loop_without_optimize);
|
||||
BENCHMARK(BM_loop_with_optimize);
|
||||
```
|
||||
|
||||
> https://quick-bench.com/q/ccjuWr_JcLozAfy3Gxf3uVu76Yk
|
||||
|
||||
https://github.com/ClickHouse/ClickHouse/pull/19946
|
||||
99
site_extras/cpp-things-cpp-string-abi-compatibility.md
Normal file
99
site_extras/cpp-things-cpp-string-abi-compatibility.md
Normal file
@@ -0,0 +1,99 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-string-abi-compatibility/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ string ABI 兼容性
|
||||
|
||||
### 项目实战问题:避坑 C++ String ABI 兼容性问题
|
||||
|
||||
[TOC]
|
||||
|
||||
为什么很多人不喜欢C++ string,反而要自己造轮子呢?其中一个问题就是C++ string abi问题,你遇到过吗?
|
||||
|
||||
之前使用conan与跨平台库的时候发生了C++ string abi兼容问题,本节将会引入ABI的背景与编译器相关的内容,讲讲如何避免这个坑,如果你遇到过,欢迎留言~
|
||||
|
||||
#### 1. ABI 变更的背景
|
||||
|
||||
**GCC 5.1**之后加强了对 C++11 的支持,并引入了一些新特性。在这一版本中,libstdc++ 引入了新的库 ABI,更新了 `std::string` 和 `std::list` 的实现。这些变化符合 C++11 标准,后者禁止使用 Copy-On-Write 字符串,并要求链表能够跟踪其大小。
|
||||
|
||||
实际项目中在使用 Conan 时,开发者可以通过调整 `compiler.libcxx` 来选择使用的 ABI:
|
||||
|
||||
- **libstdc++**:使用旧 ABI。
|
||||
- **libstdc++11**:使用新 ABI。
|
||||
|
||||
选择适当的 ABI 可以确保与其他依赖库的兼容性,特别是在使用不同版本的编译器或库时。
|
||||
|
||||
#### 2. 编译器的默认设置
|
||||
|
||||
在使用 GCC 进行编译时,如果没有显式地指定 `--with-default-libstdcxx-abi=gcc4-compatible`,则 GCC 默认使用新的 C++11 ABI。这意味着:
|
||||
|
||||
- 如果你的代码或依赖库是在旧 ABI 下编译的,那么当你尝试链接时,可能会遇到未定义的符号错误。
|
||||
|
||||
例如,编译以下代码时:
|
||||
|
||||
```cpp
|
||||
// lib.cc
|
||||
#include <string>
|
||||
void foo(const std::string& s) {}
|
||||
```
|
||||
|
||||
使用命令:
|
||||
|
||||
```bash
|
||||
g++-14 -D_GLIBCXX_USE_CXX11_ABI=0 -c lib.cc
|
||||
```
|
||||
|
||||
将生成符号 `__Z3fooRKSs`,这是旧 ABI 的格式。
|
||||
|
||||
然而,当你编译并链接另一个使用新 ABI 的文件时,可能会出现如下错误:
|
||||
|
||||
```bash
|
||||
g++-14 main.cc lib.o
|
||||
```
|
||||
|
||||
```
|
||||
Undefined symbols for architecture x86_64:
|
||||
"foo(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> > const&)", referenced from:
|
||||
_main in ccbWGoYh.o
|
||||
ld: symbol(s) not found for architecture x86_64
|
||||
collect2: error: ld returned 1 exit status
|
||||
```
|
||||
|
||||
#### 3. 解决方案
|
||||
|
||||
为了确保编译通过,有以下两种解决方案:
|
||||
|
||||
**方法 1: 手动指定 ABI**
|
||||
|
||||
在编译所有源文件时,确保手动添加 `-D_GLIBCXX_USE_CXX11_ABI=0` 来兼容旧的库,例如:
|
||||
|
||||
```bash
|
||||
g++-14 -D_GLIBCXX_USE_CXX11_ABI=0 main.cc lib.o
|
||||
```
|
||||
|
||||
**方法 2: 使用新的 ABI 编译所有文件**
|
||||
|
||||
如果你愿意使用新的 C++11 ABI,可以在编译库文件时使用 `-D_GLIBCXX_USE_CXX11_ABI=1`,这样两者符号就会匹配:
|
||||
|
||||
```bash
|
||||
g++-14 -D_GLIBCXX_USE_CXX11_ABI=1 -c lib.cc
|
||||
g++-14 main.cc lib.o
|
||||
```
|
||||
|
||||
此时,链接时符号将会匹配,不再出现未定义符号的错误。
|
||||
|
||||
#### 4. 符号比较
|
||||
|
||||
通过 `nm` 命令查看不同 ABI 下的符号,可以直观地看到二者的差异:
|
||||
|
||||
```bash
|
||||
g++-14 -D_GLIBCXX_USE_CXX11_ABI=0 -c lib.cc
|
||||
nm lib.o | grep foo
|
||||
# 输出: 0000000000000000 T __Z3fooRKSs
|
||||
|
||||
g++-14 -D_GLIBCXX_USE_CXX11_ABI=1 -c lib.cc
|
||||
nm lib.o | grep foo
|
||||
# 输出: 0000000000000000 T __Z3fooRKNSt7__cxx1112basic_stringIcSt11char_traitsIcESaIcEEE
|
||||
```
|
||||
|
||||
#### 5. 小结
|
||||
|
||||
ABI是C++升级以及编译过程中遇到的一个非常大的坑,希望可以通过这篇文章讲明白这些内容。
|
||||
57
site_extras/cpp-things-cpp-template-disambiguator.md
Normal file
57
site_extras/cpp-things-cpp-template-disambiguator.md
Normal file
@@ -0,0 +1,57 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-template-disambiguator/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 模板消歧
|
||||
|
||||
## 1.背景
|
||||
|
||||
最近看到一段代码:
|
||||
|
||||
```cpp
|
||||
auto chunk_left = first_sort_key.template GetChunk<ArrayType>(left);
|
||||
```
|
||||
|
||||
请问,这里的`.template`代表什么意义?
|
||||
|
||||
本节将从实际例子出发,探讨这个意义。
|
||||
|
||||
## 2.template disambiguator
|
||||
|
||||
在C++中,当使用模板的依赖名称(dependent names)时,有时需要使用模板消除符(template disambiguator)来帮助编译器区分这些名称。所谓"dependent names"是指依赖于模板参数的类型或值,编译器不能在实例化模板之前确定它们的具体含义。这可能会导致编译器在解析这些名称时产生二义性。
|
||||
|
||||
模板消除符(template disambiguator)使用关键字"template"来明确告诉编译器一个特定的名称是一个模板。这样编译器就可以正确地解析该名称,而不会产生二义性。
|
||||
|
||||
关键字template只能在操作符::(作用域解析)、->(通过指针访问成员)和.(成员访问),以下都是有效的示例
|
||||
|
||||
- T::template foo<X>();
|
||||
- s.template foo<X>();
|
||||
- this->template foo<X>();
|
||||
- typename T::template iterator<int>::value_type v;
|
||||
|
||||
官方资料:
|
||||
|
||||
> https://en.cppreference.com/w/cpp/language/dependent_name
|
||||
|
||||
假设有下面这个代码,我们如果不加.template会得到什么?
|
||||
|
||||
```cpp
|
||||
template <typename T>
|
||||
auto foo_is_not_a_template() {
|
||||
// ((T::foo) < 34) > (::val())
|
||||
return T::foo<34>::val();
|
||||
}
|
||||
```
|
||||
|
||||
上述会被解析为:((T::foo) < 34) > (::val())
|
||||
|
||||
对应的.template例子为:
|
||||
|
||||
```cpp
|
||||
template <typename T>
|
||||
auto foo_is_a_template() {
|
||||
return T::template foo<34>::val();
|
||||
}
|
||||
```
|
||||
|
||||
这样便调用会正确解析为模版,foo<34>。
|
||||
|
||||
本节完整代码将会在星球公布,感兴趣加入即可,谢谢!
|
||||
58
site_extras/cpp-things-cpp-vs-rust-destructor.md
Normal file
58
site_extras/cpp-things-cpp-vs-rust-destructor.md
Normal file
@@ -0,0 +1,58 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/cpp-vs-rust-destructor/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 与 Rust 析构对比
|
||||
|
||||
在Rust中mem::forget用于防止对象的析构,跳过清理工作,从而让资源的释放交给其他机制管理。
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
let file = File::open("foo.txt").unwrap();
|
||||
mem::forget(file);
|
||||
```
|
||||
|
||||
那么在C++中如何防止析构?即跳过析构函数呢?
|
||||
|
||||
**本节将给出三种办法,完整代码示例也放于星球。**
|
||||
|
||||
## 1. `placement new`
|
||||
|
||||
`placement new`可以让我们手动管理对象的构造和析构。如果不手动调用对象的析构函数,我们就可以跳过对象的析构,从而实现类似`mem::forget`的效果。
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
alignas(Foo) std::byte storage[sizeof(Foo)]; // 分配对齐的原始内存块
|
||||
Foo* pfoo = new (storage) Foo(); // 在这块内存上构造Foo对象
|
||||
```
|
||||
|
||||
在上面的代码中,`placement new`创建了对象`pfoo`,但我们不调用析构函数,这样可以跳过对象的清理逻辑。
|
||||
|
||||
## 2. 使用智能指针的自定义删除器
|
||||
|
||||
另一种实现类似功能的方法是通过自定义智能指针的删除器,防止对象被销毁。我们可以定义一个不执行任何操作的删除器,从而避免析构函数的调用。
|
||||
|
||||
```cpp
|
||||
std::unique_ptr<Foo, NoOpDeleter> pfoo(new Foo(), NoOpDeleter{});
|
||||
```
|
||||
|
||||
使用自定义的删除器`NoOpDeleter`,我们可以防止`std::unique_ptr`在离开作用域时调用析构函数,从而实现类似`mem::forget`的效果。
|
||||
|
||||
## 3.union
|
||||
|
||||
union的方案很神奇,大家知道原理吗?欢迎留言区一起讨论~
|
||||
|
||||
```cpp
|
||||
template <class T>
|
||||
union Wrapper {
|
||||
T value;
|
||||
~Wrapper() {}
|
||||
};
|
||||
|
||||
struct Foo {
|
||||
~Foo() { std::cout << "dtor foo\n"; }
|
||||
};
|
||||
|
||||
Wrapper<Foo> f;
|
||||
// f.value.~Foo); 必须手动调用
|
||||
```
|
||||
82
site_extras/cpp-things-member-initializer-list-notes.md
Normal file
82
site_extras/cpp-things-member-initializer-list-notes.md
Normal file
@@ -0,0 +1,82 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/member-initializer-list-notes/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 成员初始化列表注意点
|
||||
|
||||
在C++中,类的正确初始化是确保程序正常运行的关键步骤之一。尤其是在使用初始化列表时,我们需要注意一些潜在的陷阱,以避免在代码执行过程中产生意外的结果。
|
||||
|
||||
初始化列表通常被认为是设置新类实例状态的首选方法,因为它提供了一种简洁、高效的方式来初始化类成员。然而,有时候在初始化列表中引用其他成员变量可能导致一些令人困惑的问题。
|
||||
|
||||
## 问题示例
|
||||
|
||||
考虑以下的`Foo`类:
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
class Foo
|
||||
{
|
||||
public:
|
||||
Foo(int size) : size_(size),
|
||||
capacity_(size_ + 2),
|
||||
length_(capacity_)
|
||||
{}
|
||||
|
||||
void print() {
|
||||
std::cout << "Size: " << size_ << " Capacity: " << capacity_ << " Length: " << length_ << std::endl;
|
||||
}
|
||||
|
||||
private:
|
||||
int length_;
|
||||
int capacity_;
|
||||
int size_;
|
||||
};
|
||||
|
||||
int main() {
|
||||
Foo foo(50);
|
||||
foo.print();
|
||||
}
|
||||
```
|
||||
|
||||
在这个例子中,我们试图通过初始化列表中引用其他成员变量的方式来初始化`length_`、`capacity_`和`size_`。然而,由于类成员的初始化顺序是按照它们在类中声明的顺序进行的,可能导致`length_`与`capacity_`并没有按照我们期望的方式初始化。
|
||||
|
||||
## 如何解决?
|
||||
|
||||
为了避免这种问题,应该遵循以下几点:
|
||||
|
||||
**1.避免在初始化列表中引用其他成员变量**
|
||||
|
||||
**2.顺序一致性:成员变量的初始化顺序是按照它们在类中声明的顺序**
|
||||
|
||||
修正示例:
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
|
||||
class Foo
|
||||
{
|
||||
public:
|
||||
Foo(int size) : size_(size),
|
||||
capacity_(size_ + 2),
|
||||
length_(calculateLength(size_))
|
||||
{}
|
||||
|
||||
void print() {
|
||||
std::cout << "Size: " << size_ << " Capacity: " << capacity_ << " Length: " << length_ << std::endl;
|
||||
}
|
||||
|
||||
private:
|
||||
int calculateLength(int size) {
|
||||
return size + 2;
|
||||
}
|
||||
|
||||
private:
|
||||
int size_;
|
||||
int capacity_;
|
||||
int length_;
|
||||
};
|
||||
|
||||
int main() {
|
||||
Foo foo(50);
|
||||
foo.print();
|
||||
}
|
||||
```
|
||||
73
site_extras/cpp-things-smart-pointer-as-parameter.md
Normal file
73
site_extras/cpp-things-smart-pointer-as-parameter.md
Normal file
@@ -0,0 +1,73 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/smart-pointer-as-parameter/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 智能指针作函数参数
|
||||
|
||||
## C++那些事之智能指针何时作为函数参数
|
||||
|
||||
通常我们可以看到有些函数用了智能指针作为参数,有些函数又使用了裸指针,究竟用哪一个呢?使用原则是什么?
|
||||
|
||||
本节使用abseil的tips进行讲解。
|
||||
|
||||
如下所示,这段代码有什么问题呢?
|
||||
|
||||
```cpp
|
||||
bool CanYouPetTheDog(const std::shared_ptr<Dog>& dog,
|
||||
absl::Duration min_delay) {
|
||||
return dog->GetLastPetTime() + min_delay < absl::Now();
|
||||
}
|
||||
```
|
||||
|
||||
CanYouPetTheDog函数并不会影响其 dog 参数的所有权,但它的签名要求将其存储在 std::shared_ptr 中。这样做会在特定所有权模型上创建一个不必要的依赖,尽管函数本身并不需要这种依赖。这种依赖会阻止调用者使用其他模型,比如 std::unique_ptr 或在堆栈上构造对象。
|
||||
|
||||
## 使用指针/引用
|
||||
|
||||
当所有权没有受到影响时使用**引用或指针**。 通过使用引用/指针,我们可以消除对特定所有权模型的依赖,并允许我们的函数与任何类型为 Dog 的对象一起工作。
|
||||
|
||||
```cpp
|
||||
bool CanYouPetTheDog(const Dog& dog, absl::Duration min_delay) {
|
||||
return dog.GetLastPetTime() + min_delay < absl::Now();
|
||||
}
|
||||
```
|
||||
|
||||
有了上述定义,无论调用者的所有权模型如何,都可以调用该函数:
|
||||
|
||||
```cpp
|
||||
Dog stack_dog;
|
||||
if (CanYouPetTheDog(stack_dog, delay)) { ... }
|
||||
|
||||
auto heap_dog = std::make_unique<Dog>();
|
||||
if (CanYouPetTheDog(*heap_dog, delay)) { ... }
|
||||
|
||||
CustomPetPtr<Dog> custom_dog = CreateDog();
|
||||
if (CanYouPetTheDog(*custom_dog, delay)) { ... }
|
||||
```
|
||||
|
||||
函数修改了传递的值,则传递可变引用或原始指针,并使用与上述相同的用法。
|
||||
|
||||
## 使用智能指针
|
||||
|
||||
在函数修改所有权时使用智能指针,以下代码为不同的智能指针参数提供了几个重载。第一个重载假定接管传递对象的所有权,第二个重载为传递对象添加了一个共享引用。这两种操作取决于调用方如何处理 Dog 的所有权。无法接管位于栈的 Dog,因为无法从栈中取走所有权。
|
||||
|
||||
```cpp
|
||||
class Human {
|
||||
public:
|
||||
...
|
||||
void Adopt(std::unique_ptr<Dog> dog) {
|
||||
pets_.push_back(std::move(dog));
|
||||
}
|
||||
void Adopt(std::shared_ptr<Cat> cat) {
|
||||
pets_.push_back(std::move(cat));
|
||||
}
|
||||
|
||||
private:
|
||||
std::vector<std::shared_ptr<Pet>> pets_;
|
||||
...
|
||||
};
|
||||
|
||||
```
|
||||
|
||||
## 总结
|
||||
|
||||
如果所有权没有被转移或修改,则应该避免将智能指针作为函数参数。
|
||||
|
||||
> https://abseil.io/tips/188
|
||||
78
site_extras/cpp-things-std-function-cpp.md
Normal file
78
site_extras/cpp-things-std-function-cpp.md
Normal file
@@ -0,0 +1,78 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/std-function-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ std::function 详解
|
||||
|
||||
最近在写C++代码时用到了`is_function`,然后顺便看了一下源码实现,发现了一些问题,以前咱们学习的是三个点`...`,那六个点`......`你知道是啥吗?
|
||||
|
||||
同样,如果有一段这样的代码:
|
||||
|
||||
```
|
||||
template<typename... Args>
|
||||
struct foo(Args......);
|
||||
```
|
||||
|
||||
你知道是啥意思?
|
||||
|
||||
下面我们一起来深入细节!
|
||||
|
||||
## 1.六个点
|
||||
|
||||
六个点我们通常叫做two ellipsis operators,我们可以将六个点进行拆分,于是得到下面三种情况
|
||||
|
||||
```
|
||||
template <typename... Args> void foo1(Args......)
|
||||
template <typename... Args> void foo2(Args... ...)
|
||||
template <typename... Args> void foo3(Args..., ...)
|
||||
```
|
||||
|
||||
这下就好看了,我们来看std::is_function的代码。
|
||||
|
||||
## 2.is_function实现细节
|
||||
|
||||
`std::is_function`的实现涉及到主模板和两个偏特化:
|
||||
|
||||
```cpp
|
||||
// 主模板,假设提供的类型不是函数类型
|
||||
template<typename T>
|
||||
struct is_function : std::false_type {};
|
||||
|
||||
// 偏特化,用于正常的函数类型
|
||||
template<typename Ret, typename... Args>
|
||||
struct is_function<Ret(Args...)> : std::true_type {};
|
||||
|
||||
// 偏特化,用于变参函数类型
|
||||
template<typename Ret, typename... Args>
|
||||
struct is_function<Ret(Args......)> : std::true_type {};
|
||||
```
|
||||
|
||||
- 主模板假设提供的类型不是函数类型,并将`std::false_type`作为结果。
|
||||
- 第一个偏特化用于正常的函数类型,其中`Ret`表示返回类型,`Args...`表示参数类型。如果提供的类型匹配这种函数签名,则`std::true_type`作为结果。
|
||||
- 第二个偏特化用于变参函数类型,其中的省略号表示函数具有可变数量的参数。同样,如果提供的类型匹配这种函数签名,则`std::true_type`作为结果。
|
||||
|
||||
## 3.使用示例
|
||||
|
||||
最后给出一个`std::is_function`的使用示例:
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <type_traits>
|
||||
|
||||
int func(int x, int y) { return x + y; }
|
||||
int vararg_func(int x, ...) { return x; }
|
||||
|
||||
int main() {
|
||||
std::cout << std::boolalpha;
|
||||
std::cout << "Is func a function? " << std::is_function<decltype(func)>::value << std::endl;
|
||||
std::cout << "Is vararg_func a function? " << std::is_function<decltype(vararg_func)>::value << std::endl;
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
这将输出:
|
||||
|
||||
```
|
||||
Is func a function? true
|
||||
Is vararg_func a function? true
|
||||
```
|
||||
|
||||
你学会了吗,本节完~
|
||||
146
site_extras/cpp-things-std-ref-wrapper.md
Normal file
146
site_extras/cpp-things-std-ref-wrapper.md
Normal file
@@ -0,0 +1,146 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/std-ref-wrapper/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ ref 与 reference_wrapper
|
||||
|
||||
## 深入理解 C++ 中的 std::cref、std::ref 和 std::reference_wrapper
|
||||
|
||||
在 C++ 编程中,有时候我们需要在不进行拷贝的情况下传递引用,或者在需要引用的地方使用常量对象。为了解决这些问题,C++ 标准库提供了三个有用的工具:`std::cref`、`std::ref` 和 `std::reference_wrapper`。这篇文章将深入探讨这些工具的用途、区别以及实际应用。
|
||||
|
||||
此外,我们知道Rust语言中,经常实现了Unwrap方法,在C++中如何实现?
|
||||
|
||||
这就参考Apache arrow的代码了,有这么一段:
|
||||
|
||||
```cpp
|
||||
std::optional<std::reference_wrapper<const TransportStatusDetail>>
|
||||
TransportStatusDetail::Unwrap(const Status& status) {
|
||||
std::shared_ptr<StatusDetail> detail = status.detail();
|
||||
if (!detail) return std::nullopt;
|
||||
if (detail->type_id() != kTypeId) return std::nullopt;
|
||||
return std::cref(arrow::internal::checked_cast<const TransportStatusDetail&>(*detail));
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
随后我们便可以通过这样调用,提取出Status中实际的TransportStatusDetail。
|
||||
|
||||
```cpp
|
||||
Status status(transportDetail);
|
||||
auto result = Unwrap(status);
|
||||
```
|
||||
|
||||
下面来从几个方面看看,最后给出整个Demo代码。
|
||||
|
||||
### 1. std::cref:创建常量引用
|
||||
|
||||
`std::cref` 是一个模板函数,用于创建对常量对象的引用。它返回一个 `std::reference_wrapper` 对象,可以在需要引用的地方使用。这在函数参数传递中特别有用,因为它允许我们在不进行拷贝的情况下传递常量对象,同时保持引用的语义。
|
||||
|
||||
**示例:**
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <functional>
|
||||
|
||||
void printValue(const int& value) {
|
||||
std::cout << "Value: " << value << std::endl;
|
||||
}
|
||||
|
||||
int main() {
|
||||
int number = 42;
|
||||
auto crefNumber = std::cref(number);
|
||||
|
||||
printValue(crefNumber); // 使用常量引用传递参数
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
### 2. std::ref:创建可修改的引用
|
||||
|
||||
与 `std::cref` 不同,`std::ref` 是一个模板函数,用于创建对可修改对象的引用。它返回一个 `std::reference_wrapper` 对象,允许我们在需要引用的地方使用,同时允许修改被引用的对象。
|
||||
|
||||
**示例:**
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <functional>
|
||||
|
||||
void modifyValue(int& value) {
|
||||
value *= 2;
|
||||
}
|
||||
|
||||
int main() {
|
||||
int number = 42;
|
||||
auto refNumber = std::ref(number);
|
||||
|
||||
modifyValue(refNumber); // 使用可修改的引用作为参数
|
||||
|
||||
std::cout << "Modified Value: " << number << std::endl;
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
### 3. std::reference_wrapper:引用的包装器
|
||||
|
||||
`std::reference_wrapper` 是一个模板类,用于包装引用,使其能够在容器中存储或以引用的形式传递。它提供类似引用的语法,并且可以与标准容器一起使用,因为容器无法直接存储引用。
|
||||
|
||||
**示例:**
|
||||
|
||||
```cpp
|
||||
#include <iostream>
|
||||
#include <vector>
|
||||
#include <functional>
|
||||
|
||||
int main() {
|
||||
int number1 = 42;
|
||||
int number2 = 73;
|
||||
|
||||
std::vector<std::reference_wrapper<int>> numbers = {std::ref(number1), std::ref(number2)};
|
||||
|
||||
for (auto& num : numbers) {
|
||||
num.get() += 10; // 修改原始对象的值
|
||||
}
|
||||
|
||||
std::cout << "Number 1: " << number1 << std::endl;
|
||||
std::cout << "Number 2: " << number2 << std::endl;
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
在这个示例中,`std::reference_wrapper` 允许我们将引用包装在容器中,然后通过 `get()` 方法来访问和修改原始对象的值。
|
||||
|
||||
## 4.Unwrap Demo
|
||||
|
||||
这里给出具体的代码段,其完整代码参见知识星球内容。
|
||||
|
||||
```cpp
|
||||
std::optional<std::reference_wrapper<const TransportStatusDetail>> Unwrap(const Status& status) {
|
||||
std::shared_ptr<StatusDetail> detail = status.detail();
|
||||
if (!detail) return std::nullopt;
|
||||
if (detail->type_id() != kTypeId) return std::nullopt;
|
||||
return std::cref(static_cast<const TransportStatusDetail&>(*detail));
|
||||
}
|
||||
|
||||
int main() {
|
||||
// 创建 TransportStatusDetail 对象
|
||||
std::shared_ptr<StatusDetail> transportDetail = std::make_shared<TransportStatusDetail>();
|
||||
|
||||
// 创建 Status 对象并传入 TransportStatusDetail 对象
|
||||
Status status(transportDetail);
|
||||
|
||||
auto result = Unwrap(status);
|
||||
|
||||
if (result) {
|
||||
const TransportStatusDetail& detail = result.value().get();
|
||||
// 使用 detail 进行操作
|
||||
std::cout << "TransportStatusDetail found." << std::endl;
|
||||
} else {
|
||||
std::cout << "No valid TransportStatusDetail found." << std::endl;
|
||||
}
|
||||
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
欢迎一起探讨C++那些事,更多项目/内容,欢迎加入知识星球。
|
||||
51
site_extras/cpp-things-tail-recursion-cpp.md
Normal file
51
site_extras/cpp-things-tail-recursion-cpp.md
Normal file
@@ -0,0 +1,51 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/tail-recursion-cpp/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ 尾递归
|
||||
|
||||
尾递归优化是一种特殊的优化技术,适用于递归函数,它可以极大地减少递归调用的栈空间占用。通过尾递归优化,编译器可以在执行尾递归时避免创建新的栈帧,直接复用当前的栈帧,从而降低栈溢出的风险,并提高性能。
|
||||
|
||||
[TOC]
|
||||
|
||||
### 什么是尾递归?
|
||||
递归调用在返回时,**没有其他操作**需要执行,这样的递归称为**尾递归**。在这种情况下,编译器可以用一个循环结构替代递归,避免多次函数调用的开销。
|
||||
|
||||
### 非尾递归的例子(斐波那契数列)
|
||||
你提供的 `fibonacci_non_tail()` 函数是一个标准的非尾递归实现:
|
||||
|
||||
```cpp
|
||||
int fibonacci_non_tail(int n) {
|
||||
if (n <= 1) {
|
||||
return n;
|
||||
}
|
||||
return fibonacci_non_tail(n - 1) + fibonacci_non_tail(n - 2);
|
||||
}
|
||||
```
|
||||
|
||||
在这个实现中,递归调用 `fibonacci_non_tail(n - 1)` 和 `fibonacci_non_tail(n - 2)` 之后,还需要将它们的结果相加,因此这不是尾递归。每次调用都需要保存上下文信息,以便在递归返回后继续计算,这导致栈空间快速增长。
|
||||
|
||||
### 尾递归优化的示例
|
||||
`fibonacci_tail()` 使用了尾递归的方式:
|
||||
|
||||
```cpp
|
||||
int fibonacci_tail_helper(int n, int a, int b) {
|
||||
if (n == 0) {
|
||||
return a;
|
||||
}
|
||||
return fibonacci_tail_helper(n - 1, b, a + b);
|
||||
}
|
||||
|
||||
int fibonacci_tail(int n) {
|
||||
return fibonacci_tail_helper(n, 0, 1);
|
||||
}
|
||||
```
|
||||
|
||||
这里的 `fibonacci_tail_helper()` 是尾递归。你可以看到,递归调用 `fibonacci_tail_helper(n - 1, b, a + b)` 后,函数不再需要做任何其他工作,直接返回递归调用的结果。因此,递归调用位于函数的“尾部”,没有额外的操作需要在递归调用后执行。
|
||||
|
||||
### 尾递归优化的优势
|
||||
- **减少栈空间使用**:由于不需要保存递归调用的上下文,编译器可以复用栈帧,避免栈空间膨胀。
|
||||
- **防止栈溢出**:尾递归优化允许递归深度达到非常大的值而不会发生栈溢出。
|
||||
- **更高效**:在支持尾递归优化的编译器中,尾递归的性能接近于迭代实现,消除了递归函数调用的开销。
|
||||
|
||||
### 性能测试
|
||||
|
||||
最后针对上面做了一个benchmark,发现尾递归优化在这个场景下非常有用,可以看到性能的差异很大!
|
||||
45
site_extras/cpp-things-vector-resize-reverse.md
Normal file
45
site_extras/cpp-things-vector-resize-reverse.md
Normal file
@@ -0,0 +1,45 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-things/vector-resize-reverse/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# C++ vector resize 与 reverse
|
||||
|
||||
在C++中,`resize`和`reserve`是用于容器(例如`std::vector`)的两个成员函数,用于管理vector的大小和内存分配。
|
||||
|
||||
例如:
|
||||
|
||||
```
|
||||
std::vector<int> v1;
|
||||
v1.resize(1000); //allocation + instance creation
|
||||
cout <<(v1.size() == 1000)<< endl; //prints 1
|
||||
cout <<(v1.capacity()==1000)<< endl; //prints 1
|
||||
|
||||
std::vector<int> v2;
|
||||
v2.reserve(1000); //only allocation
|
||||
cout <<(v2.size() == 1000)<< endl; //prints 0
|
||||
cout <<(v2.capacity()==1000)<< endl; //prints 1
|
||||
```
|
||||
|
||||
`resize`函数用于更改容器的大小,可以增加或减少容器中元素的数量。当增加容器的大小时,新添加的元素将会进行初始化。当减少容器的大小时,超出新大小的元素将会被移除。
|
||||
|
||||
`reserve`函数用于预分配容器的内存空间,但不改变容器的大小。它可以用于提前分配足够的内存,以避免频繁的重新分配内存操作,从而提高性能。但是,调用`reserve`并不会改变容器的大小,只是为容器分配足够的内存空间。
|
||||
|
||||
需要注意的是,`resize`和`reserve`函数在容器类型上的可用性有所不同。`resize`函数对于大多数容器类型是可用的,而`reserve`函数只对具有动态大小的容器类型有效,例如`std::vector`和`std::deque`。对于固定大小的容器类型(例如`std::array`),调用`reserve`没有任何效果。
|
||||
|
||||
从源码层面上来看:
|
||||
|
||||
```
|
||||
void resize(size_type new_size, value_type value = value_type()) {
|
||||
if (new_size < size()) {
|
||||
erase(begin() + new_size, end()); // 移除超出新大小的元素
|
||||
} else {
|
||||
insert(end(), new_size - size(), value); // 添加新元素
|
||||
}
|
||||
}
|
||||
void reserve(size_type _n) {
|
||||
if (__n > max_size())
|
||||
__throw_length_error(__N("vector::reserve"));
|
||||
if (capacity() < __n)
|
||||
_M_reallocate(__n);
|
||||
}
|
||||
```
|
||||
|
||||
> 本节完
|
||||
61
site_extras/cpp-tools-bazel-build-guide.md
Normal file
61
site_extras/cpp-tools-bazel-build-guide.md
Normal file
@@ -0,0 +1,61 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-tools/bazel-build-guide/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# Bazel 构建 C++ 项目
|
||||
|
||||
```
|
||||
gpadmin@gpadmin:~$ ./bazel-6.1.1-installer-linux-x86_64.sh --user
|
||||
Bazel installer
|
||||
---------------
|
||||
|
||||
Bazel is bundled with software licensed under the GPLv2 with Classpath exception.
|
||||
You can find the sources next to the installer on our release page:
|
||||
https://github.com/bazelbuild/bazel/releases
|
||||
|
||||
#
|
||||
|
||||
## Build information
|
||||
- [Commit](https://github.com/bazelbuild/bazel/commit/1a90fe5)
|
||||
Uncompressing......WARNING: Invoking Bazel in batch mode since it is not invoked from within a workspace (below a directory having a WORKSPACE file).
|
||||
Extracting Bazel installation...
|
||||
.
|
||||
|
||||
Bazel is now installed!
|
||||
|
||||
Make sure you have "/home/gpadmin/bin" in your path.
|
||||
|
||||
For bash completion, add the following line to your :
|
||||
source /home/gpadmin/.bazel/bin/bazel-complete.bash
|
||||
|
||||
For fish shell completion, link this file into your
|
||||
/home/gpadmin/.config/fish/completions/ directory:
|
||||
ln -s /home/gpadmin/.bazel/bin/bazel.fish /home/gpadmin/.config/fish/completions/bazel.fish
|
||||
|
||||
See http://bazel.build/docs/getting-started.html to start a new project!
|
||||
```
|
||||
|
||||
|
||||
|
||||
默认安装到home/bin
|
||||
|
||||
|
||||
|
||||
```
|
||||
gpadmin@gpadmin:~$ ls ~/bin/
|
||||
bazel
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
1. 在安装过程中,Bazel 可能会提示您添加环境变量。如果是这样,请根据提示编辑您的 `~/.bashrc` 文件并将以下行添加到文件末尾:
|
||||
|
||||
```
|
||||
复制代码export PATH="$PATH:$HOME/bin"
|
||||
```
|
||||
|
||||
1. 重新加载 `.bashrc` 文件以使更改生效:
|
||||
|
||||
```
|
||||
复制代码source ~/.bashrc
|
||||
```
|
||||
36
site_extras/cpp-tools-bazel-debugging.md
Normal file
36
site_extras/cpp-tools-bazel-debugging.md
Normal file
@@ -0,0 +1,36 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-tools/bazel-debugging/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# Bazel 与 LLDB 联合调试
|
||||
|
||||
今天在调试时发现通过bazel编译出来的文件在mac上没法调试了,竟然全是汇编代码。
|
||||
|
||||
```
|
||||
* thread #1, queue = 'com.apple.main-thread', stop reason = breakpoint 1.1
|
||||
frame #0: 0x0000000100000fd0 hello_world`main
|
||||
hello_world`main:
|
||||
-> 0x100000fd0 <+0>: pushq %rbp
|
||||
0x100000fd1 <+1>: movq %rsp, %rbp
|
||||
0x100000fd4 <+4>: subq $0x60, %rsp
|
||||
0x100000fd8 <+8>: movl $0x0, -0x4(%rbp)
|
||||
(lldb) quit
|
||||
```
|
||||
|
||||
如何解决呢?
|
||||
|
||||
默认是standalone,我们需要disable,这里采用local,这意味着输出将与其依赖项链接,而不是采用默认的`standalone`策略。
|
||||
|
||||
```cpp
|
||||
build --spawn_strategy=local
|
||||
```
|
||||
|
||||
这样的话可以看到代码了。
|
||||
|
||||
```cpp
|
||||
* thread #1, queue = 'com.apple.main-thread', stop reason = breakpoint 1.1
|
||||
frame #0: 0x0000000100000fdf hello_world`main at hello_world.cc:14:21
|
||||
11
|
||||
12 int main() {
|
||||
13 // Create a thread pool
|
||||
-> 14 auto threadPool = GetCpuThreadPool();
|
||||
15 if (!threadPool) {
|
||||
```
|
||||
97
site_extras/cpp-tools-cmake-essentials.md
Normal file
97
site_extras/cpp-tools-cmake-essentials.md
Normal file
@@ -0,0 +1,97 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-tools/cmake-essentials/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# CMake 入门与实战
|
||||
|
||||
## CMake常用必备一
|
||||
|
||||
[TOC]
|
||||
|
||||
## 1.设置编译器flags
|
||||
|
||||
例如:设置C++标准,显示所有警告。
|
||||
|
||||
```cpp
|
||||
set(CMAKE_CXX_FLAGS "-std=c++0x -Wall")
|
||||
set(CMAKE_CXX_FLAGS "${CMAKE_CXX_FLAGS} -std=c++0x -Wall")
|
||||
add_compile_options("$<$<STREQUAL:$<TARGET_PROPERTY:LINKER_LANGUAGE>,CXX>:-std=c++11>")
|
||||
```
|
||||
|
||||
还可以设置一些优化flags
|
||||
|
||||
官方资料:https://gcc.gnu.org/onlinedocs/gcc/Optimize-Options.html
|
||||
|
||||
例如:
|
||||
|
||||
```cpp
|
||||
-O0, -O1, -O2, -O3
|
||||
```
|
||||
|
||||
如果使用llvm,则可以参考这里:
|
||||
|
||||
> https://clang.llvm.org/docs/DiagnosticsReference.html
|
||||
|
||||
## 2.设置源文件属性
|
||||
|
||||
这是CMake的一个复杂属性,如果存在多个目标,可能需要更改一个目标的某些行为。例如,如果要使用C++11构建main.cpp,而只构建库,则可能希望将其构建为C++14。在这种情况下,您可以使用`set_source_files_properties`命令来配置特定源文件的属性,如下所示:
|
||||
|
||||
```
|
||||
cmakeCopy code
|
||||
set_source_files_properties(${CMAKE_CURRENT_SOURCE_DIR}/*.cpp PROPERTIES COMPILE_FLAGS "-std=c++11")
|
||||
```
|
||||
|
||||
可以从以下手册中查看大量的属性,每个属性都可以用于满足您的特定需求。
|
||||
|
||||
- [CMake 属性](https://cmake.org/cmake/help/v3.3/manual/cmake-properties.7.html#source-file-properties)
|
||||
|
||||
> https://cmake.org/cmake/help/v3.3/manual/cmake-properties.7.html#source-file-properties
|
||||
|
||||
## 3.链接器标志
|
||||
|
||||
以下是GNU GCC链接器的链接器标志列表。
|
||||
|
||||
[GNU GCC 链接选项](https://gcc.gnu.org/onlinedocs/gcc/Link-Options.html)
|
||||
|
||||
> https://gcc.gnu.org/onlinedocs/gcc/Link-Options.html
|
||||
|
||||
GCC链接器默认情况下可以在环境变量中定义的目录(/usr/lib;/usr/local/lib)中搜索,然后默认链接标准库。
|
||||
|
||||
最常见的标志之一是`-l`,用于链接所需的库,如`-lzlib`、`-lboost`等。
|
||||
|
||||
还有其他附加标志,可帮助您更改可执行文件的链接选项行为。
|
||||
|
||||
以下是您可以添加链接器标志的变量:
|
||||
|
||||
- `CMAKE_EXE_LINKER_FLAGS`:在创建可执行文件时由链接器使用的标志
|
||||
- `CMAKE_EXE_LINKER_FLAGS_RELEASE`:在创建发布版本可执行文件时由链接器使用的标志
|
||||
- `CMAKE_EXE_LINKER_FLAGS_DEBUG`:在创建调试版本可执行文件时由链接器使用的标志
|
||||
- `CMAKE_STATIC_LINKER_FLAGS`:在创建静态库(.a、.lib)时由链接器使用的标志
|
||||
- `CMAKE_SHARED_LINKER_FLAGS`:在创建共享库(.so、.dll)时由链接器使用的标志
|
||||
- `CMAKE_MODULE_LINKER_FLAGS`:在创建模块库时由链接器使用的标志
|
||||
|
||||
例如,您可以使用以下代码添加链接器标志:
|
||||
|
||||
```
|
||||
set(CMAKE_EXE_LINKER_FLAGS "${CMAKE_EXE_LINKER_FLAGS} -fsanitize=address")
|
||||
set(CMAKE_EXE_LINKER_FLAGS "${CMAKE_EXE_LINKER_FLAGS} -Wl")
|
||||
```
|
||||
|
||||
了解如何使用这些标志可以帮助您更好地控制可执行文件的链接行为。
|
||||
|
||||
## 4.Debug与Release包
|
||||
|
||||
在CMakeLists.txt文件内部,可以访问CMAKE_BUILD_TYPE。你可以在CMakeLists.txt中轻松检查构建类型:
|
||||
|
||||
```cpp
|
||||
if(${CMAKE_BUILD_TYPE} MATCHES Debug)
|
||||
message("Debug Build")
|
||||
elseif(${CMAKE_BUILD_TYPE} MATCHES Release)
|
||||
message("Release Build")
|
||||
endif()
|
||||
```
|
||||
|
||||
您还可以使用上一节中所示的配置变量,分别为不同的构建类型设置编译器和链接器标志:
|
||||
|
||||
- CMAKE_EXE_LINKER_FLAGS_RELEASE:用于创建发布版本可执行文件的标志
|
||||
- CMAKE_EXE_LINKER_FLAGS_DEBUG:用于创建调试版本可执行文件的标志
|
||||
- CMAKE_CXX_FLAGS_RELEASE
|
||||
- CMAKE_CXX_FLAGS_DEBUG
|
||||
210
site_extras/cpp-tools-conan-package-manager.md
Normal file
210
site_extras/cpp-tools-conan-package-manager.md
Normal file
@@ -0,0 +1,210 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-tools/conan-package-manager/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# Conan C++ 包管理入门
|
||||
|
||||
## 1.Conan安装
|
||||
|
||||
```
|
||||
pip3 install conan
|
||||
```
|
||||
|
||||
## 2.安装第三方库
|
||||
|
||||
安装第三方库时,我们通常需要知道安装的库版本,那么conan提供了相应的搜索命令,列出相应库的版本。
|
||||
|
||||
```
|
||||
conan search gtest --remote=conancenter
|
||||
```
|
||||
|
||||
如果直接搜会报错,conancenter找不到,所以第一步设置remote。
|
||||
|
||||
```
|
||||
conan remote add conancenter https://center.conan.io
|
||||
```
|
||||
|
||||
随后,我们再继续上面的搜索命令,发现报错:
|
||||
|
||||
```cpp
|
||||
ERROR: HTTPSConnectionPool(host='center.conan.io', port=443): Max retries exceeded with url: /v1/ping (Caused by SSLError(SSLError(1, '[SSL: CERTIFICATE_VERIFY_FAILED] certificate verify failed (_ssl.c:877)'),))
|
||||
|
||||
Unable to connect to conancenter=https://center.conan.io
|
||||
1. Make sure the remote is reachable or,
|
||||
2. Disable it by using conan remote disable,
|
||||
Then try again.
|
||||
```
|
||||
|
||||
此时,需要配置证书
|
||||
|
||||
```
|
||||
conan config install https://github.com/conan-io/conanclientcert.git
|
||||
```
|
||||
|
||||
输出:
|
||||
|
||||
```cpp
|
||||
Trying to clone repo: https://github.com/conan-io/conanclientcert.git
|
||||
Repo cloned!
|
||||
Copying file LICENSE to /home/light/.conan/.
|
||||
Copying file cacert.pem to /home/light/.conan/.
|
||||
```
|
||||
|
||||
随后,继续使用`conan search`,我们找到:
|
||||
|
||||
```cpp
|
||||
[light@i-fu3d01tc build]$ conan search gtest --remote=conancenter
|
||||
Existing package recipes:
|
||||
|
||||
gtest/cci.20210126
|
||||
gtest/1.8.1
|
||||
gtest/1.10.0
|
||||
gtest/1.11.0
|
||||
gtest/1.12.1
|
||||
gtest/1.13.0
|
||||
gtest/1.14.0
|
||||
```
|
||||
|
||||
## 3.编写一个项目
|
||||
|
||||
接下来,使用conan编写一个项目。
|
||||
|
||||
项目背景:在开发阶段,我们需要进行单元测试,例如:除法需要测试除以0与非零等边界的断言,我们需要引入第三方库,这里用gtest。
|
||||
|
||||
1.编写代码
|
||||
|
||||
```cpp
|
||||
#include <gtest/gtest.h>
|
||||
double divide(double a, double b) { return b == 0 ? 0 : a / b; }
|
||||
|
||||
TEST(Div, NonZero) {
|
||||
double expected = 1.5;
|
||||
double actual = divide(3, 2);
|
||||
ASSERT_EQ(expected, actual);
|
||||
}
|
||||
|
||||
TEST(Div, Zero) {
|
||||
double expected = 0;
|
||||
double actual = divide(3, 0);
|
||||
ASSERT_EQ(expected, actual);
|
||||
}
|
||||
|
||||
```
|
||||
|
||||
2.编写conanfile.txt,指定一个gtest版本。
|
||||
|
||||
```
|
||||
[requires]
|
||||
gtest/1.13.0
|
||||
|
||||
[generators]
|
||||
cmake
|
||||
```
|
||||
|
||||
3.添加CMakeLists.txt,内容很简单:其中感叹号部分需要注意。
|
||||
|
||||
```cpp
|
||||
cmake_minimum_required(VERSION 3.16)
|
||||
project(MultiplyTest LANGUAGES CXX)
|
||||
|
||||
enable_testing()
|
||||
|
||||
// !!!
|
||||
find_package(GTest REQUIRED)
|
||||
|
||||
add_executable(div_test div_test.cpp)
|
||||
|
||||
// !!!
|
||||
target_link_libraries(div_test
|
||||
PRIVATE
|
||||
GTest::GTest)
|
||||
|
||||
add_test(div_gtest div_test)
|
||||
|
||||
```
|
||||
|
||||
4.开始安装与编译
|
||||
|
||||
- 安装第三方库
|
||||
|
||||
```
|
||||
[gpadmin@i-fu3d01tc build]$ conan install ../
|
||||
Configuration:
|
||||
[settings]
|
||||
arch=x86_64
|
||||
arch_build=x86_64
|
||||
build_type=Release
|
||||
compiler=gcc
|
||||
compiler.libcxx=libstdc++11
|
||||
compiler.version=10
|
||||
os=Linux
|
||||
os_build=Linux
|
||||
[options]
|
||||
[build_requires]
|
||||
[env]
|
||||
|
||||
gtest/1.13.0: Not found in local cache, looking in remotes...
|
||||
gtest/1.13.0: Trying with 'conan-public'...
|
||||
gtest/1.13.0: Trying with 'conancenter'...
|
||||
Downloading conanmanifest.txt completed [0.10k]
|
||||
Downloading conanfile.py completed [8.27k]
|
||||
Downloading conan_export.tgz completed [0.32k]
|
||||
Decompressing conan_export.tgz completed [0.00k]
|
||||
gtest/1.13.0: Downloaded recipe revision 8a0bc5b3e159ed45de97260c2bff65b5
|
||||
conanfile.txt: Installing package
|
||||
Requirements
|
||||
gtest/1.13.0 from 'conancenter' - Downloaded
|
||||
Packages
|
||||
gtest/1.13.0:e019a06362b932ca5d1b082b6c112aa150c88de4 - Download
|
||||
|
||||
Installing (downloading, building) binaries...
|
||||
gtest/1.13.0: Retrieving package e019a06362b932ca5d1b082b6c112aa150c88de4 from remote 'conancenter'
|
||||
Downloading conanmanifest.txt completed [3.07k]
|
||||
Downloading conaninfo.txt completed [0.60k]
|
||||
Downloading conan_package.tgz completed [487.88k]
|
||||
Decompressing conan_package.tgz completed [0.00k]
|
||||
gtest/1.13.0: Package installed e019a06362b932ca5d1b082b6c112aa150c88de4
|
||||
gtest/1.13.0: Downloaded package revision 81bd558bf2388a3aee4ee13b8a902a45
|
||||
conanfile.txt: Generator txt created conanbuildinfo.txt
|
||||
conanfile.txt: Generator cmake created conanbuildinfo.cmake
|
||||
conanfile.txt: Aggregating env generators
|
||||
conanfile.txt: Generated conaninfo.txt
|
||||
conanfile.txt: Generated graphinfo
|
||||
```
|
||||
|
||||
- 编译
|
||||
|
||||
```cpp
|
||||
[light@i-fu3d01tc build]$ cmake ..
|
||||
-- The CXX compiler identification is GNU 10.2.1
|
||||
-- Detecting CXX compiler ABI info
|
||||
-- Detecting CXX compiler ABI info - done
|
||||
-- Check for working CXX compiler: /opt/rh/devtoolset-10/root/usr/bin/c++ - skipped
|
||||
-- Detecting CXX compile features
|
||||
-- Detecting CXX compile features - done
|
||||
-- Found GTest: /usr/lib64/libgtest.so
|
||||
-- Configuring done
|
||||
-- Generating done
|
||||
-- Build files have been written to: /home/light/cmake-google-tests/conan/build
|
||||
[light@i-fu3d01tc build]$ make
|
||||
Scanning dependencies of target div_test
|
||||
[ 50%] Building CXX object CMakeFiles/div_test.dir/div_test.cpp.o
|
||||
[100%] Linking CXX executable div_test
|
||||
[100%] Built target div_test
|
||||
```
|
||||
|
||||
- 运行
|
||||
|
||||
```
|
||||
[light@i-fu3d01tc build]$ ./div_test
|
||||
[==========] Running 2 tests from 1 test case.
|
||||
[----------] Global test environment set-up.
|
||||
[----------] 2 tests from Div
|
||||
[ RUN ] Div.NonZero
|
||||
[ OK ] Div.NonZero (0 ms)
|
||||
[ RUN ] Div.Zero
|
||||
[ OK ] Div.Zero (0 ms)
|
||||
[----------] 2 tests from Div (0 ms total)
|
||||
|
||||
[----------] Global test environment tear-down
|
||||
[==========] 2 tests from 1 test case ran. (0 ms total)
|
||||
[ PASSED ] 2 tests.
|
||||
```
|
||||
81
site_extras/cpp-tools-gcc-flags-guide.md
Normal file
81
site_extras/cpp-tools-gcc-flags-guide.md
Normal file
@@ -0,0 +1,81 @@
|
||||
> 来自 [C++那些事网站](https://light-city.github.io/stories_things/cpp-tools/gcc-flags-guide/) 的文章,由站点同步脚本导出。
|
||||
|
||||
# GCC 编译选项详解
|
||||
|
||||
大家经常在编译代码时通常会使用一些gcc flags,今天这篇文章来梳理一下一些比较重要的gcc flag。
|
||||
|
||||
## 1.优化flag
|
||||
|
||||
优化标志用于提高编译代码的性能。这些标志可以加速编译过程并生成高效的程序。
|
||||
|
||||
一些常用的优化标志包括:
|
||||
|
||||
`-O1`、`-O2`、`-O3`、`-Os`:这些标志控制应用的优化级别。
|
||||
|
||||
`-O1`应用基本优化,而`-O2`和`-O3`提供更高级的优化。-Os优化代码大小。
|
||||
|
||||
`-finline-functions`、`-funroll-loops`:这些标志分别控制函数内联和循环展开优化,旨在消除函数调用开销并减少循环迭代。
|
||||
|
||||
## 2.调试Flag
|
||||
|
||||
调试标志有助于提供额外信息,使调试工具能够跟踪和分析代码。
|
||||
|
||||
一些常用的调试标志包括:
|
||||
|
||||
`-g`:该标志在编译后的可执行文件中包含调试符号。
|
||||
|
||||
`-ggdb`:该标志使GCC以适用于GNU调试器(GDB)的格式生成调试信息。
|
||||
|
||||
## 3.警告Flag
|
||||
|
||||
警告标志有助于识别潜在问题、编码错误或代码中存在问题的实践。通过启用警告标志,编译器会对这些情况提供警告,使开发人员能够提高代码质量。
|
||||
|
||||
一些常用的警告标志包括:
|
||||
|
||||
`-Wall`:该标志启用一套全面的警告,涵盖各种潜在问题。
|
||||
|
||||
`-Werror`:该标志将警告视为错误,使编译器在遇到警告时停止编译过程。
|
||||
|
||||
## 4.预处理器Flag
|
||||
|
||||
预处理器标志负责处理源代码中以#开头的指令。这些标志定义宏并控制编译。
|
||||
|
||||
一些常用的预处理器标志包括:
|
||||
|
||||
`-D`:该标志用于在编译过程中定义宏。例如,`-DDEBUG`可用于定义DEBUG宏,根据其是否存在启用条件编译。
|
||||
|
||||
`-I`:该标志用于指定头文件位于的额外目录。它帮助预处理器在编译代码时找到必要的头文件。
|
||||
|
||||
## 5.链接器Flag
|
||||
|
||||
链接器标志控制链接过程,该过程在编译后进行,将目标文件和库组合以生成最终的可执行文件。
|
||||
|
||||
一些常用的链接器标志包括:
|
||||
|
||||
`-l`:该标志用于链接外部库。例如:`-lpthread`链接POSIX线程库。
|
||||
|
||||
`-L`:该标志用于指定库位于的额外目录。它帮助链接器在链接过程中找到所需的库。
|
||||
|
||||
## 6.平台特定flag
|
||||
|
||||
GCC提供了针对特定平台的标志,允许开发人员针对特定架构或启用特定平台功能。在为特定硬件或操作系统开发代码时,这些标志非常有用。
|
||||
|
||||
平台特定标志包括:
|
||||
|
||||
`-march`:该标志指定目标架构。例如,`-march=native`指示GCC优化为主机机器的架构。
|
||||
|
||||
`-m32`和`-m64`:这些标志指定是为32位还是64位目标进行编译。
|
||||
|
||||
## 7.其他Flag
|
||||
|
||||
除了前面提到的类别,还有一些其他标志。
|
||||
|
||||
一些常用的杂项标志包括:
|
||||
|
||||
`-std`:该标志指定要使用的C语言标准版本。例如,`-std=c99`选择C99标准。 `-pedantic`:该标志启用对所选择的C语言标准的严格遵守,对非标准或可疑代码结构提供额外的警告。 `-Wextra`:该标志启用超过-Wall启用的额外警告,提供更全面的代码分析。
|
||||
|
||||
需要注意的是,标志的可用性和功能可能会因GCC的不同版本和平台而有所变化。因此,建议查阅GCC文档和相关资源,获取有关特定标志及其用法的详细信息。
|
||||
|
||||
完整文档地址:
|
||||
|
||||
> https://gcc.gnu.org/onlinedocs/gcc/
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user